diff --git a/.github/workflows/labels.yml b/.github/workflows/labels.yml
index 3abbb51e24c..e6f82ba7c7e 100644
--- a/.github/workflows/labels.yml
+++ b/.github/workflows/labels.yml
@@ -1,9 +1,9 @@
name: Pull Request Labels
"on":
- pull_request:
+ pull_request:
types: [opened, reopened, labeled, unlabeled, synchronize]
jobs:
- label:
+ label:
runs-on: ubuntu-latest
steps:
- uses: mheap/github-action-required-labels@v1
diff --git a/website/content/common/behavioural_analysis/messages/_index.md b/website/content/common/behavioural_analysis/messages/_index.md
index f66559046d8..6a87775faf9 100755
--- a/website/content/common/behavioural_analysis/messages/_index.md
+++ b/website/content/common/behavioural_analysis/messages/_index.md
@@ -2,7 +2,7 @@
usage: messages [-t TICKER] [-l N_LIM] [-h]
```
-Print up to 30 of the last messages on the board. [Source: Stocktwits]
+Show the last posts for a ticker. Source: https://Stocktwits.com
```
optional arguments:
@@ -13,4 +13,4 @@ optional arguments:
-h, --help show this help message (default: False)
```
- +
diff --git a/website/content/common/behavioural_analysis/popular/_index.md b/website/content/common/behavioural_analysis/popular/_index.md
index a1dcc97b291..52379eb6d4e 100755
--- a/website/content/common/behavioural_analysis/popular/_index.md
+++ b/website/content/common/behavioural_analysis/popular/_index.md
@@ -2,7 +2,7 @@
usage: popular [-n N_TOP] [-l N_LIMIT] [-s S_SUBREDDIT] [-h]
```
-Print latest popular tickers. [Source: Reddit]
+The current popular tickers on [Reddit](https://Reddit.com)
```
optional arguments:
@@ -16,4 +16,4 @@ optional arguments:
-h, --help show this help message (default: False)
```
-
 +
diff --git a/website/content/common/behavioural_analysis/popularsi/_index.md b/website/content/common/behavioural_analysis/popularsi/_index.md
index 50d929d39b9..9502a32245b 100755
--- a/website/content/common/behavioural_analysis/popularsi/_index.md
+++ b/website/content/common/behavioural_analysis/popularsi/_index.md
@@ -2,15 +2,13 @@
usage: popularsi [-l LIMIT] [-h]
```
-The popular command prints the stocks with highest Average Hype Index right now.
+The stocks with highest Average Hype Index right now.
AHI (Absolute Hype Index)
---
AHI is a measure of how much people are talking about a stock on social media.
It is calculated by dividing the total number of mentions for the chosen stock on a social network by the mean number of mentions any stock receives on that social medium.
-===
-
Sentiment Investor analyzes data from four major social media platforms to generate hourly metrics on over 2,000 stocks. Sentiment provides volume and
sentiment metrics powered by proprietary NLP models.
@@ -20,3 +18,18 @@ optional arguments:
the maximum number of stocks to retrieve
-h, --help show this help message
```
+Sample output:
+```
+(✨) (stocks)>(ba)> popularsi
+ Rank Ticker AHI
+------ -------- -----
+ 1 AMC 4.514
+ 2 TSLA 4.184
+ 3 BTC 4.045
+ 4 SPY 3.890
+ 5 WISH 3.175
+ 6 NAKD 2.220
+ 7 SOFI 2.153
+ 8 SAND 1.813
+ 9 AMD 1.628
+ 10 MMAT 1.617
diff --git a/website/content/common/behavioural_analysis/queries/_index.md b/website/content/common/behavioural_analysis/queries/_index.md
index 0c3ad1832a5..8a8951d84a0 100755
--- a/website/content/common/behavioural_analysis/queries/_index.md
+++ b/website/content/common/behavioural_analysis/queries/_index.md
@@ -2,7 +2,7 @@
usage: queries [-n N_NUM] [-h]
```
-Print top related queries with this stock's query. [Source: Google]
+Use Google metrics to see what people are searching for in the context of the loaded ticker.
```
optional arguments:
@@ -11,4 +11,4 @@ optional arguments:
-h, --help show this help message (default: False)
```
-
 +
diff --git a/website/content/common/behavioural_analysis/regions/_index.md b/website/content/common/behavioural_analysis/regions/_index.md
index e4bf2139784..2461d5e7a38 100755
--- a/website/content/common/behavioural_analysis/regions/_index.md
+++ b/website/content/common/behavioural_analysis/regions/_index.md
@@ -2,7 +2,7 @@
usage: regions [-n N_NUM] [-h]
```
-Plot bars of regions based on stock's interest. [Source: Google]
+Shows a bar graph of the interest in the stock by country using Google metrics.
```
optional arguments:
@@ -11,4 +11,4 @@ optional arguments:
-h, --help show this help message (default: False)
```
-
+
 diff --git a/website/content/common/behavioural_analysis/rise/_index.md b/website/content/common/behavioural_analysis/rise/_index.md
index f6f7e4b1779..551068ae37e 100755
--- a/website/content/common/behavioural_analysis/rise/_index.md
+++ b/website/content/common/behavioural_analysis/rise/_index.md
@@ -2,7 +2,7 @@
usage: rise [-n N_NUM] [-h]
```
-Print top rising related queries with this stock's query. [Source: Google]
+The terms searched along with the loaded ticker that are rising the fastest on Google.
```
optional arguments:
@@ -11,4 +11,4 @@ optional arguments:
-h, --help show this help message (default: False)
```
-
 +
diff --git a/website/content/common/behavioural_analysis/sentiment/_index.md b/website/content/common/behavioural_analysis/sentiment/_index.md
index 2b0b6ca0c39..a4a02012def 100755
--- a/website/content/common/behavioural_analysis/sentiment/_index.md
+++ b/website/content/common/behavioural_analysis/sentiment/_index.md
@@ -2,7 +2,7 @@
usage: sentiment [-n N_TWEETS] [-d N_DAYS_PAST] [-h]
```
-Plot in-depth sentiment predicted from tweets from last days that contain pre-defined ticker. [Source: Twitter]
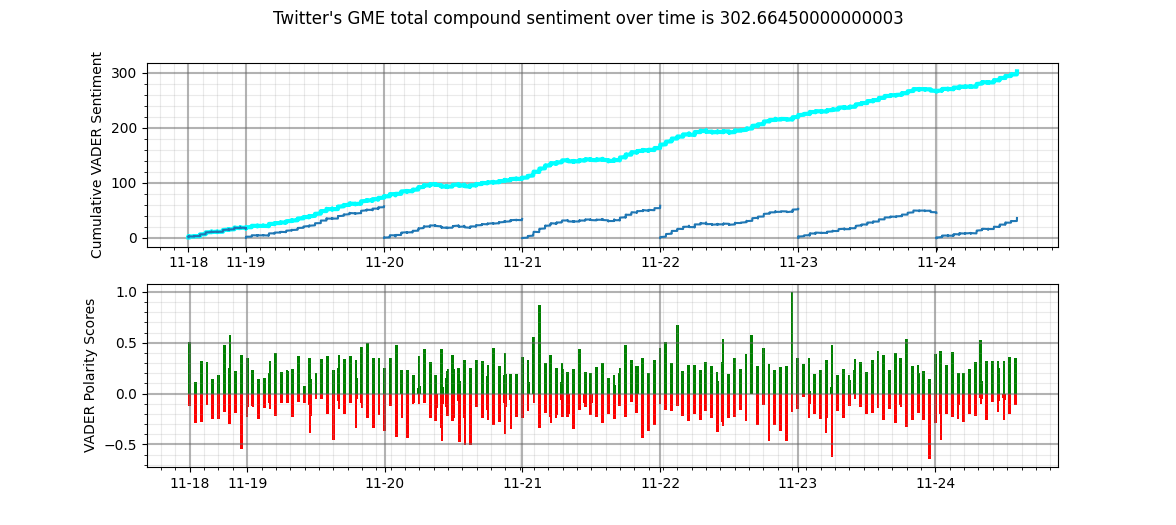
+Analyze the sentiment of Twitter users through a variable-controlled sample size using the Twitter API.
```
optional arguments:
@@ -12,3 +12,4 @@ optional arguments:
number of days in the past to extract tweets. (default: 6)
-h, --help show this help message (default: False)
```
+
 diff --git a/website/content/common/behavioural_analysis/spac_c/_index.md b/website/content/common/behavioural_analysis/spac_c/_index.md
index 4a881dcb6fe..c58f09689ba 100755
--- a/website/content/common/behavioural_analysis/spac_c/_index.md
+++ b/website/content/common/behavioural_analysis/spac_c/_index.md
@@ -2,8 +2,7 @@
usage: spac_c [-l N_LIMIT] [-p] [-h]
```
-Print other users SPACs announcement under subreddit 'SPACs'. [Source: Reddit]
-
+Follow announcements under the subReddit, r/SPACs. [Reddit](https;//reddit.com)
```
optional arguments:
-l N_LIMIT, --limit N_LIMIT
@@ -12,4 +11,4 @@ optional arguments:
-h, --help show this help message (default: False)
```
-
 +
diff --git a/website/content/common/behavioural_analysis/stalker/_index.md b/website/content/common/behavioural_analysis/stalker/_index.md
index 2236f34c0d3..d90b812bb17 100755
--- a/website/content/common/behavioural_analysis/stalker/_index.md
+++ b/website/content/common/behavioural_analysis/stalker/_index.md
@@ -2,7 +2,7 @@
usage: stalker [-u S_USER] [-l N_LIM] [-h]
```
-Print up to the last 30 messages of a user. [Source: Stocktwits]
+Show the last messages from a specified [Stocktwits](https://stocktwits.com) user.
```
optional arguments:
@@ -13,4 +13,4 @@ optional arguments:
-h, --help show this help message (default: False)
```
-
 +
diff --git a/website/content/common/behavioural_analysis/trending/_index.md b/website/content/common/behavioural_analysis/trending/_index.md
index ca81b27ef3a..4acf1ad5be4 100755
--- a/website/content/common/behavioural_analysis/trending/_index.md
+++ b/website/content/common/behavioural_analysis/trending/_index.md
@@ -2,11 +2,11 @@
usage: trending [-h]
```
-Stocks trending. [Source: Stocktwits]
+Tickers trending on [Stocktwits](https://Stocktwits.com)
```
optional arguments:
-h, --help show this help message (default: False)
```
-
 +
diff --git a/website/content/common/behavioural_analysis/watchlist/_index.md b/website/content/common/behavioural_analysis/watchlist/_index.md
index 3ec829c28ef..acb85fcc3bb 100755
--- a/website/content/common/behavioural_analysis/watchlist/_index.md
+++ b/website/content/common/behavioural_analysis/watchlist/_index.md
@@ -2,7 +2,7 @@
usage: watchlist [-l N_LIMIT] [-h]
```
-Print other users watchlist. [Source: Reddit]
+Searches [Reddit](https://reddit.com) for users' watchlists.
```
optional arguments:
@@ -11,4 +11,4 @@ optional arguments:
-h, --help show this help message (default: False)
```
-
 +
diff --git a/website/content/common/behavioural_analysis/wsb/_index.md b/website/content/common/behavioural_analysis/wsb/_index.md
index 019bea220bf..fa79c95aefc 100755
--- a/website/content/common/behavioural_analysis/wsb/_index.md
+++ b/website/content/common/behavioural_analysis/wsb/_index.md
@@ -2,7 +2,7 @@
usage: wsb [-l N_LIMIT] [-n] [-h]
```
-Print what WSB gang are up to in subreddit wallstreetbets. [Source: Reddit]
+Get some inspiration for trade ideas from the infamous subReddit, WSB.
```
optional arguments:
@@ -12,4 +12,4 @@ optional arguments:
-h, --help show this help message (default: False)
```
-
 +
diff --git a/website/content/common/quantitative_analysis/acf/_index.md b/website/content/common/quantitative_analysis/acf/_index.md
index 200a0911e50..2058d5c231a 100755
--- a/website/content/common/quantitative_analysis/acf/_index.md
+++ b/website/content/common/quantitative_analysis/acf/_index.md
@@ -1,13 +1,18 @@
```text
usage: acf [-l LAGS] [-h]
```
-
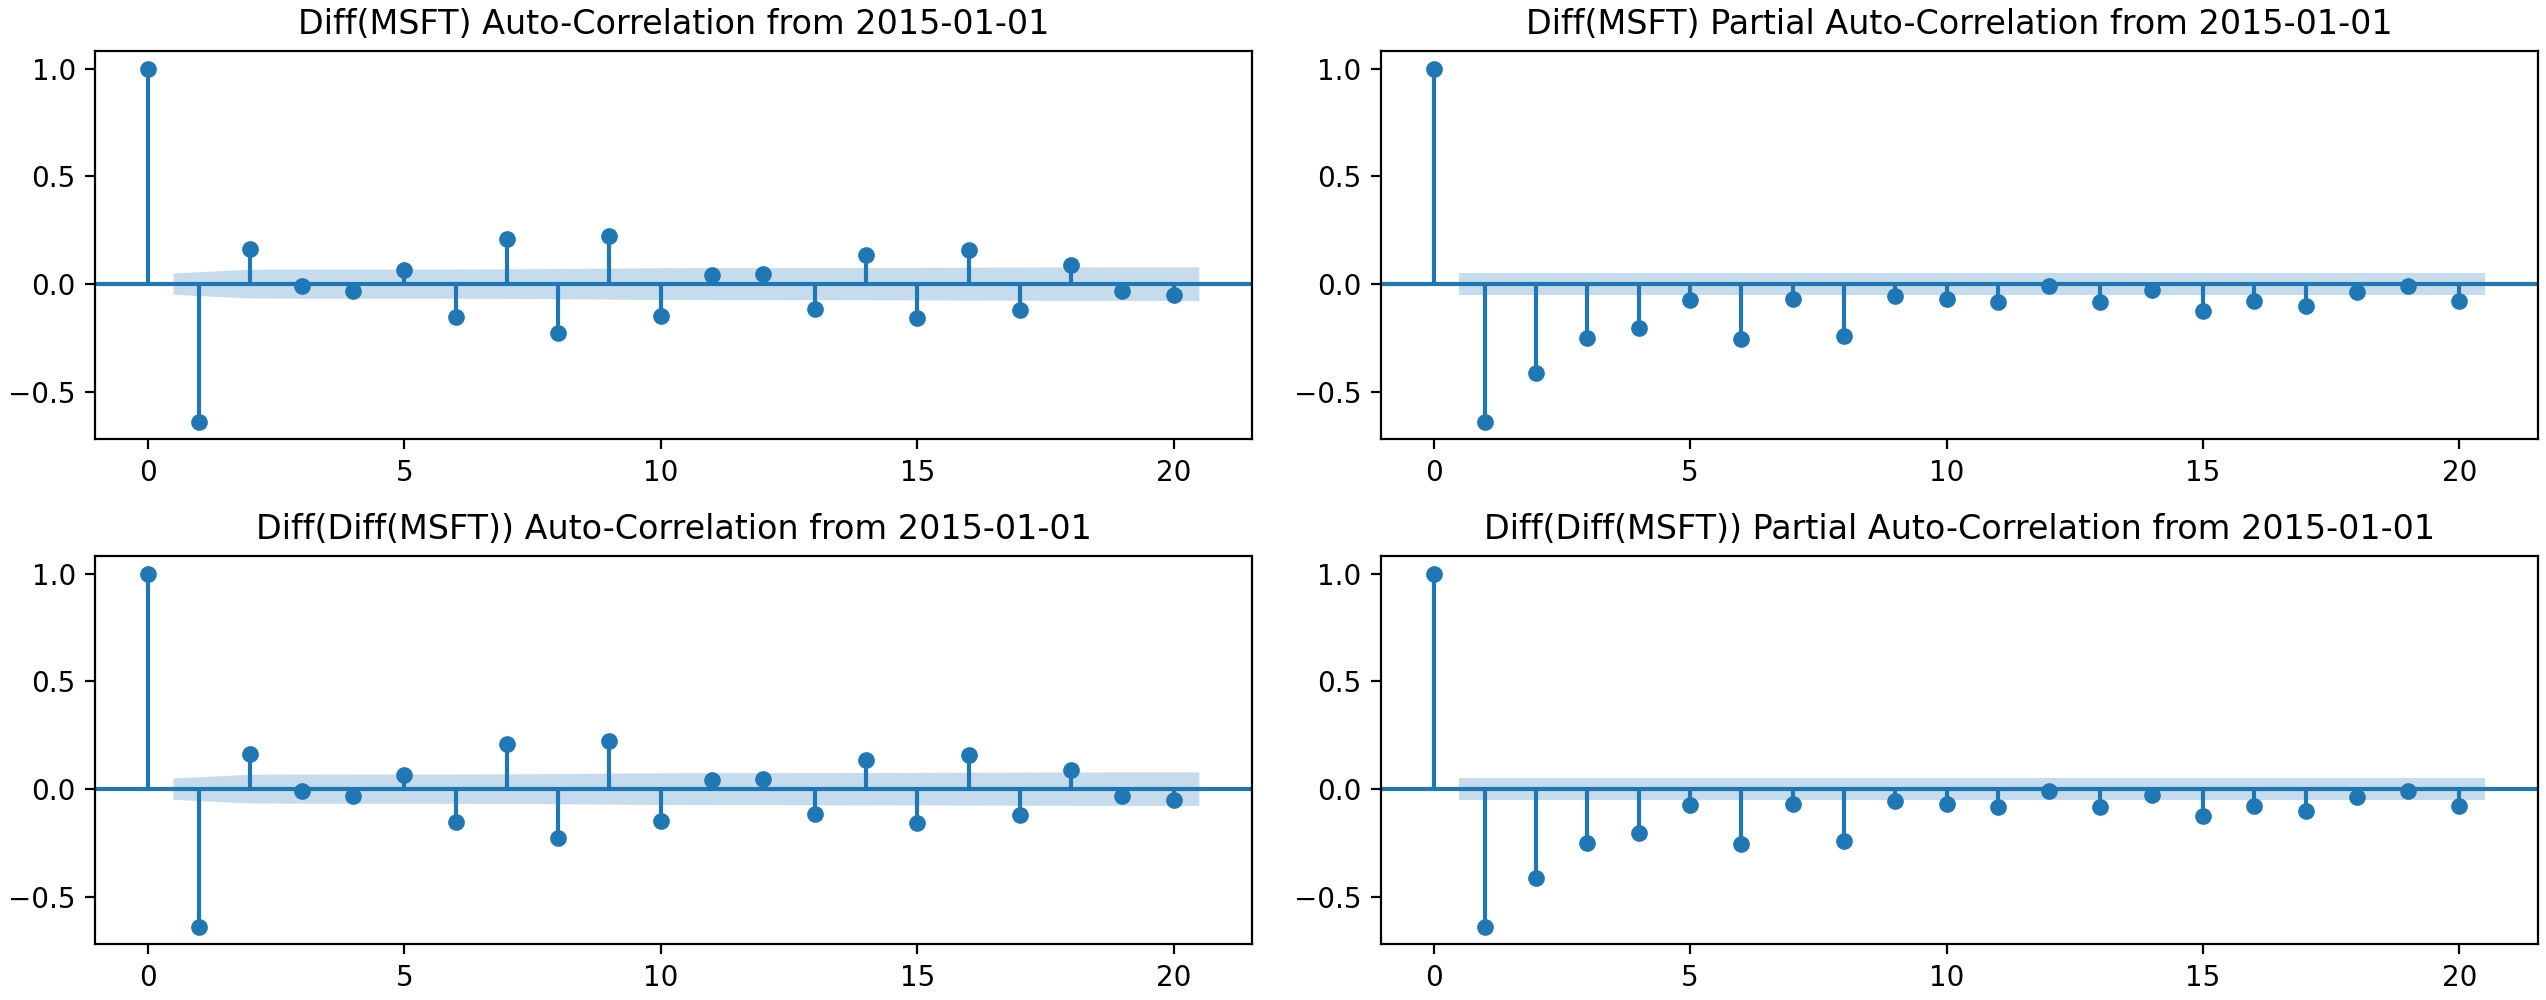
Auto-Correlation and Partial Auto-Correlation Functions for diff and diff diff stock data
+http://sciencedirect.com/topics/chemistry/autocorrelation-function
+
+The autocorrelation function (ACF) defines how data points in a time series are related, on average, to the preceding data points (Box, Jenkins, & Reinsel, 1994).
+
+A positive autocorrelation value for a particular lag τ can be interpreted as a measure of persistence of data points separated by this lag to stay above and/or below the mean value of the signal. A negative autocorrelation indicates that data points separated by this lag tend to alternate about the mean value. An important piece of information provided by the ACF is the maximum lag τmax that still has a significant value. This lag indicates the “memory” or temporal persistence of the fluctuation series. Data points separated by time lags greater than τmax are uncoupled. The ACF is often redundantly plotted for positive and negative values of τ, although by definition it is symmetric about τ = 0.
+
```
optional arguments:
-l LAGS, --lags LAGS maximum lags to display in plots (default: 15)
-h, --help show this help message (default: False)
```
-
+
 diff --git a/website/content/common/quantitative_analysis/bw/_index.md b/website/content/common/quantitative_analysis/bw/_index.md
index 043d922f176..617be59b98f 100755
--- a/website/content/common/quantitative_analysis/bw/_index.md
+++ b/website/content/common/quantitative_analysis/bw/_index.md
@@ -4,10 +4,12 @@ usage: bw [-y] [-h]
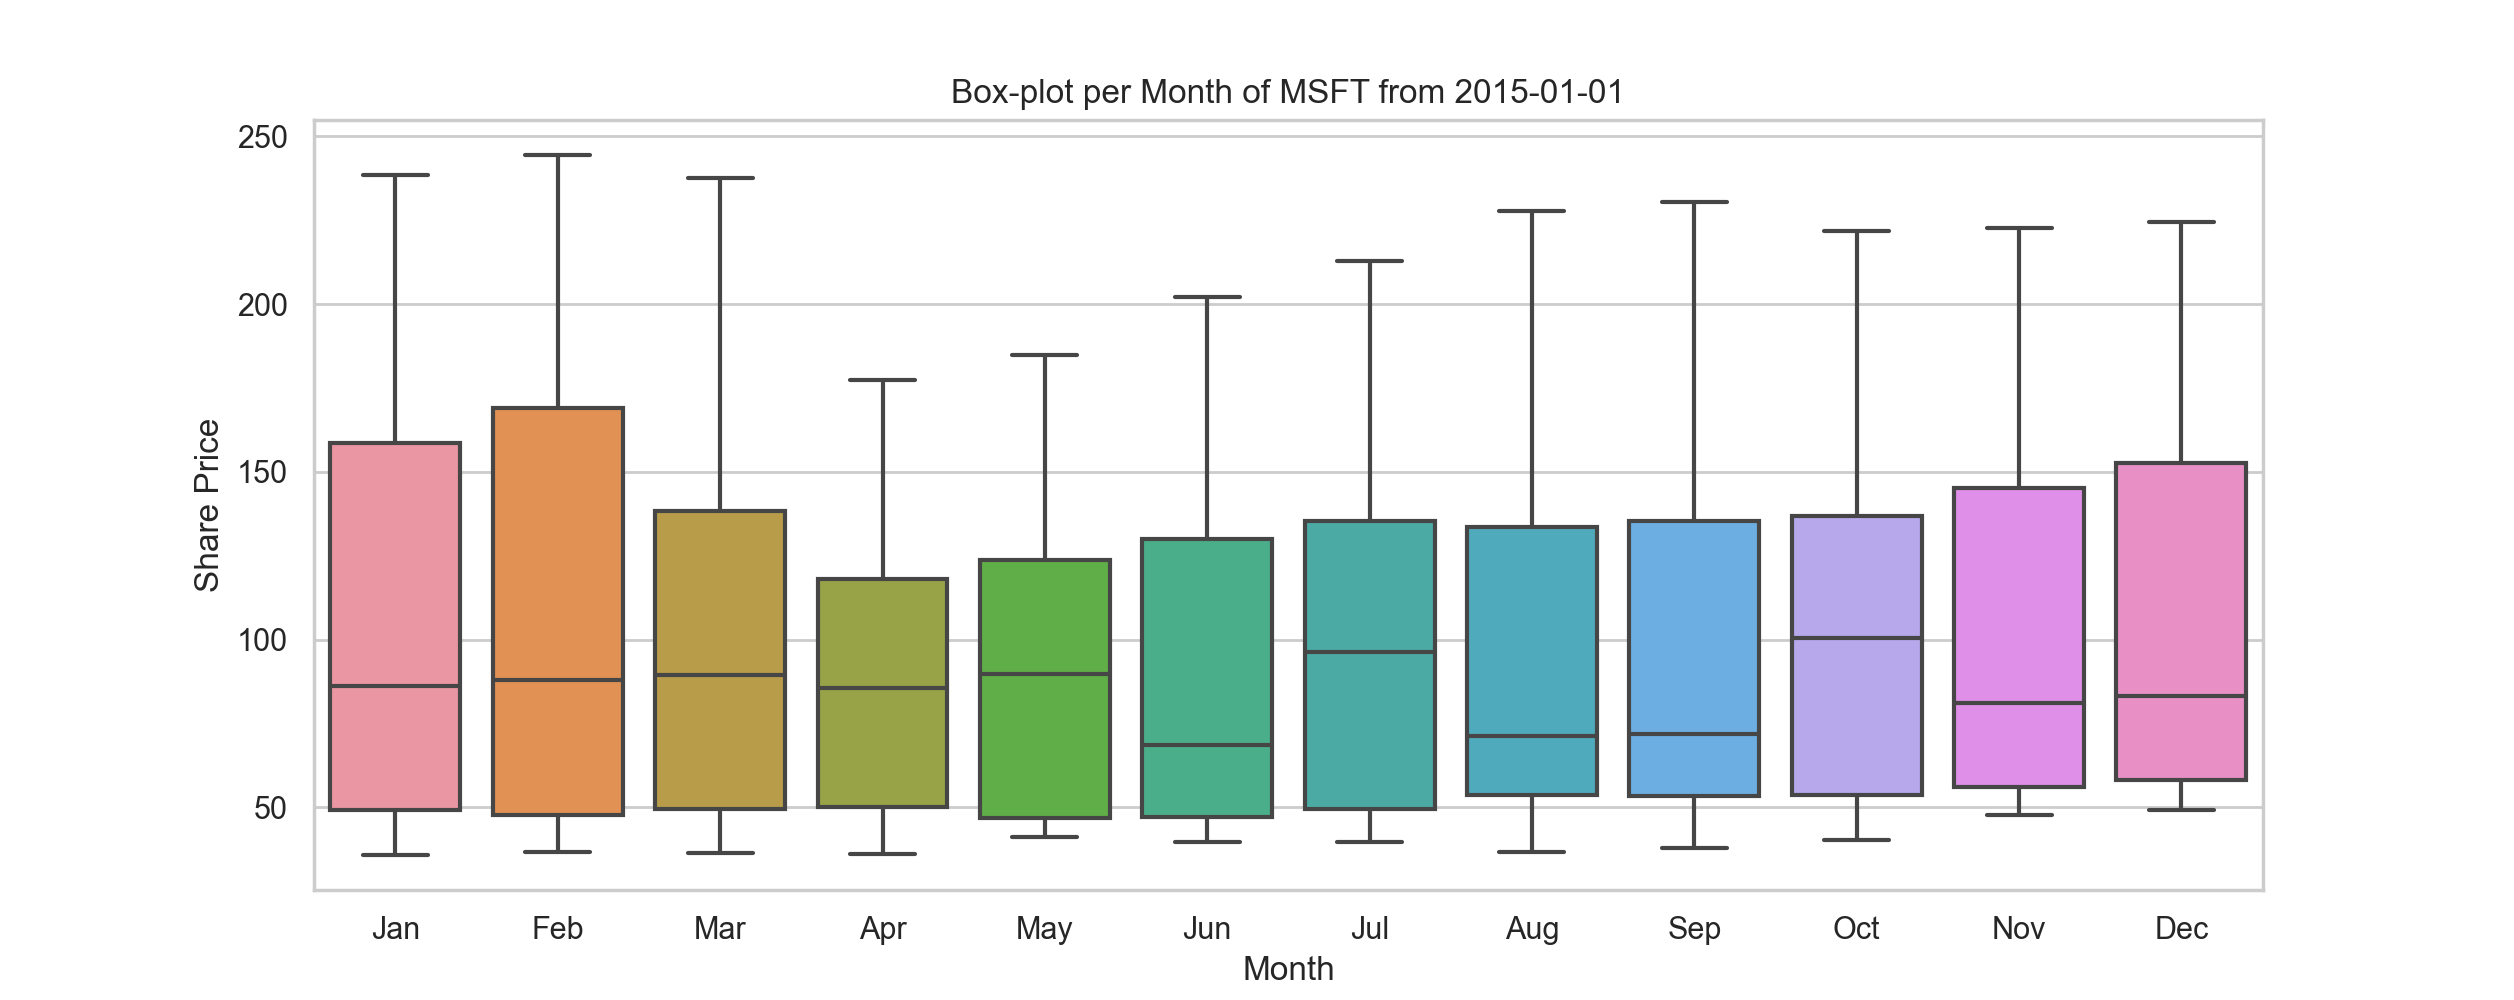
Box and Whisker plot
+Almost the same as a candle chart but with the very small difference that in addition to the open,close,min, max values it is also possible to specify a fifth, median value. The median lies between the open and close value and is illustrated as a horizontal line within the bar.
+
```
optional arguments:
-y, --yearly Flag to show yearly bw plot (default: False)
-h, --help show this help message (default: False)
```
-
+
 diff --git a/website/content/common/quantitative_analysis/capm/_index.md b/website/content/common/quantitative_analysis/capm/_index.md
index 0c63e6f6d75..4bb631d09f4 100644
--- a/website/content/common/quantitative_analysis/capm/_index.md
+++ b/website/content/common/quantitative_analysis/capm/_index.md
@@ -2,11 +2,17 @@
usage: capm [-h]
```
-Capital asset pricing model
+Capital asset pricing model for risk compared with the rest of the market.
```
optional arguments:
-h, --help show this help message (default: False)
```
+Sample output:
+```
+(✨) (stocks)>(qa)> capm
+Beta: -0.29
+Systematic Risk: 0.00%
+Unsystematic Risk: 100.00%
+```
-![capm]
diff --git a/website/content/common/quantitative_analysis/cdf/_index.md b/website/content/common/quantitative_analysis/cdf/_index.md
index 747117b2794..0fa4fc1fbe3 100755
--- a/website/content/common/quantitative_analysis/cdf/_index.md
+++ b/website/content/common/quantitative_analysis/cdf/_index.md
@@ -2,7 +2,44 @@
usage: cdf [--export {csv,json,xlsx}] [-h]
```
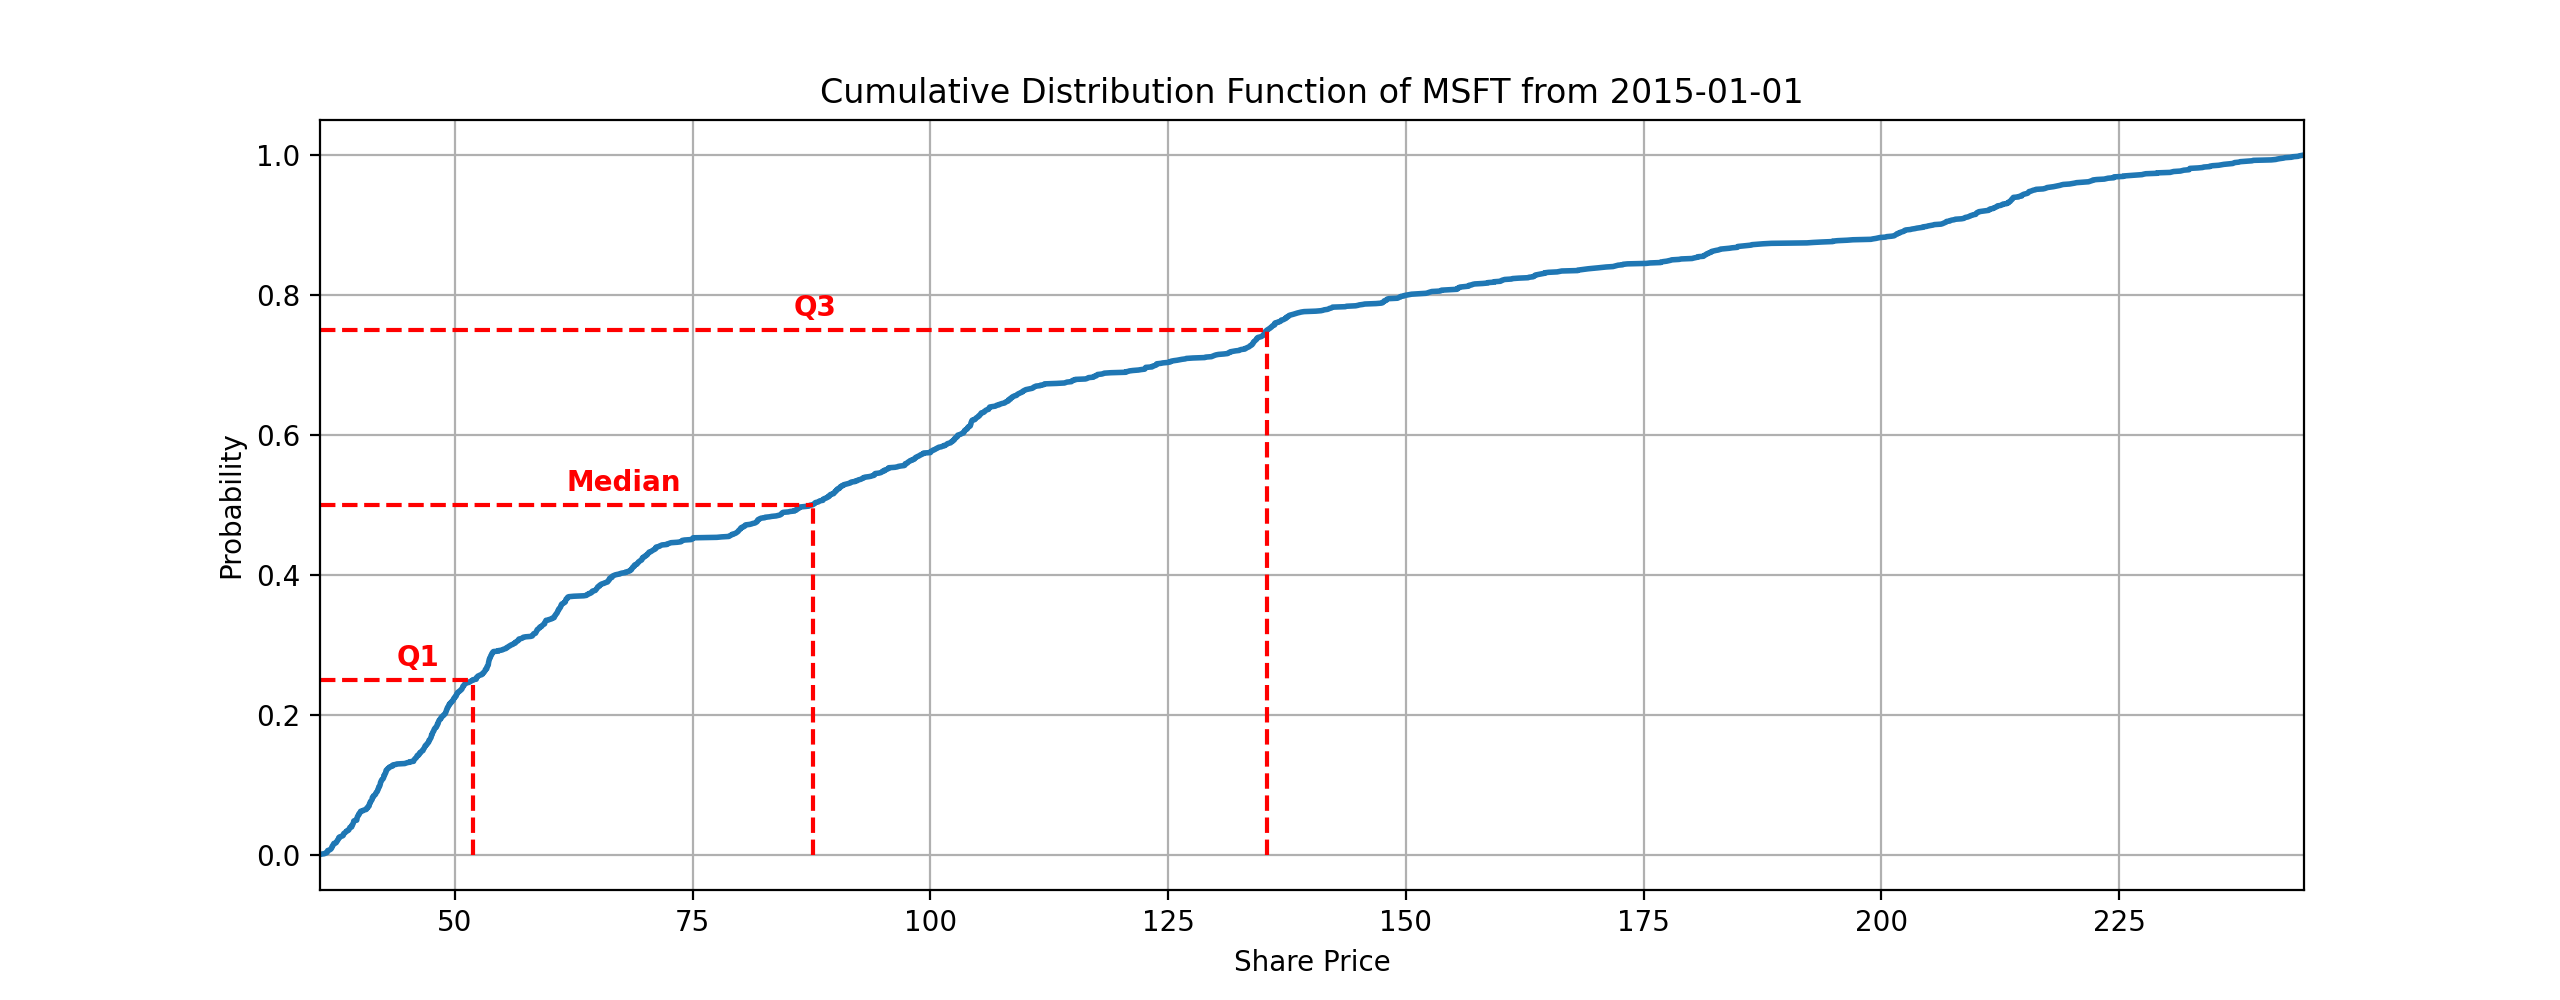
-Cumulative distribution function
+Explanation excerpt from: https://www.probabilitycourse.com/chapter3/3_2_1_cdf.php
+
+The cumulative distribution function (CDF) of a random variable is another method to describe the distribution of random variables. The advantage of the CDF is that it can be defined for any kind of random variable (discrete, continuous, and mixed).
+
+The cumulative distribution function (CDF) of random variable X is defined as:
+
+
+
+Contextual Example:
+
+I toss a coin twice. Let X be the number of observed heads. Find the CDF of X
+
+
```
optional arguments:
@@ -11,4 +48,4 @@ optional arguments:
-h, --help show this help message (default: False)
```
-
+
 diff --git a/website/content/common/quantitative_analysis/cusum/_index.md b/website/content/common/quantitative_analysis/cusum/_index.md
index 2f9ea379feb..075a66f0ba8 100755
--- a/website/content/common/quantitative_analysis/cusum/_index.md
+++ b/website/content/common/quantitative_analysis/cusum/_index.md
@@ -2,7 +2,9 @@
usage: cusum [-t THRESHOLD] [-d DRIFT] [-h]
```
-Cumulative sum algorithm (CUSUM) to detect abrupt changes in data
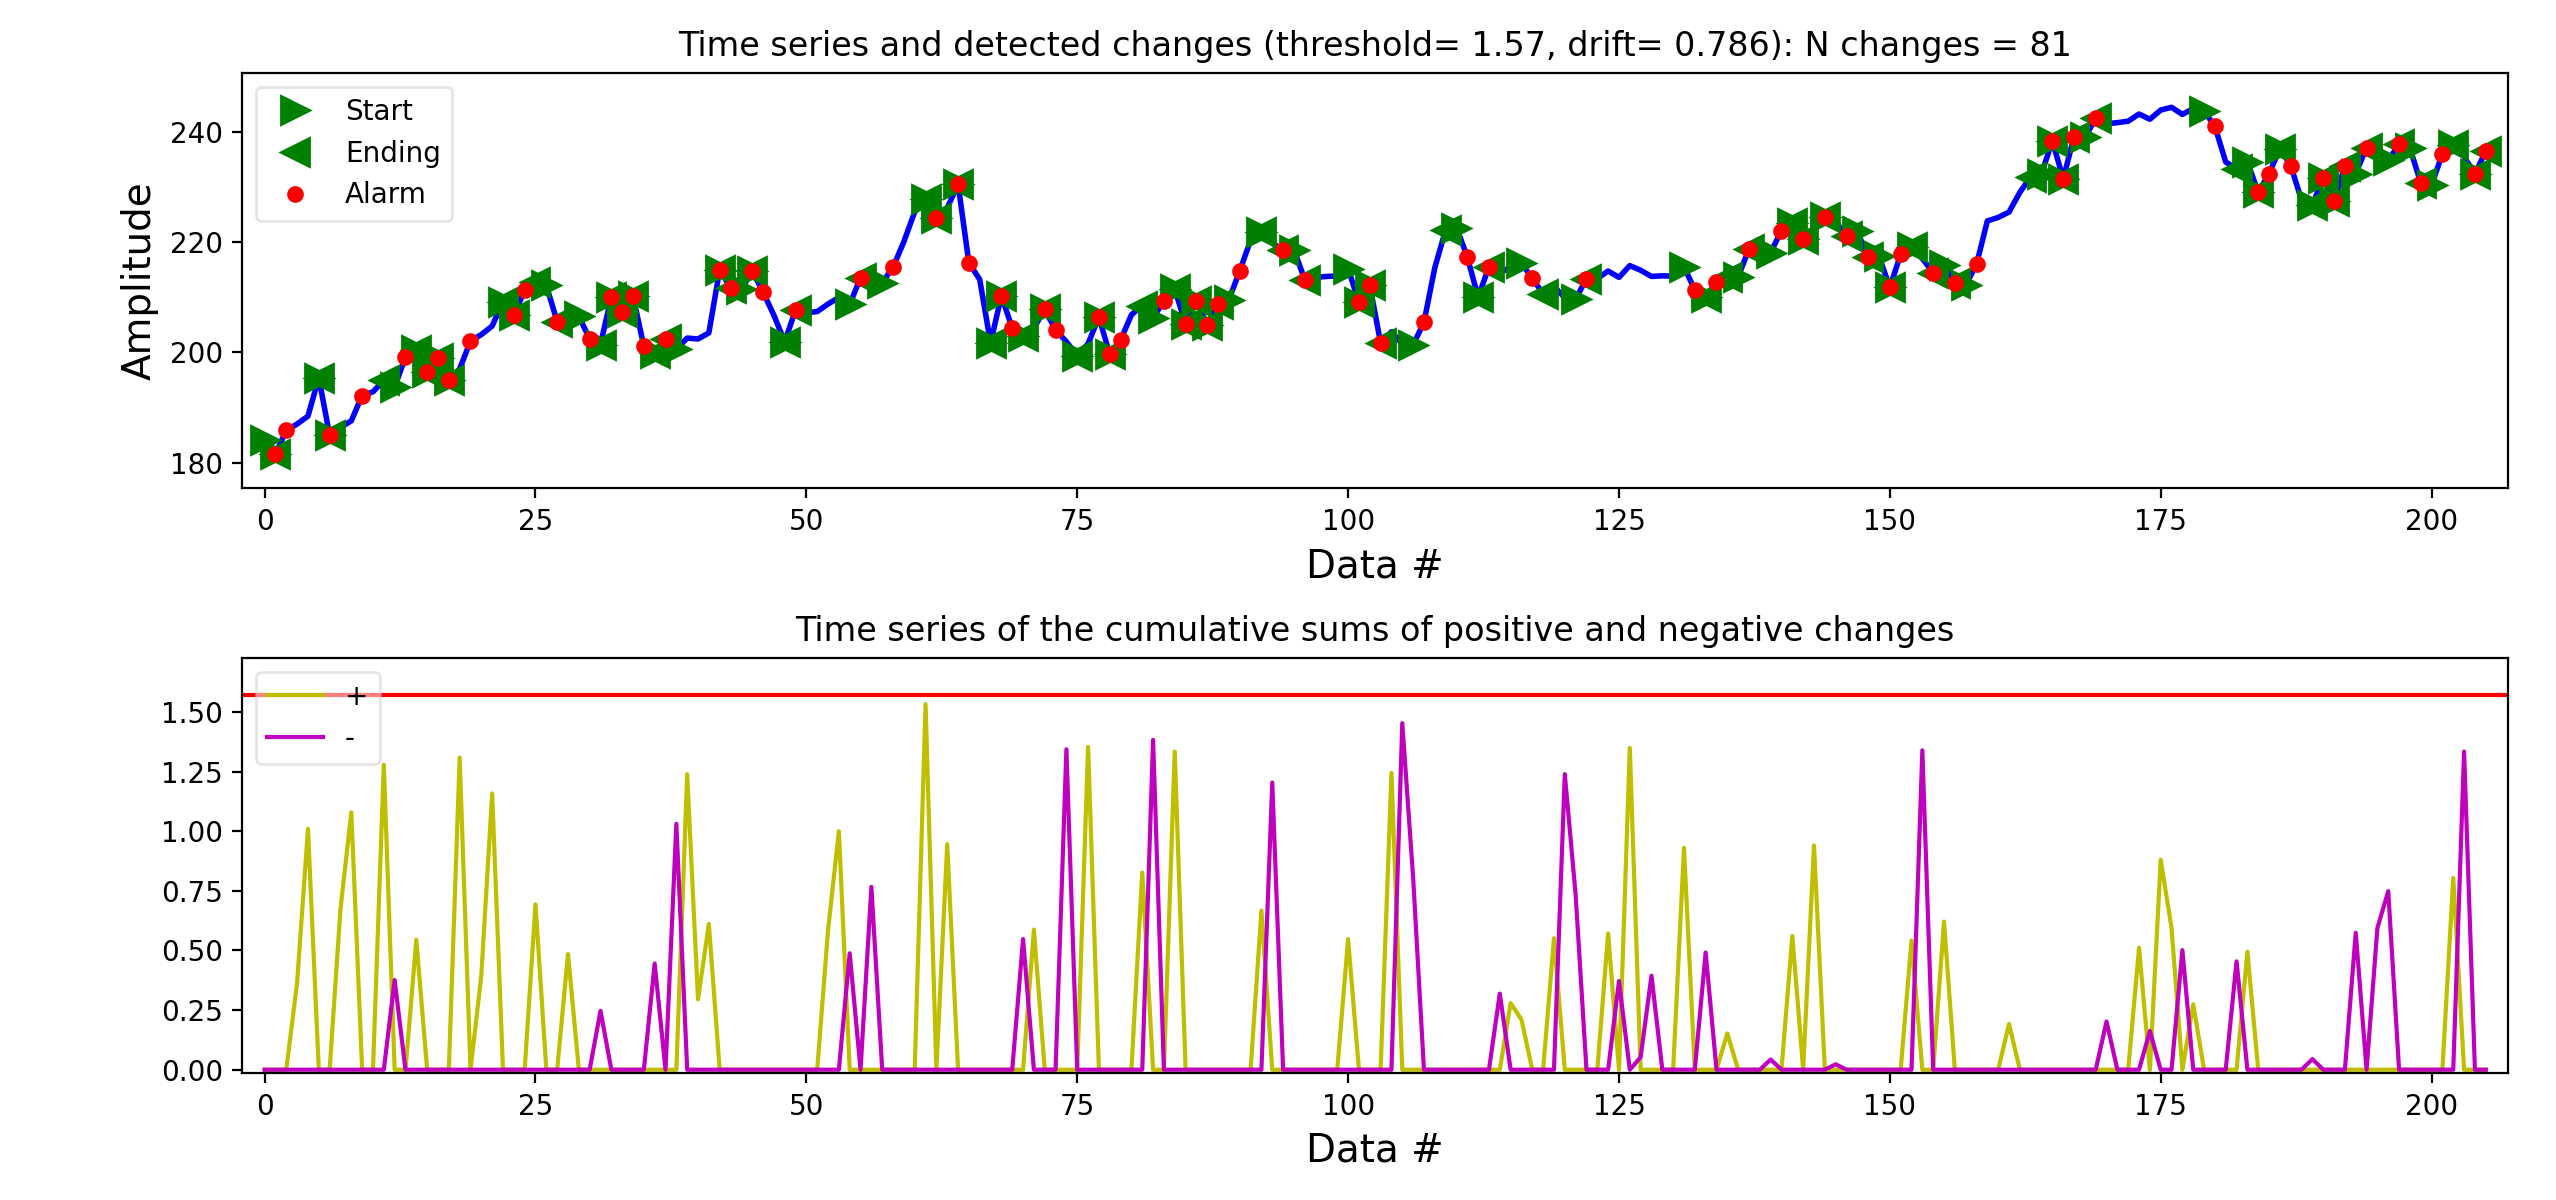
+Cumulative Sum Control Chart. A stochastic wave used as a stock market breadth indicator in mid-to-long term analysis, it is a sequential analysis technique for step detection in a time-series. The threshold can be thought of as the level where the background noise is at or below the level of the true signal.
+
+See this paper for a deep dive: https://econpapers.wiwi.kit.edu/downloads/KITe_WP_62.pdf
```
optional arguments:
@@ -13,4 +15,4 @@ optional arguments:
-h, --help show this help message (default: False)
```
-
+
 diff --git a/website/content/common/quantitative_analysis/data/_index.md b/website/content/common/quantitative_analysis/data/_index.md
index 4c0e2c7df22..ab97706f80c 100755
--- a/website/content/common/quantitative_analysis/data/_index.md
+++ b/website/content/common/quantitative_analysis/data/_index.md
@@ -1,14 +1,15 @@
-```
-usage: data [-e {csv, json, xlsx}] [-s SORT] [-d] [-n NUMBER] [-h]
+```text
+usage: raw [-n NUM] [-d] [-h] [--export {csv,json,xlsx}]
```
-Shows a table of historical information for a stock with the option to export the data [Source: Yahoo Finance]
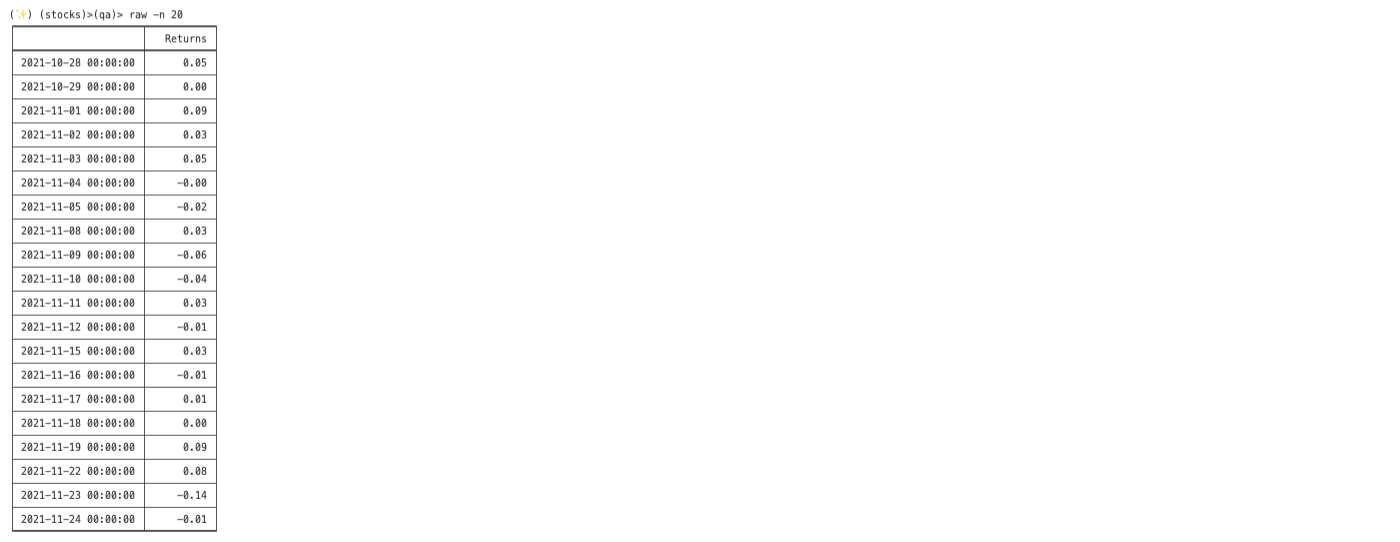
+Shows historical daily value for the target value.
```
optional arguments:
- -e, --export The format to export the information into
- -s, --sort Which column to sort the information by
- -d, --descending Show the information in descending order
- -n, --num Number of results to show
- -h, Help
+ -n NUM, --num NUM Number to show (default: 20)
+ -d, --descend Sort in descending order (default: False)
+ -h, --help show this help message (default: False)
+ --export {csv,json,xlsx}
+ Export raw data into csv, json, xlsx (default: )
```
+
 diff --git a/website/content/common/quantitative_analysis/decompose/_index.md b/website/content/common/quantitative_analysis/decompose/_index.md
index 8df3c4e4373..7cc95b39d47 100755
--- a/website/content/common/quantitative_analysis/decompose/_index.md
+++ b/website/content/common/quantitative_analysis/decompose/_index.md
@@ -2,11 +2,19 @@
usage: decompose [-m] [--export {csv,json,xlsx}] [-h]
```
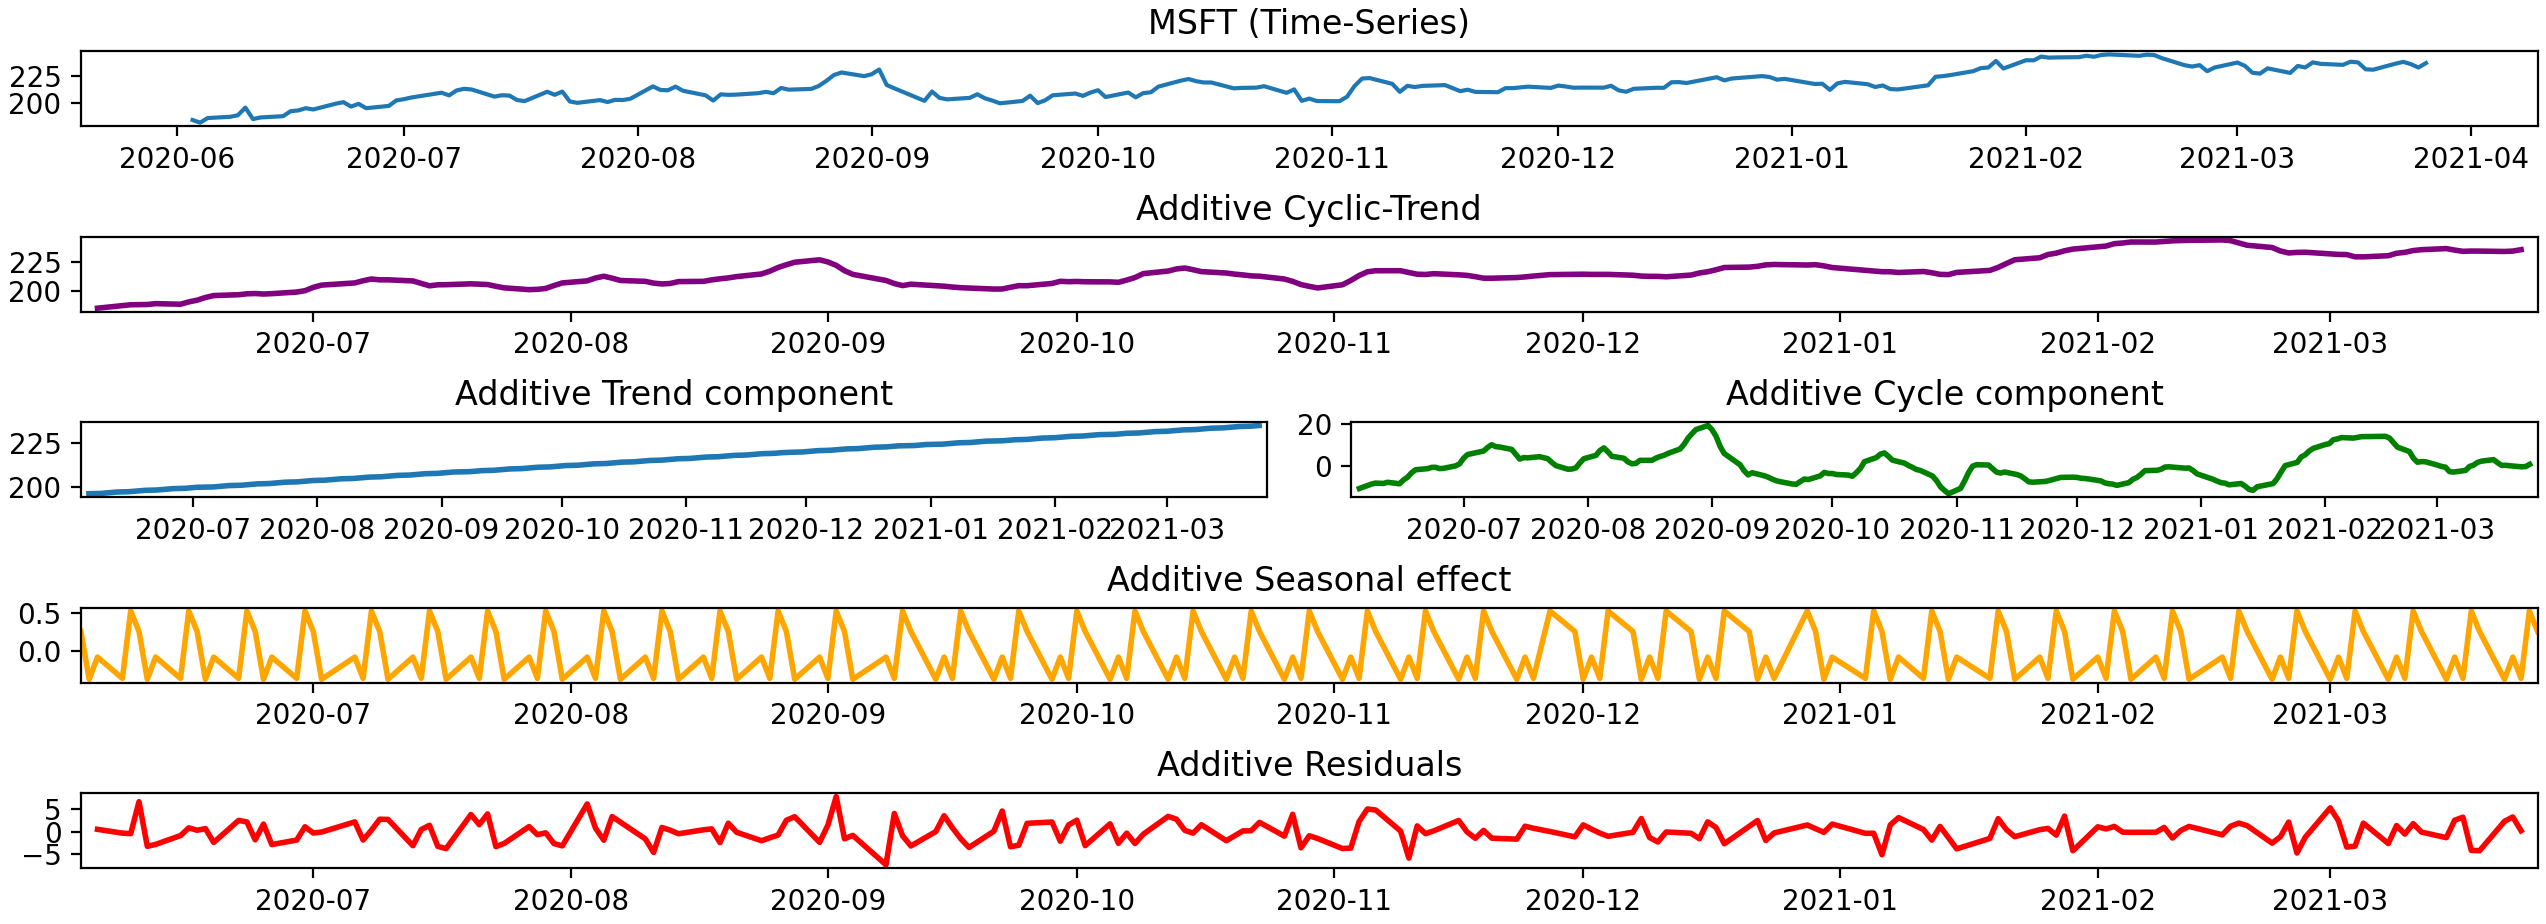
+This type of forcasting attempts to separate and index factors thought to have meaningful impact on the otherwise random movements in stock prices.
+
Decompose time series as:
- Additive Time Series = Level + CyclicTrend + Residual + Seasonality
- Multiplicative Time Series = Level * CyclicTrend *
Residual * Seasonality
+For a detailed research paper discussing analysis of the Indian Auto Sector, download the PDF here: https://www.researchgate.net/publication/290263806_Decomposition_of_Time_Series_Data_of_Stock_Markets_and_its_Implications_for_Prediction_-_An_Application_for_the_Indian_Auto_Sector
+
+"This will help in stock selection in the following ways. First, it will indicate the overall trend of the sector, hence the stock price, and help in taking a position. Second, if seasonality patterns can be seen, then during which month which sector and hence which stock should be a good buy, can be inferred. Third, the random component will throw some light on the volatility pattern of the sector and hence the stock. This decomposition will indicate which of the three components are stronger and can shed further light on the efficient market hypothesis. The decomposition will bring out the overall macroeconomic characteristic of a sector, which affects the fundamentals of a company."
+
+
+
```
optional arguments:
-m, --multiplicative decompose using multiplicative model instead of additive (default: False)
@@ -15,6 +23,6 @@ optional arguments:
-h, --help show this help message (default: False)
```
-
+
 -
 +
diff --git a/website/content/common/quantitative_analysis/hist/_index.md b/website/content/common/quantitative_analysis/hist/_index.md
index cf57cb23b59..6377c3d1641 100755
--- a/website/content/common/quantitative_analysis/hist/_index.md
+++ b/website/content/common/quantitative_analysis/hist/_index.md
@@ -2,7 +2,7 @@
usage: hist [-b N_BINS] [-h]
```
-Histogram with density and rug
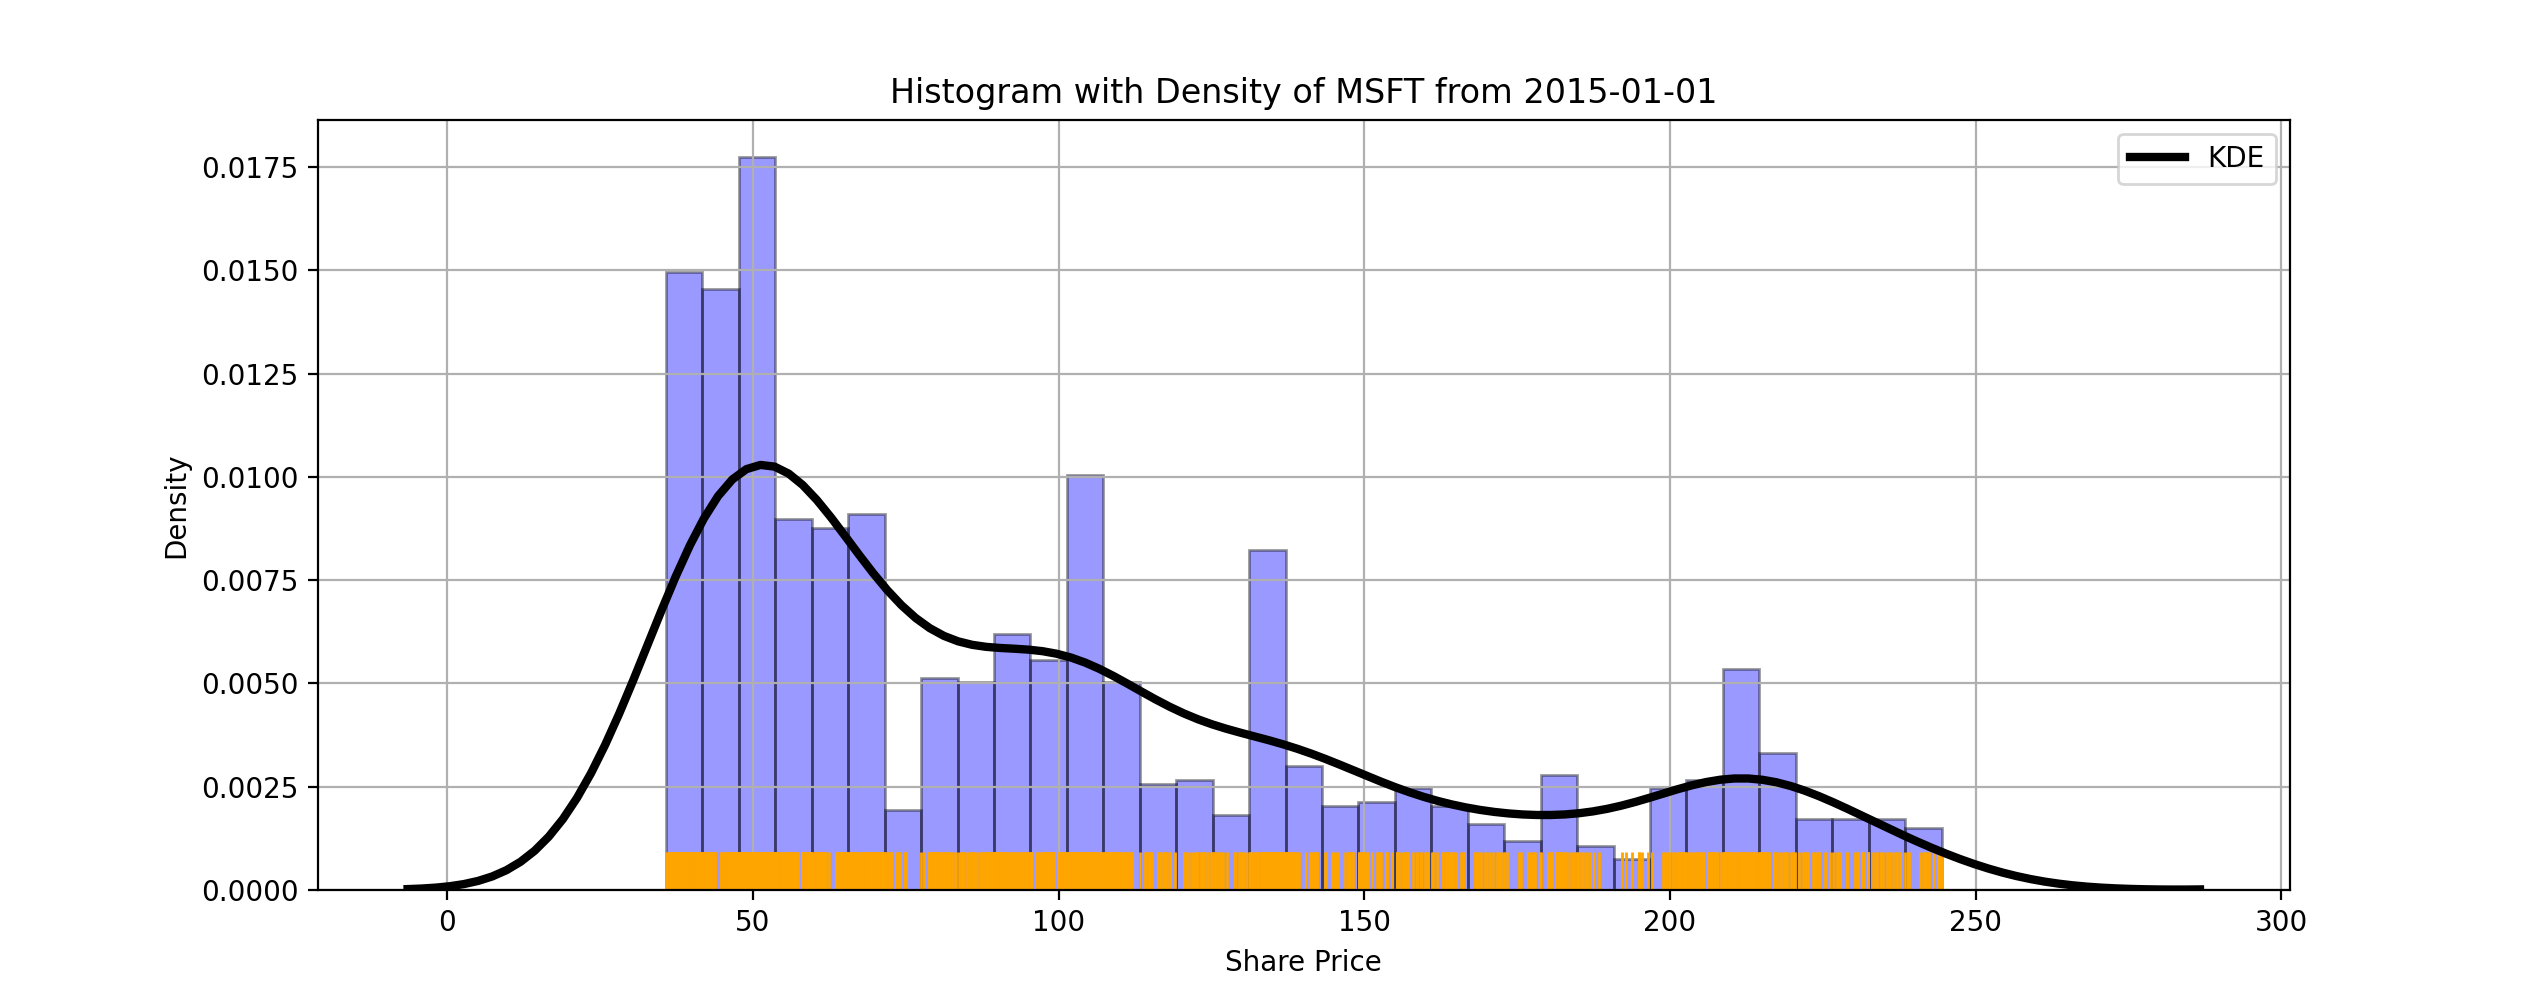
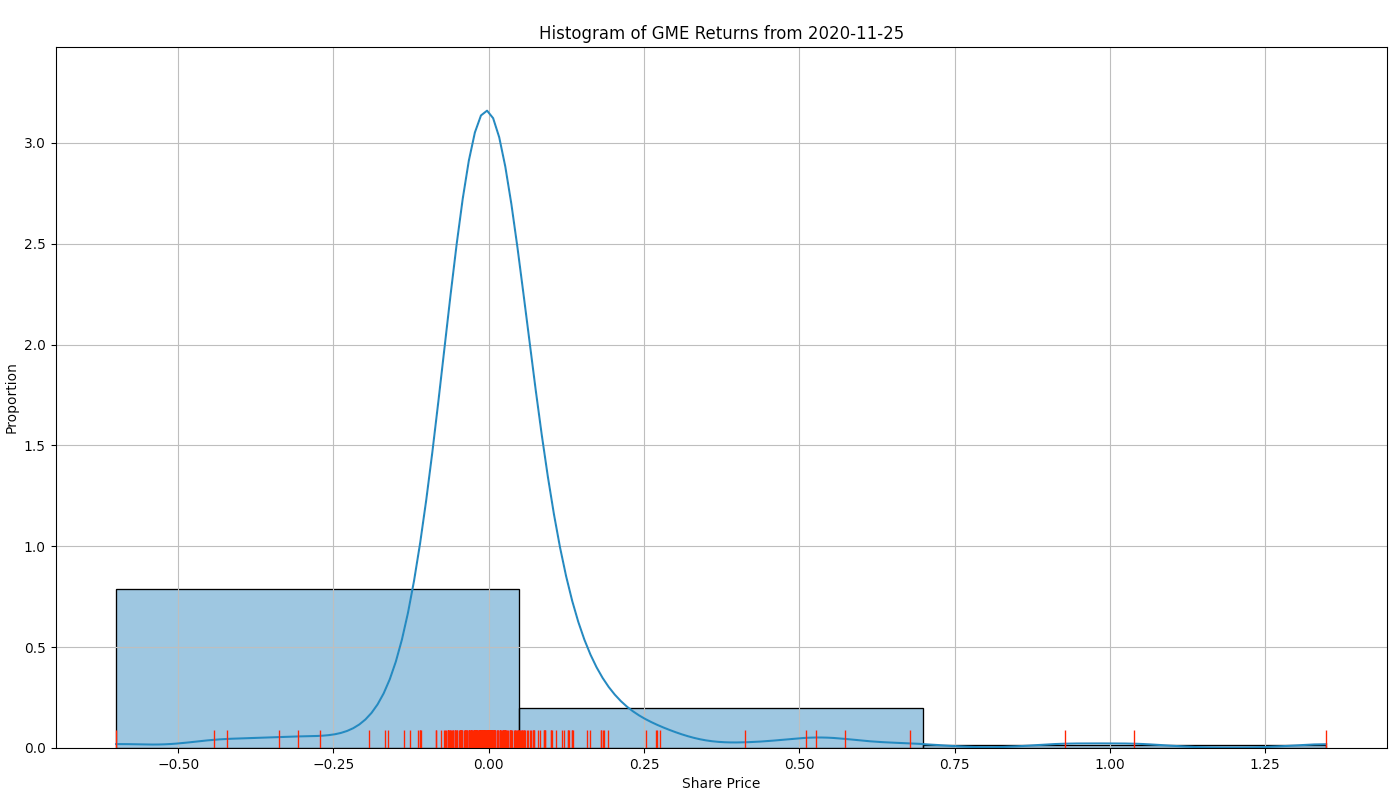
+Histogram of proportional gains by entry point from a specified date, divisible into a specified number of distributed groups.
```
optional arguments:
@@ -10,4 +10,4 @@ optional arguments:
-h, --help show this help message (default: False)
```
-
+
 diff --git a/website/content/common/quantitative_analysis/kurtosis/_index.md b/website/content/common/quantitative_analysis/kurtosis/_index.md
index 012bd69d86e..a0f546b1c43 100644
--- a/website/content/common/quantitative_analysis/kurtosis/_index.md
+++ b/website/content/common/quantitative_analysis/kurtosis/_index.md
@@ -2,6 +2,15 @@
usage: kurtosis [-l N_LENGTH] [--export {csv,json,xlsx}] [-h]
```
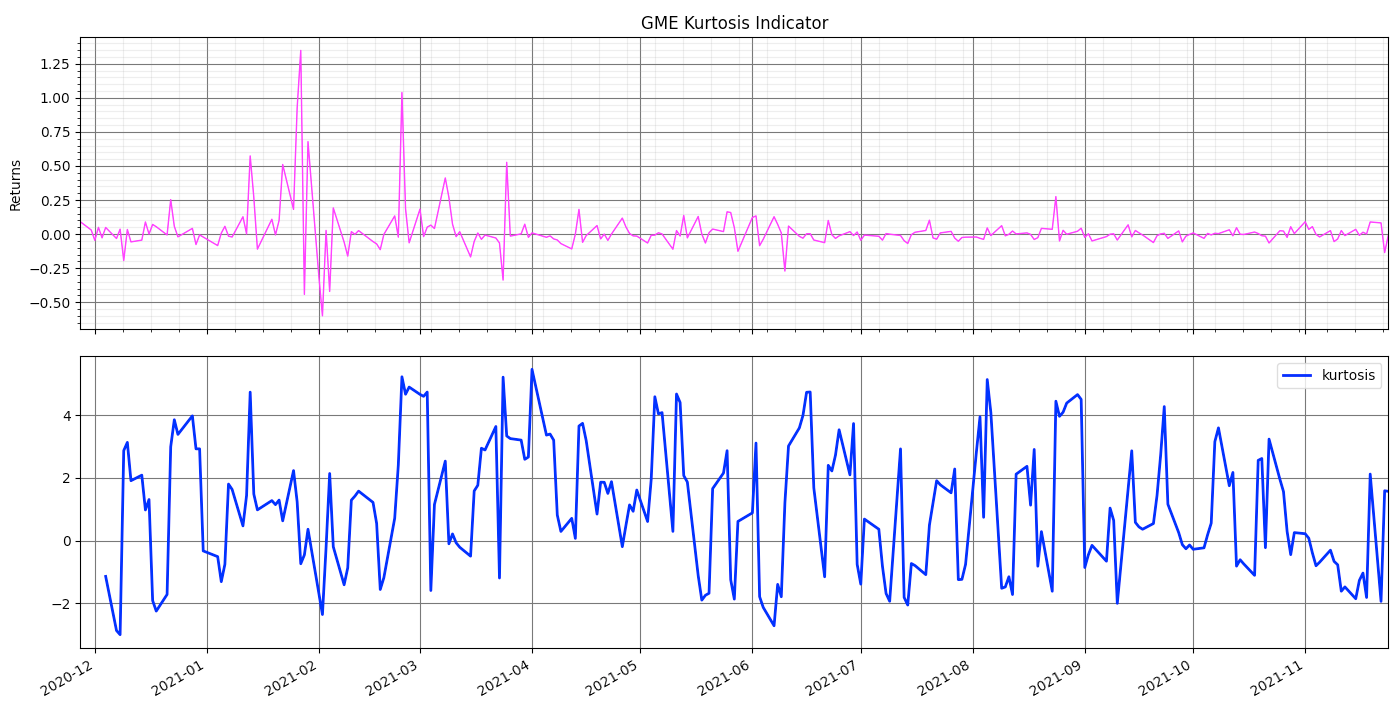
Kurtosis is a measure of the "tailedness" of the probability distribution of a real-valued random variable. Like skewness, kurtosis describes the shape of a probability distribution and there are different ways of quantifying it for a theoretical distribution and corresponding ways of estimating it from a sample from a population. Different measures of kurtosis may have different interpretations.
+
+For research on this topic, visit: https://www.styleadvisor.com/resources/statfacts/kurtosis
+
+Kurtosis identifies where the volatility risk came from in a distribution of returns. Kurtosis improves one’s understanding of volatility risk.
+
+Kurtosis is also known as the fourth moment of the distribution, used in conjunction with mean, standard deviation, and skewness to understand the shape of a distribution of returns. In its base case, kurtosis has a neutral value of 3.0. The calculation is frequently modified by the second term in the equation below, which scales kurtosis so that the baseline, neutral value is 0.0.
+
+
+
```
optional arguments:
-l N_LENGTH, --length N_LENGTH
@@ -10,3 +19,4 @@ optional arguments:
Export dataframe data to csv,json,xlsx file (default: )
-h, --help show this help message (default: False)
```
+
 diff --git a/website/content/common/quantitative_analysis/load/_index.md b/website/content/common/quantitative_analysis/load/_index.md
index 33e269a3296..e722d225fab 100755
--- a/website/content/common/quantitative_analysis/load/_index.md
+++ b/website/content/common/quantitative_analysis/load/_index.md
@@ -1,19 +1 @@
-```text
-usage: load [-t S_TICKER] [-s S_START_DATE] [-i {1,5,15,30,60}] [--source {yf,av,iex}] [-p] [-h]
-```
-
-Load stock ticker to perform analysis on. When the data source is 'yf', an Indian ticker can be loaded by using '.NS' at the end, e.g. 'SBIN.NS'. See
-available market in https://help.yahoo.com/kb/exchanges-data-providers-yahoo-finance-sln2310.html.
-
-```
-optional arguments:
- -t S_TICKER, --ticker S_TICKER
- Stock ticker (default: None)
- -s S_START_DATE, --start S_START_DATE
- The starting date (format YYYY-MM-DD) of the stock (default: 2020-09-15)
- -i {1,5,15,30,60}, --interval {1,5,15,30,60}
- Intraday stock minutes (default: 1440)
- --source {yf,av,iex} Source of historical data. (default: yf)
- -p, --prepost Pre/After market hours. Only works for 'yf' source, and intraday data (default: False)
- -h, --help show this help message (default: False)
-```
+Use the [load](https://gamestonkterminal.github.io/GamestonkTerminal/stocks/load/) command within the submenu.
diff --git a/website/content/common/quantitative_analysis/normality/_index.md b/website/content/common/quantitative_analysis/normality/_index.md
index abc8016a725..c6cd0f1db8c 100755
--- a/website/content/common/quantitative_analysis/normality/_index.md
+++ b/website/content/common/quantitative_analysis/normality/_index.md
@@ -4,9 +4,24 @@ usage: normality [--export {csv,json,xlsx}] [-h]
Normality tests
+To learn more about this subject, visit the Wiki page: https://en.wikipedia.org/wiki/Normality_test
+
+A 2011 study concludes that Shapiro–Wilk has the best power for a given significance, followed closely by Anderson–Darling when comparing the Shapiro–Wilk, Kolmogorov–Smirnov, Lilliefors, and Anderson–Darling tests.
+
```
optional arguments:
--export {csv,json,xlsx}
Export dataframe data to csv,json,xlsx file (default: )
-h, --help show this help message (default: False)
```
+Sample output
+```
+(✨) (stocks)>(qa)> normality
+╒═══════════╤════════════╤════════════╤═══════════════╤════════════════╤══════════════════════╕
+│ │ Kurtosis │ Skewness │ Jarque-Bera │ Shapiro-Wilk │ Kolmogorov-Smirnov │
+╞═══════════╪════════════╪════════════╪═══════════════╪════════════════╪══════════════════════╡
+│ Statistic │ -0.8178 │ -4.1427 │ 20.0985 │ 0.8818 │ 1.0000 │
+├───────────┼────────────┼────────────┼───────────────┼────────────────┼──────────────────────┤
+│ p-value │ 0.4135 │ 0.0000 │ 0.0000 │ 0.0000 │ 0.0000 │
+╘═══════════╧════════════╧════════════╧═══════════════╧════════════════╧══════════════════════╛
+```
diff --git a/website/content/common/quantitative_analysis/pick/_index.md b/website/content/common/quantitative_analysis/pick/_index.md
index da3023e647b..25230526442 100755
--- a/website/content/common/quantitative_analysis/pick/_index.md
+++ b/website/content/common/quantitative_analysis/pick/_index.md
@@ -1,8 +1,7 @@
```text
usage: pick [-t {Open,High,Low,Close,AdjClose,Volume,Returns,LogRet}] [-h]
```
-
-Change target variable
+Select a target variable from the available arguments listed.
```
optional arguments:
@@ -10,3 +9,4 @@ optional arguments:
Select variable to analyze (default: None)
-h, --help show this help message (default: False)
```
+
 diff --git a/website/content/common/quantitative_analysis/qqplot/_index.md b/website/content/common/quantitative_analysis/qqplot/_index.md
index d706bdb1371..ec22a56c581 100755
--- a/website/content/common/quantitative_analysis/qqplot/_index.md
+++ b/website/content/common/quantitative_analysis/qqplot/_index.md
@@ -2,9 +2,20 @@
usage: qqplot [-h]
```
-Display QQ plot vs normal quantiles
+Display Q-Q plot vs normal quantiles. See the Wiki page on this topic here: https://en.wikipedia.org/wiki/Q–Q_plot
+
+A Q–Q plot is used to compare the shapes of distributions, providing a graphical view of how properties such as location, scale, and skewness are similar or different in the two distributions. Q–Q plots can be used to compare collections of data, or theoretical distributions. The use of Q–Q plots to compare two samples of data can be viewed as a non-parametric approach to comparing their underlying distributions. A Q–Q plot is generally a more powerful approach to do this than the common technique of comparing histograms of the two samples, but requires more skill to interpret. Q–Q plots are commonly used to compare a data set to a theoretical model.
+
+The points plotted in a Q–Q plot are always non-decreasing when viewed from left to right. If the two distributions being compared are identical, the Q–Q plot follows the 45° line y = x. If the two distributions agree after linearly transforming the values in one of the distributions, then the Q–Q plot follows some line, but not necessarily the line y = x. If the general trend of the Q–Q plot is flatter than the line y = x, the distribution plotted on the horizontal axis is more dispersed than the distribution plotted on the vertical axis. Conversely, if the general trend of the Q–Q plot is steeper than the line y = x, the distribution plotted on the vertical axis is more dispersed than the distribution plotted on the horizontal axis. Q–Q plots are often arced, or "S" shaped, indicating that one of the distributions is more skewed than the other, or that one of the distributions has heavier tails than the other.
+
+Although a Q–Q plot is based on quantiles, in a standard Q–Q plot it is not possible to determine which point in the Q–Q plot determines a given quantile. For example, it is not possible to determine the median of either of the two distributions being compared by inspecting the Q–Q plot. Some Q–Q plots indicate the deciles to make determinations such as this possible.
+
+The intercept and slope of a linear regression between the quantiles gives a measure of the relative location and relative scale of the samples. If the median of the distribution plotted on the horizontal axis is 0, the intercept of a regression line is a measure of location, and the slope is a measure of scale. The distance between medians is another measure of relative location reflected in a Q–Q plot. The "probability plot correlation coefficient" (PPCC plot) is the correlation coefficient between the paired sample quantiles. The closer the correlation coefficient is to one, the closer the distributions are to being shifted, scaled versions of each other. For distributions with a single shape parameter, the probability plot correlation coefficient plot provides a method for estimating the shape parameter – one simply computes the correlation coefficient for different values of the shape parameter, and uses the one with the best fit, just as if one were comparing distributions of different types.
+
+Another common use of Q–Q plots is to compare the distribution of a sample to a theoretical distribution, such as the standard normal distribution N(0,1), as in a normal probability plot. As in the case when comparing two samples of data, one orders the data (formally, computes the order statistics), then plots them against certain quantiles of the theoretical distribution.
```
optional arguments:
-h, --help show this help message (default: False)
```
+
diff --git a/website/content/common/quantitative_analysis/quantile/_index.md b/website/content/common/quantitative_analysis/quantile/_index.md
index fa5239e85d6..c03e2250565 100755
--- a/website/content/common/quantitative_analysis/quantile/_index.md
+++ b/website/content/common/quantitative_analysis/quantile/_index.md
@@ -2,8 +2,12 @@
usage: quantile [-l N_LENGTH] [-q F_QUANTILE] [--export {csv,json,xlsx}] [-h]
```
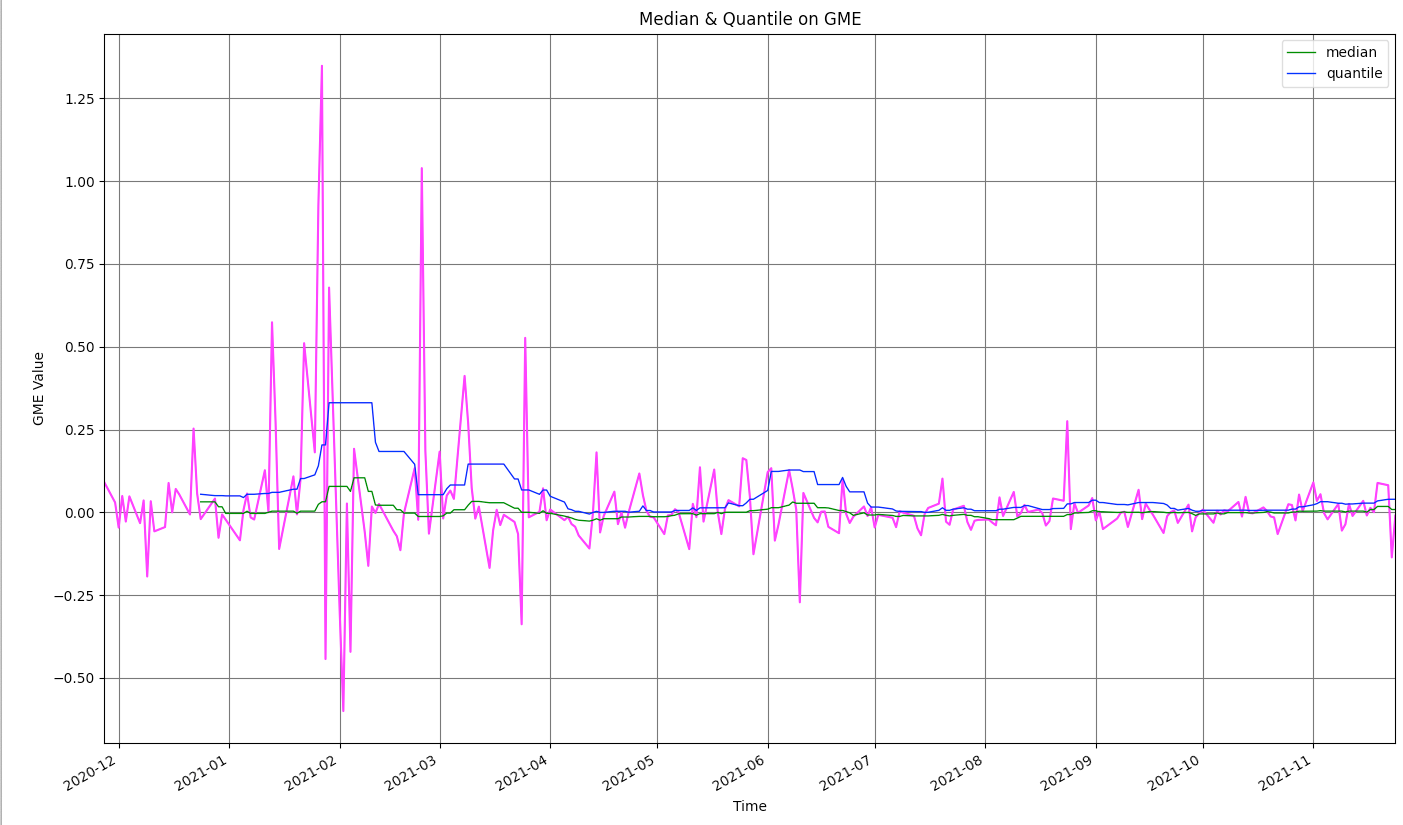
+In statistics and probability, quantiles are cut points dividing the range of a probability distribution into continuous intervals with equal probabilities, or dividing the observations in a sample in the same way.
+
The quantiles are values which divide the distribution such that there is a given proportion of observations below the quantile. For example, the median is a quantile. The median is the central value of the distribution, such that half the points are less than or equal to it and half are greater than or equal to it. By default, q is set at 0.5, which effectively is median. Change q to get the desired quantile (0 < q < 1).
+See the Wiki page on this topic for further explanation: https://en.wikipedia.org/wiki/Quantile
+
```
optional arguments:
-l N_LENGTH, --length N_LENGTH
@@ -14,3 +18,5 @@ optional arguments:
Export dataframe data to csv,json,xlsx file (default: )
-h, --help show this help message (default: False)
```
+
 +
diff --git a/website/content/common/quantitative_analysis/rolling/_index.md b/website/content/common/quantitative_analysis/rolling/_index.md
index 3a3c1d61ad0..25e2fdc4f5c 100755
--- a/website/content/common/quantitative_analysis/rolling/_index.md
+++ b/website/content/common/quantitative_analysis/rolling/_index.md
@@ -4,6 +4,10 @@ usage: rolling [-l N_LENGTH] [--export {csv,json,xlsx}] [-h]
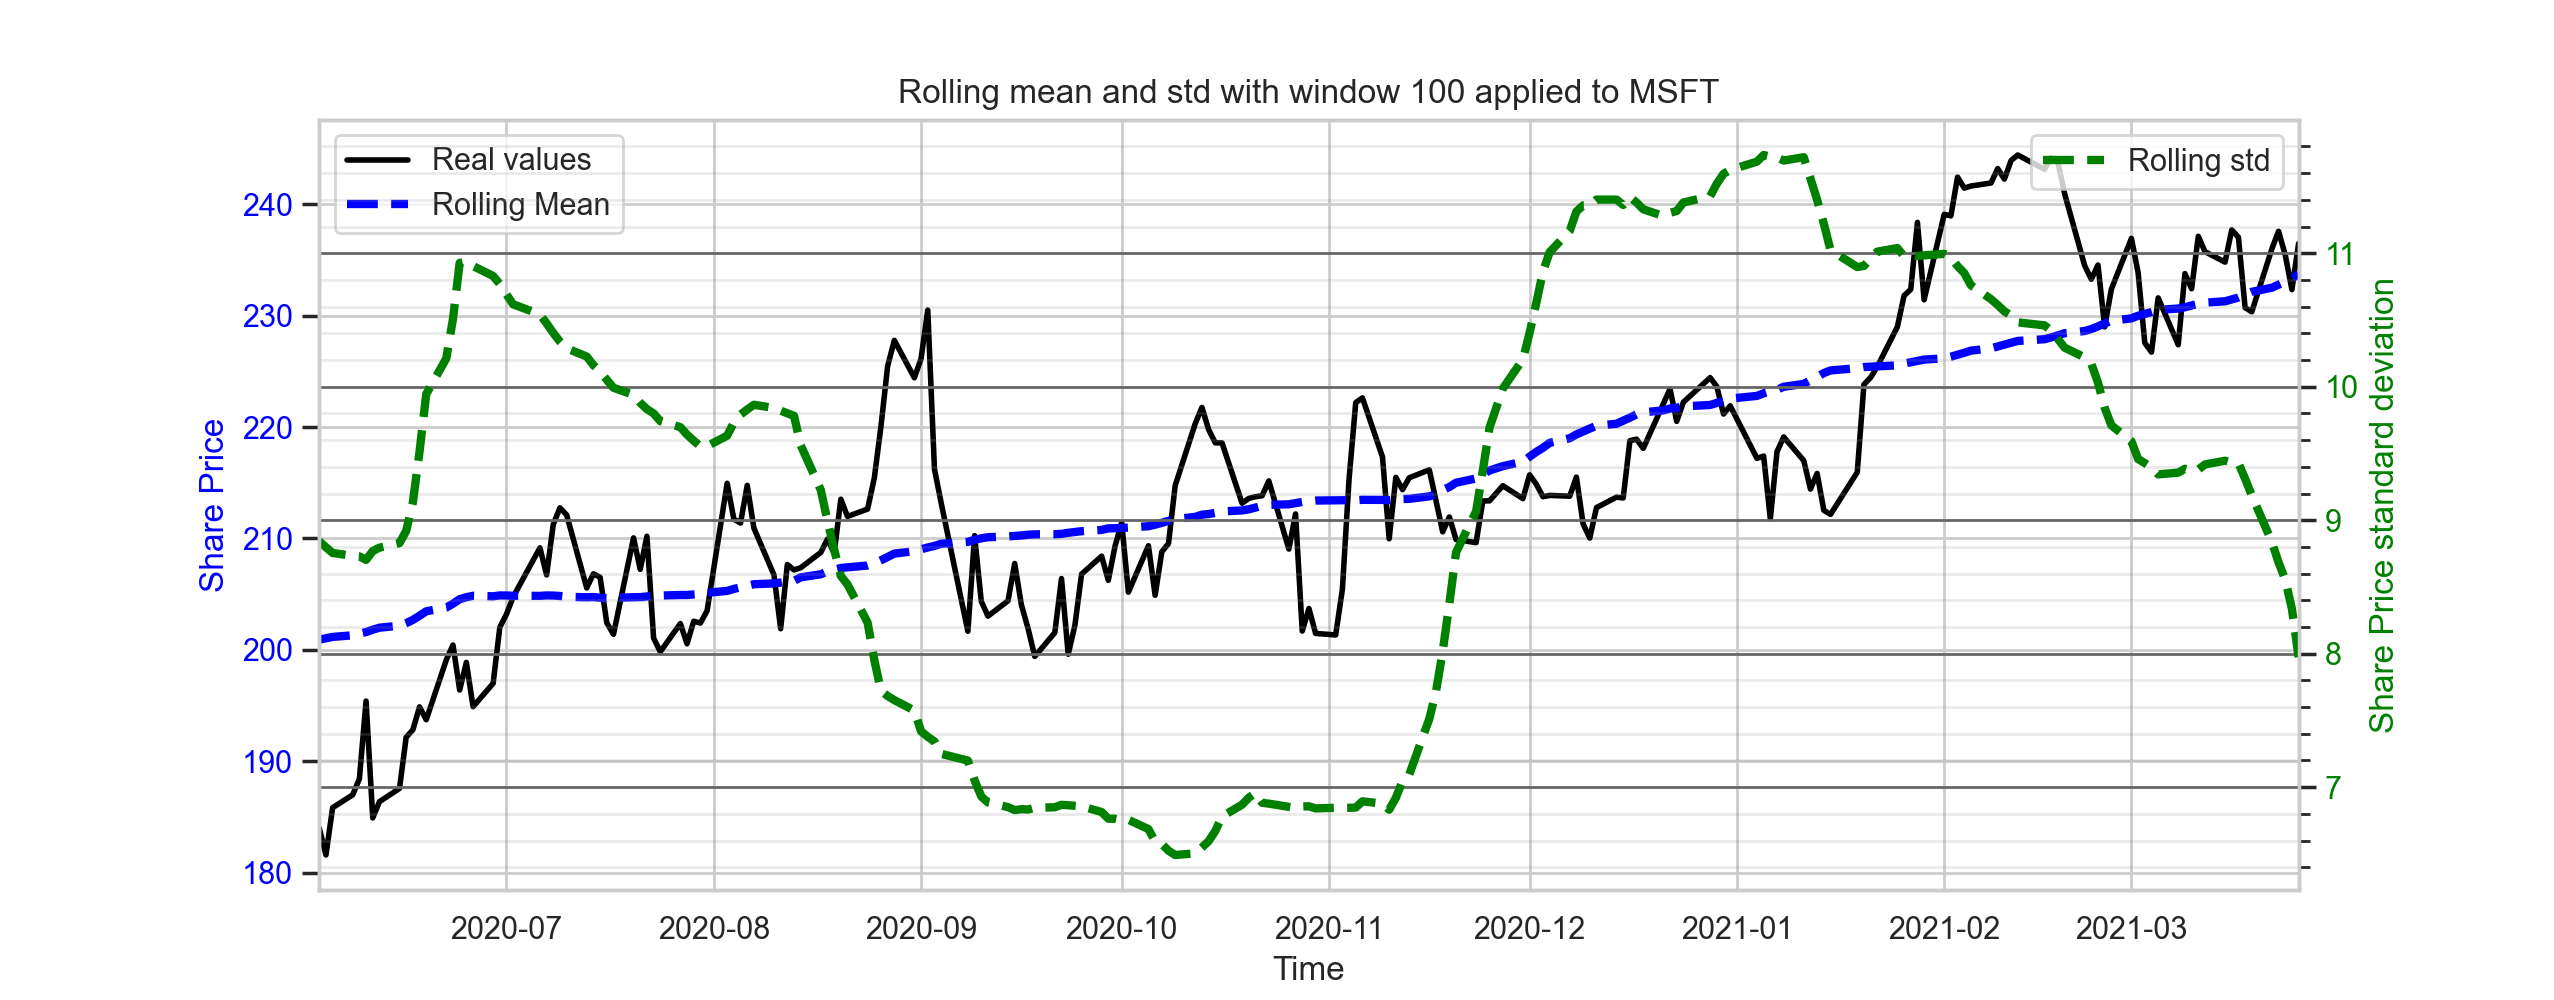
Rolling mean and std deviation
+
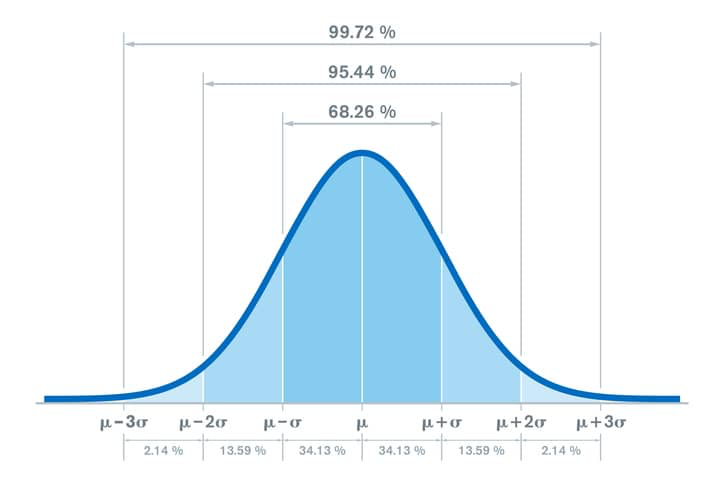 +
+To learn more on this topic, visit: https://www.mathsisfun.com/data/standard-normal-distribution.html
+
```
optional arguments:
-l N_LENGTH, --length N_LENGTH
@@ -13,4 +17,4 @@ optional arguments:
-h, --help show this help message (default: False)
```
-
+
 diff --git a/website/content/common/quantitative_analysis/skew/_index.md b/website/content/common/quantitative_analysis/skew/_index.md
index 9fe90747c5d..f1d818360ae 100755
--- a/website/content/common/quantitative_analysis/skew/_index.md
+++ b/website/content/common/quantitative_analysis/skew/_index.md
@@ -3,6 +3,8 @@ usage: skew [-l N_LENGTH] [--export {csv,json,xlsx}] [-h]
```
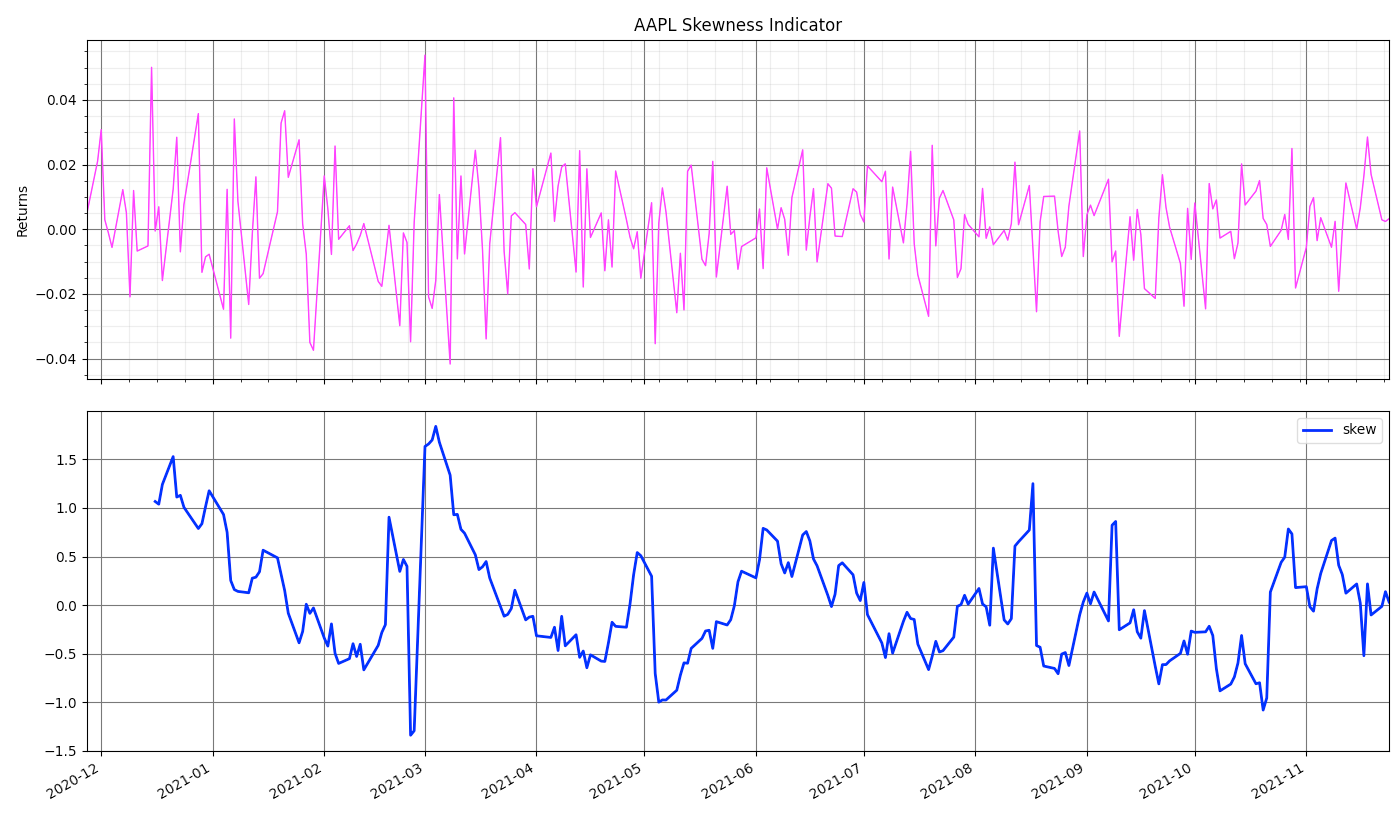
Skewness is a measure of asymmetry or distortion of symmetric distribution. It measures the deviation of the given distribution of a random variable from a symmetric distribution, such as normal distribution. A normal distribution is without any skewness, as it is symmetrical on both sides. Hence, a curve is regarded as skewed if it is shifted towards the right or the left.
+See the Wiki page for a detailed explanation: https://en.wikipedia.org/wiki/Skewness
+
```
optional arguments:
-l N_LENGTH, --length N_LENGTH
@@ -11,3 +13,4 @@ optional arguments:
Export dataframe data to csv,json,xlsx file (default: )
-h, --help show this help message (default: False)
```
+
 diff --git a/website/content/common/quantitative_analysis/spread/_index.md b/website/content/common/quantitative_analysis/spread/_index.md
index e75300d10ad..3b39f0b933d 100755
--- a/website/content/common/quantitative_analysis/spread/_index.md
+++ b/website/content/common/quantitative_analysis/spread/_index.md
@@ -1,6 +1,7 @@
```text
usage: spread [-l N_LENGTH] [--export {csv,json,xlsx}] [-h]
```
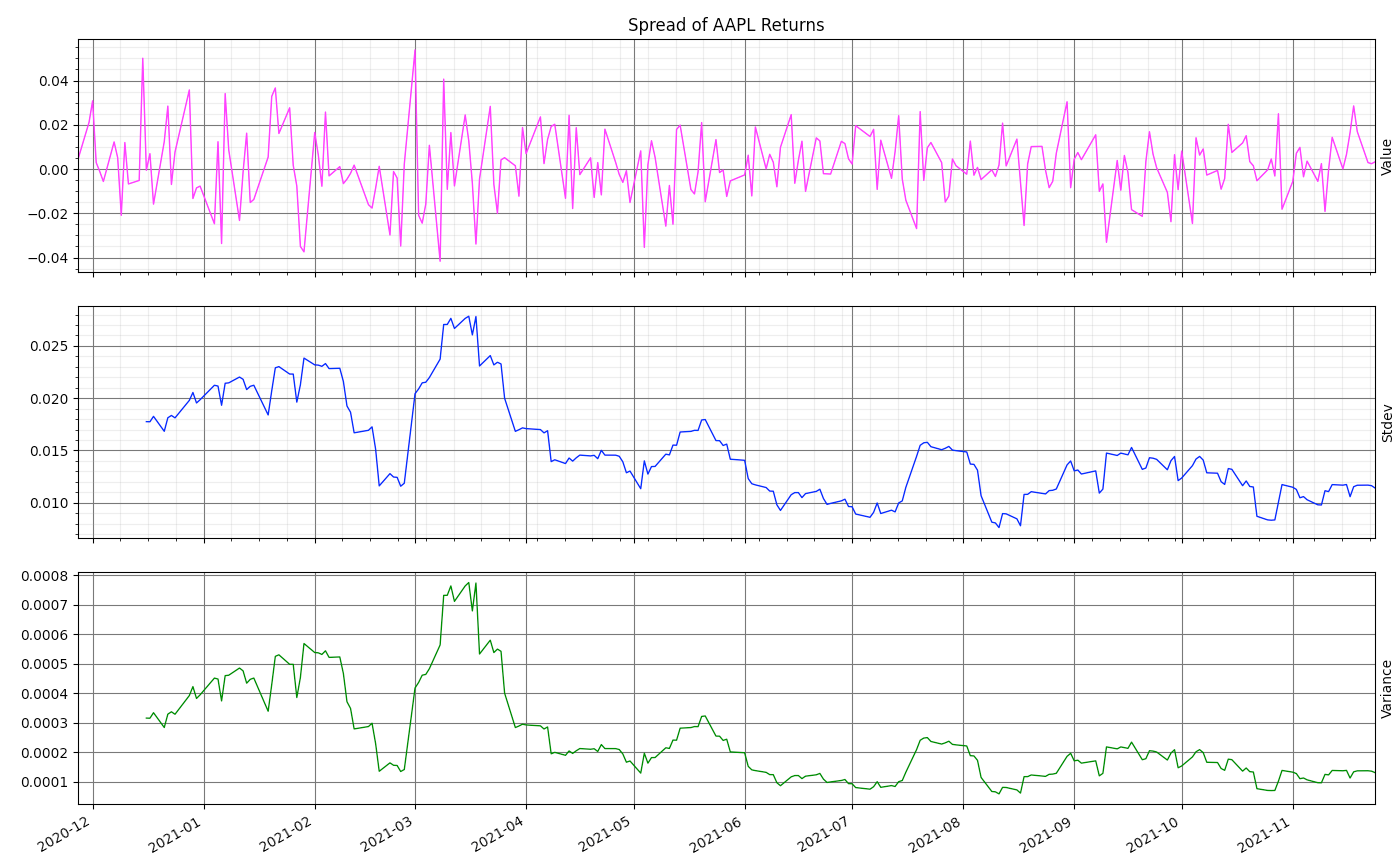
+Displays the spread of the picked target variable for three statistics: value, standard deviation, variance.
```
optional arguments:
@@ -10,3 +11,4 @@ optional arguments:
Export dataframe data to csv,json,xlsx file (default: )
-h, --help show this help message (default: False)
```
+
 diff --git a/website/content/common/quantitative_analysis/summary/_index.md b/website/content/common/quantitative_analysis/summary/_index.md
index 205fa9d9c11..a941806b8df 100755
--- a/website/content/common/quantitative_analysis/summary/_index.md
+++ b/website/content/common/quantitative_analysis/summary/_index.md
@@ -2,7 +2,7 @@
usage: summary [--export {csv,json,xlsx}] [-h]
```
-Summary statistics
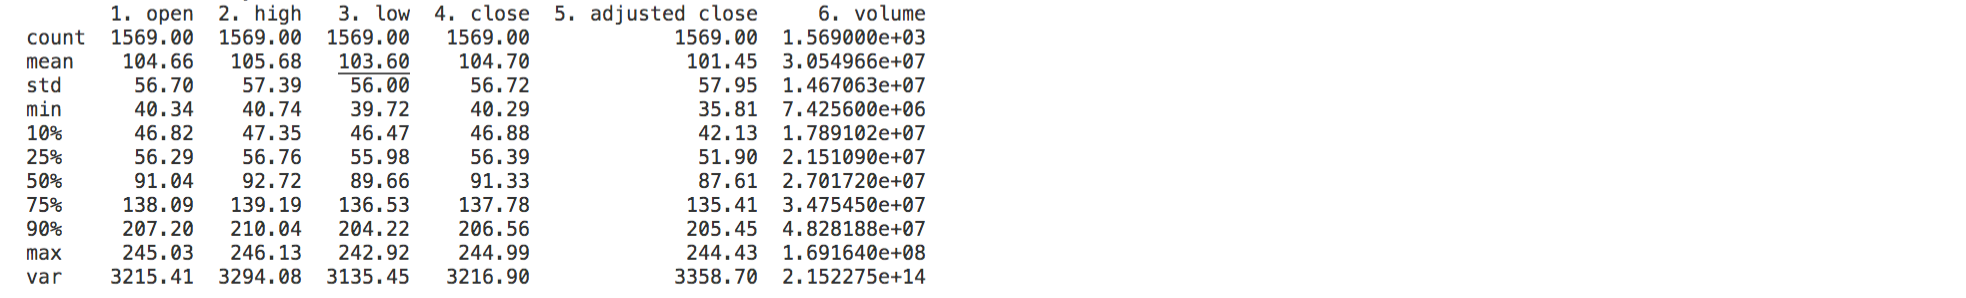
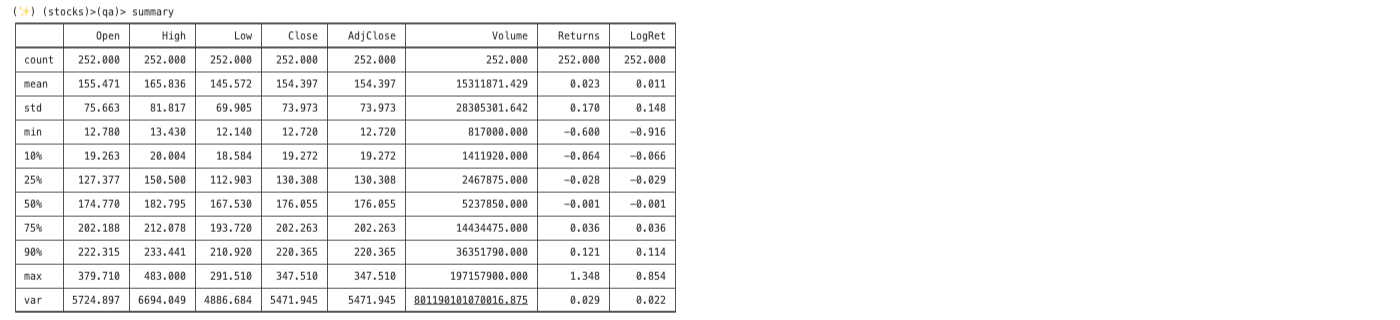
+Summary of statistics derived from the target variable.
```
optional arguments:
@@ -11,4 +11,5 @@ optional arguments:
-h, --help show this help message (default: False)
```
-
 +
 +
diff --git a/website/content/common/quantitative_analysis/unitroot/_index.md b/website/content/common/quantitative_analysis/unitroot/_index.md
index df124fcc44a..7bfc93e11b9 100755
--- a/website/content/common/quantitative_analysis/unitroot/_index.md
+++ b/website/content/common/quantitative_analysis/unitroot/_index.md
@@ -4,6 +4,10 @@ usage: unitroot [-r {c,ct,ctt,nc}] [-k {c,ct}] [--export {csv,json,xlsx}] [-h]
Unit root test / stationarity (ADF, KPSS)
+In statistics, a unit root test tests whether a time series variable is non-stationary and possesses a unit root. The null hypothesis is generally defined as the presence of a unit root and the alternative hypothesis is either stationarity, trend stationarity or explosive root depending on the test used.
+
+See the Wiki page on this subject for more information: https://en.wikipedia.org/wiki/Unit_root_test
+
```
optional arguments:
-r {c,ct,ctt,nc}, --fuller_reg {c,ct,ctt,nc}
@@ -14,3 +18,20 @@ optional arguments:
Export dataframe data to csv,json,xlsx file (default: )
-h, --help show this help message (default: False)
```
+Sample output:
+```
+(✨) (stocks)>(qa)> unitroot
+╒════════════════╤═══════════╤═════════════════════╕
+│ │ ADF │ KPSS │
+╞════════════════╪═══════════╪═════════════════════╡
+│ Test Statistic │ -4.8135 │ 0.38852605166304083 │
+├────────────────┼───────────┼─────────────────────┤
+│ P-Value │ 0.0001 │ 0.08210083980041344 │
+├────────────────┼───────────┼─────────────────────┤
+│ NLags │ 9.0000 │ 7 │
+├────────────────┼───────────┼─────────────────────┤
+│ Nobs │ 242.0000 │ │
+├────────────────┼───────────┼─────────────────────┤
+│ ICBest │ -188.0797 │ │
+╘════════════════╧═══════════╧═════════════════════╛
+```