diff --git a/gamestonk_terminal/README.md b/gamestonk_terminal/README.md
index a1d86689ddb..b5f1857b160 100644
--- a/gamestonk_terminal/README.md
+++ b/gamestonk_terminal/README.md
@@ -242,7 +242,6 @@ Command|Description|Source
Command|Technique|Sources
------ | ------------|---
-`sma` |simple moving average | [Wikipedia](https://en.wikipedia.org/wiki/Moving_average#Simple_moving_average), [Investopedia](https://www.investopedia.com/terms/s/sma.asp)
`knn` |k-Nearest Neighbors | [Wikipedia](https://en.wikipedia.org/wiki/K-nearest_neighbors_algorithm)
`linear` |linear regression (polynomial 1) | [Wikipedia](https://en.wikipedia.org/wiki/Linear_regression), [Investopedia](https://www.investopedia.com/terms/r/regression.asp)
`quadratic` |quadratic regression (polynomial 2) | [Wikipedia](https://en.wikipedia.org/wiki/Polynomial_regression), [Investopedia](https://www.investopedia.com/terms/r/regression.asp)
@@ -253,7 +252,7 @@ Command|Technique|Sources
`mlp` |MultiLayer Perceptron | [Wikipedia](https://en.wikipedia.org/wiki/Multilayer_perceptron)
`rnn` |Recurrent Neural Network | [Wikipedia](https://en.wikipedia.org/wiki/Recurrent_neural_network)
`lstm` |Long Short-Term Memory | [Wikipedia](https://en.wikipedia.org/wiki/Long_short-term_memory), [Details](https://colah.github.io/posts/2015-08-Understanding-LSTMs/)
-
+`conv1d` |1D Convolution Neural Net| [Wikipedia](https://en.wikipedia.org/wiki/Convolutional_neural_network)
## Portfolio Analysis [»](portfolio/README.md)
diff --git a/gamestonk_terminal/config_neural_network_models.py b/gamestonk_terminal/config_neural_network_models.py
index 24358030438..38ef798e18e 100644
--- a/gamestonk_terminal/config_neural_network_models.py
+++ b/gamestonk_terminal/config_neural_network_models.py
@@ -23,7 +23,7 @@ MultiLayer_Perceptron = [
{"Dense": {"units": 100, "activation": "relu"}},
{"Dense": {"units": 80, "activation": "relu"}},
{"Dense": {"units": 30, "activation": "relu"}},
- {"Dense": {"activation": "linear"}},
+ {"Dense": {"activation": "relu"}},
]
Recurrent_Neural_Network = [
@@ -31,11 +31,40 @@ Recurrent_Neural_Network = [
{"SimpleRNN": {"units": 50, "activation": "linear", "return_sequences": True}},
{"Dropout": {"rate": 0.2}},
{"SimpleRNN": {"units": 21, "activation": "linear", "return_sequences": False}},
- {"Dense": {"activation": "linear"}},
+ {"Dense": {"activation": "relu"}},
]
Long_Short_Term_Memory = [
{"LSTM": {"units": 25, "activation": "tanh", "return_sequences": True}},
{"LSTM": {"units": 15, "activation": "tanh", "return_sequences": False}},
- {"Dense": {"activation": "linear"}},
+ {"Dense": {"activation": "relu"}},
]
+
+Convolutional = [
+ {"Conv1D": {"filters": 20, "kernel_size": 10, "activation": "relu"}},
+ {"MaxPool1D": {"pool_size": 2}},
+ {"Conv1D": {"filters": 10, "kernel_size": 5, "activation": "relu"}},
+ {"MaxPool1D": {"pool_size": 2}},
+ {"Flatten": {}},
+ {"Dense": {"activation": "relu"}},
+]
+
+# Optimizers : https://www.tensorflow.org/api_docs/python/tf/keras/optimizers
+# Adam, Adagrad, Adadelta, Adamax,Ftrl, Nadam, Rmsprop, Sgd
+Optimizer = "Adam"
+
+# Add early stopping to save time training when validation is plateaued
+# Can be set to large number or None to ignore
+Early_Stop_Patience = 10
+
+# Losses https://www.tensorflow.org/api_docs/python/tf/keras/losses
+# mae, mape, mse, msle, poisson, logcosh, kld, hinge, squared_hinge, huber
+Loss = "mae"
+
+# Preprocessing technique to use : https://scikit-learn.org/stable/modules/preprocessing.html
+# Options are:
+# minmax - Adjusts data to be between 0 and 1 - Most Used for Stocks
+# standardization - Standardizes data so that it has mean 0 and standard deviation = 1
+# normalization - Normalizes data so that L2 norm (sum x_i^2) = 1
+# none - No preprocessing
+Preprocess = "minmax"
diff --git a/gamestonk_terminal/main_helper.py b/gamestonk_terminal/main_helper.py
index e4ba51b173b..78c072f40fd 100644
--- a/gamestonk_terminal/main_helper.py
+++ b/gamestonk_terminal/main_helper.py
@@ -150,7 +150,7 @@ def load(l_args, s_ticker, s_start, s_interval, df_stock):
"-s",
"--start",
type=valid_date,
- default="2015-01-01",
+ default="2019-01-01",
dest="s_start_date",
help="The starting date (format YYYY-MM-DD) of the stock",
)
diff --git a/gamestonk_terminal/prediction_techniques/FUNE-TUNING-NN-models.md b/gamestonk_terminal/prediction_techniques/FUNE-TUNING-NN-models.md
index ad4ab6bab15..2468e6f8c43 100644
--- a/gamestonk_terminal/prediction_techniques/FUNE-TUNING-NN-models.md
+++ b/gamestonk_terminal/prediction_techniques/FUNE-TUNING-NN-models.md
@@ -16,7 +16,17 @@ load MSFT -s 2014-01-01
3. **Out of this training data, select which part will be used for validation**
-Since this is a timeseries, and the data has a sequence, the data at the end of the timeseries is the one to be used for validation. As a rule of thumb I usually try to "steal" the least amount of data from the training set, since the more recent the data the more important it is for training. Hence, one could set the end date of training data to be the current day - days of predictions.
+Anyone reading this, note this is quite a discussion between the devs. Since this is a time series, there is an inherent
+ordering of the data. However, since returns are random, it is hard to predict, and ordering data may not have any meaning.
+
+To this end, we allow users to specify how much validation data to use and if it should be shuffled. By default, we will split
+into 10% validation data with a random shuffle. This will allow the user to see how the model performs at various times in your sequence.
+
+```
+-v/--valid : validation split of data. Default 0.1 (10%)
+--no_shuffle : Flag that will order the validation data so that the last (-v) percent of data is the validation.
+```
+To try "backtesting" to a certain data, you can specify the end date. This will forecast and compare the true data from that time.
```
-e/--end : end date (format YYYY-MM-DD) of the stock - Backtesting. Default None.
```
@@ -25,8 +35,9 @@ Since this is a timeseries, and the data has a sequence, the data at the end of
Decide whether you want to pre-process your share price data or not. I.e. do you want to use these values between 18 and 245, or perhaps normalize these between 0 and 1? The later may improve performance.
```
--p/--pp : pre-processing data. Default normalization.
+Preprocess = "minmax"
```
+This is defined in the config file.
5. **Select input, prediction days and jumps in training data**
@@ -44,13 +55,6 @@ Personally, I recommend to set this for a really short window. This is because t
-d/--days : prediciton days. Default 5.
```
-The **jumps in the training data** corresponds to the number of days we want to jump between training loops.
-
-Let's say we start training our Neural Network from 2021-01-04, with 10 inputs (days) and 5 prediction days. If jump is set to 1, it means that the after optimizing our model for input data from 2021-01-04 to 2021-01-15, and predicting from 2021-01-18 to 2021-01-22, we will optimize the model for input data from 2021-01-05 to 2021-01-18, and predicting from 2021-01-19 to 2021-01-25. On the other hand, if we set the jump to 5, it means that we are identifying a "weekly" frequency in the data, and therefore, our next model optimization would use input data from 2021-01-11 to 2021-01-22, and predicting from 2021-01-25 to 2021-01-29.
-```
--j/--jumps : number of jumps in training data. Default 1.
-```
-
6. **Select NN architecture.** TL;DR: LSTM > RNN > MLP
**MLP**: The neurons don't have any memory.
@@ -88,17 +92,24 @@ This model is set in [config_neural_network_models.py](/config_neural_network_mo
**Loss function**: Often chosen having the activation functions of the hidden layers in mind. See https://machinelearningmastery.com/how-to-choose-loss-functions-when-training-deep-learning-neural-networks/, and https://www.tensorflow.org/api_docs/python/tf/keras/losses.
```
--l/--loss : loss function. Default mae.
+Loss = "mae"
```
+This is defined in the config file.
-**Optimizer technique**: Adaptive Moment Estimation (_adam_) is usually the default choice for this type of problems. See https://www.tensorflow.org/api_docs/python/tf/keras/optimizers.
+**Optimizer technique**:Adaptive Moment Estimation (_adam_) is usually the default choice for this type of problems. See https://www.tensorflow.org/api_docs/python/tf/keras/optimizers.
+
+The optimizer selection has been moved to the config_neural_network_models.py file and the new argument is the learning rate.
+This tells your model how "fast" to train by adjusting the factor that gets multiplied to the loss function for updating weights
```
--o/--optimizer : optimization technique. Default adam.
+--lr : learning rate. Default 0.01.
```
9. **Training epochs**
Select the number of epochs to train your model. The bigger number of epochs, the longer the training will take, and also increase chances of overfitting.
+
+An early stopping has been implemented that will (if desired) stop training once the validation loss has plateaued. the patience (number of
+epochs with no improvement) can be found in the config file.
```
--epochs : number of training epochs. Default 200.
```
diff --git a/gamestonk_terminal/prediction_techniques/README.md b/gamestonk_terminal/prediction_techniques/README.md
index efd0a0f2fcd..cf73839b70a 100644
--- a/gamestonk_terminal/prediction_techniques/README.md
+++ b/gamestonk_terminal/prediction_techniques/README.md
@@ -2,8 +2,6 @@
This menu aims to predict the share price of a pre-loaded stock, and the usage of the following commands along with an example will be exploited below. See [How to fune-tuning a NN model](FUNE-TUNING-NN-models.md).
- * [sma](#sma)
- - simple moving average
* [ets](#ets)
- Exponential Smoothing (e.g. Holt-Winters)
* [knn](#knn)
@@ -28,6 +26,8 @@ This menu aims to predict the share price of a pre-loaded stock, and the usage o
* [lstm](#lstm)
- Long-Short Term Memory
- Contains a [backtesting example](#backtesting)
+ * [conv1d](#conv1d)
+ - 1D Convolutional Neural Net
**Note:** _Use this at your own discretion. All of these prediciton techniques rely solely on the closing price of the stock. This means that there are several factors that the models aren't aware of at the time of prediction, and may - drastically - move the price up or down. Examples are: news, analyst price targets, reddit post, tweets from Elon Musk, and so on._
@@ -35,17 +35,6 @@ This menu aims to predict the share price of a pre-loaded stock, and the usage o
-## sma
-```
-usage: sma [-l N_LENGTH] [-d N_DAYS]
-```
-Simple Moving Average:
- * -l : length of SMA window. Default 20.
- * -d : prediciton days. Default 5.
- * -e : end date (format YYYY-MM-DD) of the stock - Backtesting. Default None.
-
-
-
## ets
```
usage: ets [-t TREND] [-s SEASONAL] [-p SEASONAL_PERIODS] [-d N_DAYS]
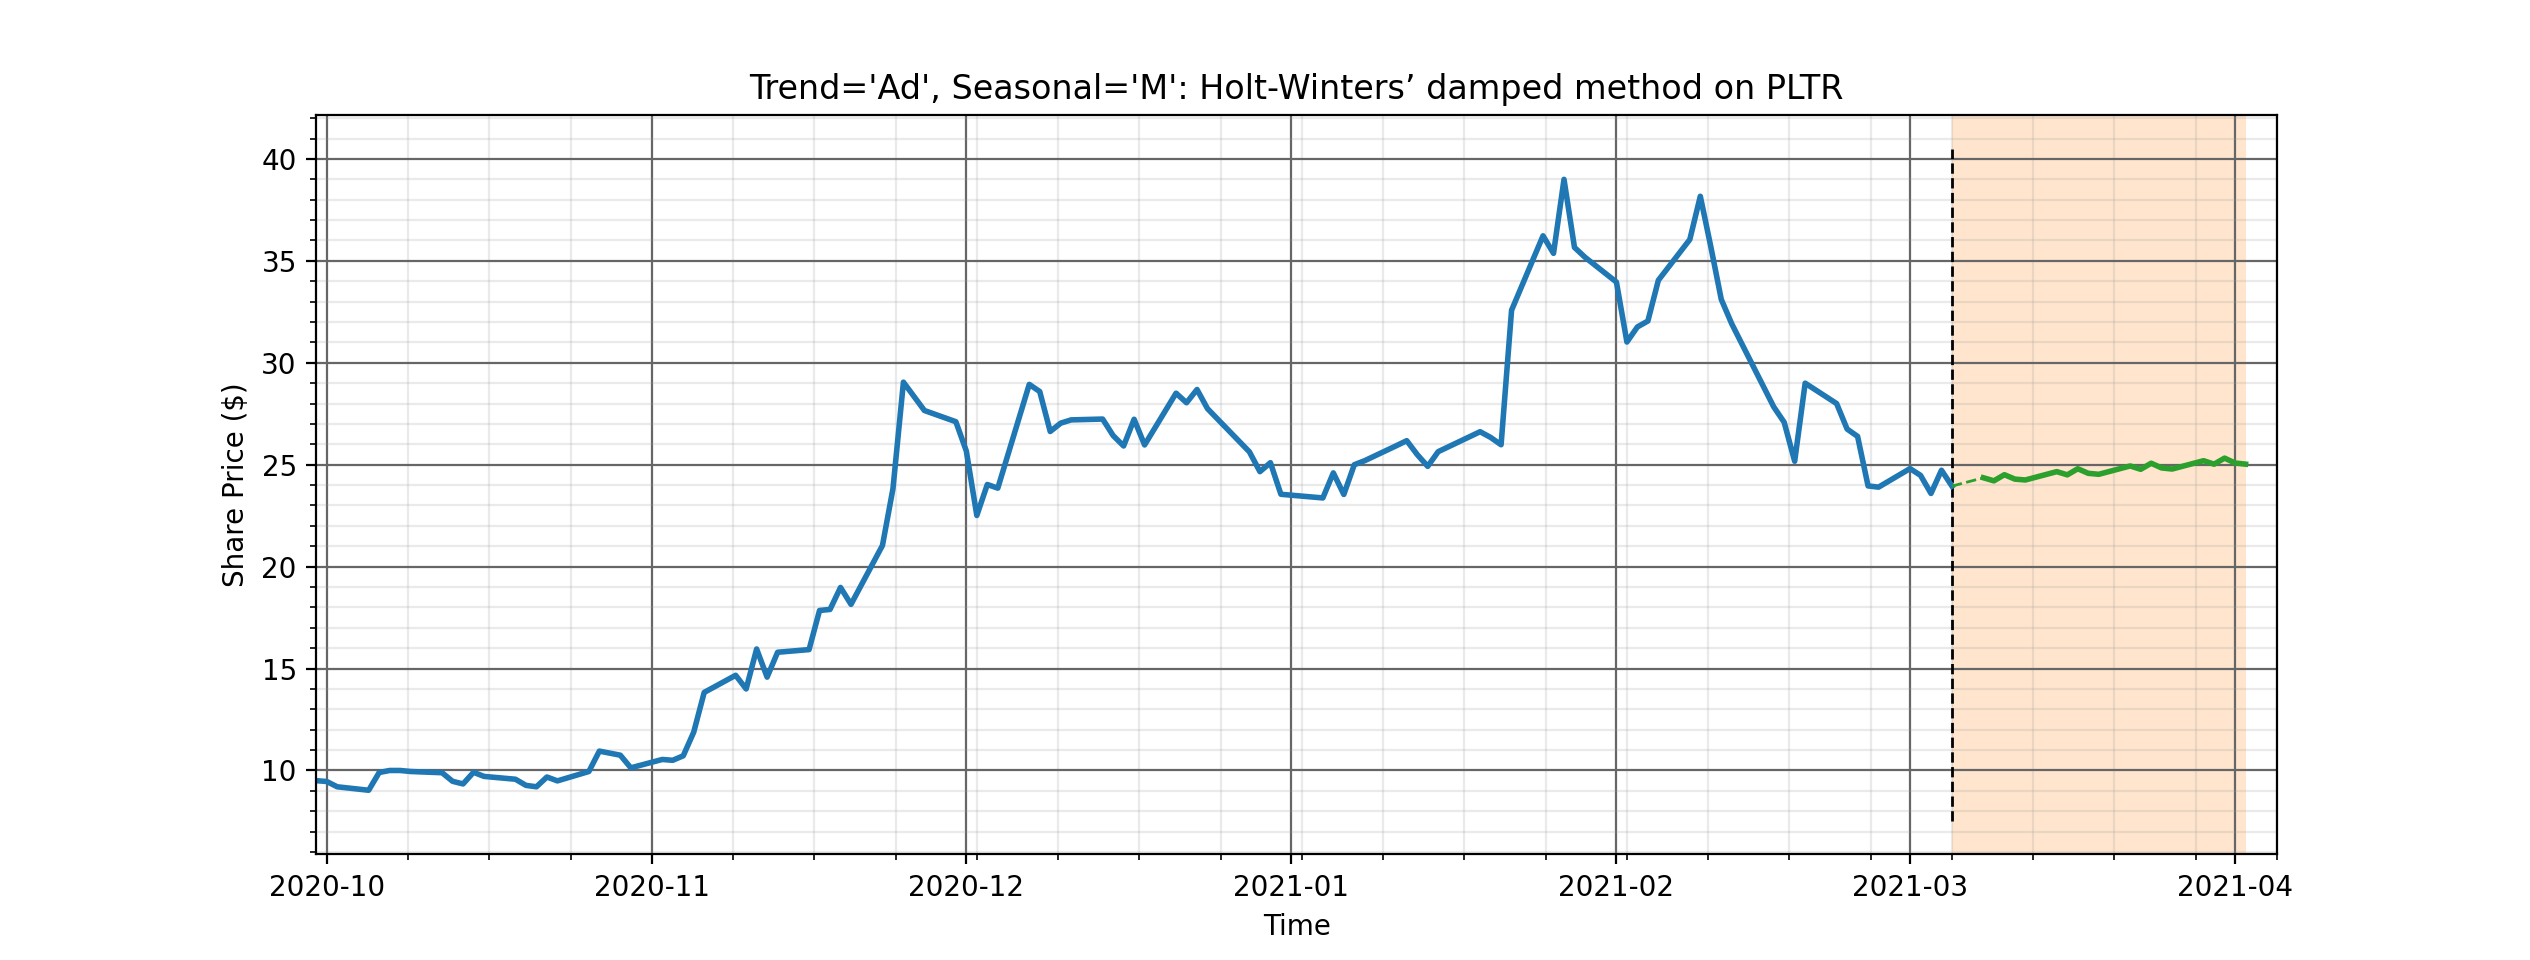
@@ -54,19 +43,18 @@ Exponential Smoothing (based on trend+seasonality, see https://otexts.com/fpp2/t
* -t : trend component: N: None, A: Additive, Ad: Additive Damped. Default N.
* -s : seasonality component: N: None, A: Additive, M: Multiplicative. Default N.
* -p : seasonal periods. Default 5.
- * -d : prediciton days. Default 5.
+ * -d : prediction days. Default 5.
* -e : end date (format YYYY-MM-DD) of the stock - Backtesting. Default None.
## knn
```
-usage: knn [-i N_INPUTS] [-d N_DAYS] [-j N_JUMPS] [-n N_NEIGHBORS]
+usage: knn [-i N_INPUTS] [-d N_DAYS] [-n N_NEIGHBORS]
```
k-Nearest Neighbors:
* -i : number of days to use for prediction. Default 40.
- * -d : prediciton days. Default 5.
- * -j : number of jumps in training data. Default 1.
+ * -d : prediction days. Default 5.
* -n : number of neighbors to use on the algorithm. Default 20.
* -e : end date (format YYYY-MM-DD) of the stock - Backtesting. Default None.
@@ -74,51 +62,47 @@ k-Nearest Neighbors:
## linear
```
-usage: linear [-i N_INPUTS] [-d N_DAYS] [-j N_JUMPS]
-usage: regression -p 1 [-i N_INPUTS] [-d N_DAYS] [-j N_JUMPS]
+usage: linear [-i N_INPUTS] [-d N_DAYS]
+usage: regression -p 1 [-i N_INPUTS] [-d N_DAYS]
```
Linear Regression (p=1):
* -i : number of days to use for prediction. Default 40.
- * -d : prediciton days. Default 5.
- * -j : number of jumps in training data. Default 1.
+ * -d : prediction days. Default 5.
* -e : end date (format YYYY-MM-DD) of the stock - Backtesting. Default None.

## quadratic
```
-usage: quadratic [-i N_INPUTS] [-d N_DAYS] [-j N_JUMPS]
-usage: regression -p 2 [-i N_INPUTS] [-d N_DAYS] [-j N_JUMPS]
+usage: quadratic [-i N_INPUTS] [-d N_DAYS]
+usage: regression -p 2 [-i N_INPUTS] [-d N_DAYS]
```
Quadratic Regression (p=2):
* -i : number of days to use for prediction. Default 40.
- * -d : prediciton days. Default 5.
- * -j : number of jumps in training data. Default 1.
+ * -d : prediction days. Default 5.
* -e : end date (format YYYY-MM-DD) of the stock - Backtesting. Default None.

## cubic
```
-usage: cubic [-i N_INPUTS] [-d N_DAYS] [-j N_JUMPS]
-usage: regression -p 3 [-i N_INPUTS] [-d N_DAYS] [-j N_JUMPS]
+usage: cubic [-i N_INPUTS] [-d N_DAYS]
+usage: regression -p 3 [-i N_INPUTS] [-d N_DAYS]
```
Cubic Regression (p=3):
* -i : number of days to use for prediction. Default 40.
- * -d : prediciton days. Default 5.
- * -j : number of jumps in training data. Default 1.
+ * -d : prediction days. Default 5.
* -e : end date (format YYYY-MM-DD) of the stock - Backtesting. Default None.

## regression
```
-usage: regression -p N_POLYNOMIAL [-i N_INPUTS] [-d N_DAYS] [-j N_JUMPS]
+usage: regression -p N_POLYNOMIAL [-i N_INPUTS] [-d N_DAYS]
```
Regression:
* -i : number of days to use for prediction. Default 40.
- * -d : prediciton days. Default 5.
- * -j : number of jumps in training data. Default 1.
+ * -d : prediction days. Default 5.
* -p : polynomial associated with regression. Required.
* -e : end date (format YYYY-MM-DD) of the stock - Backtesting. Default None.
@@ -133,7 +117,7 @@ Auto-Regressive Integrated Moving Average:
* -i : information criteria - used if auto_arima library is invoked. Default aic.
* -s : weekly seasonality flag. Default False.
* -r : results about ARIMA summary flag. Default False.
- * -o : arima model order. If the model order is defined, auto_arima is not invoked, deeming information criteria useless.
Example: -o 514, where:
+ * -o : arima model order. If the model order is defined, auto_arima is not invoked, deeming information criteria useless.
Example: `-o 5,1,4` where:
* p = 5 : order (number of time lags) of the autoregressive model.
* d = 1 : degree of differencing (the number of times the data have had past values subtracted).
* q = 4 : order of the moving-average model.
@@ -146,30 +130,29 @@ Auto-Regressive Integrated Moving Average:
usage: fbprophet [-d N_DAYS]
```
Facebook's Prophet:
- * -d : prediciton days. Default 5.
+ * -d : prediction days. Default 5.
* -e : end date (format YYYY-MM-DD) of the stock - Backtesting. Default None.

## mlp
```
-usage: mlp [-d N_DAYS] [-i N_INPUTS] [-j N_JUMPS] [--epochs N_EPOCHS] [-p {normalization,standardization,none}]
-[-o {adam,adagrad,adadelta,adamax,ftrl,nadam,optimizer,rmsprop,sgd}] [-l {mae,mape,mse,msle}] [-e S_END_DATE] [--loops N_LOOPS]
+usage: mlp [-d N_DAYS] [-i N_INPUTS] [--epochs N_EPOCHS] [-e S_END_DATE] [--loops N_LOOPS] [-v VALID]
+ [--lr LEARNING_RATE] [--no_shuffle]
```
MulitLayer Perceptron:
* -d : prediciton days. Default 5.
* -i : number of days to use for prediction. Default 40.
- * -j : number of jumps in training data. Default 1.
* --epochs : number of training epochs. Default 200.
- * -p : pre-processing data. Default normalization.
- * -o : optimization technique. Default adam.
- * -l : loss function. Default mae.
+ * -v : validation split. Default 0.1
* -e : end date (format YYYY-MM-DD) of the stock - Backtesting. Default None.
* --xla_cpu: if present, will enable XLA for CPU (overrides environment variables during run).
* --xla_gpu: if present, will enable XLA for GPU (overrides environment variables during run).
* --force_allow_gpu_growth: if true, will force TensorFlow to allow GPU memory usage to grow as needed. Otherwise will allocate 100% of available GPU memory when CUDA is set up. Default true.
* --batch_size: batch size for model training, should not be used unless advanced user. Default None.
+ * --lr : learning rate for optimizer
* --loops: number of loops to iterate and train models. Default 1.
+ * --no_shuffle : split validation data in time_ordered way instead of random.
Due to the complexity of defining a model through command line, one can define it in: [config_neural_network_models.txt](/config_neural_network_models.py)
```
@@ -183,30 +166,29 @@ MultiLayer_Perceptron \
{'Dense':
{'units':30, 'activation':'relu'} },
{'Dense':
- {'activation':'linear'} }]
+ {'activation':'relu'} }]
```

## rnn
```
-usage: rnn [-d N_DAYS] [-i N_INPUTS] [-j N_JUMPS] [--epochs N_EPOCHS] [-p {normalization,standardization,none}]
-[-o {adam,adagrad,adadelta,adamax,ftrl,nadam,optimizer,rmsprop,sgd}] [-l {mae,mape,mse,msle}] [-e S_END_DATE] [--loops N_LOOPS]
+usage: rnn [-d N_DAYS] [-i N_INPUTS] [--epochs N_EPOCHS] [-p {normalization,standardization,none}]
+ [-l {mae,mape,mse,msle}] [-e S_END_DATE] [--loops N_LOOPS] [-v VALID] [--lr LEARNING_RATE] [--no_shuffle]
```
Recurrent Neural Network:
* -d : prediciton days. Default 5.
* -i : number of days to use for prediction. Default 40.
- * -j : number of jumps in training data. Default 1.
* --epochs : number of training epochs. Default 200.
- * -p : pre-processing data. Default normalization.
- * -o : optimization technique. Default adam.
- * -l : loss function. Default mae.
+ * -v : validation split. Default 0.1
* -e : end date (format YYYY-MM-DD) of the stock - Backtesting. Default None.
* --xla_cpu: if present, will enable XLA for CPU (overrides environment variables during run).
* --xla_gpu: if present, will enable XLA for GPU (overrides environment variables during run).
* --force_allow_gpu_growth: if true, will force TensorFlow to allow GPU memory usage to grow as needed. Otherwise will allocate 100% of available GPU memory when CUDA is set up. Default true.
* --batch_size: batch size for model training, should not be used unless advanced user. Default None.
* --loops: number of loops to iterate and train models. Default 1.
+ * --lr : learning rate for optimizer
+ * --no_shuffle : split validation data in time_ordered way instead of random.
Due to the complexity of defining a model through command line, one can define it in: [config_neural_network_models.txt](/config_neural_network_models.py)
```
@@ -220,7 +202,7 @@ Recurrent_Neural_Network \
{'SimpleRNN':
{'units':21, 'activation':'linear', 'return_sequences':False} },
{'Dense':
- {'activation':'linear'} }]
+ {'activation':'relu'} }]
```

@@ -234,23 +216,22 @@ Recurrent_Neural_Network \
## lstm
```
-usage: lstm [-d N_DAYS] [-i N_INPUTS] [-j N_JUMPS] [--epochs N_EPOCHS] [-p {normalization,standardization,none}]
-[-o {adam,adagrad,adadelta,adamax,ftrl,nadam,optimizer,rmsprop,sgd}] [-l {mae,mape,mse,msle}] [-e S_END_DATE] [--loops N_LOOPS]
+usage: lstm [-d N_DAYS] [-i N_INPUTS] [--epochs N_EPOCHS] [-e S_END_DATE] [--loops N_LOOPS] [-v VALID]
+ [--lr LEARNING_RATE] [--no_shuffle]
```
Long-Short Term Memory:
- * -d : prediciton days. Default 5.
+ * -d : prediction days. Default 5.
* -i : number of days to use for prediction. Default 40.
- * -j : number of jumps in training data. Default 1.
* --epochs : number of training epochs. Default 200.
- * -p : pre-processing data. Default normalization.
- * -o : optimization technique. Default adam.
- * -l : loss function. Default mae.
+ * -v : validation split. Default 0.1
* -e : end date (format YYYY-MM-DD) of the stock - Backtesting. Default None.
* --xla_cpu: if present, will enable XLA for CPU (overrides environment variables during run).
* --xla_gpu: if present, will enable XLA for GPU (overrides environment variables during run).
* --force_allow_gpu_growth: if true, will force TensorFlow to allow GPU memory usage to grow as needed. Otherwise will allocate 100% of available GPU memory when CUDA is set up. Default true.
* --batch_size: batch size for model training, should not be used unless advanced user. Default None.
- * --loops: number of loops to iterate and train models. Default 1.
+ * --loops: number of loops to iterate and train models. Default 1
+ * --lr : learning rate for optimizer
+ * --no_shuffle : split validation data in time_ordered way instead of random.
Due to the complexity of defining a model through command line, one can define it in: [config_neural_network_models.py](/config_neural_network_models.py)
```
@@ -260,7 +241,7 @@ Long_Short_Term_Memory \
{'LSTM':
{'units':15, 'activation':'tanh', 'return_sequences':False} },
{'Dense':
- {'activation':'linear'} }]
+ {'activation':'relu'} }]
```

@@ -273,3 +254,21 @@ Long_Short_Term_Memory \
 +## conv1d
+```
+usage: lstm [-d N_DAYS] [-i N_INPUTS] [--epochs N_EPOCHS] [-e S_END_DATE] [--loops N_LOOPS] [-v VALID]
+[--lr LEARNING_RATE] [--no_shuffle]
+```
+1D Convolutional Neural Net:
+ * -d : prediction days. Default 5.
+ * -i : number of days to use for prediction. Default 40.
+ * --epochs : number of training epochs. Default 50.
+ * -v : validation split. Default 0.1
+ * -e : end date (format YYYY-MM-DD) of the stock - Backtesting. Default None.
+ * --xla_cpu: if present, will enable XLA for CPU (overrides environment variables during run).
+ * --xla_gpu: if present, will enable XLA for GPU (overrides environment variables during run).
+ * --force_allow_gpu_growth: if true, will force TensorFlow to allow GPU memory usage to grow as needed. Otherwise will allocate 100% of available GPU memory when CUDA is set up. Default true.
+ * --batch_size: batch size for model training, should not be used unless advanced user. Default None.
+ * --loops: number of loops to iterate and train models. Default 1.
+ * --lr : learning rate for optimizer
+ * --no_shuffle : split validation data in time_ordered way instead of random.
\ No newline at end of file
diff --git a/gamestonk_terminal/prediction_techniques/arima.py b/gamestonk_terminal/prediction_techniques/arima_view.py
similarity index 95%
rename from gamestonk_terminal/prediction_techniques/arima.py
rename to gamestonk_terminal/prediction_techniques/arima_view.py
index e68ac8aad8b..e0153ef5927 100644
--- a/gamestonk_terminal/prediction_techniques/arima.py
+++ b/gamestonk_terminal/prediction_techniques/arima_view.py
@@ -1,4 +1,8 @@
+""" ARIMA Model View """
+__docformat__ = "numpy"
+
import argparse
+from typing import List
import datetime
import matplotlib.pyplot as plt
import pandas as pd
@@ -25,7 +29,19 @@ from gamestonk_terminal import feature_flags as gtff
register_matplotlib_converters()
-def arima(l_args, s_ticker, df_stock):
+def arima(other_args: List[str], s_ticker: str, df_stock: pd.DataFrame):
+ """
+ ARIMA prediction
+ Parameters
+ ----------
+ other_args: List[str]
+ Argparse arguments
+ s_ticker: str
+ ticker
+ df_stock: pd.DataFrame
+ Dataframe of prices
+
+ """
parser = argparse.ArgumentParser(
add_help=False,
prog="arima",
@@ -74,7 +90,7 @@ def arima(l_args, s_ticker, df_stock):
action="store",
dest="s_order",
type=str,
- help="arima model order (p,d,q) in format: pdq.",
+ help="arima model order (p,d,q) in format: p,d,q.",
)
parser.add_argument(
"-r",
@@ -95,7 +111,7 @@ def arima(l_args, s_ticker, df_stock):
)
try:
- ns_parser = parse_known_args_and_warn(parser, l_args)
+ ns_parser = parse_known_args_and_warn(parser, other_args)
if not ns_parser:
return
@@ -134,7 +150,7 @@ def arima(l_args, s_ticker, df_stock):
# Machine Learning model
if ns_parser.s_order:
- t_order = tuple([int(ord) for ord in list(ns_parser.s_order)])
+ t_order = tuple([int(ord) for ord in ns_parser.s_order.split(",")])
model = ARIMA(df_stock["5. adjusted close"].values, order=t_order).fit()
l_predictions = model.predict(
start=len(df_stock["5. adjusted close"]) + 1,
@@ -362,5 +378,4 @@ def arima(l_args, s_ticker, df_stock):
print("")
except Exception as e:
- print(e)
- print("")
+ print(e, "\n")
diff --git a/gamestonk_terminal/prediction_techniques/ets.py b/gamestonk_terminal/prediction_techniques/ets_view.py
similarity index 94%
rename from gamestonk_terminal/prediction_techniques/ets.py
rename to gamestonk_terminal/prediction_techniques/ets_view.py
index c26e6f28a5a..7b3e02f1136 100644
--- a/gamestonk_terminal/prediction_techniques/ets.py
+++ b/gamestonk_terminal/prediction_techniques/ets_view.py
@@ -1,4 +1,8 @@
+""" ets model view """
+__docformat__ = "numpy"
+
import argparse
+from typing import List, Union
import datetime
import matplotlib.pyplot as plt
import numpy as np
@@ -45,7 +49,19 @@ def check_valid_seasonal(seasonal: str) -> str:
)
-def exponential_smoothing(l_args, s_ticker, df_stock):
+def exponential_smoothing(other_args: List[str], s_ticker: str, df_stock: pd.DataFrame):
+ """
+ Perform exponential smoothing forecasting
+ Parameters
+ ----------
+ other_args: List[str]
+ Argparse arguments
+ s_ticker: str
+ Loaded ticker
+ df_stock: pd.DataFrame
+ Loaded stock dataframe
+
+ """
parser = argparse.ArgumentParser(
add_help=False,
prog="ets",
@@ -61,7 +77,6 @@ def exponential_smoothing(l_args, s_ticker, df_stock):
Trend='Ad', Seasonal='N': Additive damped trend method
Trend='Ad', Seasonal='A': Exponential Smoothing
Trend='Ad', Seasonal='M': Holt-Winters’ damped method
-
Trend component: N: None, A: Additive, Ad: Additive Damped
Seasonality component: N: None, A: Additive, M: Multiplicative
""",
@@ -114,7 +129,7 @@ def exponential_smoothing(l_args, s_ticker, df_stock):
)
try:
- ns_parser = parse_known_args_and_warn(parser, l_args)
+ ns_parser = parse_known_args_and_warn(parser, other_args)
if not ns_parser:
return
@@ -391,7 +406,30 @@ def exponential_smoothing(l_args, s_ticker, df_stock):
print("")
-def get_exponential_smoothing_model(data, trend, seasonal, seasonal_periods):
+def get_exponential_smoothing_model(
+ data: Union[pd.Series, np.ndarray], trend, seasonal, seasonal_periods
+):
+ """
+ Perform exponential smoothing
+ Parameters
+ ----------
+ data: Union[pd.Series, np.ndarray]
+ Series of closing values
+ trend: str
+ Trend component. One of [N, A, Ad]
+ seasonal: str
+ Seasonal component. One of [N, A, M]
+ seasonal_periods: int
+ Number of seaosnal periods in a year
+
+
+ Returns
+ -------
+ model:
+ Exponential smoothing model
+ title: str
+ String describing selected model
+ """
if trend == "N": # None
if seasonal == "N": # None
title = "Trend='N', Seasonal='N': Simple Exponential Smoothing"
diff --git a/gamestonk_terminal/prediction_techniques/fbprophet.py b/gamestonk_terminal/prediction_techniques/fbprophet_view.py
similarity index 95%
rename from gamestonk_terminal/prediction_techniques/fbprophet.py
rename to gamestonk_terminal/prediction_techniques/fbprophet_view.py
index e2294791b6c..fe00655803e 100644
--- a/gamestonk_terminal/prediction_techniques/fbprophet.py
+++ b/gamestonk_terminal/prediction_techniques/fbprophet_view.py
@@ -1,4 +1,8 @@
+""" FB Prophet View"""
+__docformat__ = "numpy"
+
import argparse
+from typing import List
import datetime
import warnings
import matplotlib.pyplot as plt
@@ -26,7 +30,22 @@ register_matplotlib_converters()
warnings.simplefilter("ignore")
-def fbprophet(l_args, s_ticker, df_stock):
+def fbprophet(other_args: List[str], s_ticker: str, df_stock: pd.DataFrame):
+ """
+ Run FB Prophet model
+ Parameters
+ ----------
+ other_args: List[str]:
+ List of argparse argumenst
+ s_ticker: str
+ Stock ticker
+ df_stock: pd.DataFrame
+ Dataframe of prices
+
+ Returns
+ -------
+
+ """
parser = argparse.ArgumentParser(
add_help=False,
prog="fbprophet",
@@ -58,7 +77,7 @@ def fbprophet(l_args, s_ticker, df_stock):
)
try:
- ns_parser = parse_known_args_and_warn(parser, l_args)
+ ns_parser = parse_known_args_and_warn(parser, other_args)
if not ns_parser:
return
diff --git a/gamestonk_terminal/prediction_techniques/knn.py b/gamestonk_terminal/prediction_techniques/knn.py
deleted file mode 100644
index 01de4c62b84..00000000000
--- a/gamestonk_terminal/prediction_techniques/knn.py
+++ /dev/null
@@ -1,323 +0,0 @@
-import argparse
-import datetime
-import matplotlib.pyplot as plt
-import pandas as pd
-from pandas.plotting import register_matplotlib_converters
-from sklearn import neighbors
-from TimeSeriesCrossValidation import splitTrain
-from gamestonk_terminal.helper_funcs import (
- check_positive,
- parse_known_args_and_warn,
- valid_date,
- patch_pandas_text_adjustment,
- get_next_stock_market_days,
- plot_autoscale,
-)
-from gamestonk_terminal.prediction_techniques.pred_helper import (
- print_pretty_prediction,
- price_prediction_backtesting_color,
- print_prediction_kpis,
-)
-
-from gamestonk_terminal.config_plot import PLOT_DPI
-from gamestonk_terminal import feature_flags as gtff
-
-register_matplotlib_converters()
-
-
-def k_nearest_neighbors(l_args, s_ticker, df_stock):
- parser = argparse.ArgumentParser(
- add_help=False,
- prog="knn",
- description="""
- K nearest neighbors is a simple algorithm that stores all
- available cases and predict the numerical target based on a similarity measure
- (e.g. distance functions).
- """,
- )
-
- parser.add_argument(
- "-i",
- "--input",
- action="store",
- dest="n_inputs",
- type=check_positive,
- default=40,
- help="number of days to use for prediction.",
- )
- parser.add_argument(
- "-d",
- "--days",
- action="store",
- dest="n_days",
- type=check_positive,
- default=5,
- help="prediction days.",
- )
- parser.add_argument(
- "-j",
- "--jumps",
- action="store",
- dest="n_jumps",
- type=check_positive,
- default=1,
- help="number of jumps in training data.",
- )
- parser.add_argument(
- "-n",
- "--neighbors",
- action="store",
- dest="n_neighbors",
- type=check_positive,
- default=20,
- help="number of neighbors to use on the algorithm.",
- )
- parser.add_argument(
- "-e",
- "--end",
- action="store",
- type=valid_date,
- dest="s_end_date",
- default=None,
- help="The end date (format YYYY-MM-DD) to select - Backtesting",
- )
-
- try:
- ns_parser = parse_known_args_and_warn(parser, l_args)
- if not ns_parser:
- return
-
- # BACKTESTING
- if ns_parser.s_end_date:
- if ns_parser.s_end_date < df_stock.index[0]:
- print(
- "Backtesting not allowed, since End Date is older than Start Date of historical data\n"
- )
- return
-
- if ns_parser.s_end_date < get_next_stock_market_days(
- last_stock_day=df_stock.index[0],
- n_next_days=ns_parser.n_inputs + ns_parser.n_days,
- )[-1]:
- print(
- "Backtesting not allowed, since End Date is too close to Start Date to train model\n"
- )
- return
-
- future_index = get_next_stock_market_days(
- last_stock_day=ns_parser.s_end_date, n_next_days=ns_parser.n_days
- )
-
- if future_index[-1] > datetime.datetime.now():
- print(
- "Backtesting not allowed, since End Date + Prediction days is in the future\n"
- )
- return
-
- df_future = df_stock[future_index[0] : future_index[-1]]
- df_stock = df_stock[: ns_parser.s_end_date]
-
- # Split training data
- stock_x, stock_y = splitTrain.split_train(
- df_stock["5. adjusted close"].values,
- ns_parser.n_inputs,
- ns_parser.n_days,
- ns_parser.n_jumps,
- )
-
- if not stock_x:
- print("Given the model parameters more training data is needed.\n")
- return
-
- # Machine Learning model
- knn = neighbors.KNeighborsRegressor(n_neighbors=ns_parser.n_neighbors)
- knn.fit(stock_x, stock_y)
-
- # Prediction data
- l_predictions = knn.predict(
- df_stock["5. adjusted close"].values[-ns_parser.n_inputs :].reshape(1, -1)
- )[0]
- l_pred_days = get_next_stock_market_days(
- last_stock_day=df_stock["5. adjusted close"].index[-1],
- n_next_days=ns_parser.n_days,
- )
- df_pred = pd.Series(l_predictions, index=l_pred_days, name="Price")
-
- # Plotting
- plt.figure(figsize=plot_autoscale(), dpi=PLOT_DPI)
- plt.plot(df_stock.index, df_stock["5. adjusted close"], lw=2)
- s_knn = f"{ns_parser.n_neighbors}-Nearest Neighbors on {s_ticker}"
- # BACKTESTING
- if ns_parser.s_end_date:
- plt.title(f"BACKTESTING: {s_knn} - {ns_parser.n_days} days prediction")
- else:
- plt.title(f"{s_knn} - {ns_parser.n_days} days prediction")
- plt.xlim(
- df_stock.index[0], get_next_stock_market_days(df_pred.index[-1], 1)[-1]
- )
- plt.xlabel("Time")
- plt.ylabel("Share Price ($)")
- plt.grid(b=True, which="major", color="#666666", linestyle="-")
- plt.minorticks_on()
- plt.grid(b=True, which="minor", color="#999999", linestyle="-", alpha=0.2)
- plt.plot(
- [df_stock.index[-1], df_pred.index[0]],
- [df_stock["5. adjusted close"].values[-1], df_pred.values[0]],
- lw=1,
- c="tab:green",
- linestyle="--",
- )
- plt.plot(df_pred.index, df_pred, lw=2, c="tab:green")
- plt.axvspan(
- df_stock.index[-1], df_pred.index[-1], facecolor="tab:orange", alpha=0.2
- )
- _, _, ymin, ymax = plt.axis()
- plt.vlines(
- df_stock.index[-1], ymin, ymax, linewidth=1, linestyle="--", color="k"
- )
-
- # BACKTESTING
- if ns_parser.s_end_date:
- plt.plot(
- df_future.index,
- df_future["5. adjusted close"],
- lw=2,
- c="tab:blue",
- ls="--",
- )
- plt.plot(
- [df_stock.index[-1], df_future.index[0]],
- [
- df_stock["5. adjusted close"].values[-1],
- df_future["5. adjusted close"].values[0],
- ],
- lw=1,
- c="tab:blue",
- linestyle="--",
- )
-
- if gtff.USE_ION:
- plt.ion()
-
- plt.show()
-
- # BACKTESTING
- if ns_parser.s_end_date:
- plt.figure(figsize=plot_autoscale(), dpi=PLOT_DPI)
- plt.subplot(211)
- plt.plot(
- df_future.index,
- df_future["5. adjusted close"],
- lw=2,
- c="tab:blue",
- ls="--",
- )
- plt.plot(df_pred.index, df_pred, lw=2, c="green")
- plt.scatter(
- df_future.index, df_future["5. adjusted close"], c="tab:blue", lw=3
- )
- plt.plot(
- [df_stock.index[-1], df_future.index[0]],
- [
- df_stock["5. adjusted close"].values[-1],
- df_future["5. adjusted close"].values[0],
- ],
- lw=2,
- c="tab:blue",
- ls="--",
- )
- plt.scatter(df_pred.index, df_pred, c="green", lw=3)
- plt.plot(
- [df_stock.index[-1], df_pred.index[0]],
- [df_stock["5. adjusted close"].values[-1], df_pred.values[0]],
- lw=2,
- c="green",
- ls="--",
- )
- plt.title("BACKTESTING: Real data price versus Prediction")
- plt.xlim(df_stock.index[-1], df_pred.index[-1] + datetime.timedelta(days=1))
- plt.xticks(
- [df_stock.index[-1], df_pred.index[-1] + datetime.timedelta(days=1)]
- )
- plt.ylabel("Share Price ($)")
- plt.grid(b=True, which="major", color="#666666", linestyle="-")
- plt.minorticks_on()
- plt.grid(b=True, which="minor", color="#999999", linestyle="-", alpha=0.2)
- plt.legend(["Real data", "Prediction data"])
- plt.xticks([])
-
- plt.subplot(212)
- plt.axhline(y=0, color="k", linestyle="--", linewidth=2)
- plt.plot(
- df_future.index,
- 100
- * (df_pred.values - df_future["5. adjusted close"].values)
- / df_future["5. adjusted close"].values,
- lw=2,
- c="red",
- )
- plt.scatter(
- df_future.index,
- 100
- * (df_pred.values - df_future["5. adjusted close"].values)
- / df_future["5. adjusted close"].values,
- c="red",
- lw=5,
- )
- plt.title("BACKTESTING: Error between Real data and Prediction [%]")
- plt.plot(
- [df_stock.index[-1], df_future.index[0]],
- [
- 0,
- 100
- * (df_pred.values[0] - df_future["5. adjusted close"].values[0])
- / df_future["5. adjusted close"].values[0],
- ],
- lw=2,
- ls="--",
- c="red",
- )
- plt.xlim(df_stock.index[-1], df_pred.index[-1] + datetime.timedelta(days=1))
- plt.xticks(
- [df_stock.index[-1], df_pred.index[-1] + datetime.timedelta(days=1)]
- )
- plt.xlabel("Time")
- plt.ylabel("Prediction Error (%)")
- plt.grid(b=True, which="major", color="#666666", linestyle="-")
- plt.minorticks_on()
- plt.grid(b=True, which="minor", color="#999999", linestyle="-", alpha=0.2)
- plt.legend(["Real data", "Prediction data"])
-
- if gtff.USE_ION:
- plt.ion()
-
- plt.show()
-
- # Refactor prediction dataframe for backtesting print
- df_pred.name = "Prediction"
- df_pred = df_pred.to_frame()
- df_pred["Real"] = df_future["5. adjusted close"]
-
- if gtff.USE_COLOR:
- patch_pandas_text_adjustment()
-
- print("Time Real [$] x Prediction [$]")
- print(
- df_pred.apply(
- price_prediction_backtesting_color, axis=1
- ).to_string()
- )
- else:
- print(df_pred[["Real", "Prediction"]].round(2).to_string())
-
- print("")
- print_prediction_kpis(df_pred["Real"].values, df_pred["Prediction"].values)
-
- else:
- # Print prediction data
- print_pretty_prediction(df_pred, df_stock["5. adjusted close"].values[-1])
- print("")
-
- except Exception as e:
- print(e)
- print("")
diff --git a/gamestonk_terminal/prediction_techniques/knn_view.py b/gamestonk_terminal/prediction_techniques/knn_view.py
new file mode 100644
index 00000000000..f1c191fb53e
--- /dev/null
+++ b/gamestonk_terminal/prediction_techniques/knn_view.py
@@ -0,0 +1,171 @@
+""" K Nearest Neighbors View"""
+__docformat__ = "numpy"
+
+import argparse
+from typing import List
+import pandas as pd
+from pandas.plotting import register_matplotlib_converters
+from sklearn import neighbors
+from gamestonk_terminal.helper_funcs import (
+ check_positive,
+ parse_known_args_and_warn,
+ valid_date,
+ get_next_stock_market_days,
+)
+from gamestonk_terminal.prediction_techniques.pred_helper import (
+ print_pretty_prediction,
+ prepare_scale_train_valid_test,
+ plot_data_predictions,
+)
+
+register_matplotlib_converters()
+
+
+def k_nearest_neighbors(other_args: List[str], s_ticker: str, df_stock: pd.DataFrame):
+ """
+ Train KNN model
+ Parameters
+ ----------
+ other_args: List[str]
+ List of argparse arguments
+ s_ticker: str
+ Ticker
+ df_stock: pd.DataFrame
+ Dataframe of stock prices
+
+ Returns
+ -------
+
+ """
+ parser = argparse.ArgumentParser(
+ add_help=False,
+ prog="knn",
+ description="""
+ K nearest neighbors is a simple algorithm that stores all
+ available cases and predict the numerical target based on a similarity measure
+ (e.g. distance functions).
+ """,
+ )
+
+ parser.add_argument(
+ "-i",
+ "--input",
+ action="store",
+ dest="n_inputs",
+ type=check_positive,
+ default=40,
+ help="number of days to use as input for prediction.",
+ )
+ parser.add_argument(
+ "-d",
+ "--days",
+ action="store",
+ dest="n_days",
+ type=check_positive,
+ default=5,
+ help="prediction days.",
+ )
+ parser.add_argument(
+ "-j",
+ "--jumps",
+ action="store",
+ dest="n_jumps",
+ type=check_positive,
+ default=1,
+ help="number of jumps in training data.",
+ )
+ parser.add_argument(
+ "-n",
+ "--neighbors",
+ action="store",
+ dest="n_neighbors",
+ type=check_positive,
+ default=20,
+ help="number of neighbors to use on the algorithm.",
+ )
+ parser.add_argument(
+ "-e",
+ "--end",
+ action="store",
+ type=valid_date,
+ dest="s_end_date",
+ default=None,
+ help="The end date (format YYYY-MM-DD) to select for testing",
+ )
+
+ parser.add_argument(
+ "-t",
+ "--test_size",
+ default=0.2,
+ dest="valid_split",
+ type=float,
+ help="Percentage of data to validate in sample",
+ )
+ parser.add_argument(
+ "-p",
+ "--pp",
+ action="store",
+ dest="s_preprocessing",
+ default="none",
+ choices=["normalization", "standardization", "minmax", "none"],
+ help="pre-processing data.",
+ )
+
+ try:
+ ns_parser = parse_known_args_and_warn(parser, other_args)
+ if not ns_parser:
+ return
+
+ (
+ X_train,
+ X_valid,
+ y_train,
+ y_valid,
+ _,
+ _,
+ _,
+ y_dates_valid,
+ forecast_data_input,
+ dates_forecast_input,
+ scaler,
+ is_error,
+ ) = prepare_scale_train_valid_test(df_stock["5. adjusted close"], ns_parser)
+ if is_error:
+ print("Error preparing data")
+ return
+ print(
+ f"Training on {X_train.shape[0]} sequences of length {X_train.shape[1]}. Using {X_valid.shape[0]} sequences "
+ f" of length {X_valid.shape[1]} for validation"
+ )
+ future_dates = get_next_stock_market_days(
+ dates_forecast_input[-1], n_next_days=ns_parser.n_days
+ )
+
+ # Machine Learning model
+ knn = neighbors.KNeighborsRegressor(n_neighbors=ns_parser.n_neighbors)
+ knn.fit(
+ X_train.reshape(X_train.shape[0], X_train.shape[1]),
+ y_train.reshape(y_train.shape[0], y_train.shape[1]),
+ )
+
+ preds = knn.predict(X_valid.reshape(X_valid.shape[0], X_valid.shape[1]))
+ forecast_data = knn.predict(forecast_data_input.reshape(1, -1))
+
+ forecast_data_df = pd.DataFrame(forecast_data.T, index=future_dates)
+ print_pretty_prediction(
+ forecast_data_df[0], df_stock["5. adjusted close"].values[-1]
+ )
+ plot_data_predictions(
+ df_stock,
+ preds,
+ y_valid,
+ y_dates_valid,
+ scaler,
+ f"KNN Model with {ns_parser.n_neighbors} Neighbors on {s_ticker}",
+ forecast_data_df,
+ 1,
+ )
+
+ except Exception as e:
+ print(e)
+ print("")
diff --git a/gamestonk_terminal/prediction_techniques/neural_networks.py b/gamestonk_terminal/prediction_techniques/neural_networks.py
deleted file mode 100644
index e3cabd309f9..00000000000
--- a/gamestonk_terminal/prediction_techniques/neural_networks.py
+++ /dev/null
@@ -1,910 +0,0 @@
-import argparse
-import datetime
-import os
-import traceback
-from warnings import simplefilter
-import numpy as np
-import matplotlib.pyplot as plt
-import pandas as pd
-from pandas.plotting import register_matplotlib_converters
-from TimeSeriesCrossValidation import splitTrain
-from sklearn.preprocessing import MinMaxScaler, StandardScaler
-from tensorflow.keras.models import Sequential
-from tensorflow.keras.layers import LSTM, SimpleRNN, Dense, Dropout
-
-from gamestonk_terminal.helper_funcs import (
- check_positive,
- parse_known_args_and_warn,
- valid_date,
- patch_pandas_text_adjustment,
- get_next_stock_market_days,
- plot_autoscale,
-)
-
-from gamestonk_terminal.prediction_techniques.pred_helper import (
- print_pretty_prediction_nn,
- price_prediction_backtesting_color,
- print_prediction_kpis,
-)
-
-from gamestonk_terminal import feature_flags as gtff
-
-from gamestonk_terminal.config_plot import PLOT_DPI
-from gamestonk_terminal import config_neural_network_models as cfg_nn_models
-
-
-register_matplotlib_converters()
-
-os.environ["TF_CPP_MIN_LOG_LEVEL"] = "2"
-
-simplefilter(action="ignore", category=FutureWarning)
-
-# store the user's TensorFlow environment variables
-ORIGINAL_TF_XLA_FLAGS = os.environ.get("TF_XLA_FLAGS")
-ORIGINAL_TF_FORCE_GPU_ALLOW_GROWTH = os.environ.get("TF_FORCE_GPU_ALLOW_GROWTH")
-
-
-def build_neural_network_model(Recurrent_Neural_Network, n_inputs, n_days):
- model = Sequential()
-
- for idx_layer, d_layer in enumerate(Recurrent_Neural_Network):
- # Recurrent Neural Network
- if str(*d_layer) == "SimpleRNN":
- # Is this the input layer? If so, define input_shape
- if idx_layer == 0:
- model.add(SimpleRNN(**d_layer["SimpleRNN"], input_shape=(n_inputs, 1)))
- # Is this the last output layer? If so, set units to prediction days
- elif idx_layer == (len(Recurrent_Neural_Network) - 1):
- model.add(SimpleRNN(**d_layer["SimpleRNN"], units=n_days))
- else:
- model.add(SimpleRNN(**d_layer["SimpleRNN"]))
-
- # Long-Short Term-Memory
- elif str(*d_layer) == "LSTM":
- # Is this the input layer? If so, define input_shape
- if idx_layer == 0:
- model.add(LSTM(**d_layer["LSTM"], input_shape=(n_inputs, 1)))
- # Is this the last output layer? If so, set units to prediction days
- elif idx_layer == (len(Recurrent_Neural_Network) - 1):
- model.add(LSTM(**d_layer["LSTM"], units=n_days))
- else:
- model.add(LSTM(**d_layer["LSTM"]))
-
- # Dense (Simple Neuron)
- elif str(*d_layer) == "Dense":
- # Is this the input layer? If so, define input_shape
- if idx_layer == 0:
- model.add(Dense(**d_layer["Dense"], input_dim=n_inputs))
- # Is this the last output layer? If so, set units to prediction days
- elif idx_layer == (len(Recurrent_Neural_Network) - 1):
- model.add(Dense(**d_layer["Dense"], units=n_days))
- else:
- model.add(Dense(**d_layer["Dense"]))
-
- # Dropout (Regularization)
- elif str(*d_layer) == "Dropout":
- model.add(Dropout(**d_layer["Dropout"]))
-
- else:
- print(f"Incorrect neuron type: {str(*d_layer)}")
-
- return model
-
-
-def _parse_args(prog, description, l_args):
- """Create an argparser and parse l_args. Will print help if user requests it.
- :return: ns_parser"""
- parser = argparse.ArgumentParser(
- prog=prog,
- description=description,
- add_help=False,
- formatter_class=argparse.RawTextHelpFormatter, # enable multiline help messages
- )
- parser.add_argument(
- "-d",
- "--days",
- action="store",
- dest="n_days",
- type=check_positive,
- default=5,
- help="prediction days.",
- )
- parser.add_argument(
- "-i",
- "--input",
- action="store",
- dest="n_inputs",
- type=check_positive,
- default=40,
- help="number of days to use for prediction.",
- )
- parser.add_argument(
- "--epochs",
- action="store",
- dest="n_epochs",
- type=check_positive,
- default=200,
- help="number of training epochs.",
- )
- parser.add_argument(
- "-j",
- "--jumps",
- action="store",
- dest="n_jumps",
- type=check_positive,
- default=1,
- help="number of jumps in training data.",
- )
- parser.add_argument(
- "-p",
- "--pp",
- action="store",
- dest="s_preprocessing",
- default="normalization",
- choices=["normalization", "standardization", "none"],
- help="pre-processing data.",
- )
- parser.add_argument(
- "-o",
- "--optimizer",
- action="store",
- dest="s_optimizer",
- default="adam",
- choices=[
- "adam",
- "adagrad",
- "adadelta",
- "adamax",
- "ftrl",
- "nadam",
- "rmsprop",
- "sgd",
- ],
- help="optimization technique (see https://www.tensorflow.org/api_docs/python/tf/keras/optimizers)",
- )
- parser.add_argument(
- "-l",
- "--loss",
- action="store",
- dest="s_loss",
- default="mae",
- choices=[
- "mae",
- "mape",
- "mse",
- "msle",
- "poisson",
- "logcosh",
- "kld",
- "hinge",
- "squared_hinge",
- "huber",
- ],
- help="loss function (see https://www.tensorflow.org/api_docs/python/tf/keras/losses)",
- )
- parser.add_argument(
- "-e",
- "--end",
- action="store",
- type=valid_date,
- dest="s_end_date",
- default=None,
- help="The end date (format YYYY-MM-DD) to select - Backtesting",
- )
- parser.add_argument(
- "--batch_size",
- action="store",
- dest="n_batch_size",
- type=check_positive,
- default=None,
- help="batch size for model fitting (use a power of 2)",
- )
- parser.add_argument(
- "--xla_cpu",
- action="store_true",
- dest="b_xla_cpu",
- default=False,
- help="enable XLA for CPU (see https://www.tensorflow.org/xla)",
- )
- parser.add_argument(
- "--xla_gpu",
- action="store_true",
- dest="b_xla_gpu",
- default=False,
- help="enable XLA for GPU (see https://www.tensorflow.org/xla)",
- )
- parser.add_argument(
- "--force_gpu_allow_growth",
- action="store",
- dest="s_force_gpu_allow_growth",
- default="true",
- choices=["true", "false", "default"],
- help="true: GPU memory will grow as needed. \n"
- "false: TensorFlow will allocate 100%% of GPU memory. \n"
- "default: usually the same as false, uses env/TensorFlow default",
- )
- parser.add_argument(
- "--loops",
- action="store",
- dest="n_loops",
- type=check_positive,
- default=1,
- help="number of loops to iterate and train models",
- )
-
- try:
- ns_parser = parse_known_args_and_warn(parser, l_args)
- if not ns_parser:
- return None
-
- # set xla flags if requested
- xla_flags = (
- set(ORIGINAL_TF_XLA_FLAGS.split(" ")) if ORIGINAL_TF_XLA_FLAGS else set()
- )
- if ns_parser.b_xla_cpu or ns_parser.b_xla_gpu:
- xla_flags.add("--tf_xla_enable_xla_devices")
- if ns_parser.b_xla_cpu:
- xla_flags.add("--tf_xla_cpu_global_jit")
- if ns_parser.b_xla_gpu:
- xla_flags.add("--tf_xla_auto_jit=2")
- os.environ["TF_XLA_FLAGS"] = " ".join(xla_flags)
-
- # set GPU memory growth flag
- if ns_parser.s_force_gpu_allow_growth == "true":
- os.environ["TF_FORCE_GPU_ALLOW_GROWTH"] = "true"
- elif ns_parser.s_force_gpu_allow_growth == "false":
- os.environ["TF_FORCE_GPU_ALLOW_GROWTH"] = "false"
-
- return ns_parser
-
- except SystemExit:
- print("")
- return None
-
-
-def _restore_env():
- """Restore environment variables to original values"""
-
- def restore(key, value):
- if value is None:
- if key in os.environ:
- del os.environ[key]
- else:
- os.environ[key] = value
-
- restore("TF_XLA_FLAGS", ORIGINAL_TF_XLA_FLAGS)
- restore("TF_FORCE_GPU_ALLOW_GROWTH", ORIGINAL_TF_FORCE_GPU_ALLOW_GROWTH)
-
-
-def _setup_backtesting(df_stock, ns_parser):
- """Set up backtesting if enabled
- :return: (df_stock, df_future), where df_future is None if s_end_date is not set.
- :raises Exception: if configuration is invalid"""
- df_future = None
- if ns_parser.s_end_date:
- if ns_parser.s_end_date < df_stock.index[0]:
- raise Exception(
- "Backtesting not allowed, since End Date is older than Start Date of historical data"
- )
-
- if ns_parser.s_end_date < get_next_stock_market_days(
- last_stock_day=df_stock.index[0],
- n_next_days=ns_parser.n_inputs + ns_parser.n_days,
- )[-1]:
- raise Exception(
- "Backtesting not allowed, since End Date is too close to Start Date to train model"
- )
-
- future_index = get_next_stock_market_days(
- last_stock_day=ns_parser.s_end_date, n_next_days=ns_parser.n_days
- )
-
- if future_index[-1] > datetime.datetime.now():
- raise Exception(
- "Backtesting not allowed, since End Date + Prediction days is in the future"
- )
-
- df_future = df_stock[future_index[0] : future_index[-1]]
- df_stock = df_stock[: ns_parser.s_end_date]
- return df_stock, df_future
-
-
-def _preprocess_split(df_stock, ns_parser):
- """Preprocess and split training data.
- :return: (scaler, stock_train_data, stock_x, stock_y)
- :raises Exception: if more training data is needed."""
- # Pre-process data
- if ns_parser.s_preprocessing == "standardization":
- scaler = StandardScaler()
- stock_train_data = scaler.fit_transform(
- np.array(df_stock["5. adjusted close"].values.reshape(-1, 1))
- )
- elif ns_parser.s_preprocessing == "normalization":
- scaler = MinMaxScaler()
- stock_train_data = scaler.fit_transform(
- np.array(df_stock["5. adjusted close"].values.reshape(-1, 1))
- )
- else: # No pre-processing
- stock_train_data = np.array(df_stock["5. adjusted close"].values.reshape(-1, 1))
-
- # Split training data for the neural network
- stock_x, stock_y = splitTrain.split_train(
- stock_train_data,
- ns_parser.n_inputs,
- ns_parser.n_days,
- numJumps=ns_parser.n_jumps,
- )
- if not stock_x:
- raise Exception("Given the model parameters more training data is needed.")
- stock_x = np.array(stock_x)
- stock_y = np.array(stock_y)
- return scaler, stock_train_data, stock_x, stock_y
-
-
-def _rescale_data(df_stock, ns_parser, scaler, yhat, idx_loop):
- """Re-scale the data back and return the prediction dataframe."""
- if (ns_parser.s_preprocessing == "standardization") or (
- ns_parser.s_preprocessing == "normalization"
- ):
- y_pred_test_t = scaler.inverse_transform(yhat.tolist())
- else:
- y_pred_test_t = yhat
-
- l_pred_days = get_next_stock_market_days(
- last_stock_day=df_stock["5. adjusted close"].index[-1],
- n_next_days=ns_parser.n_days,
- )
- column_name = f"Price [{idx_loop+1}]"
- df_pred = pd.Series(y_pred_test_t[0].tolist(), index=l_pred_days, name=column_name)
- return df_pred
-
-
-def _plot_and_print_results(
- df_stock, ns_parser, df_future, df_pred, model_name, s_ticker
-):
- """Plot and print the results."""
- # Plotting
- plt.figure(figsize=plot_autoscale(), dpi=PLOT_DPI)
- plt.plot(df_stock.index, df_stock["5. adjusted close"], lw=3)
-
- # BACKTESTING
- if ns_parser.n_loops == 1:
- if ns_parser.s_end_date:
- plt.title(
- f"BACKTESTING: {model_name} on {s_ticker} - {ns_parser.n_days} days prediction"
- )
- else:
- plt.title(
- f"{model_name} on {s_ticker} - {ns_parser.n_days} days prediction"
- )
- else:
- if ns_parser.s_end_date:
- plt.title(
- f"{ns_parser.n_loops} loops - BACKTESTING: {model_name} on {s_ticker}"
- f" - {ns_parser.n_days} days prediction"
- )
- else:
- plt.title(
- f"{ns_parser.n_loops} loops - {model_name} on {s_ticker} - {ns_parser.n_days} days prediction"
- )
-
- plt.xlim(df_stock.index[0], get_next_stock_market_days(df_pred.index[-1], 1)[-1])
- plt.xlabel("Time")
- plt.ylabel("Share Price ($)")
- plt.grid(b=True, which="major", color="#666666", linestyle="-")
- plt.minorticks_on()
- plt.grid(b=True, which="minor", color="#999999", linestyle="-", alpha=0.2)
-
- if ns_parser.n_loops == 1:
- plt.plot(
- [df_stock.index[-1], df_pred.index[0]],
- [
- df_stock["5. adjusted close"].values[-1],
- df_pred[df_pred.columns[0]].values[0],
- ],
- lw=1,
- c="tab:green",
- linestyle="--",
- )
- plt.plot(df_pred.index, df_pred[df_pred.columns[0]], lw=2, c="tab:green")
- else:
- df_quantiles = pd.DataFrame()
- df_quantiles["Quantile 10%"] = df_pred.quantile(0.1, axis=1)
- df_quantiles["Median"] = df_pred.quantile(0.5, axis=1)
- df_quantiles["Quantile 90%"] = df_pred.quantile(0.9, axis=1)
-
- plt.plot(df_pred.index, df_quantiles["Median"], lw=2, c="tab:green")
- plt.fill_between(
- df_pred.index,
- df_quantiles["Quantile 10%"],
- df_quantiles["Quantile 90%"],
- alpha=0.30,
- color="tab:green",
- interpolate=True,
- )
- plt.fill_between(
- [df_stock.index[-1], df_pred.index[0]],
- [
- df_stock["5. adjusted close"].values[-1],
- df_quantiles["Quantile 10%"].values[0],
- ],
- [
- df_stock["5. adjusted close"].values[-1],
- df_quantiles["Quantile 90%"].values[0],
- ],
- alpha=0.30,
- color="tab:green",
- interpolate=True,
- )
-
- plt.axvspan(
- df_stock.index[-1], df_pred.index[-1], facecolor="tab:orange", alpha=0.2
- )
- _, _, ymin, ymax = plt.axis()
- plt.vlines(
- df_stock.index[-1],
- ymin,
- ymax,
- colors="k",
- linewidth=3,
- linestyle="--",
- color="k",
- )
-
- # BACKTESTING
- if ns_parser.s_end_date:
- plt.plot(
- df_future.index,
- df_future["5. adjusted close"],
- lw=2,
- c="tab:blue",
- ls="--",
- )
- plt.plot(
- [df_stock.index[-1], df_future.index[0]],
- [
- df_stock["5. adjusted close"].values[-1],
- df_future["5. adjusted close"].values[0],
- ],
- lw=1,
- c="tab:blue",
- linestyle="--",
- )
-
- if gtff.USE_ION:
- plt.ion()
-
- plt.show()
-
- # BACKTESTING
- if ns_parser.s_end_date:
- plt.figure(figsize=plot_autoscale(), dpi=PLOT_DPI)
- plt.subplot(211)
- plt.plot(
- df_future.index,
- df_future["5. adjusted close"],
- lw=2,
- c="tab:blue",
- ls="--",
- )
- if ns_parser.n_loops == 1:
- plt.plot(df_pred.index, df_pred, lw=2, c="green")
- else:
- plt.plot(
- df_quantiles["Median"].index, df_quantiles["Median"], lw=2, c="green"
- )
-
- plt.scatter(df_future.index, df_future["5. adjusted close"], c="tab:blue", lw=3)
- plt.plot(
- [df_stock.index[-1], df_future.index[0]],
- [
- df_stock["5. adjusted close"].values[-1],
- df_future["5. adjusted close"].values[0],
- ],
- lw=2,
- c="tab:blue",
- ls="--",
- )
- if ns_parser.n_loops == 1:
- plt.scatter(df_pred.index, df_pred, c="green", lw=3)
- plt.plot(
- [df_stock.index[-1], df_pred.index[0]],
- [df_stock["5. adjusted close"].values[-1], df_pred.values[0]],
- lw=2,
- c="green",
- ls="--",
- )
- else:
- plt.scatter(
- df_quantiles["Median"].index, df_quantiles["Median"], lw=3, c="green"
- )
- plt.plot(
- [df_stock.index[-1], df_quantiles["Median"].index[0]],
- [
- df_stock["5. adjusted close"].values[-1],
- df_quantiles["Median"].values[0],
- ],
- lw=2,
- c="green",
- ls="--",
- )
- plt.fill_between(
- df_pred.index,
- df_quantiles["Quantile 10%"],
- df_quantiles["Quantile 90%"],
- alpha=0.30,
- color="tab:green",
- interpolate=True,
- )
-
- plt.title("BACKTESTING: Real data price versus Prediction")
- plt.xlim(df_stock.index[-1], df_pred.index[-1] + datetime.timedelta(days=1))
- plt.xticks(
- [df_stock.index[-1], df_pred.index[-1] + datetime.timedelta(days=1)],
- visible=True,
- )
- plt.ylabel("Share Price ($)")
- plt.grid(b=True, which="major", color="#666666", linestyle="-")
- plt.minorticks_on()
- plt.grid(b=True, which="minor", color="#999999", linestyle="-", alpha=0.2)
- plt.legend(["Real data", "Prediction data"])
- plt.xticks([])
-
- plt.subplot(212)
- plt.axhline(y=0, color="k", linestyle="--", linewidth=2)
- if ns_parser.n_loops == 1:
- plt.plot(
- df_future.index,
- 100
- * (
- df_pred[df_pred.columns[0]].values
- - df_future["5. adjusted close"].values
- )
- / df_future["5. adjusted close"].values,
- lw=2,
- c="red",
- )
- plt.scatter(
- df_future.index,
- 100
- * (
- df_pred[df_pred.columns[0]].values
- - df_future["5. adjusted close"].values
- )
- / df_future["5. adjusted close"].values,
- c="red",
- lw=5,
- )
- plt.plot(
- [df_stock.index[-1], df_future.index[0]],
- [
- 0,
- 100
- * (
- df_pred[df_pred.columns[0]].values[0]
- - df_future["5. adjusted close"].values[0]
- )
- / df_future["5. adjusted close"].values[0],
- ],
- lw=2,
- ls="--",
- c="red",
- )
- else:
- plt.plot(
- df_future.index,
- 100
- * (
- df_quantiles["Median"].values
- - df_future["5. adjusted close"].values
- )
- / df_future["5. adjusted close"].values,
- lw=2,
- c="red",
- )
- plt.scatter(
- df_future.index,
- 100
- * (
- df_quantiles["Median"].values
- - df_future["5. adjusted close"].values
- )
- / df_future["5. adjusted close"].values,
- c="red",
- lw=5,
- )
- plt.plot(
- [df_stock.index[-1], df_future.index[0]],
- [
- 0,
- 100
- * (
- df_quantiles["Median"].values[0]
- - df_future["5. adjusted close"].values[0]
- )
- / df_future["5. adjusted close"].values[0],
- ],
- lw=2,
- ls="--",
- c="red",
- )
- plt.fill_between(
- df_pred.index,
- 100
- * (
- df_quantiles["Quantile 10%"].values
- - df_future["5. adjusted close"].values
- )
- / df_future["5. adjusted close"].values,
- 100
- * (
- df_quantiles["Quantile 90%"].values
- - df_future["5. adjusted close"].values
- )
- / df_future["5. adjusted close"].values,
- alpha=0.30,
- color="red",
- interpolate=True,
- )
- plt.title("BACKTESTING: Error between Real data and Prediction [%]")
-
- plt.xlim(df_stock.index[-1], df_pred.index[-1] + datetime.timedelta(days=1))
- plt.xticks(
- [df_stock.index[-1], df_pred.index[-1] + datetime.timedelta(days=1)],
- visible=True,
- )
- plt.xlabel("Time")
- plt.ylabel("Prediction Error (%)")
- plt.grid(b=True, which="major", color="#666666", linestyle="-")
- plt.minorticks_on()
- plt.grid(b=True, which="minor", color="#999999", linestyle="-", alpha=0.2)
- plt.legend(["Real data", "Prediction data"])
-
- if gtff.USE_ION:
- plt.ion()
-
- plt.show()
-
- # Refactor prediction dataframe for backtesting print
- if ns_parser.n_loops == 1:
- df_pred.rename(columns={df_pred.columns[0]: "Prediction"}, inplace=True)
-
- else:
- df_pred = pd.DataFrame()
- df_pred["Prediction"] = df_quantiles["Median"]
-
- df_pred["Real"] = df_future["5. adjusted close"]
-
- if gtff.USE_COLOR:
- patch_pandas_text_adjustment()
-
- print("Time Real [$] x Prediction [$]")
- print(df_pred.apply(price_prediction_backtesting_color, axis=1).to_string())
- else:
- print(df_pred[["Real", "Prediction"]].round(2).to_string())
-
- print("")
- print_prediction_kpis(df_pred["Real"].values, df_pred["Prediction"].values)
- print("")
-
- else:
- patch_pandas_text_adjustment()
- # Print prediction data
- print_pretty_prediction_nn(df_pred, df_stock["5. adjusted close"].values[-1])
- print("")
-
- if ns_parser.n_loops > 1:
- print("Prediction Stats:")
- print(df_quantiles.round(2).to_string())
- print("")
-
-
-def mlp(l_args, s_ticker, df_stock):
- try:
- ns_parser = _parse_args(
- prog="mlp", description="""Multilayer Perceptron. """, l_args=l_args
- )
- if not ns_parser:
- return
-
- # Setup backtesting
- df_stock, df_future = _setup_backtesting(df_stock, ns_parser)
-
- # Pre-process data
- scaler, stock_train_data, stock_x, stock_y = _preprocess_split(
- df_stock, ns_parser
- )
- stock_x = np.reshape(stock_x, (stock_x.shape[0], stock_x.shape[1]))
- stock_y = np.reshape(stock_y, (stock_y.shape[0], stock_y.shape[1]))
-
- # Build Neural Network model
- model = build_neural_network_model(
- cfg_nn_models.MultiLayer_Perceptron, ns_parser.n_inputs, ns_parser.n_days
- )
- model.compile(optimizer=ns_parser.s_optimizer, loss=ns_parser.s_loss)
-
- for idx_loop in range(ns_parser.n_loops):
- # Train our model
- model.fit(
- stock_x,
- stock_y,
- epochs=ns_parser.n_epochs,
- batch_size=ns_parser.n_batch_size,
- verbose=1,
- )
- print("")
-
- print(model.summary())
- print("")
-
- # Prediction
- yhat = model.predict(
- stock_train_data[-ns_parser.n_inputs :].reshape(1, ns_parser.n_inputs),
- verbose=0,
- )
-
- if idx_loop == 0:
- # Re-scale the data back, plot, and print the results
- df_pred = _rescale_data(
- df_stock, ns_parser, scaler, yhat, idx_loop
- ).to_frame()
- else:
- df_pred = df_pred.join(
- _rescale_data(
- df_stock, ns_parser, scaler, yhat, idx_loop
- ).to_frame()
- )
-
- _plot_and_print_results(
- df_stock, ns_parser, df_future, df_pred, "MLP", s_ticker
- )
-
- except Exception as e:
- print(e)
- traceback.print_exc()
- print("")
-
- finally:
- _restore_env()
-
-
-def rnn(l_args, s_ticker, df_stock):
- try:
- ns_parser = _parse_args(
- prog="rnn", description="""Recurrent Neural Network. """, l_args=l_args
- )
- if not ns_parser:
- return
-
- # Setup backtesting
- df_stock, df_future = _setup_backtesting(df_stock, ns_parser)
-
- # Pre-process data
- scaler, stock_train_data, stock_x, stock_y = _preprocess_split(
- df_stock, ns_parser
- )
- stock_x = np.reshape(stock_x, (stock_x.shape[0], stock_x.shape[1], 1))
- stock_y = np.reshape(stock_y, (stock_y.shape[0], stock_y.shape[1], 1))
-
- # Build Neural Network model
- model = build_neural_network_model(
- cfg_nn_models.Recurrent_Neural_Network, ns_parser.n_inputs, ns_parser.n_days
- )
- model.compile(optimizer=ns_parser.s_optimizer, loss=ns_parser.s_loss)
-
- for idx_loop in range(ns_parser.n_loops):
- # Train our model
- model.fit(
- stock_x,
- stock_y,
- epochs=ns_parser.n_epochs,
- batch_size=ns_parser.n_batch_size,
- verbose=1,
- )
- print("")
-
- print(model.summary())
- print("")
-
- # Prediction
- yhat = model.predict(
- stock_train_data[-ns_parser.n_inputs :].reshape(
- 1, ns_parser.n_inputs, 1
- ),
- verbose=0,
- )
-
- if idx_loop == 0:
- # Re-scale the data back, plot, and print the results
- df_pred = _rescale_data(
- df_stock, ns_parser, scaler, yhat, idx_loop
- ).to_frame()
- else:
- df_pred = df_pred.join(
- _rescale_data(
- df_stock, ns_parser, scaler, yhat, idx_loop
- ).to_frame()
- )
-
- _plot_and_print_results(
- df_stock, ns_parser, df_future, df_pred, "RNN", s_ticker
- )
-
- except Exception as e:
- print(e)
- traceback.print_exc()
- print("")
-
- finally:
- _restore_env()
-
-
-def lstm(l_args, s_ticker, df_stock):
- try:
- ns_parser = _parse_args(
- prog="lstm", description="""Long-Short Term Memory. """, l_args=l_args
- )
- if not ns_parser:
- return
-
- # Setup backtesting
- df_stock, df_future = _setup_backtesting(df_stock, ns_parser)
-
- # Pre-process data
- scaler, stock_train_data, stock_x, stock_y = _preprocess_split(
- df_stock, ns_parser
- )
- stock_x = np.reshape(stock_x, (stock_x.shape[0], stock_x.shape[1], 1))
- stock_y = np.reshape(stock_y, (stock_y.shape[0], stock_y.shape[1], 1))
-
- # Build Neural Network model
- model = build_neural_network_model(
- cfg_nn_models.Long_Short_Term_Memory, ns_parser.n_inputs, ns_parser.n_days
- )
- model.compile(optimizer=ns_parser.s_optimizer, loss=ns_parser.s_loss)
-
- for idx_loop in range(ns_parser.n_loops):
- # Train our model
- model.fit(
- stock_x,
- stock_y,
- epochs=ns_parser.n_epochs,
- batch_size=ns_parser.n_batch_size,
- verbose=1,
- )
- print("")
-
- print(model.summary())
- print("")
-
- # Prediction
- yhat = model.predict(
- stock_train_data[-ns_parser.n_inputs :].reshape(
- 1, ns_parser.n_inputs, 1
- ),
- verbose=0,
- )
-
- if idx_loop == 0:
- # Re-scale the data back, plot, and print the results
- df_pred = _rescale_data(
- df_stock, ns_parser, scaler, yhat, idx_loop
- ).to_frame()
- else:
- df_pred = df_pred.join(
- _rescale_data(
- df_stock, ns_parser, scaler, yhat, idx_loop
- ).to_frame()
- )
-
- _plot_and_print_results(
- df_stock, ns_parser, df_future, df_pred, "LSTM", s_ticker
- )
-
- except Exception as e:
- print(e)
- traceback.print_exc()
- print("")
-
- finally:
- _restore_env()
diff --git a/gamestonk_terminal/prediction_techniques/neural_networks_view.py b/gamestonk_terminal/prediction_techniques/neural_networks_view.py
new file mode 100644
index 00000000000..e88b59a679d
--- /dev/null
+++ b/gamestonk_terminal/prediction_techniques/neural_networks_view.py
@@ -0,0 +1,575 @@
+""" Neural Networks View"""
+__docformat__ = "numpy"
+
+from typing import List, Any
+import traceback
+import numpy as np
+import pandas as pd
+from tensorflow.keras.callbacks import EarlyStopping
+from tensorflow.keras.models import Sequential
+from tensorflow.keras.layers import (
+ LSTM,
+ SimpleRNN,
+ Dense,
+ Dropout,
+ Conv1D,
+ MaxPool1D,
+ AvgPool1D,
+ Flatten,
+)
+from tensorflow.keras.optimizers import (
+ Adam,
+ Adamax,
+ Adagrad,
+ Adadelta,
+ Ftrl,
+ Nadam,
+ RMSprop,
+ SGD,
+)
+from gamestonk_terminal.helper_funcs import get_next_stock_market_days
+from gamestonk_terminal.prediction_techniques.pred_helper import (
+ prepare_scale_train_valid_test,
+ forecast,
+ plot_data_predictions,
+ parse_args,
+ restore_env,
+ print_pretty_prediction,
+)
+from gamestonk_terminal import config_neural_network_models as cfg_nn_models
+
+optimizers = {
+ "Adam": Adam,
+ "Adagrad": Adagrad,
+ "Adadelta": Adadelta,
+ "Adamax": Adamax,
+ "Ftrl": Ftrl,
+ "Nadam": Nadam,
+ "Rmsprop": RMSprop,
+ "Ggd": SGD,
+}
+
+
+if cfg_nn_models.Early_Stop_Patience:
+ es = EarlyStopping(monitor="val_loss", patience=cfg_nn_models.Early_Stop_Patience)
+else:
+ # Set patience to very long value
+ es = EarlyStopping(monitor="val_loss", patience=1000)
+
+
+def build_neural_network_model(
+ Recurrent_Neural_Network: List[Any], n_inputs: int, n_days: int
+) -> Sequential:
+ """
+ Builds neural net from config_neural_network_models.py
+ Parameters
+ ----------
+ Recurrent_Neural_Network: List[Any]
+ List of layers with parameters as a dictionary in the file
+ n_inputs: int
+ Number of days that will be fed into the NN
+ n_days: int
+ Number of days the NN wants to predict
+
+ Returns
+ -------
+ model: Sequential
+ Keras sequential model with layers from the file
+
+ """
+ model = Sequential()
+
+ for idx_layer, d_layer in enumerate(Recurrent_Neural_Network):
+ # Recurrent Neural Network
+ if str(*d_layer) == "SimpleRNN":
+ # Is this the input layer? If so, define input_shape
+ if idx_layer == 0:
+ model.add(SimpleRNN(**d_layer["SimpleRNN"], input_shape=(n_inputs, 1)))
+ # Is this the last output layer? If so, set units to prediction days
+ elif idx_layer == (len(Recurrent_Neural_Network) - 1):
+ model.add(SimpleRNN(**d_layer["SimpleRNN"], units=n_days))
+ else:
+ model.add(SimpleRNN(**d_layer["SimpleRNN"]))
+
+ # Long-Short Term-Memory
+ elif str(*d_layer) == "LSTM":
+ # Is this the input layer? If so, define input_shape
+ if idx_layer == 0:
+ model.add(LSTM(**d_layer["LSTM"], input_shape=(n_inputs, 1)))
+ # Is this the last output layer? If so, set units to prediction days
+ elif idx_layer == (len(Recurrent_Neural_Network) - 1):
+ model.add(LSTM(**d_layer["LSTM"], units=n_days))
+ else:
+ model.add(LSTM(**d_layer["LSTM"]))
+
+ # Dense (Simple Neuron)
+ elif str(*d_layer) == "Dense":
+ # Is this the input layer? If so, define input_shape
+ if idx_layer == 0:
+ model.add(Dense(**d_layer["Dense"], input_dim=n_inputs))
+ # Is this the last output layer? If so, set units to prediction days
+ elif idx_layer == (len(Recurrent_Neural_Network) - 1):
+ model.add(Dense(**d_layer["Dense"], units=n_days))
+ else:
+ model.add(Dense(**d_layer["Dense"]))
+
+ # Conv1D Layer
+ elif str(*d_layer) == "Conv1D":
+ if idx_layer == 0:
+ model.add(Conv1D(**d_layer["Conv1D"], input_shape=(n_inputs, 1)))
+ else:
+ model.add(Conv1D(**d_layer["Conv1D"]))
+ # Max Pooling Layer for after Conv Layer
+ elif str(*d_layer) == "MaxPool1D":
+ model.add(MaxPool1D(**d_layer["MaxPool1D"]))
+ # Allow for if user wants to do average pooling
+ elif str(*d_layer) == "AvgPool1D":
+ model.add(AvgPool1D(**d_layer["AvgPool1D"]))
+ # Dropout (Regularization)
+ elif str(*d_layer) == "Dropout":
+ model.add(Dropout(**d_layer["Dropout"]))
+ # Flatten layer for Convolutions
+ elif str(*d_layer) == "Flatten":
+ model.add(Flatten())
+ else:
+ print(f"Incorrect neuron type: {str(*d_layer)}")
+
+ return model
+
+
+def mlp(other_args: List[str], s_ticker: str, df_stock: pd.DataFrame):
+ """
+ Train a multi-layer perceptron model
+ Parameters
+ ----------
+ other_args: List[str]
+ Argparse Arguments
+ s_ticker: str
+ Ticker
+ df_stock: pd.DataFrame
+ Loaded stock dataframe
+
+ """
+ try:
+ ns_parser = parse_args(
+ prog="mlp",
+ description="""Multi-Layered-Perceptron. """,
+ other_args=other_args,
+ )
+ if not ns_parser:
+ return
+ (
+ X_train,
+ X_valid,
+ y_train,
+ y_valid,
+ _,
+ _,
+ _,
+ y_dates_valid,
+ forecast_data_input,
+ dates_forecast_input,
+ scaler,
+ is_error,
+ ) = prepare_scale_train_valid_test(df_stock["5. adjusted close"], ns_parser)
+ if is_error:
+ return
+ print(
+ f"Training on {X_train.shape[0]} sequences of length {X_train.shape[1]}. Using {X_valid.shape[0]} sequences "
+ f" of length {X_valid.shape[1]} for validation. Model will run {ns_parser.n_loops} loops"
+ )
+ future_dates = get_next_stock_market_days(
+ dates_forecast_input[-1], n_next_days=ns_parser.n_days
+ )
+
+ preds = np.zeros((ns_parser.n_loops, X_valid.shape[0], ns_parser.n_days))
+ forecast_data = np.zeros((ns_parser.n_loops, ns_parser.n_days))
+ for i in range(ns_parser.n_loops):
+ # Build Neural Network model
+ model = build_neural_network_model(
+ cfg_nn_models.Long_Short_Term_Memory,
+ ns_parser.n_inputs,
+ ns_parser.n_days,
+ )
+ model.compile(
+ optimizer=optimizers[cfg_nn_models.Optimizer](lr=ns_parser.lr),
+ loss=cfg_nn_models.Loss,
+ )
+
+ model.fit(
+ X_train.reshape(X_train.shape[0], X_train.shape[1], 1),
+ y_train,
+ epochs=ns_parser.n_epochs,
+ verbose=True,
+ batch_size=ns_parser.n_batch_size,
+ validation_data=(
+ X_valid.reshape(X_valid.shape[0], X_valid.shape[1], 1),
+ y_valid,
+ ),
+ callbacks=[es],
+ )
+
+ preds[i] = model.predict(
+ X_valid.reshape(X_valid.shape[0], X_valid.shape[1], 1)
+ ).reshape(X_valid.shape[0], ns_parser.n_days)
+ forecast_data[i] = forecast(
+ forecast_data_input, future_dates, model, scaler
+ ).values.flat
+
+ forecast_data_df = pd.DataFrame(forecast_data.T, index=future_dates)
+ if ns_parser.n_loops > 1:
+ forecast_data_df["Median"] = forecast_data_df.median(axis=1)
+ print_pretty_prediction(
+ forecast_data_df["Median"], df_stock["5. adjusted close"].values[-1]
+ )
+ else:
+ print_pretty_prediction(
+ forecast_data_df[0], df_stock["5. adjusted close"].values[-1]
+ )
+ plot_data_predictions(
+ df_stock,
+ np.median(preds, axis=0),
+ y_valid,
+ y_dates_valid,
+ scaler,
+ f"MLP Model on {s_ticker}",
+ forecast_data_df,
+ ns_parser.n_loops,
+ )
+ print("")
+
+ except Exception as e:
+ print(e)
+ traceback.print_exc()
+ print("")
+
+ finally:
+ restore_env()
+
+
+def rnn(other_args: List[str], s_ticker: str, df_stock: pd.DataFrame):
+ """
+ Train a Recurrent Neural Network (rnn)
+ Parameters
+ ----------
+ other_args:List[str]
+ Argparse arguments
+ s_ticker: str
+ Stock ticker
+ df_stock: pd.DataFrame
+ Dataframe of stock prices
+
+ """
+ try:
+ ns_parser = parse_args(
+ prog="lstm",
+ description="""Long-Short Term Memory. """,
+ other_args=other_args,
+ )
+ if not ns_parser:
+ return
+ (
+ X_train,
+ X_valid,
+ y_train,
+ y_valid,
+ _,
+ _,
+ _,
+ y_dates_valid,
+ forecast_data_input,
+ dates_forecast_input,
+ scaler,
+ is_error,
+ ) = prepare_scale_train_valid_test(df_stock["5. adjusted close"], ns_parser)
+ if is_error:
+ return
+ print(
+ f"Training on {X_train.shape[0]} sequences of length {X_train.shape[1]}. Using {X_valid.shape[0]} sequences "
+ f" of length {X_valid.shape[1]} for validation. Model will run {ns_parser.n_loops} loops"
+ )
+ future_dates = get_next_stock_market_days(
+ dates_forecast_input[-1], n_next_days=ns_parser.n_days
+ )
+
+ preds = np.zeros((ns_parser.n_loops, X_valid.shape[0], ns_parser.n_days))
+ forecast_data = np.zeros((ns_parser.n_loops, ns_parser.n_days))
+ for i in range(ns_parser.n_loops):
+ # Build Neural Network model
+ model = build_neural_network_model(
+ cfg_nn_models.Long_Short_Term_Memory,
+ ns_parser.n_inputs,
+ ns_parser.n_days,
+ )
+ model.compile(
+ optimizer=optimizers[cfg_nn_models.Optimizer](lr=ns_parser.lr),
+ loss=cfg_nn_models.Loss,
+ )
+ model.fit(
+ X_train.reshape(X_train.shape[0], X_train.shape[1], 1),
+ y_train,
+ epochs=ns_parser.n_epochs,
+ verbose=True,
+ batch_size=ns_parser.n_batch_size,
+ validation_data=(
+ X_valid.reshape(X_valid.shape[0], X_valid.shape[1], 1),
+ y_valid,
+ ),
+ callbacks=[es],
+ )
+
+ preds[i] = model.predict(
+ X_valid.reshape(X_valid.shape[0], X_valid.shape[1], 1)
+ ).reshape(X_valid.shape[0], ns_parser.n_days)
+ forecast_data[i] = forecast(
+ forecast_data_input, future_dates, model, scaler
+ ).values.flat
+
+ forecast_data_df = pd.DataFrame(forecast_data.T, index=future_dates)
+ if ns_parser.n_loops > 1:
+ forecast_data_df["Median"] = forecast_data_df.median(axis=1)
+ print_pretty_prediction(
+ forecast_data_df["Median"], df_stock["5. adjusted close"].values[-1]
+ )
+ else:
+ print_pretty_prediction(
+ forecast_data_df[0], df_stock["5. adjusted close"].values[-1]
+ )
+ plot_data_predictions(
+ df_stock,
+ np.median(preds, axis=0),
+ y_valid,
+ y_dates_valid,
+ scaler,
+ f"RNN Model on {s_ticker}",
+ forecast_data_df,
+ ns_parser.n_loops,
+ )
+ print("")
+ except Exception as e:
+ print(e)
+ traceback.print_exc()
+ print("")
+
+ finally:
+ restore_env()
+
+
+def lstm(other_args: List[str], s_ticker: str, df_stock: pd.DataFrame):
+ """
+ Train a Long-Short-Term-Memory Neural Net (lstm)
+ Parameters
+ ----------
+ other_args:List[str]
+ Argparse arguments
+ s_ticker: str
+ Stock ticker
+ df_stock: pd.DataFrame
+ Dataframe of stock prices
+ """
+ try:
+ ns_parser = parse_args(
+ prog="lstm",
+ description="""Long-Short Term Memory. """,
+ other_args=other_args,
+ )
+ if not ns_parser:
+ return
+ (
+ X_train,
+ X_valid,
+ y_train,
+ y_valid,
+ _,
+ _,
+ _,
+ y_dates_valid,
+ forecast_data_input,
+ dates_forecast_input,
+ scaler,
+ is_error,
+ ) = prepare_scale_train_valid_test(df_stock["5. adjusted close"], ns_parser)
+ if is_error:
+ return
+ print(
+ f"Training on {X_train.shape[0]} sequences of length {X_train.shape[1]}. Using {X_valid.shape[0]} sequences "
+ f" of length {X_valid.shape[1]} for validation. Model will run {ns_parser.n_loops} loops"
+ )
+ future_dates = get_next_stock_market_days(
+ dates_forecast_input[-1], n_next_days=ns_parser.n_days
+ )
+
+ preds = np.zeros((ns_parser.n_loops, X_valid.shape[0], ns_parser.n_days))
+ forecast_data = np.zeros((ns_parser.n_loops, ns_parser.n_days))
+ for i in range(ns_parser.n_loops):
+ # Build Neural Network model
+ model = build_neural_network_model(
+ cfg_nn_models.Long_Short_Term_Memory,
+ ns_parser.n_inputs,
+ ns_parser.n_days,
+ )
+ model.compile(
+ optimizer=optimizers[cfg_nn_models.Optimizer](lr=ns_parser.lr),
+ loss=cfg_nn_models.Loss,
+ )
+
+ model.fit(
+ X_train.reshape(X_train.shape[0], X_train.shape[1], 1),
+ y_train,
+ epochs=ns_parser.n_epochs,
+ verbose=True,
+ batch_size=ns_parser.n_batch_size,
+ validation_data=(
+ X_valid.reshape(X_valid.shape[0], X_valid.shape[1], 1),
+ y_valid,
+ ),
+ callbacks=[es],
+ )
+
+ preds[i] = model.predict(
+ X_valid.reshape(X_valid.shape[0], X_valid.shape[1], 1)
+ ).reshape(X_valid.shape[0], ns_parser.n_days)
+
+ forecast_data[i] = forecast(
+ forecast_data_input, future_dates, model, scaler
+ ).values.flat
+
+ forecast_data_df = pd.DataFrame(forecast_data.T, index=future_dates)
+ if ns_parser.n_loops > 1:
+ forecast_data_df["Median"] = forecast_data_df.median(axis=1)
+ print_pretty_prediction(
+ forecast_data_df["Median"], df_stock["5. adjusted close"].values[-1]
+ )
+ else:
+ print_pretty_prediction(
+ forecast_data_df[0], df_stock["5. adjusted close"].values[-1]
+ )
+ plot_data_predictions(
+ df_stock,
+ np.median(preds, axis=0),
+ y_valid,
+ y_dates_valid,
+ scaler,
+ f"LSTM Model on {s_ticker}",
+ forecast_data_df,
+ ns_parser.n_loops,
+ )
+ print("")
+
+ except Exception as e:
+ print(e)
+ traceback.print_exc()
+ print("")
+
+ finally:
+ restore_env()
+
+
+def conv1d(other_args: List[str], s_ticker: str, df_stock: pd.DataFrame):
+ """
+ Train a 1D Convolutional Neural Net (1D CNN)
+ Parameters
+ ----------
+ other_args:List[str]
+ Argparse arguments
+ s_ticker: str
+ Stock ticker
+ df_stock: pd.DataFrame
+ Dataframe of stock prices
+ """
+ try:
+ ns_parser = parse_args(
+ prog="conv1d",
+ description="""1D CNN.""",
+ other_args=other_args,
+ )
+ if not ns_parser:
+ return
+ (
+ X_train,
+ X_valid,
+ y_train,
+ y_valid,
+ _,
+ _,
+ _,
+ y_dates_valid,
+ forecast_data_input,
+ dates_forecast_input,
+ scaler,
+ is_error,
+ ) = prepare_scale_train_valid_test(df_stock["5. adjusted close"], ns_parser)
+ if is_error:
+ return
+ print(
+ f"Training on {X_train.shape[0]} sequences of length {X_train.shape[1]}. Using {X_valid.shape[0]} sequences "
+ f" of length {X_valid.shape[1]} for validation. Model will run {ns_parser.n_loops} loops"
+ )
+ future_dates = get_next_stock_market_days(
+ dates_forecast_input[-1], n_next_days=ns_parser.n_days
+ )
+
+ preds = np.zeros((ns_parser.n_loops, X_valid.shape[0], ns_parser.n_days))
+ forecast_data = np.zeros((ns_parser.n_loops, ns_parser.n_days))
+ for i in range(ns_parser.n_loops):
+ # Build Neural Network model
+ model = build_neural_network_model(
+ cfg_nn_models.Convolutional,
+ ns_parser.n_inputs,
+ ns_parser.n_days,
+ )
+
+ model.compile(
+ optimizer=optimizers[cfg_nn_models.Optimizer](lr=ns_parser.lr),
+ loss=cfg_nn_models.Loss,
+ )
+
+ model.fit(
+ X_train.reshape(X_train.shape[0], X_train.shape[1], 1),
+ y_train,
+ epochs=ns_parser.n_epochs,
+ verbose=True,
+ batch_size=ns_parser.n_batch_size,
+ validation_data=(
+ X_valid.reshape(X_valid.shape[0], X_valid.shape[1], 1),
+ y_valid,
+ ),
+ callbacks=[es],
+ )
+
+ preds[i] = model.predict(
+ X_valid.reshape(X_valid.shape[0], X_valid.shape[1], 1)
+ ).reshape(X_valid.shape[0], ns_parser.n_days)
+ forecast_data[i] = forecast(
+ forecast_data_input, future_dates, model, scaler
+ ).values.flat
+
+ forecast_data_df = pd.DataFrame(forecast_data.T, index=future_dates)
+ if ns_parser.n_loops > 1:
+ forecast_data_df["Median"] = forecast_data_df.median(axis=1)
+ print_pretty_prediction(
+ forecast_data_df["Median"], df_stock["5. adjusted close"].values[-1]
+ )
+ else:
+ print_pretty_prediction(
+ forecast_data_df[0], df_stock["5. adjusted close"].values[-1]
+ )
+ plot_data_predictions(
+ df_stock,
+ np.median(preds, axis=0),
+ y_valid,
+ y_dates_valid,
+ scaler,
+ f"Conv1D Model on {s_ticker}",
+ forecast_data_df,
+ ns_parser.n_loops,
+ )
+ print("")
+
+ except Exception as e:
+ print(e)
+ traceback.print_exc()
+ print("")
+
+ finally:
+ restore_env()
diff --git a/gamestonk_terminal/prediction_techniques/pred_controller.py b/gamestonk_terminal/prediction_techniques/pred_controller.py
index 200a93dd1b2..293d06c4553 100644
--- a/gamestonk_terminal/prediction_techniques/pred_controller.py
+++ b/gamestonk_terminal/prediction_techniques/pred_controller.py
@@ -1,3 +1,6 @@
+""" Due Diligence Controller """
+__docformat__ = "numpy"
+
import argparse
from typing import List
from datetime import datetime
@@ -9,12 +12,11 @@ from gamestonk_terminal import feature_flags as gtff
from gamestonk_terminal.helper_funcs import get_flair
from gamestonk_terminal.menu import session
from gamestonk_terminal.prediction_techniques import (
- arima,
- ets,
- knn,
- neural_networks,
- regression,
- sma,
+ arima_view,
+ ets_view,
+ knn_view,
+ neural_networks_view,
+ regression_view,
)
@@ -26,7 +28,6 @@ class PredictionTechniquesController:
"help",
"q",
"quit",
- "sma",
"ets",
"knn",
"linear",
@@ -37,6 +38,7 @@ class PredictionTechniquesController:
"mlp",
"rnn",
"lstm",
+ "conv1d",
]
if gtff.ENABLE_FBPROPHET:
@@ -77,7 +79,6 @@ class PredictionTechniquesController:
print(" q quit this menu, and shows back to main menu")
print(" quit quit to abandon program")
print("")
- print(" sma simple moving average")
print(" ets exponential smoothing (e.g. Holt-Winters)")
print(" knn k-Nearest Neighbors")
print(" linear linear regression (polynomial 1)")
@@ -88,6 +89,7 @@ class PredictionTechniquesController:
print(" mlp MultiLayer Perceptron")
print(" rnn Recurrent Neural Network")
print(" lstm Long-Short Term Memory")
+ print(" conv1d 1D Convolutional Neural Network")
if gtff.ENABLE_FBPROPHET:
print(" prophet Facebook's prophet prediction")
print("")
@@ -120,60 +122,66 @@ class PredictionTechniquesController:
"""Process Quit command - quit the program"""
return True
- def call_sma(self, other_args: List[str]):
- """Process sma command"""
- sma.simple_moving_average(other_args, self.ticker, self.stock)
-
def call_ets(self, other_args: List[str]):
"""Process ets command"""
- ets.exponential_smoothing(other_args, self.ticker, self.stock)
+ ets_view.exponential_smoothing(other_args, self.ticker, self.stock)
def call_knn(self, other_args: List[str]):
"""Process knn command"""
- knn.k_nearest_neighbors(other_args, self.ticker, self.stock)
+ knn_view.k_nearest_neighbors(other_args, self.ticker, self.stock)
def call_linear(self, other_args: List[str]):
"""Process linear command"""
- regression.regression(other_args, self.ticker, self.stock, regression.LINEAR)
+ regression_view.regression(
+ other_args, self.ticker, self.stock, regression_view.LINEAR
+ )
def call_quadratic(self, other_args: List[str]):
"""Process quadratic command"""
- regression.regression(other_args, self.ticker, self.stock, regression.QUADRATIC)
+ regression_view.regression(
+ other_args, self.ticker, self.stock, regression_view.QUADRATIC
+ )
def call_cubic(self, other_args: List[str]):
"""Process cubic command"""
- regression.regression(other_args, self.ticker, self.stock, regression.CUBIC)
+ regression_view.regression(
+ other_args, self.ticker, self.stock, regression_view.CUBIC
+ )
def call_regression(self, other_args: List[str]):
"""Process regression command"""
- regression.regression(
- other_args, self.ticker, self.stock, regression.USER_INPUT
+ regression_view.regression(
+ other_args, self.ticker, self.stock, regression_view.USER_INPUT
)
def call_arima(self, other_args: List[str]):
"""Process arima command"""
- arima.arima(other_args, self.ticker, self.stock)
+ arima_view.arima(other_args, self.ticker, self.stock)
def call_mlp(self, other_args: List[str]):
"""Process mlp command"""
- neural_networks.mlp(other_args, self.ticker, self.stock)
+ neural_networks_view.mlp(other_args, self.ticker, self.stock)
def call_rnn(self, other_args: List[str]):
"""Process rnn command"""
- neural_networks.rnn(other_args, self.ticker, self.stock)
+ neural_networks_view.rnn(other_args, self.ticker, self.stock)
def call_lstm(self, other_args: List[str]):
"""Process lstm command"""
- neural_networks.lstm(other_args, self.ticker, self.stock)
+ neural_networks_view.lstm(other_args, self.ticker, self.stock)
+
+ def call_conv1d(self, other_args: List[str]):
+ """Process conv1d command"""
+ neural_networks_view.conv1d(other_args, self.ticker, self.stock)
if gtff.ENABLE_FBPROPHET:
def call_prophet(self, other_args: List[str]):
"""Process prophet command"""
# pylint: disable=import-outside-toplevel
- from gamestonk_terminal.prediction_techniques import fbprophet
+ from gamestonk_terminal.prediction_techniques import fbprophet_view
- fbprophet.fbprophet(other_args, self.ticker, self.stock)
+ fbprophet_view.fbprophet(other_args, self.ticker, self.stock)
def menu(stock: pd.DataFrame, ticker: str, start: datetime, interval: str):
diff --git a/gamestonk_terminal/prediction_techniques/pred_helper.py b/gamestonk_terminal/prediction_techniques/pred_helper.py
index c69ac5f0616..197a5c16e2a 100644
--- a/gamestonk_terminal/prediction_techniques/pred_helper.py
+++ b/gamestonk_terminal/prediction_techniques/pred_helper.py
@@ -1,16 +1,517 @@
+""" Prediction helper functions """
+__docformat__ = "numpy"
+
+import argparse
+from typing import List
+import os
+from warnings import simplefilter
+from datetime import timedelta
import numpy as np
import pandas as pd
+from pandas.plotting import register_matplotlib_converters
+import matplotlib.pyplot as plt
from colorama import Fore, Style
from sklearn.metrics import (
mean_absolute_error,
r2_score,
mean_squared_error,
)
-
+from sklearn.model_selection import train_test_split
+from sklearn.preprocessing import StandardScaler, MinMaxScaler, Normalizer
+from tensorflow.keras.models import Sequential
+from gamestonk_terminal.helper_funcs import (
+ check_positive,
+ parse_known_args_and_warn,
+ valid_date,
+ plot_autoscale,
+)
+from gamestonk_terminal import config_neural_network_models as cfg
from gamestonk_terminal import feature_flags as gtff
+from gamestonk_terminal.config_plot import PLOT_DPI
+
+
+register_matplotlib_converters()
+
+os.environ["TF_CPP_MIN_LOG_LEVEL"] = "2"
+
+simplefilter(action="ignore", category=FutureWarning)
+
+# store the user's TensorFlow environment variables
+ORIGINAL_TF_XLA_FLAGS = os.environ.get("TF_XLA_FLAGS")
+ORIGINAL_TF_FORCE_GPU_ALLOW_GROWTH = os.environ.get("TF_FORCE_GPU_ALLOW_GROWTH")
+
+PREPROCESSER = cfg.Preprocess
+
+
+def check_valid_frac(num) -> float:
+ if (num < 0) or (num > 1):
+ raise argparse.ArgumentTypeError(f"{num} is an invalid percentage")
+ return num
+
+
+def restore_env():
+ """Restore environment variables to original values"""
+
+ def restore(key, value):
+ if value is None:
+ if key in os.environ:
+ del os.environ[key]
+ else:
+ os.environ[key] = value
+
+ restore("TF_XLA_FLAGS", ORIGINAL_TF_XLA_FLAGS)
+ restore("TF_FORCE_GPU_ALLOW_GROWTH", ORIGINAL_TF_FORCE_GPU_ALLOW_GROWTH)
+
+
+def parse_args(prog: str, description: str, other_args: List[str]):
+ """
+ Create an argparser and parse other_args. Will print help if user requests it.
+ Parameters
+ ----------
+ prog: str
+ Program for argparser
+ description: str
+ Description for argparser
+ other_args
+ Argparse arguments to pass
+ Returns
+ -------
+ ns_parser: argparse.Namespace
+ Parsed argument parser
+ """
+
+ parser = argparse.ArgumentParser(
+ prog=prog,
+ description=description,
+ add_help=False,
+ formatter_class=argparse.RawTextHelpFormatter, # enable multiline help messages
+ )
+ parser.add_argument(
+ "-d",
+ "--days",
+ action="store",
+ dest="n_days",
+ type=check_positive,
+ default=5,
+ help="prediction days.",
+ )
+ parser.add_argument(
+ "-i",
+ "--input",
+ action="store",
+ dest="n_inputs",
+ type=check_positive,
+ default=40,
+ help="number of days to use for prediction.",
+ )
+ parser.add_argument(
+ "--epochs",
+ action="store",
+ dest="n_epochs",
+ type=check_positive,
+ default=50,
+ help="number of training epochs.",
+ )
+ parser.add_argument(
+ "-e",
+ "--end",
+ action="store",
+ type=valid_date,
+ dest="s_end_date",
+ default=None,
+ help="The end date (format YYYY-MM-DD) to select - Backtesting",
+ )
+ parser.add_argument(
+ "--batch_size",
+ action="store",
+ dest="n_batch_size",
+ type=check_positive,
+ default=None,
+ help="batch size for model fitting (use a power of 2)",
+ )
+ parser.add_argument(
+ "--xla_cpu",
+ action="store_true",
+ dest="b_xla_cpu",
+ default=False,
+ help="enable XLA for CPU (see https://www.tensorflow.org/xla)",
+ )
+ parser.add_argument(
+ "--xla_gpu",
+ action="store_true",
+ dest="b_xla_gpu",
+ default=False,
+ help="enable XLA for GPU (see https://www.tensorflow.org/xla)",
+ )
+ parser.add_argument(
+ "--force_gpu_allow_growth",
+ action="store",
+ dest="s_force_gpu_allow_growth",
+ default="true",
+ choices=["true", "false", "default"],
+ help="true: GPU memory will grow as needed. \n"
+ "false: TensorFlow will allocate 100%% of GPU memory. \n"
+ "default: usually the same as false, uses env/TensorFlow default",
+ )
+ parser.add_argument(
+ "--loops",
+ action="store",
+ dest="n_loops",
+ type=check_positive,
+ default=1,
+ help="number of loops to iterate and train models",
+ )
+ parser.add_argument(
+ "-v",
+ "--valid",
+ type=check_valid_frac,
+ dest="valid_split",
+ default=0.1,
+ help="Validation data split fraction",
+ )
+
+ parser.add_argument(
+ "--lr",
+ type=check_positive,
+ dest="lr",
+ default=0.01,
+ help="Specify learning rate for optimizer.",
+ )
+
+ parser.add_argument(
+ "--no_shuffle",
+ action="store_false",
+ dest="no_shuffle",
+ default=True,
+ help="Specify if shuffling validation inputs.",
+ )
+
+ try:
+ ns_parser = parse_known_args_and_warn(parser, other_args)
+ if not ns_parser:
+ return None
+
+ # set xla flags if requested
+ xla_flags = (
+ set(ORIGINAL_TF_XLA_FLAGS.split(" ")) if ORIGINAL_TF_XLA_FLAGS else set()
+ )
+ if ns_parser.b_xla_cpu or ns_parser.b_xla_gpu:
+ xla_flags.add("--tf_xla_enable_xla_devices")
+ if ns_parser.b_xla_cpu:
+ xla_flags.add("--tf_xla_cpu_global_jit")
+ if ns_parser.b_xla_gpu:
+ xla_flags.add("--tf_xla_auto_jit=2")
+ os.environ["TF_XLA_FLAGS"] = " ".join(xla_flags)
+
+ # set GPU memory growth flag
+ if ns_parser.s_force_gpu_allow_growth == "true":
+ os.environ["TF_FORCE_GPU_ALLOW_GROWTH"] = "true"
+ elif ns_parser.s_force_gpu_allow_growth == "false":
+ os.environ["TF_FORCE_GPU_ALLOW_GROWTH"] = "false"
+
+ return ns_parser
+
+ except SystemExit:
+ print("")
+ return None
+
+
+def prepare_scale_train_valid_test(
+ df_stock: pd.DataFrame, ns_parser: argparse.Namespace
+):
+ """
+ Prepare and scale train, validate and test data.
+ Parameters
+ ----------
+ df_stock: pd.DataFrame
+ Dataframe of stock prices
+ ns_parser: argparse.Namespace
+ Parsed arguments
+ Returns
+ -------
+ X_train: np.ndarray
+ Array of training data. Shape (# samples, n_inputs, 1)
+ X_test: np.ndarray
+ Array of validation data. Shape (totoal sequences - #samples, n_inputs, 1)
+ y_train: np.ndarray
+ Array of training outputs. Shape (#samples, n_days)
+ y_test: np.ndarray
+ Array of validation outputs. Shape (total sequences -#samples, n_days)
+ X_dates_train: np.ndarray
+ Array of dates for X_train
+ X_dates_test: np.ndarray
+ Array of dates for X_test
+ y_dates_train: np.ndarray
+ Array of dates for y_train
+ y_dates_test: np.ndarray
+ Array of dates for y_test
+ test_data: np.ndarray
+ Array of prices after the specified end date
+ dates_test: np.ndarray
+ Array of dates after specified end date
+ scaler:
+ Fitted preprocesser
+ """
+
+ n_input_days = ns_parser.n_inputs
+ n_predict_days = ns_parser.n_days
+ test_size = ns_parser.valid_split
+
+ # Pre-process data
+ if PREPROCESSER == "standardization":
+ scaler = StandardScaler()
+
+ elif PREPROCESSER == "minmax":
+ scaler = MinMaxScaler()
+
+ elif PREPROCESSER == "normalization":
+ scaler = Normalizer()
+
+ elif (PREPROCESSER == "none") or (PREPROCESSER is None):
+ scaler = None
+ # Test data is used for forecasting. Takes the last n_input_days data points.
+ # These points are not fed into training
+
+ if ns_parser.s_end_date:
+ df_stock = df_stock[df_stock.index <= ns_parser.s_end_date]
+ if n_input_days + n_predict_days > df_stock.shape[0]:
+ print("Cannot train enough input days to predict with loaded dataframe\n")
+ return (
+ None,
+ None,
+ None,
+ None,
+ None,
+ None,
+ None,
+ None,
+ None,
+ None,
+ None,
+ True,
+ )
+
+ test_data = df_stock.iloc[-n_input_days:]
+ train_data = df_stock.iloc[:-n_input_days]
+
+ dates = df_stock.index
+ dates_test = test_data.index
+ if scaler:
+ train_data = scaler.fit_transform(df_stock.values.reshape(-1, 1))
+ test_data = scaler.transform(test_data.values.reshape(-1, 1))
+ else:
+ train_data = df_stock.values.reshape(-1, 1)
+ test_data = test_data.values.reshape(-1, 1)
+
+ prices = train_data
+
+ input_dates = []
+ input_prices = []
+ next_n_day_prices = []
+ next_n_day_dates = []
+
+ for idx in range(len(prices) - n_input_days - n_predict_days):
+ input_prices.append(prices[idx : idx + n_input_days])
+ input_dates.append(dates[idx : idx + n_input_days])
+ next_n_day_prices.append(
+ prices[idx + n_input_days : idx + n_input_days + n_predict_days]
+ )
+ next_n_day_dates.append(
+ dates[idx + n_input_days : idx + n_input_days + n_predict_days]
+ )
+
+ input_dates = np.asarray(input_dates)
+ input_prices = np.array(input_prices)
+ next_n_day_prices = np.array(next_n_day_prices)
+ next_n_day_dates = np.asarray(next_n_day_dates)
+
+ (
+ X_train,
+ X_valid,
+ y_train,
+ y_valid,
+ X_dates_train,
+ X_dates_valid,
+ y_dates_train,
+ y_dates_valid,
+ ) = train_test_split(
+ input_prices,
+ next_n_day_prices,
+ input_dates,
+ next_n_day_dates,
+ test_size=test_size,
+ shuffle=ns_parser.no_shuffle,
+ )
+ return (
+ X_train,
+ X_valid,
+ y_train,
+ y_valid,
+ X_dates_train,
+ X_dates_valid,
+ y_dates_train,
+ y_dates_valid,
+ test_data,
+ dates_test,
+ scaler,
+ False,
+ )
+
+
+def forecast(
+ input_values: np.ndarray, future_dates: List, model: Sequential, scaler
+) -> pd.DataFrame:
+ """
+ Forecast the stock movement over future days and rescale
+ Parameters
+ ----------
+ input_values: np.ndarray
+ Array of values to be fed into the model
+ future_dates: List
+ List of future dates
+ model: Sequential
+ Pretrained model
+ scaler:
+ Fit scaler to be used to 'unscale' the data
+
+ Returns
+ -------
+ df_future: pd.DataFrame
+ Dataframe of predicted values
+ """
+ if scaler:
+ future_values = scaler.inverse_transform(
+ model.predict(input_values.reshape(1, -1, 1)).reshape(-1, 1)
+ )
+ else:
+ future_values = model.predict(input_values.reshape(1, -1, 1)).reshape(-1, 1)
+
+ df_future = pd.DataFrame(
+ future_values, index=future_dates, columns=["Predicted Price"]
+ )
+ return df_future
+
+
+def plot_data_predictions(
+ df_stock, preds, y_valid, y_dates_valid, scaler, title, forecast_data, n_loops
+):
+
+ plt.figure(figsize=plot_autoscale(), dpi=PLOT_DPI)
+ plt.plot(
+ df_stock.index,
+ df_stock["5. adjusted close"].values,
+ "-ob",
+ lw=1,
+ ms=2,
+ label="Prices",
+ )
+ for i in range(len(y_valid) - 1):
+
+ if scaler:
+ y_pred = scaler.inverse_transform(preds[i].reshape(-1, 1)).ravel()
+ y_act = scaler.inverse_transform(y_valid[i].reshape(-1, 1)).ravel()
+ else:
+ y_pred = preds[i].ravel()
+ y_act = y_valid[i].ravel()
+ plt.plot(
+ y_dates_valid[i],
+ y_pred,
+ "r",
+ lw=1,
+ )
+ plt.fill_between(
+ y_dates_valid[i],
+ y_pred,
+ y_act,
+ where=(y_pred < y_act),
+ color="r",
+ alpha=0.2,
+ )
+ plt.fill_between(
+ y_dates_valid[i],
+ y_pred,
+ y_act,
+ where=(y_pred > y_act),
+ color="g",
+ alpha=0.2,
+ )
+
+ # Leave this one out of the loop so that the legend doesn't get overpopulated with "Predictions"
+ if scaler:
+ final_pred = scaler.inverse_transform(preds[-1].reshape(-1, 1)).ravel()
+ final_valid = scaler.inverse_transform(y_valid[-1].reshape(-1, 1)).ravel()
+ else:
+ final_pred = preds[-1].reshape(-1, 1).ravel()
+ final_valid = y_valid[-1].reshape(-1, 1).ravel()
+ plt.plot(
+ y_dates_valid[-1],
+ final_pred,
+ "r",
+ lw=2,
+ label="Predictions",
+ )
+ plt.fill_between(
+ y_dates_valid[-1],
+ final_pred,
+ final_valid,
+ color="k",
+ alpha=0.2,
+ )
+ plt.axvspan(
+ forecast_data.index[0] - timedelta(days=1),
+ forecast_data.index[-1],
+ facecolor="tab:orange",
+ alpha=0.2,
+ )
+ _, _, ymin, ymax = plt.axis()
+ plt.vlines(
+ forecast_data.index[0] - timedelta(days=1),
+ ymin,
+ ymax,
+ colors="k",
+ linewidth=3,
+ linestyle="--",
+ color="k",
+ )
+ if n_loops == 1:
+ plt.plot(
+ forecast_data.index,
+ forecast_data.values,
+ "-ok",
+ ms=3,
+ label="Forecast",
+ )
+ else:
+ plt.plot(
+ forecast_data.index,
+ forecast_data.median(axis=1).values,
+ "-ok",
+ ms=3,
+ label="Forecast",
+ )
+ plt.fill_between(
+ forecast_data.index,
+ forecast_data.quantile(0.25, axis=1).values,
+ forecast_data.quantile(0.75, axis=1).values,
+ color="c",
+ alpha=0.3,
+ )
+ plt.legend(loc=0)
+ plt.xlim(df_stock.index[0], forecast_data.index[-1] + timedelta(days=1))
+ plt.xlabel("Time")
+ plt.ylabel("Share Price ($)")
+ plt.grid(b=True, which="major", color="#666666", linestyle="-")
+ plt.minorticks_on()
+ plt.grid(b=True, which="minor", color="#999999", linestyle="-", alpha=0.2)
+ plt.title(title)
+ if gtff.USE_ION:
+ plt.ion()
+ plt.show()
+ print("")
def price_prediction_color(val: float, last_val: float) -> str:
+ """Set prediction to be a colored string"""
if float(val) > last_val:
color = Fore.GREEN
else:
@@ -19,6 +520,7 @@ def price_prediction_color(val: float, last_val: float) -> str:
def print_pretty_prediction(df_pred: pd.DataFrame, last_price: float):
+ """Print predictions"""
if gtff.USE_COLOR:
print(f"Actual price: {Fore.YELLOW}{last_price:.2f} ${Style.RESET_ALL}\n")
print("Prediction:")
@@ -44,12 +546,14 @@ def print_pretty_prediction_nn(df_pred: pd.DataFrame, last_price: float):
print(df_pred.to_string())
-def mean_absolute_percentage_error(y_true, y_pred):
+def mean_absolute_percentage_error(y_true: np.ndarray, y_pred: np.ndarray) -> np.number:
+ """Calculate mean absolute percent error"""
y_true, y_pred = np.array(y_true), np.array(y_pred)
return np.mean(np.abs((y_true - y_pred) / y_true)) * 100
-def print_prediction_kpis(real, pred):
+def print_prediction_kpis(real: np.ndarray, pred: np.ndarray):
+ """Print prediction statistics"""
print("KPIs")
print(f"MAPE: {mean_absolute_percentage_error(real, pred):.3f} %")
print(f"R2: {r2_score(real, pred):.3f}")
@@ -59,6 +563,7 @@ def print_prediction_kpis(real, pred):
def price_prediction_backtesting_color(val: list) -> str:
+ """Add color to backtest data"""
err_pct = 100 * (val[0] - val[1]) / val[1]
if val[0] > val[1]:
s_err_pct = f" {Fore.GREEN} +{err_pct:.2f} %"
diff --git a/gamestonk_terminal/prediction_techniques/regression.py b/gamestonk_terminal/prediction_techniques/regression_view.py
similarity index 95%
rename from gamestonk_terminal/prediction_techniques/regression.py
rename to gamestonk_terminal/prediction_techniques/regression_view.py
index 8e02f37b44b..2746fc291b1 100644
--- a/gamestonk_terminal/prediction_techniques/regression.py
+++ b/gamestonk_terminal/prediction_techniques/regression_view.py
@@ -1,4 +1,8 @@
+""" Regression View"""
+__docformat__ = "numpy"
+
import argparse
+from typing import List
import datetime
import matplotlib.pyplot as plt
import pandas as pd
@@ -34,7 +38,23 @@ QUADRATIC = 2
CUBIC = 3
-def regression(l_args, s_ticker, df_stock, polynomial):
+def regression(
+ other_args: List[str], s_ticker: str, df_stock: pd.DataFrame, polynomial: int
+):
+ """
+ Train a regression model
+ Parameters
+ ----------
+ other_args: List[str]
+ Argparse arguments
+ s_ticker: str
+ Stock ticker
+ df_stock: pd.DataFrame
+ Dataframe of stock prices
+ polynomial: int
+ Order of polynomial
+
+ """
parser = argparse.ArgumentParser(
add_help=False,
prog="regression",
@@ -95,7 +115,7 @@ def regression(l_args, s_ticker, df_stock, polynomial):
)
try:
- ns_parser = parse_known_args_and_warn(parser, l_args)
+ ns_parser = parse_known_args_and_warn(parser, other_args)
if not ns_parser:
return
diff --git a/gamestonk_terminal/prediction_techniques/sma.py b/gamestonk_terminal/prediction_techniques/sma.py
deleted file mode 100644
index b371553343c..00000000000
--- a/gamestonk_terminal/prediction_techniques/sma.py
+++ /dev/null
@@ -1,313 +0,0 @@
-import argparse
-import datetime
-import numpy as np
-import matplotlib.pyplot as plt
-import pandas as pd
-from pandas.plotting import register_matplotlib_converters
-
-from gamestonk_terminal.helper_funcs import (
- check_positive,
- parse_known_args_and_warn,
- valid_date,
- patch_pandas_text_adjustment,
- get_next_stock_market_days,
- plot_autoscale,
-)
-
-from gamestonk_terminal.prediction_techniques.pred_helper import (
- print_pretty_prediction,
- price_prediction_backtesting_color,
- print_prediction_kpis,
-)
-
-from gamestonk_terminal.config_plot import PLOT_DPI
-from gamestonk_terminal import feature_flags as gtff
-
-register_matplotlib_converters()
-
-
-# pylint: disable=unused-argument
-def simple_moving_average(l_args, s_ticker, df_stock):
- parser = argparse.ArgumentParser(
- add_help=False,
- prog="sma",
- description="""
- Moving Averages are used to smooth the data in an array to
- help eliminate noise and identify trends. The Simple Moving Average is literally
- the simplest form of a moving average. Each output value is the average of the
- previous n values. In a Simple Moving Average, each value in the time period carries
- equal weight, and values outside of the time period are not included in the average.
- This makes it less responsive to recent changes in the data, which can be useful for
- filtering out those changes.
- """,
- )
-
- parser.add_argument(
- "-l",
- "--length",
- action="store",
- dest="n_length",
- type=check_positive,
- default=20,
- help="length of SMA window.",
- )
- parser.add_argument(
- "-d",
- "--days",
- action="store",
- dest="n_days",
- type=check_positive,
- default=5,
- help="prediction days.",
- )
- parser.add_argument(
- "-e",
- "--end",
- action="store",
- type=valid_date,
- dest="s_end_date",
- default=None,
- help="The end date (format YYYY-MM-DD) to select - Backtesting",
- )
-
- try:
- ns_parser = parse_known_args_and_warn(parser, l_args)
- if not ns_parser:
- return
-
- # BACKTESTING
- if ns_parser.s_end_date:
-
- if ns_parser.s_end_date < df_stock.index[0]:
- print(
- "Backtesting not allowed, since End Date is older than Start Date of historical data\n"
- )
- return
-
- if (
- ns_parser.s_end_date
- < get_next_stock_market_days(
- last_stock_day=df_stock.index[0], n_next_days=5 + ns_parser.n_days
- )[-1]
- ):
- print(
- "Backtesting not allowed, since End Date is too close to Start Date to train model\n"
- )
- return
-
- future_index = get_next_stock_market_days(
- last_stock_day=ns_parser.s_end_date, n_next_days=ns_parser.n_days
- )
-
- if future_index[-1] > datetime.datetime.now():
- print(
- "Backtesting not allowed, since End Date + Prediction days is in the future\n"
- )
- return
-
- df_future = df_stock[future_index[0] : future_index[-1]]
- df_stock = df_stock[: ns_parser.s_end_date]
-
- # Prediction data
- l_predictions = list()
- for pred_day in range(ns_parser.n_days):
- if pred_day < ns_parser.n_length:
- l_ma_stock = df_stock["5. adjusted close"].values[
- -ns_parser.n_length + pred_day :
- ]
- else:
- l_ma_stock = list()
- l_predictions.append(np.mean(np.append(l_ma_stock, l_predictions)))
-
- l_pred_days = get_next_stock_market_days(
- last_stock_day=df_stock["5. adjusted close"].index[-1],
- n_next_days=ns_parser.n_days,
- )
- df_pred = pd.Series(l_predictions, index=l_pred_days, name="Price")
-
- # Plotting
- plt.figure(figsize=plot_autoscale(), dpi=PLOT_DPI)
- plt.plot(df_stock.index, df_stock["5. adjusted close"], lw=2)
- # BACKTESTING
- if ns_parser.s_end_date:
- plt.title(
- f"BACKTESTING: {ns_parser.n_length} Moving Average on {s_ticker} - {ns_parser.n_days} days prediction"
- )
- else:
- plt.title(
- f"{ns_parser.n_length} Moving Average on {s_ticker} - {ns_parser.n_days} days prediction"
- )
- plt.xlim(
- df_stock.index[0], get_next_stock_market_days(df_pred.index[-1], 1)[-1]
- )
- plt.xlabel("Time")
- plt.ylabel("Share Price ($)")
- plt.grid(b=True, which="major", color="#666666", linestyle="-")
- plt.minorticks_on()
- plt.grid(b=True, which="minor", color="#999999", linestyle="-", alpha=0.2)
- df_ma = df_stock["5. adjusted close"].rolling(window=ns_parser.n_length).mean()
- plt.plot(df_ma.index, df_ma, lw=2, linestyle="--", c="tab:orange")
- plt.plot(
- [df_stock.index[-1], df_pred.index[0]],
- [df_stock["5. adjusted close"].values[-1], df_pred.values[0]],
- lw=1,
- c="tab:green",
- linestyle="--",
- )
- plt.plot(df_pred.index, df_pred, lw=2, c="tab:green")
- plt.axvspan(
- df_stock.index[-1], df_pred.index[-1], facecolor="tab:orange", alpha=0.2
- )
- _, _, ymin, ymax = plt.axis()
- plt.vlines(
- df_stock.index[-1], ymin, ymax, linewidth=1, linestyle="--", color="k"
- )
-
- # BACKTESTING
- if ns_parser.s_end_date:
- plt.plot(
- df_future.index,
- df_future["5. adjusted close"],
- lw=2,
- c="tab:blue",
- ls="--",
- )
- plt.plot(
- [df_stock.index[-1], df_future.index[0]],
- [
- df_stock["5. adjusted close"].values[-1],
- df_future["5. adjusted close"].values[0],
- ],
- lw=1,
- c="tab:blue",
- linestyle="--",
- )
-
- if gtff.USE_ION:
- plt.ion()
-
- plt.show()
-
- # BACKTESTING
- if ns_parser.s_end_date:
- plt.figure(figsize=plot_autoscale(), dpi=PLOT_DPI)
- plt.subplot(211)
- plt.plot(
- df_future.index,
- df_future["5. adjusted close"],
- lw=2,
- c="tab:blue",
- ls="--",
- )
- plt.plot(df_pred.index, df_pred, lw=2, c="green")
- plt.scatter(
- df_future.index, df_future["5. adjusted close"], c="tab:blue", lw=3
- )
- plt.plot(
- [df_stock.index[-1], df_future.index[0]],
- [
- df_stock["5. adjusted close"].values[-1],
- df_future["5. adjusted close"].values[0],
- ],
- lw=2,
- c="tab:blue",
- ls="--",
- )
- plt.scatter(df_pred.index, df_pred, c="green", lw=3)
- plt.plot(
- [df_stock.index[-1], df_pred.index[0]],
- [df_stock["5. adjusted close"].values[-1], df_pred.values[0]],
- lw=2,
- c="green",
- ls="--",
- )
- plt.title("BACKTESTING: Real data price versus Prediction")
- plt.xlim(df_stock.index[-1], df_pred.index[-1] + datetime.timedelta(days=1))
- plt.xticks(
- [df_stock.index[-1], df_pred.index[-1] + datetime.timedelta(days=1)],
- visible=True,
- )
- plt.ylabel("Share Price ($)")
- plt.grid(b=True, which="major", color="#666666", linestyle="-")
- plt.minorticks_on()
- plt.grid(b=True, which="minor", color="#999999", linestyle="-", alpha=0.2)
- plt.legend(["Real data", "Prediction data"])
- plt.xticks([])
-
- plt.subplot(212)
- plt.axhline(y=0, color="k", linestyle="--", linewidth=2)
- plt.plot(
- df_future.index,
- 100
- * (df_pred.values - df_future["5. adjusted close"].values)
- / df_future["5. adjusted close"].values,
- lw=2,
- c="red",
- )
- plt.scatter(
- df_future.index,
- 100
- * (df_pred.values - df_future["5. adjusted close"].values)
- / df_future["5. adjusted close"].values,
- c="red",
- lw=5,
- )
- plt.title("BACKTESTING: Error between Real data and Prediction [%]")
- plt.plot(
- [df_stock.index[-1], df_future.index[0]],
- [
- 0,
- 100
- * (df_pred.values[0] - df_future["5. adjusted close"].values[0])
- / df_future["5. adjusted close"].values[0],
- ],
- lw=2,
- ls="--",
- c="red",
- )
- plt.xlim(df_stock.index[-1], df_pred.index[-1] + datetime.timedelta(days=1))
- plt.xticks(
- [df_stock.index[-1], df_pred.index[-1] + datetime.timedelta(days=1)],
- visible=True,
- )
- plt.xlabel("Time")
- plt.ylabel("Prediction Error (%)")
- plt.grid(b=True, which="major", color="#666666", linestyle="-")
- plt.minorticks_on()
- plt.grid(b=True, which="minor", color="#999999", linestyle="-", alpha=0.2)
- plt.legend(["Real data", "Prediction data"])
-
- if gtff.USE_ION:
- plt.ion()
-
- plt.show()
-
- # Refactor prediction dataframe for backtesting print
- df_pred.name = "Prediction"
- df_pred = df_pred.to_frame()
- df_pred["Real"] = df_future["5. adjusted close"]
-
- if gtff.USE_COLOR:
-
- patch_pandas_text_adjustment()
-
- print("Time Real [$] x Prediction [$]")
- print(
- df_pred.apply(
- price_prediction_backtesting_color, axis=1
- ).to_string()
- )
- else:
- print(df_pred[["Real", "Prediction"]].round(2).to_string())
-
- print("")
- print_prediction_kpis(df_pred["Real"].values, df_pred["Prediction"].values)
-
- else:
- # Print prediction data
- print_pretty_prediction(df_pred, df_stock["5. adjusted close"].values[-1])
- print("")
-
- except Exception as e:
- print(e)
- print("")
diff --git a/tests/test_pred_neural_networks.py b/tests/test_pred_neural_networks.py
index cc369861296..303038f2a02 100644
--- a/tests/test_pred_neural_networks.py
+++ b/tests/test_pred_neural_networks.py
@@ -2,7 +2,7 @@
import unittest
try:
- from gamestonk_terminal.prediction_techniques.neural_networks import mlp
+ from gamestonk_terminal.prediction_techniques.neural_networks_view import mlp
except ModuleNotFoundError as e:
print("One of the optional packages seems to be missing")
print(e)