 -
-## stats
-
-```text
-usage: stats
-```
-
-Sentiment stats which displays buzz, news score, articles last week, articles weekly average, bullish vs bearish
-percentages, sector average bullish percentage, and sector average news score. [Source:
 -
-# REDDIT
-
-## wsb
-
-```text
-usage: wsb [-l N_LIMIT] [-n]
-```
-
-Print what WSB gang are up to in subreddit wallstreetbets. [Source: Reddit]
-
-* -l : limit of posts to print. Default 10.
-* -n : new flag, if true the posts retrieved are based on being more recent rather than their score. Default False.
-
-
 -
-## watchlist
-
-```text
-usage: watchlist [-l N_LIMIT]
-```
-
-Print other users watchlist. [Source: Reddit]
-
-* -l : limit of posts to print. Default 5.
-
-
 -
-## popular
-
-```text
-usage: popular [-l N_LIMIT] [-s S_SUBREDDIT] [-d N_DAYS]
-```
-
-Print latest popular tickers. [Source: Reddit]
-
-* -l : limit of posts retrieved per sub reddit. Default 50.
-* -s : subreddits to look for tickers, e.g. pennystocks,stocks. Default: pennystocks, RobinHoodPennyStocks, Daytrading,
-StockMarket, stocks, investing, wallstreetbets.
-
-
 -
-## spac_c
-
-```text
-usage: spac_c [-l N_LIMIT] [-p]
-```
-
-Print other users SPACs announcement under subreddit 'SPACs'. [Source: Reddit]
-
-* -l : limit of posts with SPACs retrieved. Default 10.
-* -p : popular flag, if true the posts retrieved are based on score rather than time. Default False.
-
-
 -
-## spac
-
-```text
-usage: spac [-h] [-l N_LIMIT] [-d N_DAYS]
-```
-
-Print other users SPACs announcement under subreddit 'SPACs'. [Source: Reddit]
-
-* -l : limit of posts with SPACs retrieved. Default 5.
-
-
 -
-# STOCKTWITS
-
-## bullbear
-
-```text
-usage: bullbear [-t S_TICKER]
-```
-
-Print bullbear sentiment based on last 30 messages on the board. Also prints the watchlist_count. [Source: Stocktwits]
-
-* -t : ticker to gather sentiment from.
-
-
 -
-## messages
-
-```text
-usage: messages [-t S_TICKER] [-l N_LIM]
-```
-
-Print up to 30 of the last messages on the board. [Source: Stocktwits]
-
-* -t : get board messages from this ticker. Default pre-loaded.
-* -l : limit messages shown. Default 30.
-
-
 -
-## trending
-
-```text
-usage: trending
-```
-
-Stocks trending. [Source: Stocktwits]
-
-
 -
-## stalker
-
-```text
-usage: stalker [-u S_USER] [-l N_LIM]
-```
-
-Print up to the last 30 messages of a user. [Source: Stocktwits]
-
-* -u : username. Default newsfilter.
-* -l : limit messages shown. Default 30.
-
-
 -
-# TWITTER
-
-Uses VADER sentiment. VADER (Valence Aware Dictionary and sEntiment Reasoner) is a lexicon and rule-based sentiment
-analysis tool that is specifically attuned to sentiments expressed in social media.
-
-The output of VADER analysis :
-
-```text
-The compound score is computed by summing the valence scores of each word in the lexicon, adjusted according to the
-rules, and then normalized to be between -1 (most extreme negative) and +1 (most extreme positive). This is the most
-useful metric if you want a single unidimensional measure of sentiment for a given sentence. Calling it a 'normalized,
- weighted composite score' is accurate.
-```
-
-A sample tweet is shown below along with what the VADER polarity scores are.
-
-```text
-Have some $SENS 🚀🏆\n👉FDA approval coming very soon, 👉News is out, amazing test results. \n👉Very high short
-interest rate. \n👉Major short squeeze coming. \n\n$amc $gme $nakd $ctrm $tsla $aapl $oeg $aht $bbby $bb $fsr $spce
- https://t.co/B0cPhufpA2'
-```
-
-This gives the following scores:
-
-```python
-created_at Thu Jun 03 20:37:54
-text Have some $SENS 🚀🏆\n👉FDA approval coming very...
-sentiment 0.872
-positive 0.177
-negative 0
-neutral 0.823
-```
-
-Note that both functions use twitters v2 endpoint, which only gives 7 days of historical data. It also requires at
-least 10 tweets be pulled.
-
-## infer
-
-```text
-usage: infer [-n N_NUM]
-```
-
-Print quick sentiment inference from last tweets that contain the ticker. This model splits the text into
-character-level tokens and uses theVADER model to make predictions.
-
-* -n : num of latest tweets to infer from. Default 100.
-
-## sentiment
-
-```text
-usage: sentiment [-n N_NUM] [-d N_DAYS_PAST]
-```
-
-Plot in-depth sentiment extracted from tweets from last days that contain pre-defined ticker. This model splits the
-text into character-level tokens and uses the VADER model to make predictions.
-
-* -n : num of tweets to extract per hour. Default 15.
-* -d : num of days in the past to extract tweets. Default 6. Max 6
-
-# GOOGLE
-
-## mentions
-
-```text
-usage: mentions [-s S_START]
-```
-
-Plot weekly bars of stock's interest over time. other users watchlist. [Source: Google]
-
-* -s : starting date (format YYYY-MM-DD) from when we are interested in stock's mentions. Default: the one provided
-in main menu.
-
-
-
-## regions
-
-```text
-usage: regions [-n N_NUM]
-```
-
-Plot bars of regions based on stock's interest. [Source: Google]
-
-* -n : number of regions to plot that show highest interest. Default 10.
-
-
-
-## queries
-
-```text
-usage: queries [-n N_NUM]
-```
-
-Print top related queries with this stock's query. [Source: Google]
-
-* -n : number of top related queries to print. Default 10.
-
-
 -
-## rise
-
-```text
-usage: rise [-n N_NUM]
-```
-
-Print top rising related queries with this stock's query. [Source: Google]
-
-* -n : number of top rising related queries to print. Default 10.
-
-
 -
-# SENTIMENTINVESTOR
-
-> **[Sentiment Investor](https://sentimentinvestor.com)** analyzes data from four major social media platforms to
-> generate hourly metrics on over 2,000 stocks. Sentiment provides volume and
-> sentiment metrics powered by proprietary NLP models.
-
-## Metric definitions
-
-### AHI (Absolute Hype Index)
-
-AHI is a measure of how much people are talking about a stock on social media.
-It is calculated by dividing the total number of mentions for the chosen stock
-on a social network by the mean number of mentions any stock receives on that
-social medium.
-
-### RHI (Relative Hype Index)
-
-RHI is a measure of whether people are talking about a stock more or less than
-usual, calculated by dividing the mean AHI for the past day by the mean AHI for
-for the past week for that stock.
-
-### Sentiment Score
-
-Sentiment score is the percentage of people talking positively about the stock.
-For each social network the number of positive posts/comments is divided by the
-total number of both positive and negative posts/comments.
-
-### SGP (Standard General Perception)
-
-SGP is a measure of whether people are more or less positive about a stock than
-usual. It is calculated by averaging the past day of sentiment values and then
-dividing it by the average of the past week of sentiment values.
-
-## metrics
-
-```text
-usage: metrics [-h] [ticker]
-```
-
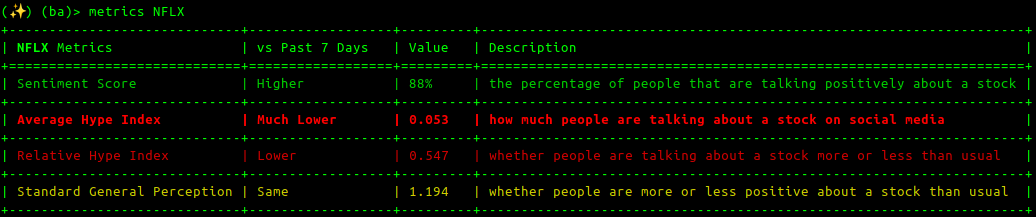
-The `metrics` command presents the four core metrics provided by Sentiment Investor,
-including AHI, RHI, sentiment and SGP, as described above.
-
-Optional arguments:
-
-* [optional, positional] ticker
- ticker to use instead of the loaded one
-* `-h`, `--help`
- show this help message
-
-Example output:
-
-
-
-## social
-
-```text
-usage: social [-h] [ticker]
-```
-
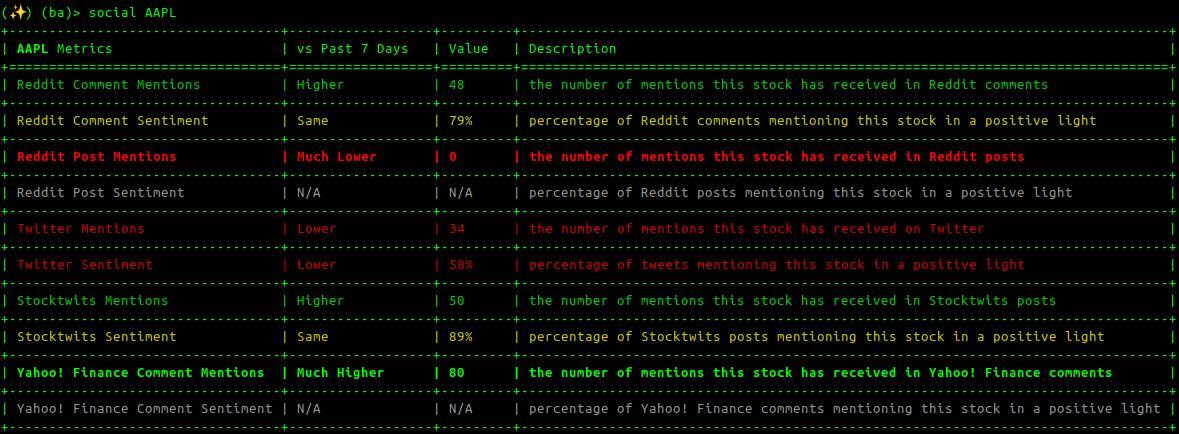
-The `social` command prints the raw data for a given stock, including the number
-of mentions it has received on social media in the last hour and the sentiment
-score of those comments.
-
-Optional arguments:
-
-* [optional, positional] ticker
- ticker to use instead of the loaded one
-* `-h`, `--help`
- show this help message
-
-Example output:
-
-
-
-## historical
-
-```text
-usage: historical [-t TICKER] [-s [{date,value}]] [-d [{asc,desc}]] [-h] [{sentiment,AHI,RHI,SGP}]
-```
-
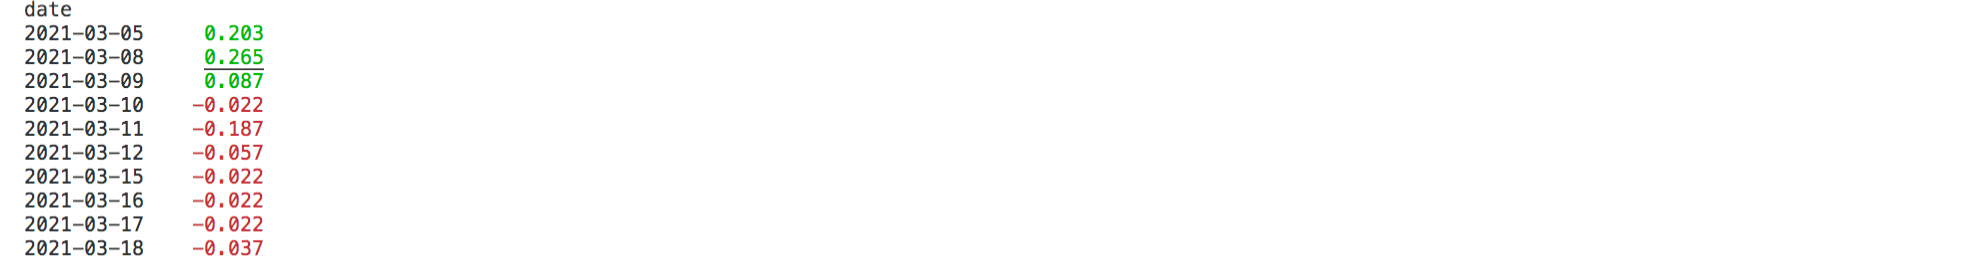
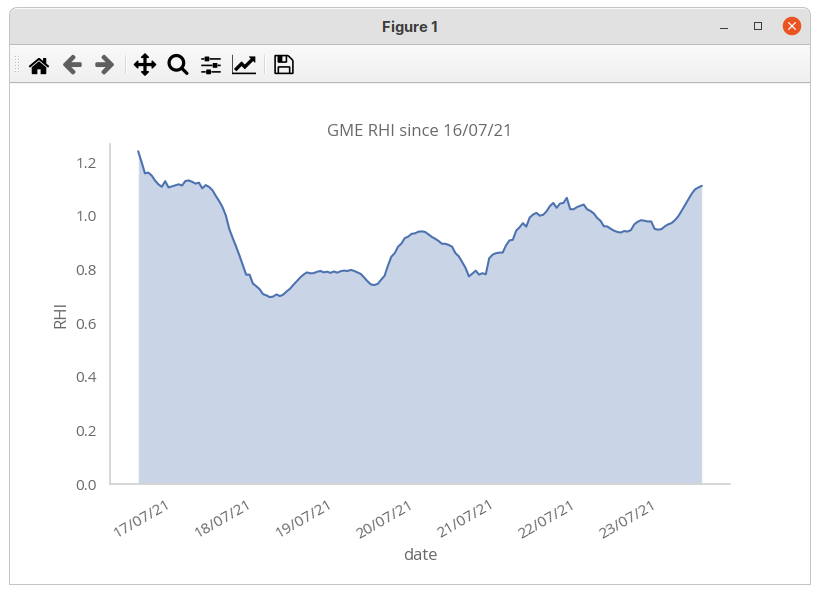
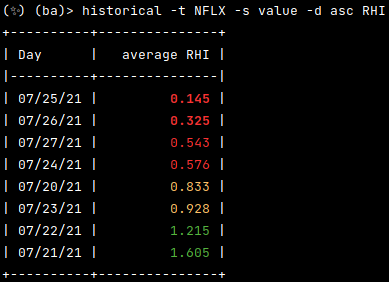
-The `historical` command plots the past week of data for a selected
-SentimentInvestor core metric, one of:
-[AHI](#ahi), [RHI](#ahi), [sentiment](#sentiment) or [SGP](#SGP).
-It also outputs a sorted table of the mean value for that metric for each day.
-
-Positional arguments:
-
-* one of `sentiment`, `AHI`, `RHI` or `SGP`
- (optional) the metric to plot (default: `sentiment`)
-
-Optional arguments:
-
-* `-t`, `--ticker TICKER`
- ticker for which to fetch data
-* `-s`, `--sort [{date,value}]`
- the parameter to sort output table by
-* `-d`, `--direction [{asc,desc}]`
- the direction to sort the output table
-* `-h`, `--help`
- show this help message
-
-Example output:
-
-
-
-
diff --git a/gamestonk_terminal/common/prediction_techniques/README.md b/gamestonk_terminal/common/prediction_techniques/README.md
deleted file mode 100644
index 0cf3e5c79b0..00000000000
--- a/gamestonk_terminal/common/prediction_techniques/README.md
+++ /dev/null
@@ -1,308 +0,0 @@
-# PREDICTION TECHNIQUES
-
-This menu aims to predict the share price of a pre-loaded stock, and the usage of the following commands along with an
-example will be exploited below. See [How to fune-tuning a NN model](FUNE-TUNING-NN-models.md).
-
-* [ets](#ets)
- * Exponential Smoothing (e.g. Holt-Winters)
-* [knn](#knn)
- * k-Nearest Neighbors
-* [linear](#linear)
- * linear regression (polynomial 1)
-* [quadratic](#quadratic)
- * quadratic regression (polynomial 2)
-* [cubic](#cubic)
- * cubic regression (polynomial 3)
-* [regression](#regression)
- * regression (other polynomial)
-* [arima](#arima)
- * autoregressive integrated moving average
-* [mlp](#mlp)
- * MultiLayer Perceptron
-* [rnn](#rnn)
- * Recurrent Neural Network
- * Contains a [looping example](#looping)
-* [lstm](#lstm)
- * Long-Short Term Memory
- * Contains a [backtesting example](#backtesting)
-* [conv1d](#conv1d)
- * 1D Convolutional Neural Net
-
-**Note:** _Use this at your own discretion. All of these prediciton techniques rely solely on the closing price of the
-stock. This means that there are several factors that the models aren't aware of at the time of prediction, and may -
-drastically - move the price up or down. Examples are: news, analyst price targets, reddit post, tweets from Elon Musk,
-and so on._
-
-**Note 2:** _[Enabling GPU acceleration for TensorFlow requires CUDA setup](README-gpu-accel.md) and will probably not
-provide any speedup unless you are building large custom models._
-
-## ets
-
-```text
-usage: ets [-t TREND] [-s SEASONAL] [-p SEASONAL_PERIODS] [-d N_DAYS]
-```
-
-Exponential Smoothing (based on trend+seasonality, see
Example: `-o 5,1,4` where: - * p = 5 : order (number of time lags) of the autoregressive model. - * d = 1 : degree of differencing (the number of times the data have had past values subtracted). - * q = 4 : order of the moving-average model. -* -e : end date (format YYYY-MM-DD) of the stock - Backtesting. Default None. - - - -## mlp - -```text -usage: mlp [-d N_DAYS] [-i N_INPUTS] [--epochs N_EPOCHS] [-e S_END_DATE] [--loops N_LOOPS] [-v VALID] - [--lr LEARNING_RATE] [--no_shuffle] -``` - -MulitLayer Perceptron: - -* -d : prediciton days. Default 5. -* -i : number of days to use for prediction. Default 40. -* --epochs : number of training epochs. Default 200. -* -v : validation split. Default 0.1 -* -e : end date (format YYYY-MM-DD) of the stock - Backtesting. Default None. -* --xla_cpu: if present, will enable XLA for CPU (overrides environment variables during run). -* --xla_gpu: if present, will enable XLA for GPU (overrides environment variables during run). -* --force_allow_gpu_growth: if true, will force TensorFlow to allow GPU memory usage to grow as needed. Otherwise will - allocate 100% of available GPU memory when CUDA is set up. Default true. -* --batch_size: batch size for model training, should not be used unless advanced user. Default None. -* --lr : learning rate for optimizer -* --loops: number of loops to iterate and train models. Default 1. -* --no_shuffle : split validation data in time_ordered way instead of random. - -Due to the complexity of defining a model through command line, one can define it in: -[config_neural_network_models.txt](/config_neural_network_models.py) - -```python -MultiLayer_Perceptron \ - = [ {'Dense': - {'units':50, 'activation':'relu'} }, - {'Dense': - {'units':100, 'activation':'relu'} }, - {'Dense': - {'units':80, 'activation':'relu'} }, - {'Dense': - {'units':30, 'activation':'relu'} }, - {'Dense': - {'activation':'relu'} }] -``` - - - -## rnn - -```text -usage: rnn [-d N_DAYS] [-i N_INPUTS] [--epochs N_EPOCHS] [-p {normalization,standardization,none}] - [-l {mae,mape,mse,msle}] [-e S_END_DATE] [--loops N_LOOPS] [-v VALID] [--lr LEARNING_RATE] [--no_shuffle] -``` - -Recurrent Neural Network: - -* -d : prediciton days. Default 5. -* -i : number of days to use for prediction. Default 40. -* --epochs : number of training epochs. Default 200. -* -v : validation split. Default 0.1 -* -e : end date (format YYYY-MM-DD) of the stock - Backtesting. Default None. -* --xla_cpu: if present, will enable XLA for CPU (overrides environment variables during run). -* --xla_gpu: if present, will enable XLA for GPU (overrides environment variables during run). -* --force_allow_gpu_growth: if true, will force TensorFlow to allow GPU memory usage to grow as needed. - Otherwise will allocate 100% of available GPU memory when CUDA is set up. Default true. -* --batch_size: batch size for model training, should not be used unless advanced user. Default None. -* --loops: number of loops to iterate and train models. Default 1. -* --lr : learning rate for optimizer -* --no_shuffle : split validation data in time_ordered way instead of random. - -Due to the complexity of defining a model through command line, one can define it in: -[config_neural_network_models.txt](/config_neural_network_models.py) - -```python -Recurrent_Neural_Network \ - = [ {'SimpleRNN': - {'units':100, 'activation':'linear', 'return_sequences':True} }, - {'SimpleRNN': - {'units':50, 'activation':'linear', 'return_sequences':True} }, - {'Dropout': - {'rate':0.2} }, - {'SimpleRNN': - {'units':21, 'activation':'linear', 'return_sequences':False} }, - {'Dense': - {'activation':'relu'} }] -``` - - - -### Looping Example - - - -
 -
-## lstm
-
-```text
-usage: lstm [-d N_DAYS] [-i N_INPUTS] [--epochs N_EPOCHS] [-e S_END_DATE] [--loops N_LOOPS] [-v VALID]
- [--lr LEARNING_RATE] [--no_shuffle]
-```
-
-Long-Short Term Memory:
-
-* -d : prediction days. Default 5.
-* -i : number of days to use for prediction. Default 40.
-* --epochs : number of training epochs. Default 200.
-* -v : validation split. Default 0.1
-* -e : end date (format YYYY-MM-DD) of the stock - Backtesting. Default None.
-* --xla_cpu: if present, will enable XLA for CPU (overrides environment variables during run).
-* --xla_gpu: if present, will enable XLA for GPU (overrides environment variables during run).
-* --force_allow_gpu_growth: if true, will force TensorFlow to allow GPU memory usage to grow as needed. Otherwise will
- allocate 100% of available GPU memory when CUDA is set up. Default true.
-* --batch_size: batch size for model training, should not be used unless advanced user. Default None.
-* --loops: number of loops to iterate and train models. Default 1
-* --lr : learning rate for optimizer
-* --no_shuffle : split validation data in time_ordered way instead of random.
-
-Due to the complexity of defining a model through command line, one can define it in:
-[config_neural_network_models.py](/config_neural_network_models.py)
-
-```python
-Long_Short_Term_Memory \
- = [ {'LSTM':
- {'units':25, 'activation':'tanh', 'return_sequences':True} },
- {'LSTM':
- {'units':15, 'activation':'tanh', 'return_sequences':False} },
- {'Dense':
- {'activation':'relu'} }]
-```
-
-
-
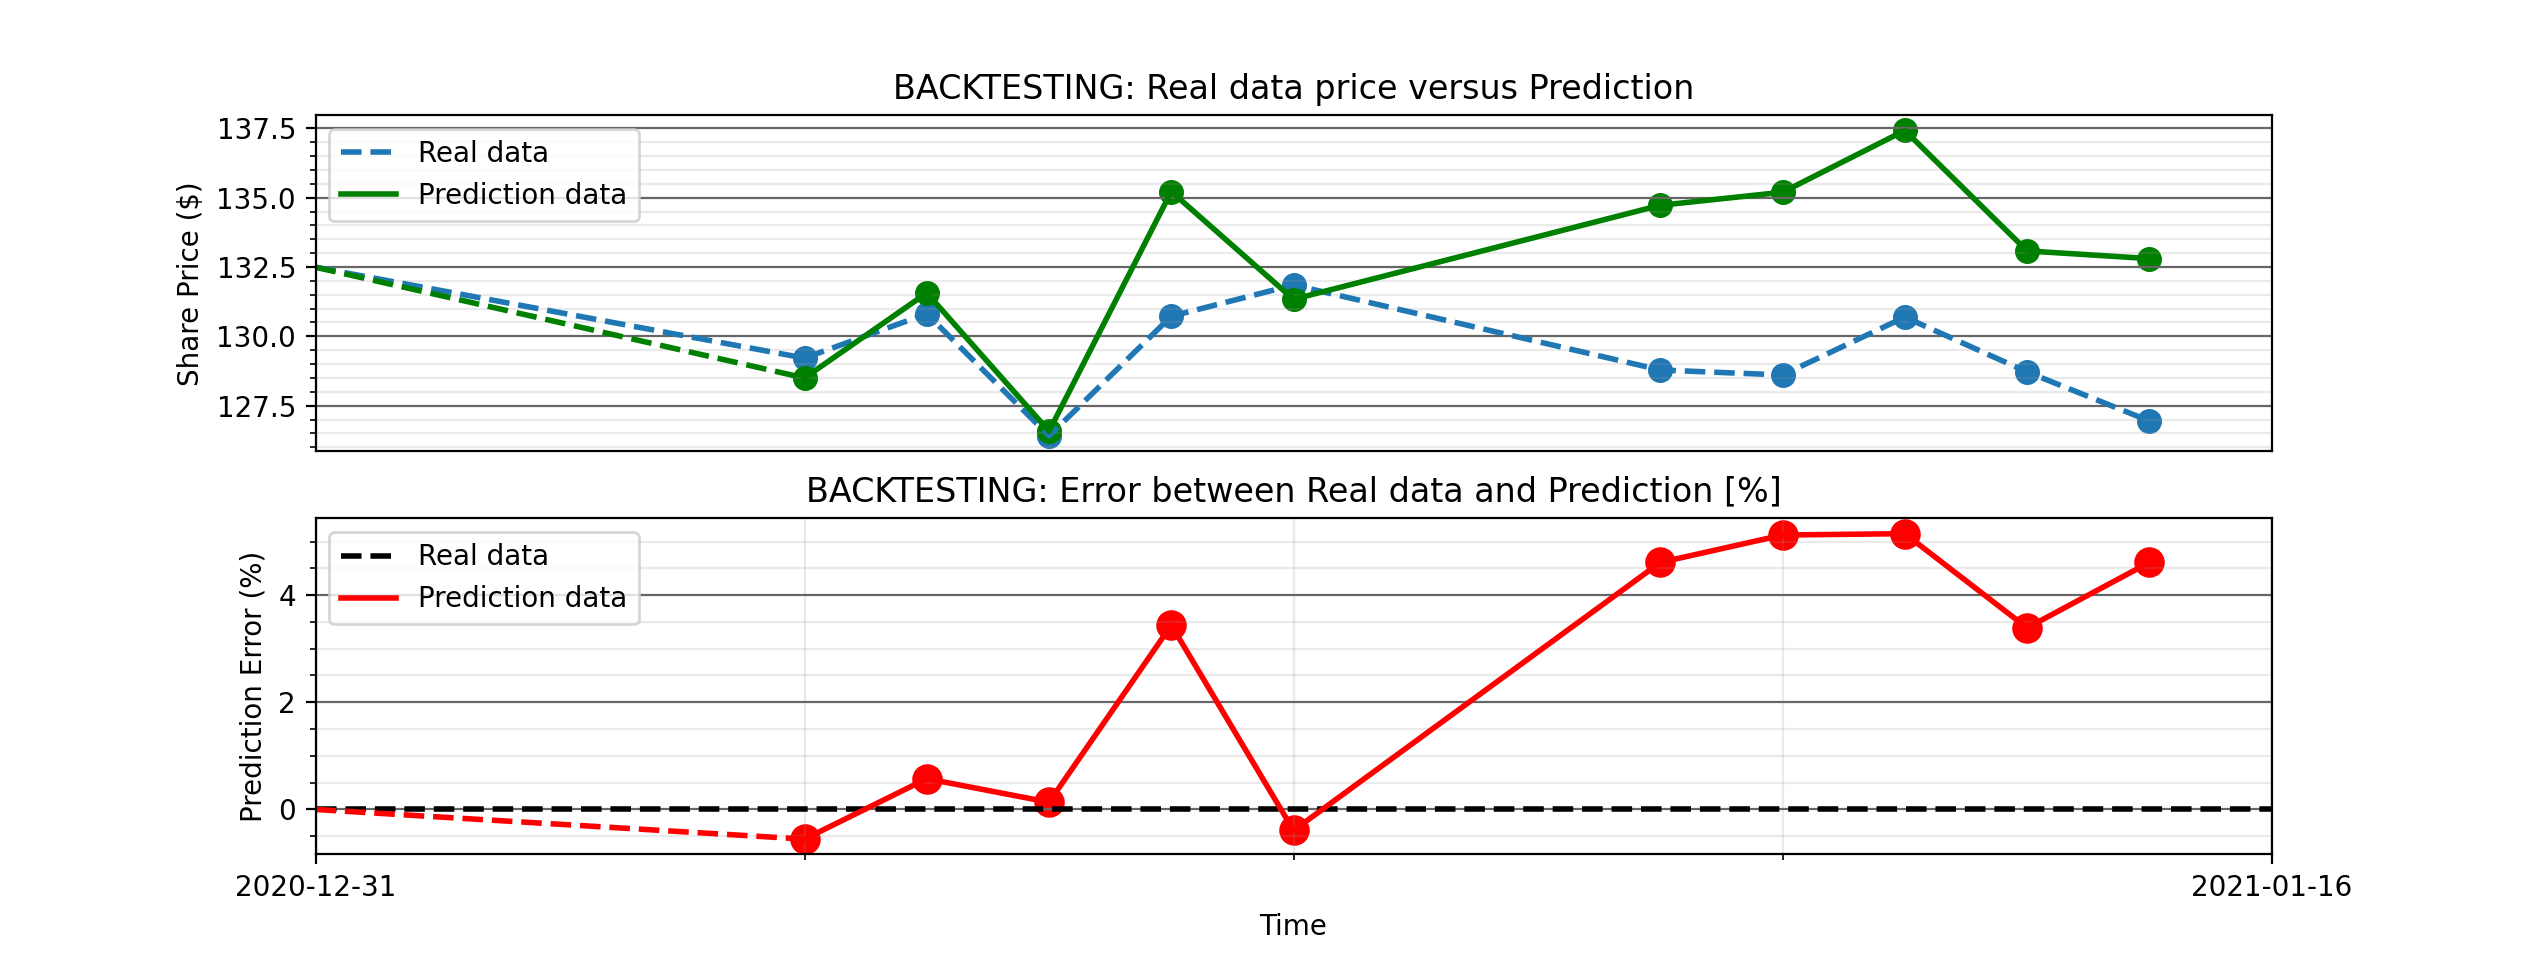
-### Backtesting Example
-
-
-
-
-
-
 -
-## conv1d
-
-```text
-usage: lstm [-d N_DAYS] [-i N_INPUTS] [--epochs N_EPOCHS] [-e S_END_DATE] [--loops N_LOOPS] [-v VALID]
-[--lr LEARNING_RATE] [--no_shuffle]
-```
-
-1D Convolutional Neural Net:
-
-* -d : prediction days. Default 5.
-* -i : number of days to use for prediction. Default 40.
-* --epochs : number of training epochs. Default 50.
-* -v : validation split. Default 0.1
-* -e : end date (format YYYY-MM-DD) of the stock - Backtesting. Default None.
-* --xla_cpu: if present, will enable XLA for CPU (overrides environment variables during run).
-* --xla_gpu: if present, will enable XLA for GPU (overrides environment variables during run).
-* --force_allow_gpu_growth: if true, will force TensorFlow to allow GPU memory usage to grow as needed. Otherwise will
- allocate 100% of available GPU memory when CUDA is set up. Default true.
-* --batch_size: batch size for model training, should not be used unless advanced user. Default None.
-* --loops: number of loops to iterate and train models. Default 1.
-* --lr : learning rate for optimizer
-* --no_shuffle : split validation data in time_ordered way instead of random.
diff --git a/gamestonk_terminal/common/technical_analysis/README.md b/gamestonk_terminal/common/technical_analysis/README.md
deleted file mode 100644
index 2e7258f5a25..00000000000
--- a/gamestonk_terminal/common/technical_analysis/README.md
+++ /dev/null
@@ -1,240 +0,0 @@
-# TECHNICAL ANALYSIS
-
-This menu aims to perform a technical analysis on a pre-loaded ticker chart, and the usage of the following commands
-along with an example will be exploited below.
-
-* [view](#view)
- * view historical data and trendlines [Finviz]
-* [summary](#summary)
- * technical summary report [FinBrain API]
-* [recom](#recom)
- * recommendation based on Technical Indicators [Tradingview API]
-* [pr](#pr)
- * pattern recognition [Finnhub]
-
-[OVERLAP](#OVERLAP)
-
-* [ema](#ema)
- * exponential moving average
-* [sma](#sma)
- * simple moving average
-* [vwap](#vwap)
- * volume weighted average price
-
-[MOMENTUM](#MOMENTUM)
-
-* [cci](#cci)
- * commodity channel index
-* [macd](#macd)
- * moving average convergence/divergence
-* [rsi](#rsi)
- * relative strength index
-* [stoch](#stoch)
- * stochastic oscillator
-
-[TREND](#TREND)
-
-* [adx](#adx)
- * average directional movement index
-* [aroon](#aroon)
- * aroon indicator
-
-[VOLATILITY](#VOLATILITY)
-
-* [bbands](#bbands)
- * bollinger bands
-
-[VOLUME](#VOLUME)
-
-* [ad](#ad)
- * Accumulation/distribution line values
-* [obv](#obv)
- * on balance volume
-
-[CUSTOM](#CUSTOM)
-
-* [fib](#fib)
- * Shows fibonocci levels
-
-**S/O to
 -
-## recom
-
-```text
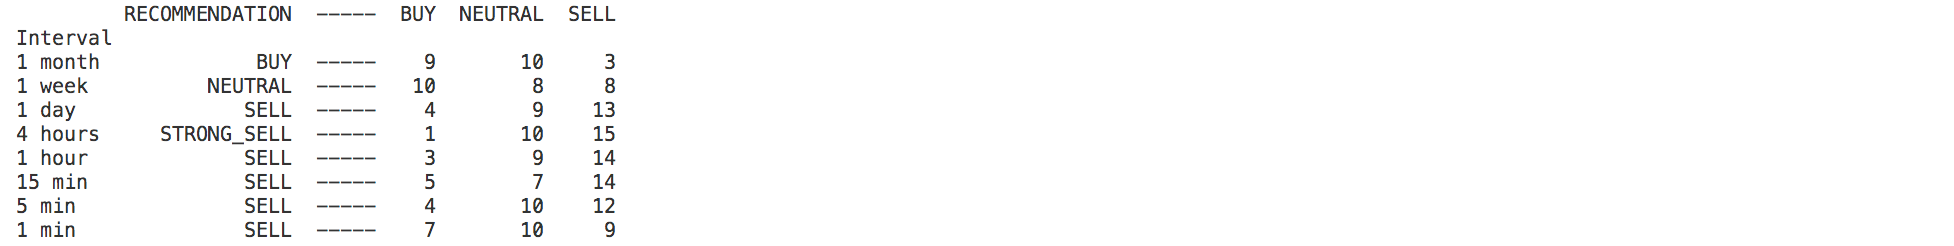
-usage: recom [-s {crypto,forex,cfd}] [-e EXCHANGE] [-i {1M,1W,1d,4h,1h,15m,5m,1m}]
-```
-
-Print tradingview recommendation based on technical indicators. [Source:
 -
-## pr
-
-```text
-usage: pr [-r {1,5,15,30,60,D,W,M}]
-```
-
-Display pattern recognition signals on the data. [Source:
 -
-# OVERLAP
-
-## ema
-
-```text
-usage: ema [-l N_LENGTH] [-o N_OFFSET]
-```
-
-
-
-## sma
-
-```text
-usage: sma [-l L_LENGTH] [-o N_OFFSET]
-```
-
-
-
-## vwap
-
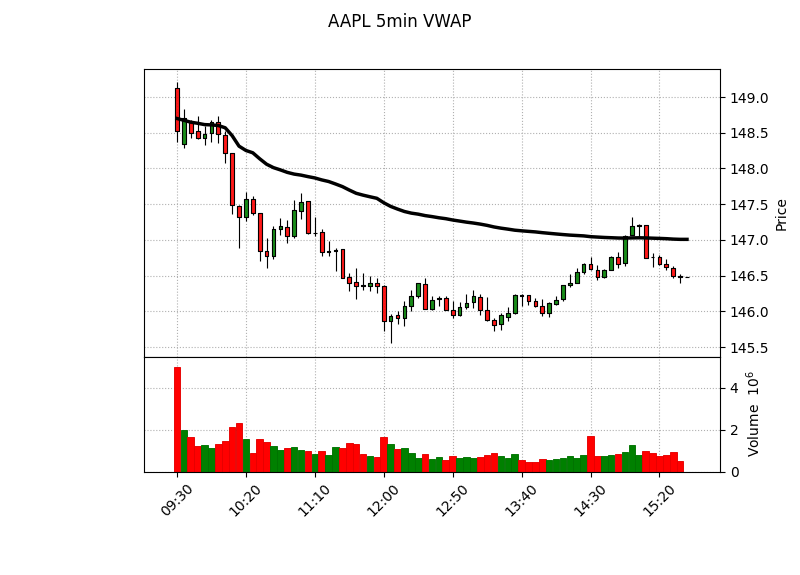
-VWAP is available for intraday data. This plots the most recent day only.
-
-```text
-usage: vwap [-o N_OFFSET]
-```
-
-
-
-# MOMENTUM
-
-## cci
-
-```text
-usage: cci [-l N_LENGTH] [-s N_SCALAR] [-o N_OFFSET]
-```
-
-
-
-## macd
-
-```text
-usage: macd [-f N_FAST] [-s N_SLOW] [--signal N_SIGNAL] [-o N_OFFSET]
-```
-
-
-
-## rsi
-
-```text
-usage: rsi [-l N_LENGTH] [-s N_SCALAR] [-d N_DRIFT] [-o N_OFFSET]
-```
-
-
-
-## stoch
-
-```text
-usage: stoch [-k N_FASTKPERIOD] [-d N_SLOWDPERIOD] [--slowkperiod N_SLOWKPERIOD] [-o N_OFFSET]
-```
-
-
-
-# TREND
-
-## adx
-
-```text
-usage: adx [-l N_LENGTH] [-s N_SCALAR] [-d N_DRIFT] [-o N_OFFSET]
-```
-
-
-
-## aroon
-
-```text
-usage: aroon [-l N_LENGTH] [-s N_SCALAR] [-o N_OFFSET]
-```
-
-
-
-# VOLATILITY
-
-## bbands
-
-```text
-usage: bbands [-h] [-l N_LENGTH] [-s N_STD] [-m S_MAMODE] [-o N_OFFSET]
-```
-
-
-
-# VOLUME
-
-## ad
-
-```text
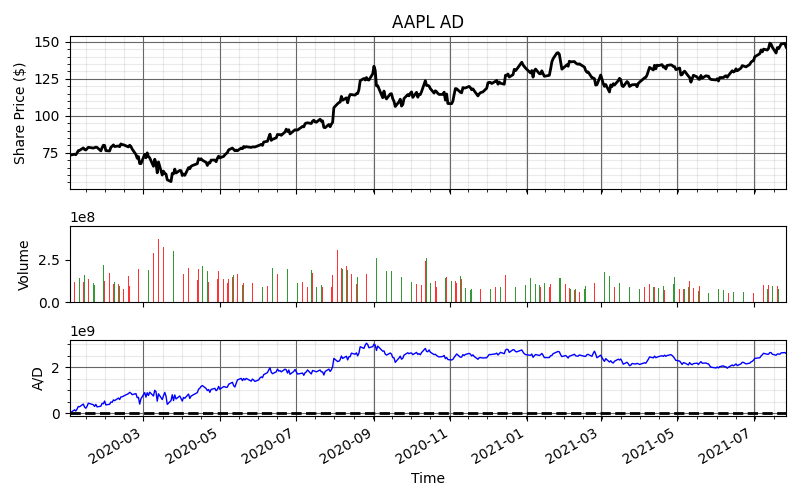
-usage: ad [-o N_OFFSET] [--open]
-```
-
-
-
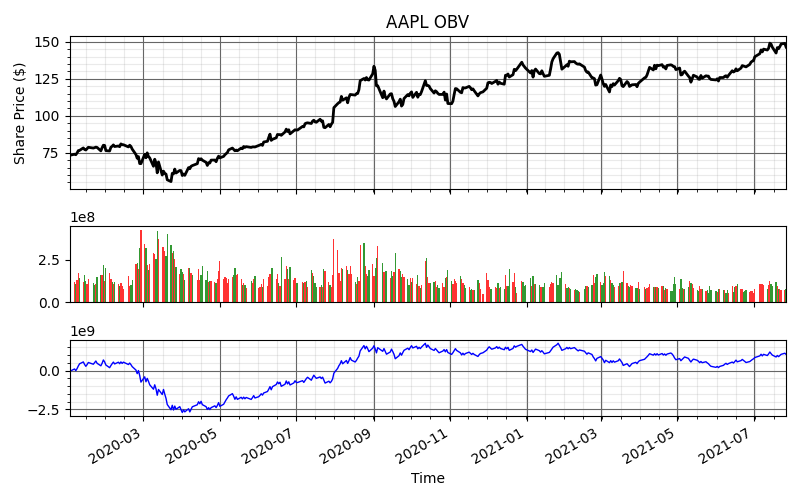
-## obv
-
-```text
-usage: obv [-o N_OFFSET]
-```
-
-
-
-# CUSTOM
-
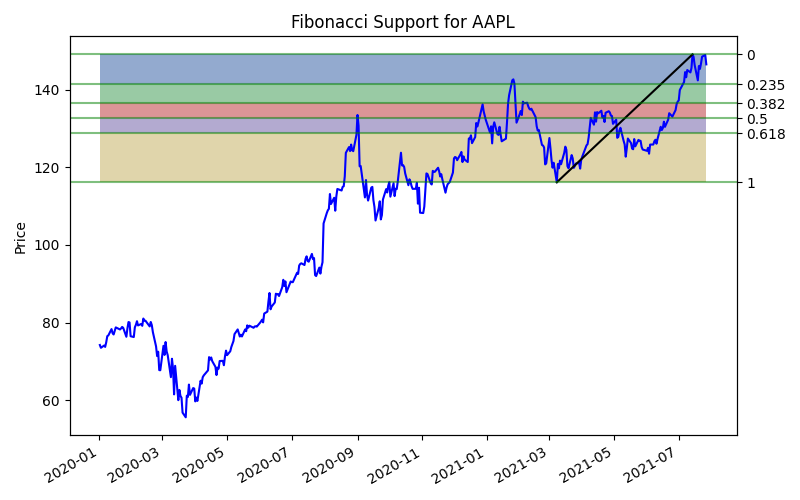
-## fib
-
-Shows fibonocci levels
-
-```python
-usage: fib [-p PERIOD] [--start] [--end]
-```
-
-* -p/--period: Number of days to lookback for retracement. Default = 120.
-* --start: Allows for custom selection of min point.
-* --end : Allows for custom selection of max point.
-
-The fibonocci retracement works by looking at a minimum and maximum point. Between these values, there is typically
-support/resistance at 23.5 %, 38.2%, 50% and 61.8%. Those values follow the golden ratio from the fibonocci sequence.
-
-The `--start` and `--end` flags allow the user to select dates for the min and max points as your retracement levels.
-Both flags are required if using.
-
-
diff --git a/gamestonk_terminal/stocks/discovery/README.md b/gamestonk_terminal/stocks/discovery/README.md
index f9df0f30561..a338f4f7459 100644
--- a/gamestonk_terminal/stocks/discovery/README.md
+++ b/gamestonk_terminal/stocks/discovery/README.md
@@ -15,8 +15,8 @@ Command|Description|Source
`ford` |orders by Fidelity Customers |[Fidelity](https://www.fidelity.com/)
`arkord` |orders by ARK Investment Management LLC | [Cathiesark](https://www.cathiesark.com)
`upcoming` |upcoming earnings release dates |[Seeking Alpha](https://seekingalpha.com/)
-`latest` |latest news |[Seeking Alpha](https://seekingalpha.com/)
`trending` |trending news |[Seeking Alpha](https://seekingalpha.com/)
+`cnews` |customized news (buybacks, ipos, spacs, healthcare, politics) |[Seeking Alpha](https://seekingalpha.com/)
`low_float` |show low float stocks under 10M shares float |[Low Float](https://www.lowfloat.com/)
`hotpenny` |today's hot penny stocks |[hotpenny](https://pennystockflow.com)
`fds` |advanced Equities search based on country, sector, industry, name and/or description |[FinanceDatabase](https://github.com/JerBouma/FinanceDatabase)
diff --git a/gamestonk_terminal/stocks/discovery/disc_controller.py b/gamestonk_terminal/stocks/discovery/disc_controller.py
index 3e3faebfeeb..63c4ffb5c9c 100644
--- a/gamestonk_terminal/stocks/discovery/disc_controller.py
+++ b/gamestonk_terminal/stocks/discovery/disc_controller.py
@@ -58,12 +58,12 @@ class DiscoveryController:
"ford",
"arkord",
"upcoming",
- "latest",
"trending",
"lowfloat",
"hotpenny",
"rtearn",
"fds",
+ "cnews",
]
CHOICES += CHOICES_COMMANDS
@@ -105,8 +105,8 @@ cathiesark.com:
arkord orders by ARK Investment Management LLC
Seeking Alpha:
upcoming upcoming earnings release dates
- latest latest news
trending trending news
+ cnews customized news (buybacks, ipos, spacs, healthcare, politics)
shortinterest.com
lowfloat low float stocks under 10M shares float
pennystockflow.com
@@ -683,66 +683,6 @@ Finance Database:
export=ns_parser.export,
)
- @try_except
- def call_latest(self, other_args: List[str]):
- """Process latest command"""
- parser = argparse.ArgumentParser(
- add_help=False,
- formatter_class=argparse.ArgumentDefaultsHelpFormatter,
- prog="latest",
- description="""Latest news articles. [Source: Seeking Alpha]""",
- )
- parser.add_argument(
- "-i",
- "--id",
- action="store",
- dest="n_id",
- type=check_positive,
- default=-1,
- help="article ID",
- )
- parser.add_argument(
- "-n",
- "--num",
- action="store",
- dest="n_num",
- type=check_positive,
- default=5,
- help="number of articles being printed",
- )
- parser.add_argument(
- "-d",
- "--date",
- action="store",
- dest="s_date",
- type=valid_date,
- default=datetime.now().strftime("%Y-%m-%d"),
- help="starting date of articles",
- )
- parser.add_argument(
- "--export",
- choices=["csv", "json", "xlsx"],
- default="",
- type=str,
- dest="export",
- help="Export dataframe data to csv,json,xlsx file",
- )
- if other_args:
- if "-" not in other_args[0]:
- other_args.insert(0, "-i")
-
- ns_parser = parse_known_args_and_warn(parser, other_args)
- if not ns_parser:
- return
-
- seeking_alpha_view.news(
- news_type="latest",
- article_id=ns_parser.n_id,
- num=ns_parser.n_num,
- start_date=ns_parser.s_date,
- export=ns_parser.export,
- )
-
@try_except
def call_trending(self, other_args: List[str]):
"""Process trending command"""
@@ -844,6 +784,78 @@ Finance Database:
export=ns_parser.export,
)
+ @try_except
+ def call_cnews(self, other_args: List[str]):
+ """Process cnews command"""
+ parser = argparse.ArgumentParser(
+ add_help=False,
+ formatter_class=argparse.ArgumentDefaultsHelpFormatter,
+ prog="cnews",
+ description="""Customized news. [Source: Seeking Alpha]""",
+ )
+ l_news_type = [
+ "Top-News",
+ "On-The-Move",
+ "Market-Pulse",
+ "Notable-Calls",
+ "Buybacks",
+ "Commodities",
+ "Crypto",
+ "Issuance",
+ "Global",
+ "Guidance",
+ "IPOs",
+ "SPACs",
+ "Politics",
+ "M-A",
+ "Consumer",
+ "Energy",
+ "Financials",
+ "Healthcare",
+ "MLPs",
+ "REITs",
+ "Technology",
+ ]
+ parser.add_argument(
+ "-t",
+ "--type",
+ action="store",
+ dest="s_type",
+ choices=[tnews.lower() for tnews in l_news_type],
+ default="Top-News",
+ help="number of news to display",
+ )
+ parser.add_argument(
+ "-n",
+ "--num",
+ action="store",
+ dest="n_num",
+ type=check_positive,
+ default=5,
+ help="number of news to display",
+ )
+ parser.add_argument(
+ "--export",
+ choices=["csv", "json", "xlsx"],
+ default="",
+ type=str,
+ dest="export",
+ help="Export dataframe data to csv,json,xlsx file",
+ )
+ if other_args:
+ if "-" not in other_args[0]:
+ other_args.insert(0, "-t")
+
+ ns_parser = parse_known_args_and_warn(parser, other_args)
+ if not ns_parser:
+ return
+
+ seeking_alpha_view.display_news(
+ news_type=ns_parser.s_type,
+ num=ns_parser.n_num,
+ export=ns_parser.export,
+ )
+
@try_except
def call_hotpenny(self, other_args: List[str]):
"""Process hotpenny command"""
diff --git a/gamestonk_terminal/stocks/discovery/seeking_alpha_model.py b/gamestonk_terminal/stocks/discovery/seeking_alpha_model.py
index 31a3ceded78..8a242b15c9b 100644
--- a/gamestonk_terminal/stocks/discovery/seeking_alpha_model.py
+++ b/gamestonk_terminal/stocks/discovery/seeking_alpha_model.py
@@ -1,7 +1,7 @@
""" Seeking Alpha Model """
__docformat__ = "numpy"
-from typing import List
+from typing import List, Dict
from datetime import datetime
import requests
from bs4 import BeautifulSoup
@@ -210,3 +210,66 @@ def get_article_data(article_id: int) -> dict:
}
return article
+
+
+def get_news_html(news_type: str = "Top-News") -> dict:
+ """Gets news. [Source: SeekingAlpha]
+
+ Parameters
+ ----------
+ news_type : str
+ From: Top-News, On-The-Move, Market-Pulse, Notable-Calls, Buybacks, Commodities, Crypto, Issuance, Global,
+ Guidance, IPOs, SPACs, Politics, M-A, Consumer, Energy, Financials, Healthcare, MLPs, REITs, Technology
+
+ Returns
+ -------
+ dict
+ HTML page of articles
+ """
+ sa_url = (
+ f"http://seekingalpha.com/api/v3/news?filter%5Bcategory%5D=market-news%3A%3A{news_type}"
+ "&filter%5Bsince%5D=0&filter%5Buntil%5D=0&include=author%2CprimaryTickers%2CsecondaryTickers"
+ "&isMounting=true&page%5Bsize%5D=25&page%5Bnumber%5D=1"
+ )
+
+ articles_html = requests.get(
+ sa_url, headers={"User-Agent": get_user_agent()}
+ ).json()
+
+ return articles_html
+
+
+def get_news(news_type: str = "Top-News", num: int = 5) -> List:
+ """Gets news. [Source: SeekingAlpha]
+
+ Parameters
+ ----------
+ news_type : str
+ From: Top-News, On-The-Move, Market-Pulse, Notable-Calls, Buybacks, Commodities, Crypto, Issuance, Global,
+ Guidance, IPOs, SPACs, Politics, M-A, Consumer, Energy, Financials, Healthcare, MLPs, REITs, Technology
+ num : int
+ Number of news to display
+
+ Returns
+ -------
+ List[dict]
+ List of dict news
+ """
+ news_articles: Dict = get_news_html(news_type)
+ news_to_display = list()
+
+ if news_articles:
+ for idx, news in enumerate(news_articles["data"]):
+ if idx > num:
+ break
+
+ news_to_display.append(
+ {
+ "publishOn": news["attributes"]["publishOn"].replace("T", " ")[:-6],
+ "id": news["id"],
+ "title": news["attributes"]["title"],
+ "url": news["links"]["canonical"],
+ }
+ )
+
+ return news_to_display
diff --git a/gamestonk_terminal/stocks/discovery/seeking_alpha_view.py b/gamestonk_terminal/stocks/discovery/seeking_alpha_view.py
index eb492ab8766..ffd367848b3 100644
--- a/gamestonk_terminal/stocks/discovery/seeking_alpha_view.py
+++ b/gamestonk_terminal/stocks/discovery/seeking_alpha_view.py
@@ -1,6 +1,7 @@
""" Seeking Alpha View """
__docformat__ = "numpy"
+from typing import List
import os
from datetime import datetime
from tabulate import tabulate
@@ -149,3 +150,41 @@ def news(news_type: str, article_id: int, num: int, start_date: datetime, export
news_type,
df_articles,
)
+
+
+def display_news(news_type: str = "Top-News", num: int = 5, export: str = ""):
+ """Display news. [Source: SeekingAlpha]
+
+ Parameters
+ ----------
+ news_type : str
+ From: Top-News, On-The-Move, Market-Pulse, Notable-Calls, Buybacks, Commodities, Crypto, Issuance, Global,
+ Guidance, IPOs, SPACs, Politics, M-A, Consumer, Energy, Financials, Healthcare, MLPs, REITs, Technology
+ num : int
+ Number of news to display
+ export : str
+ Export dataframe data to csv,json,xlsx file
+ """
+ news_to_display: List = seeking_alpha_model.get_news(news_type, num)
+
+ if not news:
+ print("No news found.", "\n")
+
+ else:
+ for news_element in news_to_display:
+ print(
+ news_element["publishOn"]
+ + " - "
+ + news_element["id"]
+ + " - "
+ + news_element["title"]
+ )
+ print(news_element["url"])
+ print("")
+
+ export_data(
+ export,
+ os.path.dirname(os.path.abspath(__file__)),
+ "cnews : " + news_type,
+ pd.DataFrame(news_to_display),
+ )
diff --git a/website/content/stocks/discovery/cnews/_index.md b/website/content/stocks/discovery/cnews/_index.md
new file mode 100755
index 00000000000..17a2e919e9f
--- /dev/null
+++ b/website/content/stocks/discovery/cnews/_index.md
@@ -0,0 +1,16 @@
+```
+usage: cnews [-t {top-news,on-the-move,market-pulse,notable-calls,buybacks,commodities,crypto,issuance,global,guidance,ipos,spacs,politics,m-a,consumer,energy,financials,healthcare,mlps,reits,technology}] [-n N_NUM] [--export {csv,json,xlsx}] [-h]
+```
+
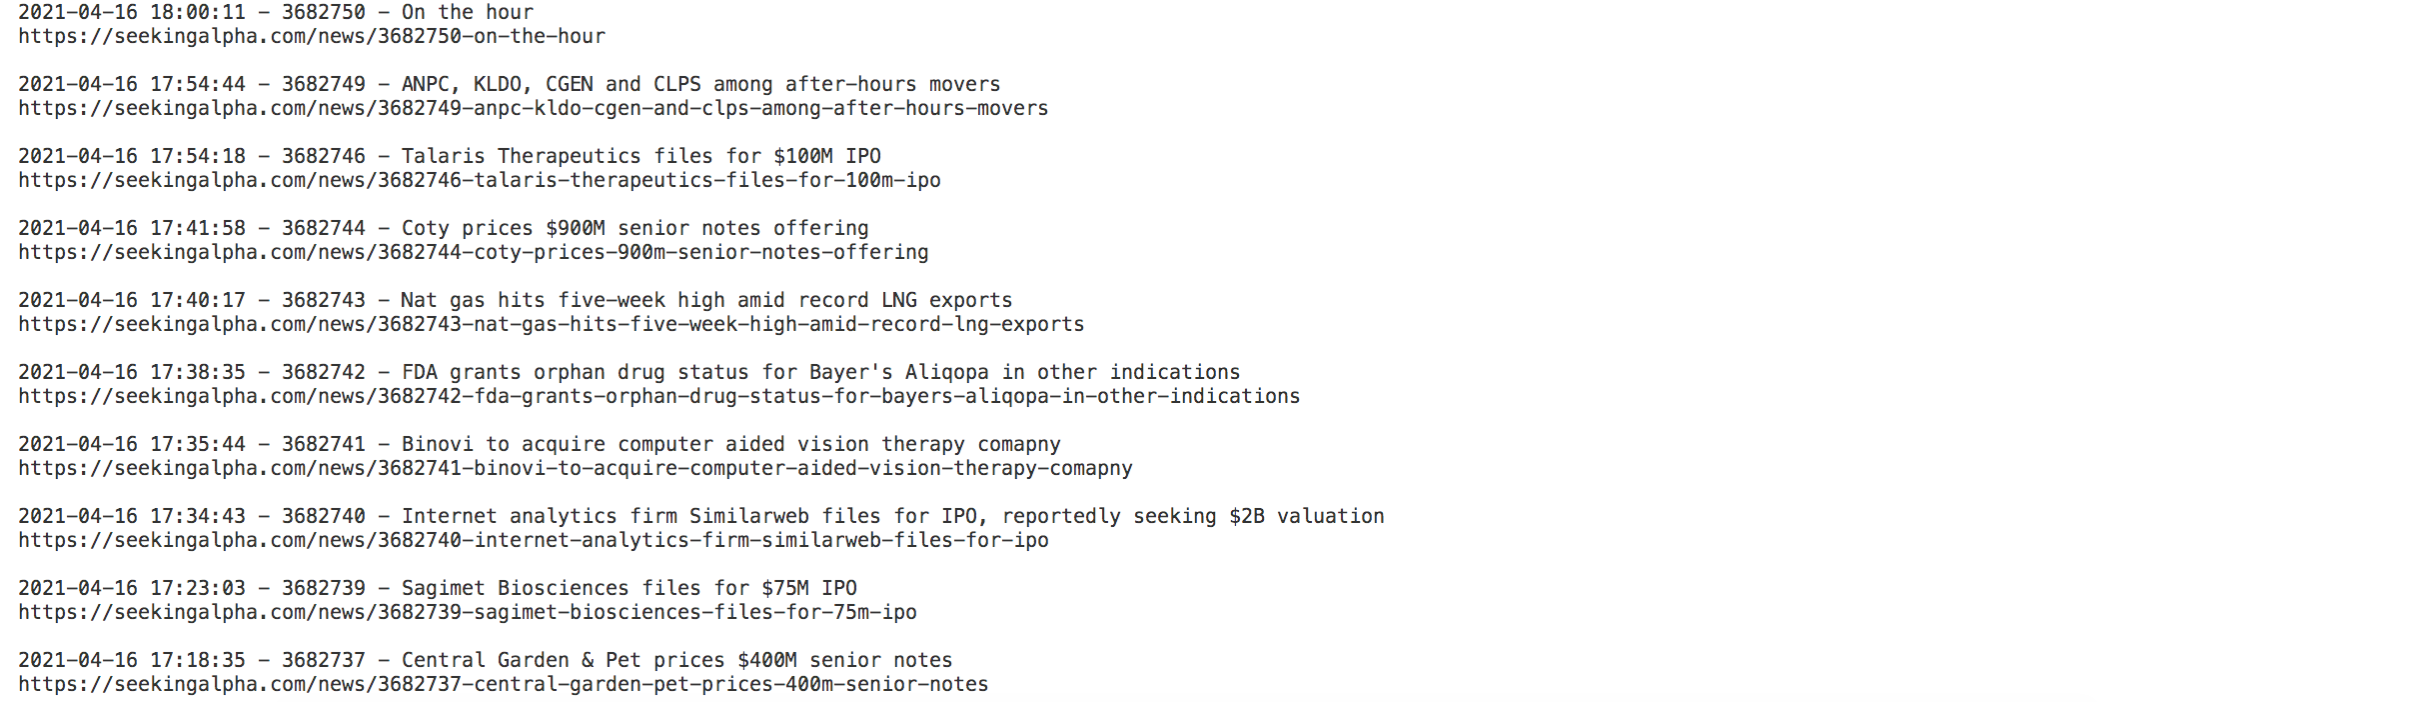
+Customized news. [Source: Seeking Alpha]
+
+```
+optional arguments:
+ -t {top-news,on-the-move,market-pulse,notable-calls,buybacks,commodities,crypto,issuance,global,guidance,ipos,spacs,politics,m-a,consumer,energy,financials,healthcare,mlps,reits,technology}, --type {top-news,on-the-move,market-pulse,notable-calls,buybacks,commodities,crypto,issuance,global,guidance,ipos,spacs,politics,m-a,consumer,energy,financials,healthcare,mlps,reits,technology}
+ number of news to display (default: Top-News)
+ -n N_NUM, --num N_NUM
+ number of news to display (default: 5)
+ --export {csv,json,xlsx}
+ Export dataframe data to csv,json,xlsx file (default: )
+ -h, --help show this help message (default: False)
+```
diff --git a/website/content/stocks/discovery/latest/_index.md b/website/content/stocks/discovery/latest/_index.md
deleted file mode 100755
index 25684e969a7..00000000000
--- a/website/content/stocks/discovery/latest/_index.md
+++ /dev/null
@@ -1,19 +0,0 @@
-```
-usage: latest [-i N_ID] [-n N_NUM] [-d S_DATE] [--export {csv,json,xlsx}] [-h]
-```
-
-Latest news articles. [Source: Seeking Alpha]
-
-```
-optional arguments:
- -i N_ID, --id N_ID article ID (default: -1)
- -n N_NUM, --num N_NUM
- number of articles being printed (default: 5)
- -d S_DATE, --date S_DATE
- starting date of articles (default: 2021-09-16)
- --export {csv,json,xlsx}
- Export dataframe data to csv,json,xlsx file (default: )
- -h, --help show this help message (default: False)
-```
-
-
 diff --git a/website/data/menu/main.yml b/website/data/menu/main.yml
index ed99f72be7a..114759aad41 100755
--- a/website/data/menu/main.yml
+++ b/website/data/menu/main.yml
@@ -40,8 +40,8 @@ main:
ref: "/stocks/discovery/arkord"
- name: upcoming
ref: "/stocks/discovery/upcoming"
- - name: latest
- ref: "/stocks/discovery/latest"
+ - name: cnews
+ ref: "/stocks/discovery/cnews"
- name: trending
ref: "/stocks/discovery/trending"
- name: lowfloat