mirror of
https://github.com/block/buzz.git
synced 2026-11-13 21:01:53 +00:00
 41587e0284
Message Markdown on mobile moves from gpt_markdown 1.2.1's legacy regex
pipeline to the CommonMark parser that 1.3 added ("plusparse"). Before
this, passing `inlineComponents` (now deprecated, removed in 2.0.0) kept
every message on the legacy pipeline.
### What changes for users
Rendering moves closer to desktop (react-markdown + remark-gfm):
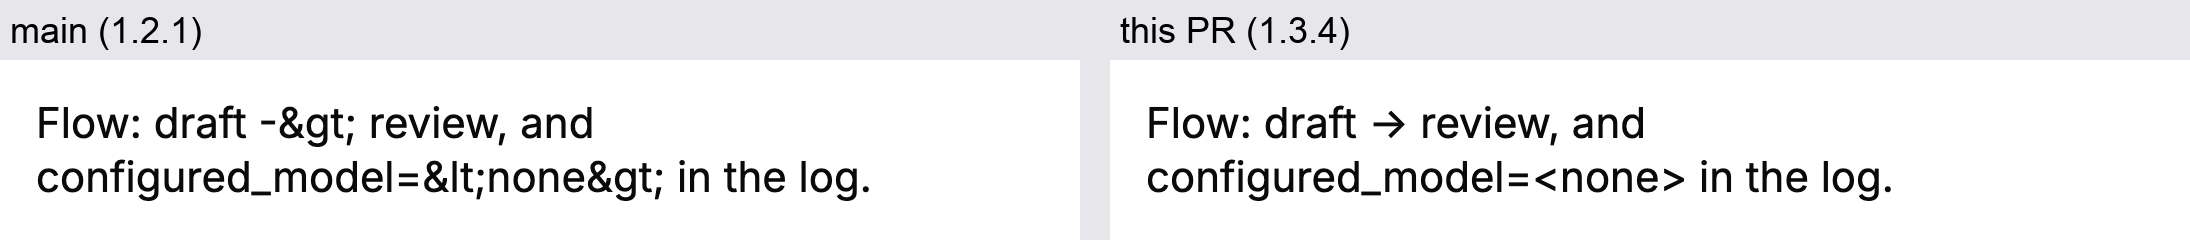
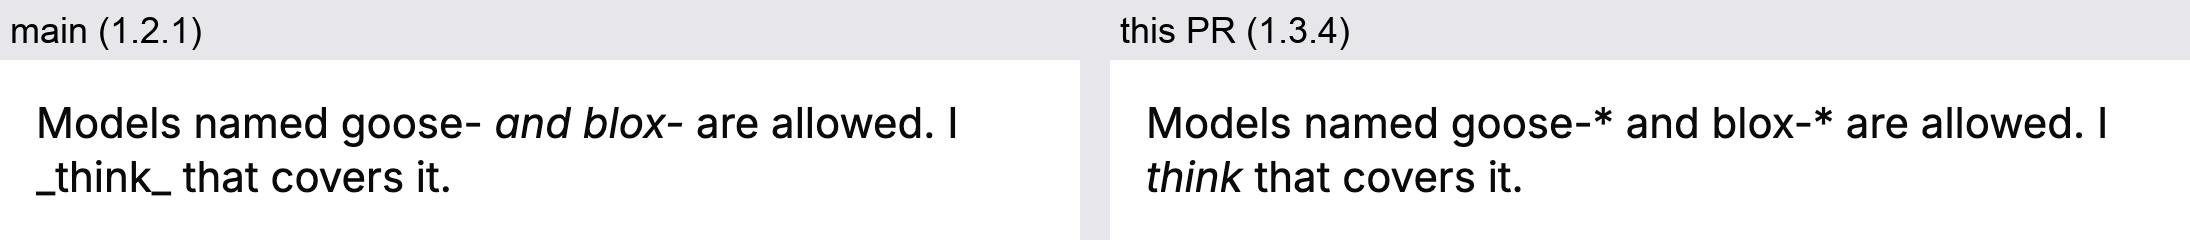
- `_italic_` and `__bold__` work, backslash escapes and HTML entities
decode, and `[a [b] c](url)` labels are correct.
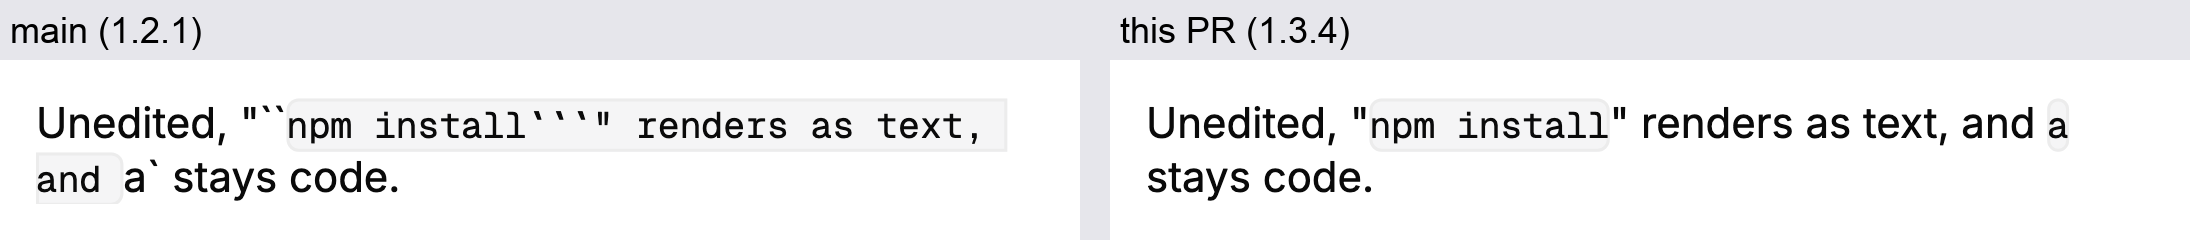
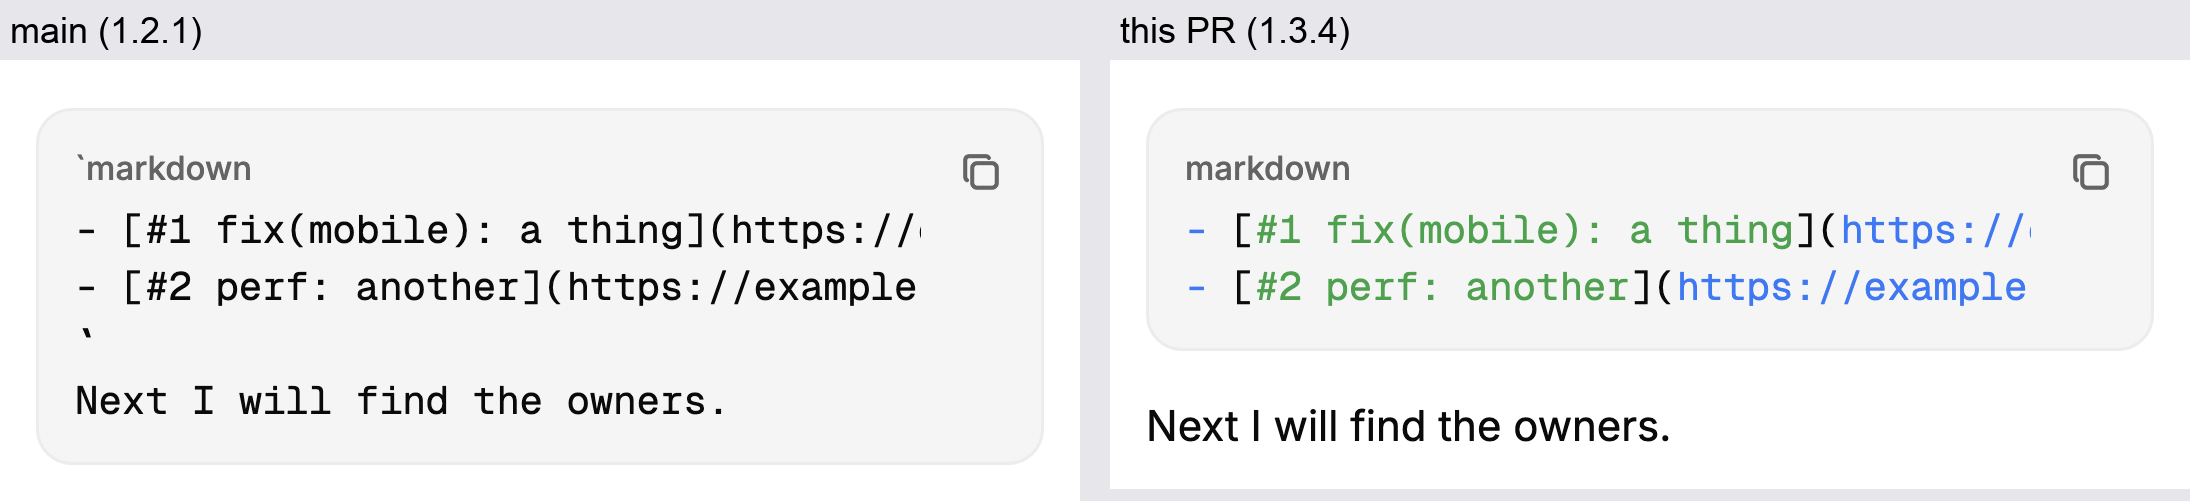
- Inline code follows CommonMark pairing: `"```npm install```"` in a
sentence is inline code, and four-backtick fences work.
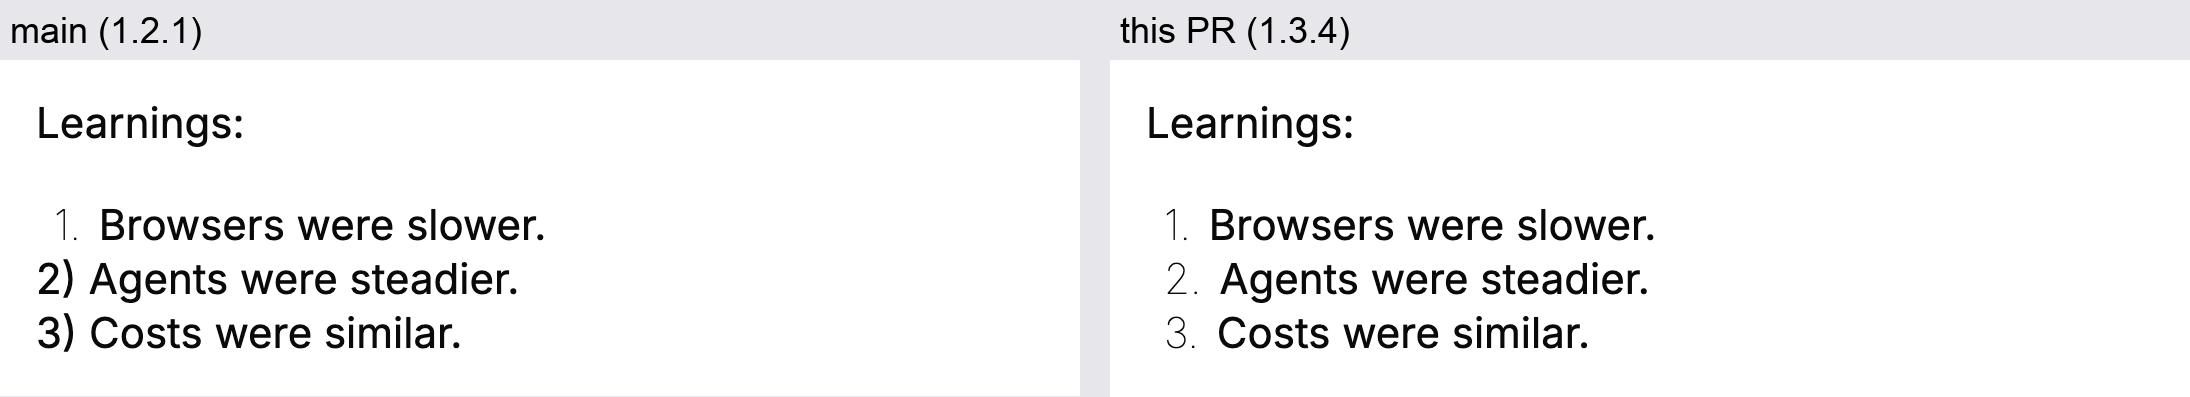
- Setext headings, reference links, footnotes, `~~~` fences, `1)` lists
and CommonMark list/quote continuation render.
- HTML comments are hidden, as on desktop.
- `\[`, `\]`, `\(` and `\)` stay literal, as on desktop. Plusparse
hard-codes them as LaTeX delimiters, so they're written as entities
before rendering.
- Side effect: an unfenced `__init__` now renders as bold "init", and a
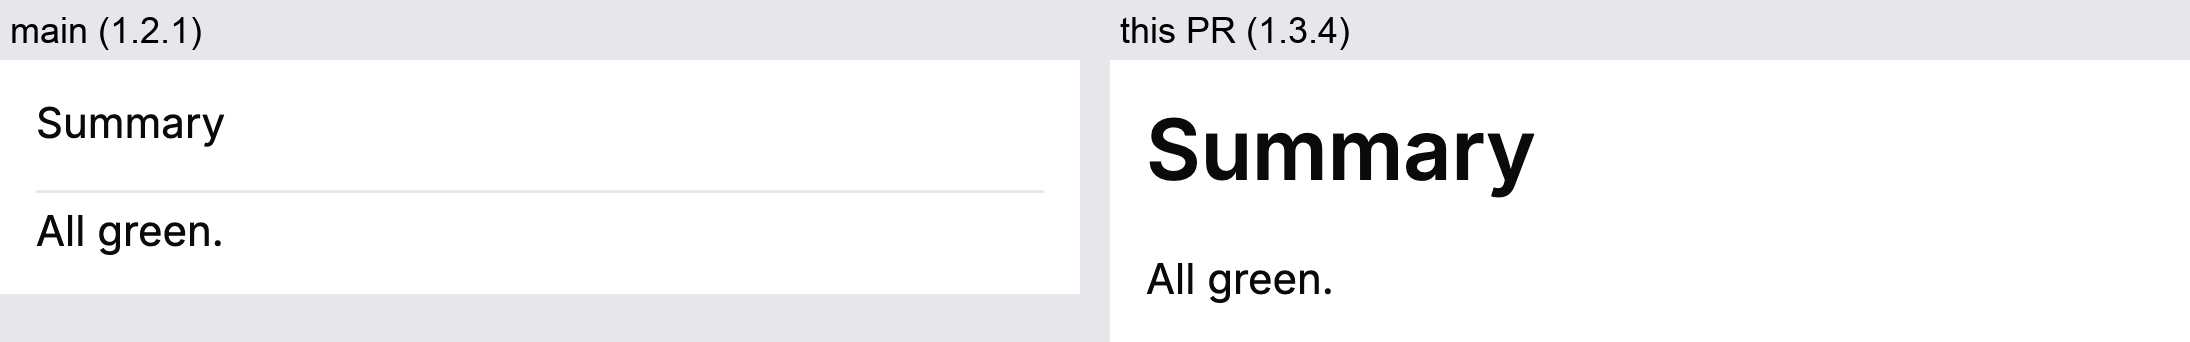
line over `---` becomes a heading, same as desktop.
Device benchmark (iPhone SE, profile build, 600 synthetic messages, 3
launches per build): scrolling spends 9% less time building, and frames
with more than 8 ms of build drop from 63 to 22. Jumping onto unbuilt
messages is 11% cheaper, and raster time is unchanged.
App size: the release app grows about 4.6 MB uncompressed (80.6 to 85.2
MB), mostly Dart code from the new math and highlighting packages.
### Before and after
Synthetic messages that reproduce differences found in real channel
history, rendered through `MessageContent` on main and on this branch:


### Demo
A scroll through synthetic messages covering common formatting
(headings, lists, quotes, links, highlighted code, a table, a task list,
escapes), recorded on an iPhone 17 Pro simulator running this branch:
https://github.com/user-attachments/assets/bdc9680c-d20b-41ec-8e1a-a5b51c602f9d
### How
- Mentions, custom emoji and `#channel` tokens are `InlinePattern`s.
Links go through `inlineLinkBuilder` into the existing `_buildLink`, so
chips, media links and taps are unchanged.
- Removed workarounds the parser makes unnecessary:
- the render-path escape shielding from #8925
- the `_MarkdownEscapeMd`, `_MarkdownLabelEntityMd` and `_MessageLinkMd`
components
- the zero-width prefix before a leading `#channel`
Plain-text previews and gallery helpers keep their own escape handling.
`normalizeBareLinks` stays because attachment and gallery detection
depend on its output. Bubble segmentation unescapes a link destination
itself before its imeta lookup, since content no longer arrives
shielded.
- Kept desktop parity where plusparse differs from GFM:
- a table typed directly under a caption line gets a blank line inserted
before it, since plusparse can't start a table mid-paragraph
- `> [!NOTE]` quotes render as quotes (`alertBuilder` returns
`asBlockQuote()`), since desktop has no alerts
- `mapMarkdownProse` now ends an unclosed backtick run at its paragraph.
Before, it could pair with a run in a later block and flip code and
prose for the rest of the message.
- Synthesized autolink labels escape backslashes instead of using
`\`, which the parser leaves undecoded in a URL-shaped label.
- Repo/PR/issue chips keep their own semantics node.
- Forum card previews clip at their 120 px cap instead of overflowing:
blocks now lay out as a column.
- Pinned to exactly 1.3.4. 1.4.0 renders HTML by default and themes
through the separate `material_ui` package, which would need a theme
bridge.
### Validation
- Full mobile suite passes and analyze is clean at 78b9c1a6d0.
- All of #8925's and #8940's backslash-escape cases pass on the new
parser, including the strike-across-lines case that used to be a known
limitation.
- Real-message diff: 2,259 recent messages from 13 busy channels,
rendered through `MessageContent` on main and on this branch. 29
differed in text or styling. On inline and fenced code, the branch
matched desktop's parser (remark-gfm) in 23 of them and main in 7. The
review found the three parity gaps above, now fixed. The rest are
CommonMark behavior that desktop shares.
- Added tests, each confirmed to fail without its fix:
- a leading `#channel` renders as a link, not a heading
- a table under its caption renders as a table
- an alert-marker quote stays a quote
- an unclosed backtick run doesn't flip later code
- the transcript tests detect a rendered link by its style; the old
`LinkButton` check passed even with autolink on
- Automated simulator run (iPhone 17 Pro, iOS 27, debug build, signed in
to a Builderlab community): channel list, two channels with history
scrolled back several pages (mentions, link previews, thread summaries,
images), an agent Solo chat with long agent messages, and the inbox. No
rendering errors or layout breaks; the Solo chat screen also matched
main's build side by side.
🤖 Generated with [Claude Code](https://claude.com/claude-code)
---------
Signed-off-by: Tom Brow <tomb@squareup.com>
Co-authored-by: Tom Brow <tomb@squareup.com>
Co-authored-by: studio <dc2fc481343672df31a689840c09299972e704dac592e0da6f18486646a7ee3e@buzz.block.builderlab.xyz>
Co-authored-by: Claude Opus 5.5 <noreply@anthropic.com>








568 lines
20 KiB
Dart
568 lines
20 KiB
Dart
/// Escapes destination characters that the mobile Markdown renderer treats as
|
|
/// syntax. Apply the same conversion to metadata keys to preserve media types.
|
|
String normalizeMarkdownDestination(String url) =>
|
|
url.replaceAll(' ', '%20').replaceAll('(', '%28').replaceAll(')', '%29');
|
|
|
|
const _backslashUnit = 0x5C;
|
|
const _markdownDelimiters = ['***', '___', '**', '__', '~~', '*', '_'];
|
|
|
|
final _autolinkPattern = RegExp(
|
|
r'<((?:https?://|buzz://(?:message\?|join\?|channel/|(?:pr|issue|repo)\?))[^>]+)>',
|
|
);
|
|
final _bareLinkPattern = RegExp(
|
|
r'(?<![(\]=])(?:https?://|buzz://(?:message\?|join\?|channel/|(?:pr|issue|repo)\?))[^\s)>\]]+',
|
|
);
|
|
final _trailingPunctuationPattern = RegExp(r'[.,!?:;]+$');
|
|
final _backtickRunPattern = RegExp(r'`+');
|
|
final _codeRunPattern = RegExp(r'`+|~{3,}');
|
|
|
|
/// Converts supported Buzz and HTTP(S) autolinks and bare links into Markdown
|
|
/// links while leaving inline and fenced code and link reference definitions
|
|
/// untouched. Punctuation peeling is limited to Buzz URLs so existing HTTP(S)
|
|
/// destinations stay unchanged.
|
|
String normalizeBareLinks(String content) {
|
|
final definitions = _DefinitionScan(content);
|
|
return _mapMarkdownProseAt(content, definitions.normalize);
|
|
}
|
|
|
|
// A link reference definition line, `[label]: destination`. Wrapping its
|
|
// destination in a Markdown link would make the wrapped text the destination.
|
|
// A definition cannot interrupt a paragraph, so it counts only at a block
|
|
// start: the first line, after a blank line, or after another definition.
|
|
final _definitionLine = RegExp(
|
|
r'^ {0,3}\[[^\]\n]+\]:[ \t]*\S.*$',
|
|
multiLine: true,
|
|
);
|
|
|
|
/// Finds the link reference definitions in one message, in order, in time
|
|
/// linear in its length. A definition cannot interrupt a paragraph, so a
|
|
/// definition line counts only when the line above it is absent, blank, or
|
|
/// itself a counted definition. That last answer is remembered, so a run of
|
|
/// definitions is never rescanned.
|
|
class _DefinitionScan {
|
|
_DefinitionScan(this.content);
|
|
|
|
final String content;
|
|
// Content offset where the last definition-shaped source line ended, and
|
|
// whether it counted.
|
|
int _lastEnd = -2;
|
|
bool _lastCounted = false;
|
|
|
|
/// [prose], the run of [content] at [start], with bare links normalized
|
|
/// outside the definitions that count.
|
|
String normalize(String prose, int start) {
|
|
final result = StringBuffer();
|
|
var offset = 0;
|
|
for (final line in _definitionLine.allMatches(prose)) {
|
|
if (!_counts(start + line.start)) continue;
|
|
result
|
|
..write(_normalizeLinkSegment(prose.substring(offset, line.start)))
|
|
..write(line[0]);
|
|
offset = line.end;
|
|
}
|
|
result.write(_normalizeLinkSegment(prose.substring(offset)));
|
|
return result.toString();
|
|
}
|
|
|
|
bool _counts(int index) {
|
|
// A candidate mid-line, after code, is not a definition and leaves the
|
|
// memo for the line it sits on alone.
|
|
if (index > 0 && content[index - 1] != '\n') return false;
|
|
final bool counted;
|
|
if (index == _lastEnd + 1) {
|
|
counted = _lastCounted;
|
|
} else {
|
|
final previousEnd = index - 1;
|
|
final previousStart = previousEnd <= 0
|
|
? 0
|
|
: content.lastIndexOf('\n', previousEnd - 1) + 1;
|
|
counted =
|
|
index == 0 ||
|
|
content.substring(previousStart, previousEnd).trim().isEmpty;
|
|
}
|
|
// The source line's end: a definition's title may hold code, which ends
|
|
// this prose run early.
|
|
final lineEnd = content.indexOf('\n', index);
|
|
_lastEnd = lineEnd < 0 ? content.length : lineEnd;
|
|
_lastCounted = counted;
|
|
return counted;
|
|
}
|
|
}
|
|
|
|
/// Applies [transform] to each run of [content] outside inline and fenced
|
|
/// code, leaving code untouched. Fences may use backticks or tildes.
|
|
String mapMarkdownProse(String content, String Function(String) transform) =>
|
|
_mapMarkdownProseAt(content, (prose, _) => transform(prose));
|
|
|
|
/// [mapMarkdownProse], with each run's start offset in [content].
|
|
String _mapMarkdownProseAt(
|
|
String content,
|
|
String Function(String prose, int start) transform,
|
|
) {
|
|
final buffer = StringBuffer();
|
|
var offset = 0;
|
|
var proseStart = 0;
|
|
var codeStart = 0;
|
|
var inlineDelimiterLength = 0;
|
|
var fenceDelimiterLength = 0;
|
|
var fenceChar = '';
|
|
var fenceQuoteDepth = 0;
|
|
// The paragraph end found for the last unpaired opener, reused while later
|
|
// openers at the same quote depth sit before it, so a long paragraph is
|
|
// walked once rather than once per opener.
|
|
var paragraphEnd = -1;
|
|
var paragraphDepth = -1;
|
|
|
|
while (offset < content.length) {
|
|
// A fence opened inside a quote ends with that quote, closed or not.
|
|
if (fenceDelimiterLength > 0 &&
|
|
fenceQuoteDepth > 0 &&
|
|
content[offset] == '\n' &&
|
|
_lineQuoteDepth(content, offset + 1) < fenceQuoteDepth) {
|
|
buffer.write(content.substring(codeStart, offset));
|
|
fenceDelimiterLength = 0;
|
|
proseStart = offset;
|
|
}
|
|
final run = _codeRunPattern.matchAsPrefix(content, offset);
|
|
if (run == null) {
|
|
offset++;
|
|
continue;
|
|
}
|
|
|
|
final runLength = run.end - run.start;
|
|
final runChar = content[run.start];
|
|
if (fenceDelimiterLength > 0) {
|
|
if (runChar == fenceChar &&
|
|
_isClosingFence(
|
|
content,
|
|
run.start,
|
|
run.end,
|
|
fenceDelimiterLength,
|
|
fenceQuoteDepth,
|
|
)) {
|
|
buffer.write(content.substring(codeStart, run.end));
|
|
fenceDelimiterLength = 0;
|
|
proseStart = run.end;
|
|
}
|
|
} else if (inlineDelimiterLength > 0) {
|
|
if (runChar == '`' && runLength == inlineDelimiterLength) {
|
|
buffer.write(content.substring(codeStart, run.end));
|
|
inlineDelimiterLength = 0;
|
|
proseStart = run.end;
|
|
}
|
|
} else if (runChar == '~') {
|
|
// Tildes only fence code; shorter runs are strikethrough.
|
|
if (_isOpeningFence(content, run.start, runLength)) {
|
|
buffer.write(
|
|
transform(content.substring(proseStart, run.start), proseStart),
|
|
);
|
|
codeStart = run.start;
|
|
fenceDelimiterLength = runLength;
|
|
fenceChar = runChar;
|
|
fenceQuoteDepth = _fenceQuoteDepth(content, run.start);
|
|
}
|
|
} else if (_isEscaped(content, run.start)) {
|
|
// An escaped backtick is literal; the rest of its run may still open.
|
|
offset = run.start + 1;
|
|
continue;
|
|
} else if (_hasInlineCloserOnLine(content, run.end, runLength) ||
|
|
(!_isOpeningFence(content, run.start, runLength) &&
|
|
_hasInlineCloser(content, run.end, runLength, () {
|
|
final depth = _lineQuoteDepth(
|
|
content,
|
|
content.lastIndexOf('\n', run.start) + 1,
|
|
);
|
|
if (run.end >= paragraphEnd || depth != paragraphDepth) {
|
|
paragraphEnd = _paragraphEnd(content, run.end, depth);
|
|
paragraphDepth = depth;
|
|
}
|
|
return paragraphEnd;
|
|
}))) {
|
|
buffer.write(
|
|
transform(content.substring(proseStart, run.start), proseStart),
|
|
);
|
|
codeStart = run.start;
|
|
inlineDelimiterLength = runLength;
|
|
} else if (_isOpeningFence(content, run.start, runLength)) {
|
|
buffer.write(
|
|
transform(content.substring(proseStart, run.start), proseStart),
|
|
);
|
|
codeStart = run.start;
|
|
fenceDelimiterLength = runLength;
|
|
fenceChar = runChar;
|
|
fenceQuoteDepth = _fenceQuoteDepth(content, run.start);
|
|
}
|
|
|
|
offset = run.end;
|
|
}
|
|
|
|
if (inlineDelimiterLength > 0 || fenceDelimiterLength > 0) {
|
|
buffer.write(content.substring(codeStart));
|
|
} else {
|
|
buffer.write(transform(content.substring(proseStart), proseStart));
|
|
}
|
|
return buffer.toString();
|
|
}
|
|
|
|
/// Whether an odd number of backslashes precedes [index].
|
|
bool _isEscaped(String content, int index) {
|
|
var backslashes = 0;
|
|
while (index - backslashes > 0 && content[index - backslashes - 1] == r'\') {
|
|
backslashes++;
|
|
}
|
|
return backslashes.isOdd;
|
|
}
|
|
|
|
bool _isOpeningFence(String content, int runStart, int runLength) =>
|
|
runLength >= 3 && _fenceQuoteDepth(content, runStart) >= 0;
|
|
|
|
bool _isClosingFence(
|
|
String content,
|
|
int runStart,
|
|
int runEnd,
|
|
int openerLength,
|
|
int openerQuoteDepth,
|
|
) {
|
|
if (runEnd - runStart < openerLength) return false;
|
|
// A fence closes only at the quote depth it opened at.
|
|
if (_fenceQuoteDepth(content, runStart) != openerQuoteDepth) return false;
|
|
// Stops at the first non-blank character, so each run scans only up to
|
|
// the next one and a long line of runs stays linear.
|
|
for (var i = runEnd; i < content.length; i++) {
|
|
final char = content[i];
|
|
if (char == '\n') return true;
|
|
if (char.trim().isNotEmpty) return false;
|
|
}
|
|
return true;
|
|
}
|
|
|
|
/// The number of quote markers (`>`) before [runStart] on its line when only
|
|
/// blanks and markers precede it, or -1 when anything else does. This matches
|
|
/// where the renderer opens a fence: gpt_markdown re-parses quote bodies, and
|
|
/// list continuations are indented. The scan stops at the first other
|
|
/// character, so it never crosses an earlier run and a long line of runs
|
|
/// stays linear.
|
|
int _fenceQuoteDepth(String content, int runStart) {
|
|
var depth = 0;
|
|
for (var i = runStart - 1; i >= 0; i--) {
|
|
final char = content[i];
|
|
if (char == '\n') return depth;
|
|
if (char == '>') {
|
|
depth++;
|
|
} else if (char.trim().isNotEmpty) {
|
|
return -1;
|
|
}
|
|
}
|
|
return depth;
|
|
}
|
|
|
|
/// The number of quote markers (`>`) in the blank-and-marker prefix of the
|
|
/// line starting at [lineStart].
|
|
int _lineQuoteDepth(String content, int lineStart) {
|
|
var depth = 0;
|
|
for (var i = lineStart; i < content.length; i++) {
|
|
final char = content[i];
|
|
if (char == '>') {
|
|
depth++;
|
|
} else if (char == '\n' || char.trim().isNotEmpty) {
|
|
break;
|
|
}
|
|
}
|
|
return depth;
|
|
}
|
|
|
|
bool _hasInlineCloserOnLine(String content, int start, int delimiterLength) {
|
|
final newline = content.indexOf('\n', start);
|
|
final lineEnd = newline < 0 ? content.length : newline;
|
|
for (final run in _backtickRunPattern.allMatches(content, start)) {
|
|
if (run.start >= lineEnd) return false;
|
|
if (run.end - run.start == delimiterLength) return true;
|
|
}
|
|
return false;
|
|
}
|
|
|
|
/// Whether a closing run follows before the paragraph ends: a code span
|
|
/// cannot continue past a blank line, a list item, heading, fence or a deeper
|
|
/// block quote. [paragraphEnd] is asked only when no closer is near.
|
|
bool _hasInlineCloser(
|
|
String content,
|
|
int start,
|
|
int delimiterLength,
|
|
int Function() paragraphEnd,
|
|
) {
|
|
int? end;
|
|
for (final run in _backtickRunPattern.allMatches(content, start)) {
|
|
if (run.start >= (end ??= paragraphEnd())) return false;
|
|
if (run.end - run.start == delimiterLength) return true;
|
|
}
|
|
return false;
|
|
}
|
|
|
|
/// Where the paragraph containing [start] ends, for a line at quote depth
|
|
/// [openerDepth]. A block quote can interrupt a paragraph, so a line opening a
|
|
/// deeper quote ends it. Equal or shallower markers continue it, as in a
|
|
/// multi-line code span inside a quote.
|
|
int _paragraphEnd(String content, int start, int openerDepth) {
|
|
var newline = content.indexOf('\n', start);
|
|
while (newline >= 0) {
|
|
if (_lineQuoteDepth(content, newline + 1) > openerDepth ||
|
|
_paragraphBreak.matchAsPrefix(content, newline + 1) != null) {
|
|
return newline;
|
|
}
|
|
newline = content.indexOf('\n', newline + 1);
|
|
}
|
|
return content.length;
|
|
}
|
|
|
|
final _paragraphBreak = RegExp(
|
|
r'[ \t]*(?:$|[-*+][ \t]|\d{1,9}[.)][ \t]|#{1,6}(?:[ \t]|$)|`{3}|~{3})',
|
|
multiLine: true,
|
|
);
|
|
|
|
// Numeric entities keep literal label punctuation out of the line-based
|
|
// attachment, gallery and preview matchers, which do not balance brackets.
|
|
// The renderer decodes them.
|
|
String _normalizeMarkdownLabel(String label) => label.replaceAllMapped(
|
|
RegExp(r'\\([\\\[\]])|[\[\]]'),
|
|
(match) => '&#${(match[1] ?? match[0]!).codeUnitAt(0)};',
|
|
);
|
|
|
|
/// Restores the literal punctuation encoded for Markdown attachment labels.
|
|
String decodeMarkdownLabelSyntax(String label) => label.replaceAllMapped(
|
|
RegExp(r'&#(91|92|93);'),
|
|
(match) => String.fromCharCode(int.parse(match[1]!)),
|
|
);
|
|
|
|
// Scan each label character once, treating escaped brackets as label text.
|
|
// Nested brackets are balanced without restarting at every opening bracket.
|
|
({int start, int end})? _findMarkdownLinkStart(String segment, int offset) {
|
|
final openers = <int>[];
|
|
for (var cursor = offset; cursor < segment.length; cursor++) {
|
|
final char = segment[cursor];
|
|
if (char == r'\' &&
|
|
cursor + 1 < segment.length &&
|
|
segment[cursor + 1] != '\n') {
|
|
cursor++;
|
|
continue;
|
|
}
|
|
if (char == '\n') {
|
|
openers.clear();
|
|
} else if (char == '[') {
|
|
openers.add(cursor);
|
|
} else if (char == ']' && openers.isNotEmpty) {
|
|
final opener = openers.removeLast();
|
|
// A destination belongs to this matching opener even if an earlier
|
|
// prose bracket never closed. Inner label brackets without a destination
|
|
// still balance normally, preserving true nested labels.
|
|
if (cursor + 1 < segment.length && segment[cursor + 1] == '(') {
|
|
final start = opener > 0 && segment[opener - 1] == '!'
|
|
? opener - 1
|
|
: opener;
|
|
return (start: start, end: cursor + 2);
|
|
}
|
|
}
|
|
}
|
|
return null;
|
|
}
|
|
|
|
String _normalizeLinkSegment(String segment) {
|
|
final result = StringBuffer();
|
|
var offset = 0;
|
|
while (offset < segment.length) {
|
|
final match = _findMarkdownLinkStart(segment, offset);
|
|
if (match == null) break;
|
|
var cursor = match.end;
|
|
if (cursor >= segment.length) break;
|
|
final angled = segment[cursor] == '<';
|
|
final start = angled ? ++cursor : cursor;
|
|
var depth = 0;
|
|
while (cursor < segment.length) {
|
|
final char = segment[cursor];
|
|
if (angled) {
|
|
if (char == '>' || char == '\n' || char == '<') break;
|
|
} else {
|
|
if (char.trim().isEmpty) break;
|
|
if (char == '(') depth++;
|
|
if (char == ')') {
|
|
if (depth == 0) break;
|
|
depth--;
|
|
}
|
|
}
|
|
cursor++;
|
|
}
|
|
final destinationEnd = cursor;
|
|
var valid = cursor > start && cursor < segment.length;
|
|
if (angled && valid) {
|
|
valid = segment[cursor] == '>';
|
|
if (valid) cursor++;
|
|
}
|
|
if (valid) {
|
|
// gpt_markdown has no title parameter. Consume all Markdown title
|
|
// delimiters and escaped delimiters before removing the title.
|
|
final suffix = _scanLinkSuffix(segment, cursor);
|
|
cursor = suffix.end;
|
|
valid = suffix.valid;
|
|
}
|
|
result.write(_normalizeProseLinks(segment.substring(offset, match.start)));
|
|
if (valid) {
|
|
final destination = segment.substring(start, destinationEnd);
|
|
final image = segment[match.start] == '!';
|
|
final labelStart = match.start + (image ? 2 : 1);
|
|
final label = _normalizeMarkdownLabel(
|
|
segment.substring(labelStart, match.end - 2),
|
|
);
|
|
result.write(
|
|
'${image ? '!' : ''}[$label](${normalizeMarkdownDestination(destination)})',
|
|
);
|
|
} else {
|
|
// Preserve malformed source, and never scan its inspected suffix again.
|
|
// This cursor advances on failure as well as success, bounding work even
|
|
// for a relay-sized message made entirely of unterminated link openers.
|
|
result.write(segment.substring(match.start, cursor));
|
|
}
|
|
offset = cursor;
|
|
}
|
|
result.write(_normalizeProseLinks(segment.substring(offset)));
|
|
return result.toString();
|
|
}
|
|
|
|
({int end, bool valid}) _scanLinkSuffix(String segment, int cursor) {
|
|
final start = cursor;
|
|
while (cursor < segment.length && segment[cursor].trim().isEmpty) {
|
|
cursor++;
|
|
}
|
|
if (cursor < segment.length && segment[cursor] == ')') {
|
|
return (end: cursor + 1, valid: true);
|
|
}
|
|
if (cursor == start || cursor == segment.length) {
|
|
return (end: cursor, valid: false);
|
|
}
|
|
final opener = segment[cursor];
|
|
if (opener != '"' && opener != "'" && opener != '(') {
|
|
return (end: cursor, valid: false);
|
|
}
|
|
final closer = opener == '(' ? ')' : opener;
|
|
cursor++;
|
|
while (cursor < segment.length) {
|
|
final char = segment[cursor++];
|
|
if (char == r'\' && cursor < segment.length) {
|
|
cursor++;
|
|
} else if (char == closer) {
|
|
while (cursor < segment.length && segment[cursor].trim().isEmpty) {
|
|
cursor++;
|
|
}
|
|
if (cursor < segment.length && segment[cursor] == ')') {
|
|
return (end: cursor + 1, valid: true);
|
|
}
|
|
return (end: cursor, valid: false);
|
|
} else if (opener == '(' && char == '(') {
|
|
return (end: cursor, valid: false);
|
|
}
|
|
}
|
|
return (end: cursor, valid: false);
|
|
}
|
|
|
|
String _normalizeProseLinks(String segment) {
|
|
// An escaped `\<` is literal, not an autolink; its URL stays a bare link.
|
|
var normalized = segment.replaceAllMapped(
|
|
_autolinkPattern,
|
|
(match) =>
|
|
_isEscaped(segment, match.start) ? match[0]! : _autolink(match[1]!),
|
|
);
|
|
normalized = normalized.replaceAllMapped(
|
|
_bareLinkPattern,
|
|
(match) => _normalizeBareLink(normalized, match),
|
|
);
|
|
return normalized;
|
|
}
|
|
|
|
// An autolink keeps its backslashes literally. Escape them so none is read
|
|
// as an escape of the synthesized `]` or `)`. A numeric entity would show
|
|
// verbatim: gpt_markdown leaves a URL-shaped label undecoded.
|
|
String _autolink(String url) =>
|
|
'[${url.replaceAll(r'\', r'\\')}](${url.replaceAll(r'\', '%5C')})';
|
|
|
|
String _normalizeBareLink(String segment, Match match) {
|
|
final matched = match[0]!;
|
|
var url = matched;
|
|
var trailing = '';
|
|
final isBuzzUrl = matched.startsWith('buzz://');
|
|
final start = match.start;
|
|
|
|
// A trailing backslash escapes what follows or breaks the line; it is never
|
|
// part of the destination, and the renderer would read it as an escape.
|
|
// Peel it again whenever stripping punctuation or a delimiter exposes one.
|
|
// Scan back rather than match `\\+$`, which retries from every offset.
|
|
void peelBackslashes() {
|
|
var urlEnd = url.length;
|
|
while (urlEnd > 0 && url.codeUnitAt(urlEnd - 1) == _backslashUnit) {
|
|
urlEnd--;
|
|
}
|
|
trailing = '${url.substring(urlEnd)}$trailing';
|
|
url = url.substring(0, urlEnd);
|
|
}
|
|
|
|
peelBackslashes();
|
|
if (isBuzzUrl) {
|
|
final outsidePunctuation = _trailingPunctuationPattern.firstMatch(url);
|
|
if (outsidePunctuation != null) {
|
|
url = url.substring(0, outsidePunctuation.start);
|
|
trailing = '${outsidePunctuation[0]}$trailing';
|
|
}
|
|
}
|
|
|
|
var strippedDelimiter = true;
|
|
while (strippedDelimiter) {
|
|
strippedDelimiter = false;
|
|
peelBackslashes();
|
|
for (final delimiter in _markdownDelimiters) {
|
|
if (url.endsWith(delimiter) &&
|
|
_hasUnclosedMarkdownDelimiter(
|
|
segment.substring(0, start),
|
|
delimiter,
|
|
)) {
|
|
url = url.substring(0, url.length - delimiter.length);
|
|
trailing = '$delimiter$trailing';
|
|
strippedDelimiter = true;
|
|
break;
|
|
}
|
|
}
|
|
}
|
|
|
|
if (isBuzzUrl) {
|
|
final punctuation = _trailingPunctuationPattern.firstMatch(url);
|
|
if (punctuation != null) {
|
|
url = url.substring(0, punctuation.start);
|
|
trailing = '${punctuation[0]}$trailing';
|
|
peelBackslashes();
|
|
}
|
|
}
|
|
|
|
// Preserve a URL already used as its own Markdown label. This covers both
|
|
// converted autolinks and authored `[url](url)` links.
|
|
if (start >= 1 && segment[start - 1] == '[') return matched;
|
|
// A backslash before the URL is literal, since a letter follows it. Double
|
|
// it so it can't escape the synthesized `[`.
|
|
final literalBackslash = _isEscaped(segment, start) ? r'\' : '';
|
|
return '$literalBackslash[$url]($url)$trailing';
|
|
}
|
|
|
|
bool _hasUnclosedMarkdownDelimiter(String prefix, String delimiter) {
|
|
var open = false;
|
|
var offset = 0;
|
|
while (true) {
|
|
final index = prefix.indexOf(delimiter, offset);
|
|
if (index < 0) return open;
|
|
final before = index == 0 ? null : prefix[index - 1];
|
|
final afterIndex = index + delimiter.length;
|
|
final after = afterIndex == prefix.length ? null : prefix[afterIndex];
|
|
final canOpen =
|
|
(after == null || after.trim().isNotEmpty) &&
|
|
(before == null ||
|
|
before.trim().isEmpty ||
|
|
RegExp(r'[^\w]').hasMatch(before));
|
|
if (open || canOpen) open = !open;
|
|
offset = afterIndex;
|
|
}
|
|
}
|