mirror of
https://github.com/OpenBB-finance/OpenBB.git
synced 2026-10-27 04:31:13 +00:00
Dark Pool Shorts menu (#668)
* Work on dark pool short menu

* refactor some code

* fix sec_view and sec_model, and dp notebook

* improvements

* fix test

* minor fix

* add load command

* improve commands name

* remove news
This commit is contained in:
 DidierRLopes
2
.github/workflows/test.yml
vendored
2
.github/workflows/test.yml
vendored
@@ -30,7 +30,7 @@ jobs:
|
||||
- run: pip install types-pytz types-requests types-termcolor types-tabulate types-PyYAML types-python-dateutil
|
||||
- run: bandit -r . || true
|
||||
- run: black --check .
|
||||
- run: codespell --ignore-words-list=pres,coo,navagation,ser,buil,operatio,mape,ba,hist,yeld,ether --quiet-level=2 --skip=".git" --skip="*.yaml" --skip="*.json" --skip="*.html" --skip="*.ini" --skip="*.md"
|
||||
- run: codespell --ignore-words-list=pres,coo,navagation,ser,buil,operatio,mape,ba,hist,yeld,ether,hsi --quiet-level=2 --skip=".git" --skip="*.yaml" --skip="*.json" --skip="*.html" --skip="*.ini" --skip="*.md"
|
||||
- run: flake8 . --count --ignore=E203,W503 --max-line-length=122 --show-source --statistics
|
||||
- run: mypy --ignore-missing-imports .
|
||||
- run: shopt -s globstar && pyupgrade --py36-plus **/*.py
|
||||
|
||||
2
.pre-commit-config.yaml
vendored
2
.pre-commit-config.yaml
vendored
@@ -21,7 +21,7 @@ repos:
|
||||
hooks:
|
||||
- id: codespell
|
||||
entry: codespell
|
||||
args: [ '--ignore-words-list=pres,coo,navagation,ser,buil,operatio,mape,ba,hist,yeld,ether', '--quiet-level=2', '--skip=".git,*.html,*.yaml,*.json,./tests"' ]
|
||||
args: [ '--ignore-words-list=pres,coo,navagation,ser,buil,operatio,mape,ba,hist,yeld,ether,hsi', '--quiet-level=2', '--skip=".git,*.html,*.yaml,*.json,./tests"' ]
|
||||
- repo: https://github.com/pre-commit/mirrors-mypy
|
||||
rev: 'v0.812'
|
||||
hooks:
|
||||
|
||||
370
gamestonk_terminal/stocks/dark_pool_shorts/README.md
vendored
Normal file
370
gamestonk_terminal/stocks/dark_pool_shorts/README.md
vendored
Normal file
@@ -0,0 +1,370 @@
|
||||
# DISCOVER STOCKS
|
||||
|
||||
This menu aims to discover new stocks, and the usage of the following commands along with an example will be exploited below.
|
||||
|
||||
* [ipo](#ipo)
|
||||
* past and future IPOs [Finnhub]
|
||||
* [map](#map)
|
||||
* S&P500 index stocks map [Finviz]
|
||||
* [rtp_sectors](#rtp_sectors)
|
||||
* real-time performance sectors [Alpha Vantage]
|
||||
* [gainers](#gainers)
|
||||
* show latest top gainers [Yahoo Finance]
|
||||
* [losers](#losers)
|
||||
* show latest top losers [Yahoo Finance]
|
||||
* [orders](#orders)
|
||||
* orders by Fidelity Customers [Fidelity]
|
||||
* [ark_orders](#ark_orders)
|
||||
* orders by ARK Investment Management LLC [https://cathiesark.com]
|
||||
* [up_earnings](#up_earnings)
|
||||
* upcoming earnings release dates [Seeking Alpha]
|
||||
* [high_short](#high_short)
|
||||
* show top high short interest stocks of over 20% ratio [www.highshortinterest.com]
|
||||
* [low_float](#low_float)
|
||||
* show low float stocks under 10M shares float [www.lowfloat.com]
|
||||
* [simply_wallst](#simply_wallst)
|
||||
* Simply Wall St. research data [Simply Wall St.]
|
||||
* [spachero](#spachero)
|
||||
* great website for SPACs research [SpacHero]
|
||||
* [uwhales](#uwhales)
|
||||
* good website for SPACs research [UnusualWhales]
|
||||
* [valuation](#valuation)
|
||||
* valuation of sectors, industry, country [Finviz]
|
||||
* [performance](#performance)
|
||||
* performance of sectors, industry, country [Finviz]
|
||||
* [spectrum](#spectrum)
|
||||
* spectrum of sectors, industry, country [Finviz]
|
||||
* [latest](#latest)
|
||||
* latest news [Seeking Alpha]
|
||||
* [trending](#trending)
|
||||
* trending news [Seeking Alpha]
|
||||
* [darkpool](#darkpool)
|
||||
* dark pool tickers with growing activity [FINRA]
|
||||
* [darkshort](#darkshort)
|
||||
* dark pool short position [Stockgrid]
|
||||
* [shortvol](#shortvol)
|
||||
* short interest and days to cover [Stockgrid]
|
||||
* [popular](#popular)
|
||||
* most popular stocks on social media right now [SentimentInvestor.com]
|
||||
* [emerging](#emerging)
|
||||
* stocks that are being talked about more than usual [SentimentInvestor.com]
|
||||
|
||||
## ipo <a name="ipo"></a>
|
||||
|
||||
```shell
|
||||
usage: ipo [-p PAST_DAYS] [-f FUTURE_DAYS]
|
||||
```
|
||||
|
||||
Past and future IPOs. [Source: https://finnhub.io]
|
||||
|
||||
* -p : Number of past days to look for IPOs. Default 0.
|
||||
* -f : Number of future days to look for IPOs. Default 10.
|
||||
|
||||
<img width="1005" alt="Captura de ecrã 2021-05-03, às 12 54 44" src="https://user-images.githubusercontent.com/25267873/116873168-1e6ed900-ac0f-11eb-9d80-dddc8a754885.png">
|
||||
|
||||
|
||||
## map <a name="map"></a>
|
||||
|
||||
```shell
|
||||
usage: map [-p {1d,1w,1m,3m,6m,1y}] [-t {sp500,world,full,etf}]
|
||||
```
|
||||
|
||||
Performance index stocks map categorized by sectors and industries. Size represents market cap. Opens web-browser. [Source: Finviz]
|
||||
|
||||
* -p : Performance period. Default 1 day.
|
||||
* -t : Map filter type. Default S&P500.
|
||||
|
||||

|
||||
|
||||
## rtp_sectors <a name="rtp_sectors"></a>
|
||||
|
||||
```shell
|
||||
usage: rtp_sectors
|
||||
```
|
||||
|
||||
Real-time and historical sector performances calculated from S&P500 incumbents. Pops plot in terminal. [Source: Alpha Vantage]
|
||||
|
||||

|
||||
|
||||
## gainers <a name="gainers"></a>
|
||||
|
||||
```shell
|
||||
usage: gainers [-n {1,2,3,4,5,6,7,8,9,10,11,12,13,14,15,16,17,18,19,20,21,22,23,24}]
|
||||
```
|
||||
|
||||
Print up to 25 top ticker gainers in terminal. [Source: Yahoo Finance]
|
||||
|
||||
* -n : Number of the top gainers stocks to retrieve. Default 5.
|
||||
|
||||
<img width="935" alt="Captura de ecrã 2021-02-20, às 11 46 09" src="https://user-images.githubusercontent.com/25267873/108594319-46b99c00-7371-11eb-877e-ef75d3ba472b.png">
|
||||
|
||||
## losers <a name="losers"></a>
|
||||
|
||||
```shell
|
||||
usage: losers [-n {1,2,3,4,5,6,7,8,9,10,11,12,13,14,15,16,17,18,19,20,21,22,23,24}]
|
||||
```
|
||||
|
||||
Print up to 25 top ticker losers in terminal. [Source: Yahoo Finance]
|
||||
|
||||
* -n : Number of the top losers stocks to retrieve. Default 5.
|
||||
|
||||
<img width="993" alt="Captura de ecrã 2021-03-14, às 20 23 21" src="https://user-images.githubusercontent.com/25267873/111083099-a421b280-8503-11eb-9bb0-c728ce1e313f.png">
|
||||
|
||||
## orders <a name="orders"></a>
|
||||
|
||||
```shell
|
||||
usage: orders [-n N_NUM]
|
||||
```
|
||||
|
||||
Orders by Fidelity customers. Information shown in the table below is based on the volume of orders entered on the "as of" date shown. Securities identified are not recommended or endorsed by Fidelity and are displayed for informational purposes only. [Source: Fidelity]
|
||||
|
||||
* -n : Number of top ordered stocks to be printed. Default 10.
|
||||
|
||||
<img width="945" alt="Captura de ecrã 2021-02-20, às 11 45 43" src="https://user-images.githubusercontent.com/25267873/108594318-45886f00-7371-11eb-919f-fd1bce6d4001.png">
|
||||
|
||||
## ark_orders <a name="ark_orders"></a>
|
||||
|
||||
```shell
|
||||
usage: ark_orders [-n N_NUM]
|
||||
```
|
||||
|
||||
Orders by ARK Investment Management LLC - https://ark-funds.com/. [Source: https://cathiesark.com]
|
||||
|
||||
* -n : Last N orders to be printed. Default 20.
|
||||
|
||||
<img width="957" alt="Captura de ecrã 2021-03-10, às 21 36 38" src="https://user-images.githubusercontent.com/25267873/110701322-ef2c8480-81e8-11eb-85a2-7ebfa3fa0680.png">
|
||||
|
||||
|
||||
## up_earnings <a name="up_earnings"></a>
|
||||
|
||||
```shell
|
||||
usage: up_earnings [-p N_PAGES] [-n N_NUM]
|
||||
```
|
||||
|
||||
Print upcoming earnings release dates. [Source: Seeking Alpha]
|
||||
|
||||
* -p : Number of pages to read upcoming earnings from in Seeking Alpha website. Default 10.
|
||||
* -n : Number of upcoming earnings release dates to print. Default 3.
|
||||
|
||||
<img width="933" alt="Captura de ecrã 2021-02-20, às 11 45 24" src="https://user-images.githubusercontent.com/25267873/108594317-45886f00-7371-11eb-85e6-03d839d421b3.png">
|
||||
|
||||
## high_short <a name="high_short"></a>
|
||||
|
||||
```shell
|
||||
usage: high_short [-n N_NUM]
|
||||
```
|
||||
|
||||
Print top stocks being more heavily shorted. HighShortInterest.com provides a convenient sorted database of stocks which have a short interest of over 20 percent. Additional key data such as the float, number of outstanding shares, and company industry is displayed. Data is presented for the Nasdaq Stock Market, the New York Stock Exchange, and the American Stock Exchange. Stocks with high short interest are often very volatile and are well known for making explosive upside moves (known as a short squeeze). [Source: www.highshortinterest.com]
|
||||
|
||||
* -n : Number of top stocks to print
|
||||
|
||||
<img width="940" alt="Captura de ecrã 2021-02-20, às 11 45 02" src="https://user-images.githubusercontent.com/25267873/108594316-45886f00-7371-11eb-8ded-94fbe28ac84c.png">
|
||||
|
||||
## low_float <a name="low_float"></a>
|
||||
|
||||
```shell
|
||||
usage: low_float [-n N_NUM]
|
||||
```
|
||||
|
||||
Print top stocks with lowest float. LowFloat.com provides a convenient sorted database of stocks which have a float of under 10 million shares. Additional key data such as the number of outstanding shares, short interest, and company industry is displayed. Data is presented for the Nasdaq Stock Market, the New York Stock Exchange, the American Stock Exchange, and the Over the Counter Bulletin Board. [Source: www.lowfloat.com]
|
||||
|
||||
* -n : Number of top stocks to print
|
||||
|
||||
<img width="942" alt="Captura de ecrã 2021-02-20, às 11 44 39" src="https://user-images.githubusercontent.com/25267873/108594315-44efd880-7371-11eb-9be7-7ae02999fd09.png">
|
||||
|
||||
## simply_wallst <a name="simply_wallst"></a>
|
||||
|
||||
```shell
|
||||
usage: simply_wallst [-i {any,automobiles,banks,capital-goods,commercial-services,consumer-durables,consumer-services,diversified-financials,energy,consumer-retailing,food-beverage-tobacco,healthcare,household,insurance,materials,media,pharmaceuticals-biotech,real-estate,retail,semiconductors,software,tech,telecom,transportation,utilities}]
|
||||
```
|
||||
|
||||
Simply Wall Street Research. Opens web browser. Although this does not require an API key, it requires a subscription to the website by the user (there's a 14 days free trial). [Source: Simply Wall St.]
|
||||
|
||||
* -i : Industry of interest
|
||||
|
||||
<img width="1200" alt="sw" src="https://user-images.githubusercontent.com/25267873/108576534-dfbac980-7315-11eb-9350-254fb9b64773.png">
|
||||
|
||||
## spachero <a name="spachero"></a>
|
||||
|
||||
```shell
|
||||
usage: spachero
|
||||
```
|
||||
|
||||
Great website for SPACs research. [Source: www.spachero.com]
|
||||
|
||||
<img width="1265" alt="Captura de ecrã 2021-02-20, às 01 12 14" src="https://user-images.githubusercontent.com/25267873/108577430-f282cd80-7318-11eb-888b-82dcf90d4f32.png">
|
||||
|
||||
## uwhales <a name="uwhales"></a>
|
||||
|
||||
```shell
|
||||
usage: uwhales
|
||||
```
|
||||
|
||||
Good website for SPACs research. [Source: www.unusualwhales.com]
|
||||
|
||||
<img width="1247" alt="Captura de ecrã 2021-02-20, às 11 38 54" src="https://user-images.githubusercontent.com/25267873/108594176-47056780-7370-11eb-8f2d-5972c8634974.png">
|
||||
|
||||
## valuation <a name="valuation"></a>
|
||||
|
||||
```shell
|
||||
usage: valuation [-g Sector,Industry,Industry (Basic Materials),Industry (Communication Services),
|
||||
Industry (Consumer Cyclical),Industry (Consumer Defensive),Industry (Energy),Industry (Financial),
|
||||
Industry (Healthcare),Industry (Industrials),Industry (Real Estate),Industry (Technology),
|
||||
Industry (Utilities),Country (U.S. listed stocks only),Capitalization]
|
||||
```
|
||||
|
||||
valuation of sectors, industry, country. [Source: Finviz]
|
||||
* -g : Data group (sector, industry or country). Default: Sector.
|
||||
|
||||
<img width="1020" alt="sec_val" src="https://user-images.githubusercontent.com/25267873/113647490-d2b62780-9682-11eb-8346-089bd0499ba9.png">
|
||||
|
||||
|
||||
## performance <a name="performance"></a>
|
||||
|
||||
```shell
|
||||
usage: performance [-g Sector,Industry,Industry (Basic Materials),Industry (Communication Services),
|
||||
Industry (Consumer Cyclical),Industry (Consumer Defensive),Industry (Energy),Industry (Financial),
|
||||
Industry (Healthcare),Industry (Industrials),Industry (Real Estate),Industry (Technology),
|
||||
Industry (Utilities),Country (U.S. listed stocks only),Capitalization]
|
||||
```
|
||||
|
||||
performance of sectors, industry, country. [Source: Finviz]
|
||||
* -g : Data group (sector, industry or country). Default: Sector.
|
||||
|
||||
<img width="1034" alt="ind_per" src="https://user-images.githubusercontent.com/25267873/113647513-dba6f900-9682-11eb-9b43-c1055af85536.png">
|
||||
|
||||
|
||||
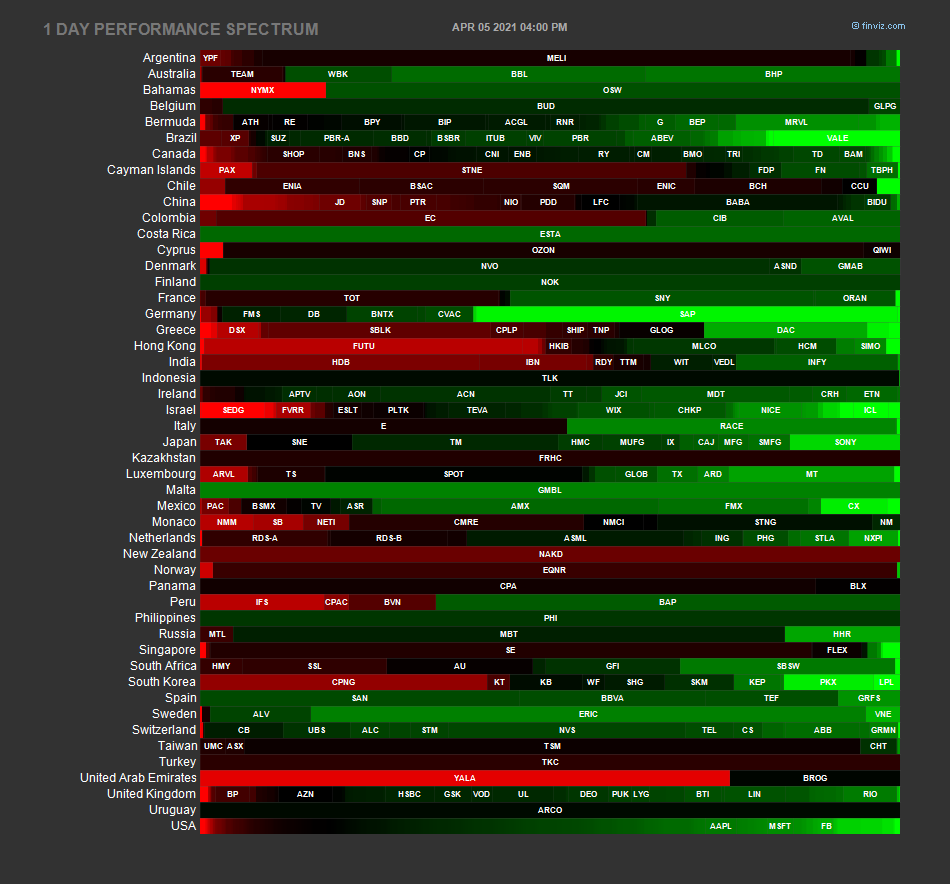
## spectrum <a name="spectrum"></a>
|
||||
|
||||
```
|
||||
usage: spectrum [-g Sector,Industry,Industry (Basic Materials),Industry (Communication Services),
|
||||
Industry (Consumer Cyclical),Industry (Consumer Defensive),Industry (Energy),Industry (Financial),
|
||||
Industry (Healthcare),Industry (Industrials),Industry (Real Estate),Industry (Technology),
|
||||
Industry (Utilities),Country (U.S. listed stocks only),Capitalization]
|
||||
```
|
||||
|
||||
Spectrum of sectors, industry, country. [Source: Finviz]
|
||||
* -g : Data group (sector, industry or country). Default: Sector.
|
||||
|
||||
|
||||
|
||||
|
||||
## latest <a name="latest"></a>
|
||||
|
||||
```
|
||||
usage: latest [-i N_ID] [-n N_NUM] [-d DATE]
|
||||
```
|
||||
|
||||
Latest news articles. [Source: Seeking Alpha]
|
||||
* -i : Article ID number.
|
||||
* -n : Number of articles being printed. Default 10.
|
||||
* -d : Date of news article.
|
||||
|
||||
<img width="1208" alt="latest" src="https://user-images.githubusercontent.com/25267873/115089633-926c6a00-9f0a-11eb-9d0e-1eedfd8ba7ce.png">
|
||||
|
||||
|
||||
## trending <a name="trending"></a>
|
||||
|
||||
```
|
||||
usage: trending [-i N_ID] [-n N_NUM]
|
||||
```
|
||||
|
||||
Trending news articles. [Source: Seeking Alpha]
|
||||
* -i : Article ID number.
|
||||
* -n : Number of articles being printed. Default 10.
|
||||
|
||||
<img width="1213" alt="trending" src="https://user-images.githubusercontent.com/25267873/115089640-96988780-9f0a-11eb-9ca7-70a245fa3960.png">
|
||||
|
||||
|
||||
## darkpool <a name="darkpool"></a>
|
||||
|
||||
```
|
||||
usage: darkpool [-n N_NUM] [-t N_TOP]
|
||||
```
|
||||
|
||||
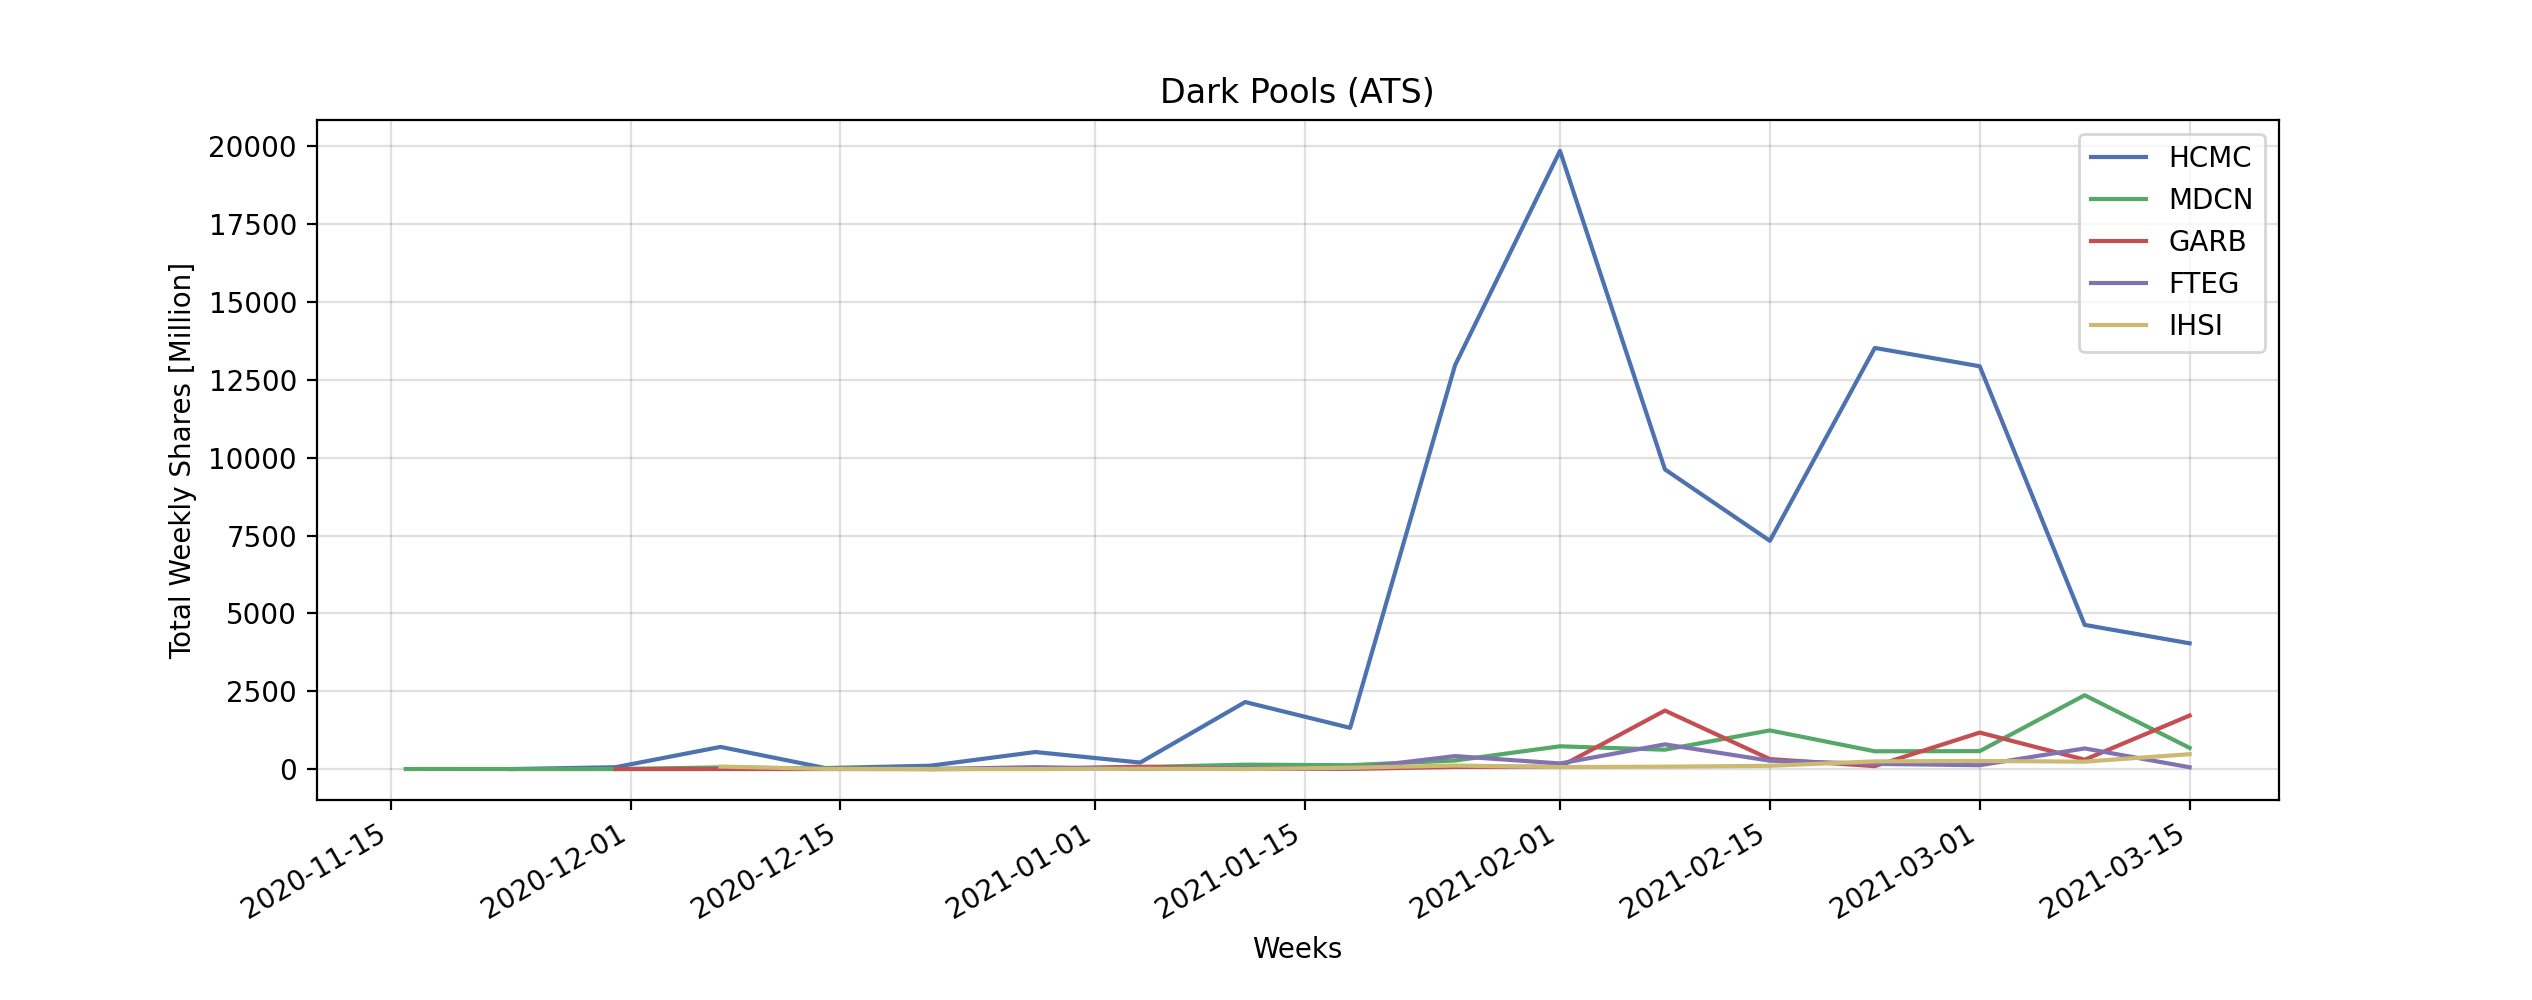
Display dark pool (ATS) data of tickers with growing trades activity. [Source: FINRA]
|
||||
|
||||
* -n : Number of tickers to filter from entire ATS data based on the sum of the total weekly shares quantity. Default: 1000.
|
||||
* -t : List of tickers from most promising with better linear regression slope. Default: 5.
|
||||
|
||||
|
||||
|
||||
## darkshort <a name="darkshort"></a>
|
||||
|
||||
```
|
||||
usage: darkshort [-n NUM] [-s {sv,sv_pct,nsv,nsv_dollar,dpp,dpp_dollar}]
|
||||
```
|
||||
Get dark pool short positions. [Source: Stockgrid]
|
||||
* -n: Number of top tickers to show
|
||||
* -s: Field for which to sort by, where 'sv': Short Vol. (1M), 'sv_pct': Short Vol. %, 'nsv': Net Short Vol. (1M), 'nsv_dollar': Net Short Vol. ($100M), 'dpp': DP Position (1M), 'dpp_dollar': DP Position ($1B). Default: dpp_dollar.
|
||||
* --export: Save dataframe as a csv file. Default: false.
|
||||
|
||||
<img width="945" alt="darkshort" src="https://user-images.githubusercontent.com/25267873/122323732-76dc0a80-cf1f-11eb-9983-fd7688778016.png">
|
||||
|
||||
|
||||
## shortvol <a name="darkpool"></a>
|
||||
|
||||
```
|
||||
usage: shortvol [-n NUM] [-s {float,dtc,si}] [-h]
|
||||
```
|
||||
|
||||
Print short interest and days to cover. [Source: Stockgrid]
|
||||
* -n: Number of top tickers to show
|
||||
* -s: Field for which to sort by, where 'float': Float Short %, 'dtc': Days to Cover, 'si': Short Interest. Default: float.
|
||||
* -a: Data in ascending order. Default: false.
|
||||
* --export: Save dataframe as a csv file. Default: false.
|
||||
|
||||
<img width="949" alt="shortvol" src="https://user-images.githubusercontent.com/25267873/122323861-af7be400-cf1f-11eb-9de2-5c7f2debddf0.png">
|
||||
|
||||
## popular <a name="popular"></a>
|
||||
|
||||
```
|
||||
usage: popular [-l LIMIT] [-h]
|
||||
```
|
||||
|
||||
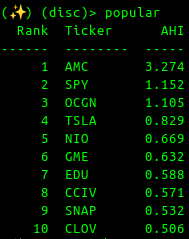
The `popular` command prints the top `n` (default=10) stocks with the highest Average Hype Index right now.
|
||||
|
||||
### AHI (Absolute Hype Index)
|
||||
|
||||
AHI is a measure of how much people are talking about a stock on social media.
|
||||
It is calculated by dividing the total number of mentions for the chosen stock
|
||||
on a social network by the mean number of mentions any stock receives on that
|
||||
social medium.
|
||||
|
||||
> **[Sentiment Investor](https://sentimentinvestor.com)** analyzes data from four major social media platforms to
|
||||
> generate hourly metrics on over 2,000 stocks. Sentiment provides volume and
|
||||
> sentiment metrics powered by proprietary NLP models.
|
||||
|
||||
Optional arguments:
|
||||
- `-l`, `--limit LIMIT`
|
||||
the maximum number of stocks to retrieve
|
||||
- `-h`, `--help`
|
||||
show this help message
|
||||
|
||||
|
||||
|
||||
## emerging <a name="emerging"></a>
|
||||
|
||||
```
|
||||
usage: emerging [-l LIMIT] [-h]
|
||||
```
|
||||
|
||||
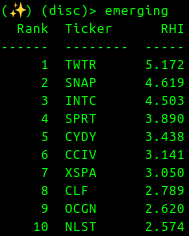
The `emerging` command prints the top `n` (default=10) stocks with the highest Relative Hype Index right now.
|
||||
|
||||
### RHI (Relative Hype Index)
|
||||
RHI is a measure of whether people are talking about a stock more or less than
|
||||
usual, calculated by dividing the mean AHI for the past day by the mean AHI for
|
||||
for the past week for that stock.
|
||||
|
||||
> **[Sentiment Investor](https://sentimentinvestor.com)** analyzes data from four major social media platforms to
|
||||
> generate hourly metrics on over 2,000 stocks. Sentiment provides volume and
|
||||
> sentiment metrics powered by proprietary NLP models.
|
||||
|
||||
|
||||
Optional arguments:
|
||||
- `-l`, `--limit LIMIT`
|
||||
the maximum number of stocks to retrieve
|
||||
- `-h`, `--help`
|
||||
show this help message
|
||||
|
||||
|
||||
1
gamestonk_terminal/stocks/dark_pool_shorts/__init__.py
Normal file
1
gamestonk_terminal/stocks/dark_pool_shorts/__init__.py
Normal file
@@ -0,0 +1 @@
|
||||
from . import dps_controller # noqa: F401
|
||||
596
gamestonk_terminal/stocks/dark_pool_shorts/dps_controller.py
Normal file
596
gamestonk_terminal/stocks/dark_pool_shorts/dps_controller.py
Normal file
@@ -0,0 +1,596 @@
|
||||
""" Disc Controller """
|
||||
__docformat__ = "numpy"
|
||||
|
||||
import argparse
|
||||
import os
|
||||
from typing import List
|
||||
from datetime import datetime, timedelta
|
||||
from colorama import Style
|
||||
import pandas as pd
|
||||
from matplotlib import pyplot as plt
|
||||
from prompt_toolkit.completion import NestedCompleter
|
||||
from gamestonk_terminal import feature_flags as gtff
|
||||
from gamestonk_terminal.helper_funcs import get_flair
|
||||
from gamestonk_terminal.menu import session
|
||||
from gamestonk_terminal.helper_funcs import (
|
||||
parse_known_args_and_warn,
|
||||
check_positive,
|
||||
valid_date,
|
||||
)
|
||||
from gamestonk_terminal.stocks.stocks_helper import load
|
||||
from gamestonk_terminal.stocks.dark_pool_shorts import (
|
||||
stockgrid_view,
|
||||
shortinterest_view,
|
||||
quandl_view,
|
||||
sec_view,
|
||||
finra_view,
|
||||
)
|
||||
|
||||
|
||||
class DarkPoolShortsController:
|
||||
"""Dark Pool Shorts Controller"""
|
||||
|
||||
# Command choices
|
||||
CHOICES = [
|
||||
"?",
|
||||
"cls",
|
||||
"help",
|
||||
"q",
|
||||
"quit",
|
||||
"load",
|
||||
]
|
||||
|
||||
CHOICES_COMMANDS = [
|
||||
"hsi",
|
||||
"prom",
|
||||
"pos",
|
||||
"sidtc",
|
||||
]
|
||||
|
||||
CHOICES_COMMANDS_WITH_TICKER = [
|
||||
"shortint",
|
||||
"dpotc",
|
||||
"ftd",
|
||||
"spos",
|
||||
]
|
||||
|
||||
CHOICES += CHOICES_COMMANDS
|
||||
CHOICES += CHOICES_COMMANDS_WITH_TICKER
|
||||
|
||||
def __init__(self, ticker: str, start: str, stock: pd.DataFrame):
|
||||
"""Constructor"""
|
||||
self.ticker = ticker
|
||||
self.start = start
|
||||
self.stock = stock
|
||||
|
||||
self.disc_parser = argparse.ArgumentParser(add_help=False, prog="dps")
|
||||
self.disc_parser.add_argument(
|
||||
"cmd",
|
||||
choices=self.CHOICES,
|
||||
)
|
||||
|
||||
def print_help(self):
|
||||
"""Print help"""
|
||||
help_text = f"""https://github.com/GamestonkTerminal/GamestonkTerminal/tree/main/gamestonk_terminal/stocks/dark_pool_shorts
|
||||
|
||||
Dark Pool Shorts:
|
||||
cls clear screen
|
||||
?/help show this menu again
|
||||
q quit this menu, and shows back to main menu
|
||||
quit quit to abandon program
|
||||
load load a specific stock ticker for analysis
|
||||
|
||||
shortinterest.com
|
||||
hsi show top high short interest stocks of over 20% ratio
|
||||
FINRA:
|
||||
prom promising tickers based on dark pool shares regression
|
||||
Stockgrid:
|
||||
pos dark pool short position
|
||||
sidtc short interest and days to cover
|
||||
{Style.DIM if not self.ticker else ''}
|
||||
Ticker: {self.ticker or None}
|
||||
|
||||
FINRA:
|
||||
dpotc dark pools (ATS) vs OTC data
|
||||
SEC:
|
||||
ftd fails-to-deliver data
|
||||
Stockgrid:
|
||||
spos net short vs position
|
||||
Quandl/Stockgrid:
|
||||
psi price vs short interest volume
|
||||
{Style.RESET_ALL if not self.ticker else ''}"""
|
||||
print(help_text)
|
||||
|
||||
def switch(self, an_input: str):
|
||||
"""Process and dispatch input
|
||||
Returns
|
||||
-------
|
||||
True, False or None
|
||||
False - quit the menu
|
||||
True - quit the program
|
||||
None - continue in the menu
|
||||
"""
|
||||
# Empty command
|
||||
if not an_input:
|
||||
print("")
|
||||
return None
|
||||
|
||||
(known_args, other_args) = self.disc_parser.parse_known_args(an_input.split())
|
||||
|
||||
# Help menu again
|
||||
if known_args.cmd == "?":
|
||||
self.print_help()
|
||||
return None
|
||||
|
||||
# Clear screen
|
||||
if known_args.cmd == "cls":
|
||||
os.system("cls||clear")
|
||||
return None
|
||||
|
||||
return getattr(
|
||||
self, "call_" + known_args.cmd, lambda: "Command not recognized!"
|
||||
)(other_args)
|
||||
|
||||
def call_help(self, _):
|
||||
"""Process Help command"""
|
||||
self.print_help()
|
||||
|
||||
def call_q(self, _):
|
||||
"""Process Q command - quit the menu"""
|
||||
return False
|
||||
|
||||
def call_quit(self, _):
|
||||
"""Process Quit command - quit the program"""
|
||||
return True
|
||||
|
||||
def call_load(self, other_args: List[str]):
|
||||
"""Process load command"""
|
||||
self.ticker, self.start, _, self.stock = load(
|
||||
other_args, self.ticker, self.start, "1440min", self.stock
|
||||
)
|
||||
|
||||
def call_hsi(self, other_args: List[str]):
|
||||
"""Process hsi command"""
|
||||
parser = argparse.ArgumentParser(
|
||||
add_help=False,
|
||||
formatter_class=argparse.ArgumentDefaultsHelpFormatter,
|
||||
prog="hsi",
|
||||
description="""
|
||||
Print top stocks being more heavily shorted. HighShortInterest.com provides
|
||||
a convenient sorted database of stocks which have a short interest of over
|
||||
20 percent. Additional key data such as the float, number of outstanding shares,
|
||||
and company industry is displayed. Data is presented for the Nasdaq Stock Market,
|
||||
the New York Stock Exchange, and the American Stock Exchange. [Source: www.highshortinterest.com]
|
||||
""",
|
||||
)
|
||||
parser.add_argument(
|
||||
"-n",
|
||||
"--num",
|
||||
action="store",
|
||||
dest="n_num",
|
||||
type=check_positive,
|
||||
default=10,
|
||||
help="Number of top stocks to print.",
|
||||
)
|
||||
parser.add_argument(
|
||||
"--export",
|
||||
choices=["csv", "json", "xlsx"],
|
||||
default="",
|
||||
type=str,
|
||||
dest="export",
|
||||
help="Export dataframe data to csv,json,xlsx file",
|
||||
)
|
||||
try:
|
||||
ns_parser = parse_known_args_and_warn(parser, other_args)
|
||||
if not ns_parser:
|
||||
return
|
||||
|
||||
shortinterest_view.high_short_interest(
|
||||
num=ns_parser.n_num,
|
||||
export=ns_parser.export,
|
||||
)
|
||||
|
||||
except Exception as e:
|
||||
print(e, "\n")
|
||||
|
||||
def call_prom(self, other_args: List[str]):
|
||||
"""Process prom command"""
|
||||
parser = argparse.ArgumentParser(
|
||||
add_help=False,
|
||||
formatter_class=argparse.ArgumentDefaultsHelpFormatter,
|
||||
prog="prom",
|
||||
description="Display dark pool (ATS) data of tickers with growing trades activity",
|
||||
)
|
||||
parser.add_argument(
|
||||
"-n",
|
||||
"--num",
|
||||
action="store",
|
||||
dest="n_num",
|
||||
type=check_positive,
|
||||
default=1_000,
|
||||
help="Number of tickers to filter from entire ATS data based on the sum of the total weekly shares quantity.",
|
||||
)
|
||||
parser.add_argument(
|
||||
"-t",
|
||||
"--top",
|
||||
action="store",
|
||||
dest="n_top",
|
||||
type=check_positive,
|
||||
default=5,
|
||||
help="List of tickers from most promising with better linear regression slope.",
|
||||
)
|
||||
try:
|
||||
ns_parser = parse_known_args_and_warn(parser, other_args)
|
||||
if not ns_parser:
|
||||
return
|
||||
|
||||
finra_view.darkpool_otc(num=ns_parser.n_num, promising=ns_parser.n_top)
|
||||
|
||||
except Exception as e:
|
||||
print(e, "\n")
|
||||
|
||||
def call_pos(self, other_args: List[str]):
|
||||
"""Process pos command"""
|
||||
parser = argparse.ArgumentParser(
|
||||
prog="pos",
|
||||
add_help=False,
|
||||
formatter_class=argparse.ArgumentDefaultsHelpFormatter,
|
||||
description="Get dark pool short positions. [Source: Stockgrid]",
|
||||
)
|
||||
parser.add_argument(
|
||||
"-n",
|
||||
"--number",
|
||||
help="Number of top tickers to show",
|
||||
type=check_positive,
|
||||
default=10,
|
||||
dest="num",
|
||||
)
|
||||
parser.add_argument(
|
||||
"-s",
|
||||
"--sort",
|
||||
help="Field for which to sort by, where 'sv': Short Vol. (1M), "
|
||||
"'sv_pct': Short Vol. %%, 'nsv': Net Short Vol. (1M), "
|
||||
"'nsv_dollar': Net Short Vol. ($100M), 'dpp': DP Position (1M), "
|
||||
"'dpp_dollar': DP Position ($1B)",
|
||||
choices=["sv", "sv_pct", "nsv", "nsv_dollar", "dpp", "dpp_dollar"],
|
||||
default="dpp_dollar",
|
||||
dest="sort_field",
|
||||
)
|
||||
parser.add_argument(
|
||||
"-a",
|
||||
"--ascending",
|
||||
action="store_true",
|
||||
default=False,
|
||||
dest="ascending",
|
||||
help="Data in ascending order",
|
||||
)
|
||||
parser.add_argument(
|
||||
"--export",
|
||||
choices=["csv", "json", "xlsx"],
|
||||
default="",
|
||||
dest="export",
|
||||
help="Export dataframe data to csv,json,xlsx file",
|
||||
)
|
||||
try:
|
||||
ns_parser = parse_known_args_and_warn(parser, other_args)
|
||||
if not ns_parser:
|
||||
return
|
||||
|
||||
stockgrid_view.dark_pool_short_positions(
|
||||
num=ns_parser.num,
|
||||
sort_field=ns_parser.sort_field,
|
||||
ascending=ns_parser.ascending,
|
||||
export=ns_parser.export,
|
||||
)
|
||||
|
||||
except Exception as e:
|
||||
print(e, "\n")
|
||||
|
||||
def call_sidtc(self, other_args: List[str]):
|
||||
"""Process sidtc command"""
|
||||
parser = argparse.ArgumentParser(
|
||||
prog="sidtc",
|
||||
add_help=False,
|
||||
formatter_class=argparse.ArgumentDefaultsHelpFormatter,
|
||||
description="Print short interest and days to cover. [Source: Stockgrid]",
|
||||
)
|
||||
parser.add_argument(
|
||||
"-n",
|
||||
"--number",
|
||||
help="Number of top tickers to show",
|
||||
type=check_positive,
|
||||
default=10,
|
||||
dest="num",
|
||||
)
|
||||
parser.add_argument(
|
||||
"-s",
|
||||
"--sort",
|
||||
help="Field for which to sort by, where 'float': Float Short %%, "
|
||||
"'dtc': Days to Cover, 'si': Short Interest",
|
||||
choices=["float", "dtc", "si"],
|
||||
default="float",
|
||||
dest="sort_field",
|
||||
)
|
||||
parser.add_argument(
|
||||
"--export",
|
||||
choices=["csv", "json", "xlsx"],
|
||||
default="",
|
||||
dest="export",
|
||||
help="Export dataframe data to csv,json,xlsx file",
|
||||
)
|
||||
try:
|
||||
ns_parser = parse_known_args_and_warn(parser, other_args)
|
||||
if not ns_parser:
|
||||
return
|
||||
|
||||
stockgrid_view.short_interest_days_to_cover(
|
||||
num=ns_parser.num,
|
||||
sort_field=ns_parser.sort_field,
|
||||
export=ns_parser.export,
|
||||
)
|
||||
|
||||
except Exception as e:
|
||||
print(e, "\n")
|
||||
|
||||
def call_dpotc(self, other_args: List[str]):
|
||||
"""Process dpotc command"""
|
||||
parser = argparse.ArgumentParser(
|
||||
add_help=False,
|
||||
formatter_class=argparse.ArgumentDefaultsHelpFormatter,
|
||||
prog="dpotc",
|
||||
description="Display barchart of dark pool (ATS) and OTC (Non ATS) data. [Source: FINRA]",
|
||||
)
|
||||
try:
|
||||
ns_parser = parse_known_args_and_warn(parser, other_args)
|
||||
if not ns_parser:
|
||||
return
|
||||
if not self.ticker:
|
||||
print("No ticker loaded.\n")
|
||||
return
|
||||
|
||||
finra_view.darkpool_ats_otc(ticker=self.ticker)
|
||||
|
||||
except Exception as e:
|
||||
print(e, "\n")
|
||||
|
||||
def call_ftd(self, other_args: List[str]):
|
||||
"""Process ftd command"""
|
||||
parser = argparse.ArgumentParser(
|
||||
add_help=False,
|
||||
prog="ftd",
|
||||
description="""Prints latest fails-to-deliver data. [Source: SEC]""",
|
||||
)
|
||||
parser.add_argument(
|
||||
"-s",
|
||||
"--start",
|
||||
action="store",
|
||||
dest="start",
|
||||
type=valid_date,
|
||||
default=(datetime.now() - timedelta(days=60)).strftime("%Y-%m-%d"),
|
||||
help="start of datetime to see FTD",
|
||||
)
|
||||
parser.add_argument(
|
||||
"-e",
|
||||
"--end",
|
||||
action="store",
|
||||
dest="end",
|
||||
type=valid_date,
|
||||
default=datetime.now().strftime("%Y-%m-%d"),
|
||||
help="end of datetime to see FTD",
|
||||
)
|
||||
parser.add_argument(
|
||||
"-n",
|
||||
"--num",
|
||||
action="store",
|
||||
dest="n_num",
|
||||
type=check_positive,
|
||||
default=0,
|
||||
help="number of latest fails-to-deliver being printed",
|
||||
)
|
||||
parser.add_argument(
|
||||
"--raw",
|
||||
action="store_true",
|
||||
default=False,
|
||||
dest="raw",
|
||||
help="Print raw data.",
|
||||
)
|
||||
parser.add_argument(
|
||||
"--export",
|
||||
choices=["csv", "json", "xlsx"],
|
||||
default="",
|
||||
dest="export",
|
||||
help="Export dataframe data to csv,json,xlsx file",
|
||||
)
|
||||
|
||||
try:
|
||||
ns_parser = parse_known_args_and_warn(parser, other_args)
|
||||
if not ns_parser:
|
||||
return
|
||||
if not self.ticker:
|
||||
print("No ticker loaded.\n")
|
||||
return
|
||||
|
||||
sec_view.fails_to_deliver(
|
||||
ticker=self.ticker,
|
||||
stock=self.stock,
|
||||
start=ns_parser.start,
|
||||
end=ns_parser.end,
|
||||
num=ns_parser.n_num,
|
||||
raw=ns_parser.raw,
|
||||
export=ns_parser.export,
|
||||
)
|
||||
|
||||
except Exception as e:
|
||||
print(e, "\n")
|
||||
|
||||
def call_spos(self, other_args: List[str]):
|
||||
"""Process spos command"""
|
||||
parser = argparse.ArgumentParser(
|
||||
prog="spos",
|
||||
add_help=False,
|
||||
description="Shows Net Short Vol. vs Position. [Source: Stockgrid]",
|
||||
)
|
||||
parser.add_argument(
|
||||
"-n",
|
||||
"--number",
|
||||
help="Number of last open market days to show",
|
||||
type=check_positive,
|
||||
default=10 if "-r" in other_args else 120,
|
||||
dest="num",
|
||||
)
|
||||
parser.add_argument(
|
||||
"-r",
|
||||
action="store_true",
|
||||
default=False,
|
||||
help="Flag to print raw data instead",
|
||||
dest="raw",
|
||||
)
|
||||
parser.add_argument(
|
||||
"--export",
|
||||
choices=["csv", "json", "xlsx"],
|
||||
default="",
|
||||
dest="export",
|
||||
help="Export dataframe data to csv,json,xlsx file",
|
||||
)
|
||||
try:
|
||||
ns_parser = parse_known_args_and_warn(parser, other_args)
|
||||
if not ns_parser:
|
||||
return
|
||||
if not self.ticker:
|
||||
print("No ticker loaded.\n")
|
||||
return
|
||||
|
||||
stockgrid_view.net_short_position(
|
||||
ticker=self.ticker,
|
||||
num=ns_parser.num,
|
||||
raw=ns_parser.raw,
|
||||
export=ns_parser.export,
|
||||
)
|
||||
|
||||
except Exception as e:
|
||||
print(e, "\n")
|
||||
|
||||
def call_psi(self, other_args: List[str]):
|
||||
"""Process psi command"""
|
||||
parser = argparse.ArgumentParser(
|
||||
prog="psi",
|
||||
add_help=False,
|
||||
description="Shows price vs short interest volume. [Source: Quandl/Stockgrid]",
|
||||
)
|
||||
parser.add_argument(
|
||||
"--source",
|
||||
choices=["quandl", "stockgrid"],
|
||||
default="",
|
||||
dest="stockgrid",
|
||||
help="Source of short interest volume",
|
||||
)
|
||||
if "quandl" in other_args:
|
||||
parser.add_argument(
|
||||
"-n",
|
||||
"--nyse",
|
||||
action="store_true",
|
||||
default=False,
|
||||
dest="b_nyse",
|
||||
help="Data from NYSE flag. Otherwise comes from NASDAQ.",
|
||||
)
|
||||
parser.add_argument(
|
||||
"-d",
|
||||
"--days",
|
||||
action="store",
|
||||
dest="n_days",
|
||||
type=check_positive,
|
||||
default=10,
|
||||
help="Number of latest days to print data.",
|
||||
)
|
||||
else:
|
||||
parser.add_argument(
|
||||
"-n",
|
||||
"--number",
|
||||
help="Number of last open market days to show",
|
||||
type=check_positive,
|
||||
default=10 if "-r" in other_args else 120,
|
||||
dest="num",
|
||||
)
|
||||
parser.add_argument(
|
||||
"-r",
|
||||
action="store_true",
|
||||
default=False,
|
||||
help="Flag to print raw data instead",
|
||||
dest="raw",
|
||||
)
|
||||
parser.add_argument(
|
||||
"--export",
|
||||
choices=["csv", "json", "xlsx"],
|
||||
default="",
|
||||
dest="export",
|
||||
help="Export dataframe data to csv,json,xlsx file",
|
||||
)
|
||||
try:
|
||||
ns_parser = parse_known_args_and_warn(parser, other_args)
|
||||
if not ns_parser:
|
||||
return
|
||||
if not self.ticker:
|
||||
print("No ticker loaded.\n")
|
||||
return
|
||||
|
||||
if "quandl" in other_args:
|
||||
quandl_view.short_interest(
|
||||
ticker=self.ticker,
|
||||
start=self.start,
|
||||
nyse=ns_parser.b_nyse,
|
||||
days=ns_parser.n_days,
|
||||
export=ns_parser.export,
|
||||
)
|
||||
else:
|
||||
stockgrid_view.short_interest_volume(
|
||||
ticker=self.ticker,
|
||||
num=ns_parser.num,
|
||||
raw=ns_parser.raw,
|
||||
export=ns_parser.export,
|
||||
)
|
||||
|
||||
except Exception as e:
|
||||
print(e, "\n")
|
||||
|
||||
|
||||
def menu(ticker: str = "", start: str = "", stock: pd.DataFrame = pd.DataFrame()):
|
||||
"""Dark Pool Shorts Menu
|
||||
|
||||
Parameters
|
||||
----------
|
||||
stock : DataFrame
|
||||
Due diligence stock dataframe
|
||||
ticker : str
|
||||
Due diligence ticker symbol
|
||||
start : str
|
||||
Start date of the stock data
|
||||
"""
|
||||
dps_controller = DarkPoolShortsController(ticker, start, stock)
|
||||
dps_controller.call_help(None)
|
||||
|
||||
# Loop forever and ever
|
||||
while True:
|
||||
# Get input command from user
|
||||
if session and gtff.USE_PROMPT_TOOLKIT:
|
||||
completer = NestedCompleter.from_nested_dict(
|
||||
{c: None for c in dps_controller.CHOICES}
|
||||
)
|
||||
|
||||
an_input = session.prompt(
|
||||
f"{get_flair()} (stocks)>(dps)> ",
|
||||
completer=completer,
|
||||
)
|
||||
else:
|
||||
an_input = input(f"{get_flair()} (stocks)>(dps)> ")
|
||||
|
||||
try:
|
||||
plt.close("all")
|
||||
|
||||
process_input = dps_controller.switch(an_input)
|
||||
|
||||
if process_input is not None:
|
||||
return process_input
|
||||
|
||||
except SystemExit:
|
||||
print("The command selected doesn't exist\n")
|
||||
continue
|
||||
@@ -1,18 +1,14 @@
|
||||
""" FINRA View """
|
||||
""" FINRA Model """
|
||||
__docformat__ = "numpy"
|
||||
|
||||
import argparse
|
||||
from typing import List, Tuple
|
||||
from typing import List, Tuple, Dict
|
||||
import requests
|
||||
import pandas as pd
|
||||
from matplotlib import pyplot as plt
|
||||
from gamestonk_terminal.config_plot import PLOT_DPI
|
||||
from gamestonk_terminal import feature_flags as gtff
|
||||
from gamestonk_terminal.helper_funcs import parse_known_args_and_warn, plot_autoscale
|
||||
from scipy import stats
|
||||
|
||||
|
||||
def getFINRAweeks(tier, is_ats) -> List:
|
||||
"""Get FINRA weeks
|
||||
def getFINRAweeks(tier: str, is_ats: bool) -> List:
|
||||
"""Get FINRA weeks. [Source: FINRA]
|
||||
|
||||
Parameters
|
||||
----------
|
||||
@@ -22,7 +18,7 @@ def getFINRAweeks(tier, is_ats) -> List:
|
||||
ATS data if true, NON-ATS otherwise
|
||||
|
||||
Returns
|
||||
----------
|
||||
-------
|
||||
List
|
||||
List of response data
|
||||
"""
|
||||
@@ -57,10 +53,81 @@ def getFINRAweeks(tier, is_ats) -> List:
|
||||
return response.json() if response.status_code == 200 else list()
|
||||
|
||||
|
||||
def getFINRAdata_offset(
|
||||
weekStartDate: str, tier: str, ticker: str, is_ats: bool, offset: int
|
||||
) -> requests.Response:
|
||||
"""Get FINRA data. [Source: FINRA]
|
||||
|
||||
Parameters
|
||||
----------
|
||||
weekStartDate : str
|
||||
Weekly data to get FINRA data
|
||||
tier : str
|
||||
Stock tier between T1, T2, or OTCE
|
||||
ticker : str
|
||||
Stock ticker to get data from
|
||||
is_ats : bool
|
||||
ATS data if true, NON-ATS otherwise
|
||||
offset : int
|
||||
Offset in getting the data
|
||||
|
||||
Returns
|
||||
-------
|
||||
requests.Response
|
||||
Response from FINRA data
|
||||
"""
|
||||
req_hdr = {"Accept": "application/json", "Content-Type": "application/json"}
|
||||
|
||||
l_cmp_filters = [
|
||||
{
|
||||
"compareType": "EQUAL",
|
||||
"fieldName": "weekStartDate",
|
||||
"fieldValue": weekStartDate,
|
||||
},
|
||||
{"compareType": "EQUAL", "fieldName": "tierIdentifier", "fieldValue": tier},
|
||||
{
|
||||
"compareType": "EQUAL",
|
||||
"description": "",
|
||||
"fieldName": "summaryTypeCode",
|
||||
"fieldValue": "ATS_W_SMBL" if is_ats else "OTC_W_SMBL",
|
||||
},
|
||||
]
|
||||
|
||||
if ticker:
|
||||
l_cmp_filters.append(
|
||||
{
|
||||
"compareType": "EQUAL",
|
||||
"fieldName": "issueSymbolIdentifier",
|
||||
"fieldValue": ticker,
|
||||
}
|
||||
)
|
||||
|
||||
req_data = {
|
||||
"compareFilters": l_cmp_filters,
|
||||
"delimiter": "|",
|
||||
"fields": [
|
||||
"issueSymbolIdentifier",
|
||||
"totalWeeklyShareQuantity",
|
||||
"totalWeeklyTradeCount",
|
||||
"lastUpdateDate",
|
||||
],
|
||||
"limit": 5000,
|
||||
"offset": offset,
|
||||
"quoteValues": False,
|
||||
"sortFields": ["totalWeeklyShareQuantity"],
|
||||
}
|
||||
|
||||
return requests.post(
|
||||
"https://api.finra.org/data/group/otcMarket/name/weeklySummary",
|
||||
headers=req_hdr,
|
||||
json=req_data,
|
||||
)
|
||||
|
||||
|
||||
def getFINRAdata(
|
||||
weekStartDate: str, tier: str, ticker: str, is_ats: bool
|
||||
) -> Tuple[int, List]:
|
||||
"""Get FINRA data
|
||||
"""Get FINRA data. [Source: FINRA]
|
||||
|
||||
Parameters
|
||||
----------
|
||||
@@ -74,8 +141,8 @@ def getFINRAdata(
|
||||
ATS data if true, NON-ATS otherwise
|
||||
|
||||
Returns
|
||||
----------
|
||||
str
|
||||
-------
|
||||
int
|
||||
Status code from request
|
||||
List
|
||||
List of response data
|
||||
@@ -132,6 +199,76 @@ def getFINRAdata(
|
||||
)
|
||||
|
||||
|
||||
def getATSdata(num_tickers_to_filter: int) -> Tuple[pd.DataFrame, Dict]:
|
||||
"""Get all FINRA ATS data, and parse most promising tickers based on linear regression
|
||||
|
||||
Parameters
|
||||
----------
|
||||
num_tickers_to_filter : int
|
||||
Number of tickers to filter from entire ATS data based on the sum of the total weekly shares quantity
|
||||
|
||||
Returns
|
||||
-------
|
||||
pd.DataFrame
|
||||
Dark Pools (ATS) Data
|
||||
Dict
|
||||
Tickers from Dark Pools with better regression slope
|
||||
"""
|
||||
tiers = ["T1", "T2", "OTCE"]
|
||||
df_ats = pd.DataFrame()
|
||||
|
||||
for tier in tiers:
|
||||
print(f"Processing Tier {tier} ...")
|
||||
for d_week in getFINRAweeks(tier, is_ats=True):
|
||||
offset = 0
|
||||
response = getFINRAdata_offset(
|
||||
d_week["weekStartDate"], tier, "", True, offset
|
||||
)
|
||||
l_data = response.json()
|
||||
|
||||
while len(response.json()) == 5000:
|
||||
offset += 5000
|
||||
response = getFINRAdata_offset(
|
||||
d_week["weekStartDate"], tier, "", True, offset
|
||||
)
|
||||
l_data += response.json()
|
||||
|
||||
df_ats_week = pd.DataFrame(l_data)
|
||||
df_ats_week["weekStartDate"] = d_week["weekStartDate"]
|
||||
|
||||
if not df_ats_week.empty:
|
||||
df_ats = df_ats.append(df_ats_week, ignore_index=True)
|
||||
|
||||
df_ats = df_ats.sort_values("weekStartDate")
|
||||
df_ats["weekStartDateInt"] = pd.to_datetime(df_ats["weekStartDate"]).apply(
|
||||
lambda x: x.timestamp()
|
||||
)
|
||||
|
||||
print(f"Processing regression on {num_tickers_to_filter} promising tickers ...")
|
||||
|
||||
d_ats_reg = {}
|
||||
# set(df_ats['issueSymbolIdentifier'].values) this would be iterating through all tickers
|
||||
# but that is extremely time consuming for little reward. A little filtering is done to
|
||||
# speed up search for best ATS tickers
|
||||
for symbol in list(
|
||||
df_ats.groupby("issueSymbolIdentifier")["totalWeeklyShareQuantity"]
|
||||
.sum()
|
||||
.sort_values()[-num_tickers_to_filter:]
|
||||
.index
|
||||
):
|
||||
slope = stats.linregress(
|
||||
df_ats[df_ats["issueSymbolIdentifier"] == symbol][
|
||||
"weekStartDateInt"
|
||||
].values,
|
||||
df_ats[df_ats["issueSymbolIdentifier"] == symbol][
|
||||
"totalWeeklyShareQuantity"
|
||||
].values,
|
||||
)[0]
|
||||
d_ats_reg[symbol] = slope
|
||||
|
||||
return df_ats, d_ats_reg
|
||||
|
||||
|
||||
def getTickerFINRAdata(ticker: str) -> Tuple[pd.DataFrame, pd.DataFrame]:
|
||||
"""Get all FINRA data associated with a ticker
|
||||
|
||||
@@ -141,7 +278,7 @@ def getTickerFINRAdata(ticker: str) -> Tuple[pd.DataFrame, pd.DataFrame]:
|
||||
Stock ticker to get data from
|
||||
|
||||
Returns
|
||||
----------
|
||||
-------
|
||||
pd.DataFrame
|
||||
Dark Pools (ATS) Data
|
||||
pd.DataFrame
|
||||
@@ -188,117 +325,3 @@ def getTickerFINRAdata(ticker: str) -> Tuple[pd.DataFrame, pd.DataFrame]:
|
||||
df_otc = df_otc.set_index("weekStartDate")
|
||||
|
||||
return df_ats, df_otc
|
||||
|
||||
|
||||
def plot_dark_pools(ticker: str, ats: pd.DataFrame, otc: pd.DataFrame):
|
||||
"""Plots ATS and NON-ATS data
|
||||
|
||||
Parameters
|
||||
----------
|
||||
ticker : str
|
||||
Stock ticker to get data from
|
||||
ats : pd.DataFrame
|
||||
Dark Pools (ATS) Data
|
||||
otc : pd.DataFrame
|
||||
OTC (Non-ATS) Data
|
||||
"""
|
||||
_, _ = plt.subplots(figsize=plot_autoscale(), dpi=PLOT_DPI)
|
||||
|
||||
plt.subplot(3, 1, (1, 2))
|
||||
if not ats.empty and not otc.empty:
|
||||
plt.bar(
|
||||
ats.index,
|
||||
(ats["totalWeeklyShareQuantity"] + otc["totalWeeklyShareQuantity"])
|
||||
/ 1_000_000,
|
||||
color="tab:orange",
|
||||
)
|
||||
plt.bar(
|
||||
otc.index, otc["totalWeeklyShareQuantity"] / 1_000_000, color="tab:blue"
|
||||
)
|
||||
plt.legend(["ATS", "OTC"])
|
||||
|
||||
elif not ats.empty:
|
||||
plt.bar(
|
||||
ats.index,
|
||||
ats["totalWeeklyShareQuantity"] / 1_000_000,
|
||||
color="tab:orange",
|
||||
)
|
||||
plt.legend(["ATS"])
|
||||
|
||||
elif not otc.empty:
|
||||
plt.bar(
|
||||
otc.index, otc["totalWeeklyShareQuantity"] / 1_000_000, color="tab:blue"
|
||||
)
|
||||
plt.legend(["OTC"])
|
||||
|
||||
plt.ylabel("Total Weekly Shares [Million]")
|
||||
plt.grid(b=True, which="major", color="#666666", linestyle="-", alpha=0.2)
|
||||
plt.title(f"Dark Pools (ATS) vs OTC (Non-ATS) Data for {ticker}")
|
||||
|
||||
plt.subplot(313)
|
||||
if not ats.empty:
|
||||
plt.plot(
|
||||
ats.index,
|
||||
ats["totalWeeklyShareQuantity"] / ats["totalWeeklyTradeCount"],
|
||||
color="tab:orange",
|
||||
)
|
||||
plt.legend(["ATS"])
|
||||
|
||||
if not otc.empty:
|
||||
plt.plot(
|
||||
otc.index,
|
||||
otc["totalWeeklyShareQuantity"] / otc["totalWeeklyTradeCount"],
|
||||
color="tab:blue",
|
||||
)
|
||||
plt.legend(["ATS", "OTC"])
|
||||
|
||||
else:
|
||||
plt.plot(
|
||||
otc.index,
|
||||
otc["totalWeeklyShareQuantity"] / otc["totalWeeklyTradeCount"],
|
||||
color="tab:blue",
|
||||
)
|
||||
plt.legend(["OTC"])
|
||||
|
||||
plt.ylabel("Shares per Trade")
|
||||
plt.grid(b=True, which="major", color="#666666", linestyle="-", alpha=0.2)
|
||||
plt.gcf().autofmt_xdate()
|
||||
plt.xlabel("Weeks")
|
||||
|
||||
if gtff.USE_ION:
|
||||
plt.ion()
|
||||
|
||||
plt.show()
|
||||
|
||||
|
||||
def dark_pool(other_args: List[str], ticker: str):
|
||||
"""Display barchart of dark pool (ATS) and OTC (Non ATS) data
|
||||
|
||||
Parameters
|
||||
----------
|
||||
other_args : List[str]
|
||||
argparse other args
|
||||
ticker : str
|
||||
Stock ticker
|
||||
"""
|
||||
parser = argparse.ArgumentParser(
|
||||
add_help=False,
|
||||
formatter_class=argparse.ArgumentDefaultsHelpFormatter,
|
||||
prog="dp",
|
||||
description="Display barchart of dark pool (ATS) and OTC (Non ATS) data [Source: FINRA]",
|
||||
)
|
||||
try:
|
||||
ns_parser = parse_known_args_and_warn(parser, other_args)
|
||||
if not ns_parser:
|
||||
return
|
||||
|
||||
df_ats, df_otc = getTickerFINRAdata(ticker)
|
||||
|
||||
if df_ats.empty and df_otc.empty:
|
||||
print("No ticker data found!")
|
||||
|
||||
plot_dark_pools(ticker, df_ats, df_otc)
|
||||
print("")
|
||||
|
||||
except Exception as e:
|
||||
print(e, "\n")
|
||||
164
gamestonk_terminal/stocks/dark_pool_shorts/finra_view.py
Normal file
164
gamestonk_terminal/stocks/dark_pool_shorts/finra_view.py
Normal file
@@ -0,0 +1,164 @@
|
||||
""" FINRA View """
|
||||
__docformat__ = "numpy"
|
||||
|
||||
from typing import List
|
||||
import pandas as pd
|
||||
from matplotlib import pyplot as plt
|
||||
from gamestonk_terminal.stocks.dark_pool_shorts import finra_model
|
||||
from gamestonk_terminal.config_plot import PLOT_DPI
|
||||
from gamestonk_terminal import feature_flags as gtff
|
||||
from gamestonk_terminal.helper_funcs import plot_autoscale
|
||||
|
||||
|
||||
def plot_dark_pools(ticker: str, ats: pd.DataFrame, otc: pd.DataFrame):
|
||||
"""Plots ATS and NON-ATS data
|
||||
|
||||
Parameters
|
||||
----------
|
||||
ticker : str
|
||||
Stock ticker to get data from
|
||||
ats : pd.DataFrame
|
||||
Dark Pools (ATS) Data
|
||||
otc : pd.DataFrame
|
||||
OTC (Non-ATS) Data
|
||||
"""
|
||||
_, _ = plt.subplots(figsize=plot_autoscale(), dpi=PLOT_DPI)
|
||||
|
||||
plt.subplot(3, 1, (1, 2))
|
||||
if not ats.empty and not otc.empty:
|
||||
plt.bar(
|
||||
ats.index,
|
||||
(ats["totalWeeklyShareQuantity"] + otc["totalWeeklyShareQuantity"])
|
||||
/ 1_000_000,
|
||||
color="tab:orange",
|
||||
)
|
||||
plt.bar(
|
||||
otc.index, otc["totalWeeklyShareQuantity"] / 1_000_000, color="tab:blue"
|
||||
)
|
||||
plt.legend(["ATS", "OTC"])
|
||||
|
||||
elif not ats.empty:
|
||||
plt.bar(
|
||||
ats.index,
|
||||
ats["totalWeeklyShareQuantity"] / 1_000_000,
|
||||
color="tab:orange",
|
||||
)
|
||||
plt.legend(["ATS"])
|
||||
|
||||
elif not otc.empty:
|
||||
plt.bar(
|
||||
otc.index, otc["totalWeeklyShareQuantity"] / 1_000_000, color="tab:blue"
|
||||
)
|
||||
plt.legend(["OTC"])
|
||||
|
||||
plt.ylabel("Total Weekly Shares [Million]")
|
||||
plt.grid(b=True, which="major", color="#666666", linestyle="-", alpha=0.2)
|
||||
plt.title(f"Dark Pools (ATS) vs OTC (Non-ATS) Data for {ticker}")
|
||||
|
||||
plt.subplot(313)
|
||||
if not ats.empty:
|
||||
plt.plot(
|
||||
ats.index,
|
||||
ats["totalWeeklyShareQuantity"] / ats["totalWeeklyTradeCount"],
|
||||
color="tab:orange",
|
||||
)
|
||||
plt.legend(["ATS"])
|
||||
|
||||
if not otc.empty:
|
||||
plt.plot(
|
||||
otc.index,
|
||||
otc["totalWeeklyShareQuantity"] / otc["totalWeeklyTradeCount"],
|
||||
color="tab:blue",
|
||||
)
|
||||
plt.legend(["ATS", "OTC"])
|
||||
|
||||
else:
|
||||
plt.plot(
|
||||
otc.index,
|
||||
otc["totalWeeklyShareQuantity"] / otc["totalWeeklyTradeCount"],
|
||||
color="tab:blue",
|
||||
)
|
||||
plt.legend(["OTC"])
|
||||
|
||||
plt.ylabel("Shares per Trade")
|
||||
plt.grid(b=True, which="major", color="#666666", linestyle="-", alpha=0.2)
|
||||
plt.gcf().autofmt_xdate()
|
||||
plt.xlabel("Weeks")
|
||||
|
||||
if gtff.USE_ION:
|
||||
plt.ion()
|
||||
|
||||
plt.show()
|
||||
|
||||
|
||||
def darkpool_ats_otc(ticker: str):
|
||||
"""Display barchart of dark pool (ATS) and OTC (Non ATS) data
|
||||
|
||||
Parameters
|
||||
----------
|
||||
ticker : str
|
||||
Stock ticker
|
||||
"""
|
||||
df_ats, df_otc = finra_model.getTickerFINRAdata(ticker)
|
||||
|
||||
if df_ats.empty and df_otc.empty:
|
||||
print("No ticker data found!")
|
||||
|
||||
plot_dark_pools(ticker, df_ats, df_otc)
|
||||
print("")
|
||||
|
||||
|
||||
def plot_dark_pools_ats(ats: pd.DataFrame, top_ats_tickers: List):
|
||||
"""Plots promising tickers based on growing ATS data
|
||||
|
||||
Parameters
|
||||
----------
|
||||
ats : pd.DataFrame
|
||||
Dark Pools (ATS) Data
|
||||
top_ats_tickers : List
|
||||
List of tickers from most promising with better linear regression slope
|
||||
"""
|
||||
plt.figure(figsize=plot_autoscale(), dpi=PLOT_DPI)
|
||||
|
||||
for symbol in top_ats_tickers:
|
||||
plt.plot(
|
||||
pd.to_datetime(
|
||||
ats[ats["issueSymbolIdentifier"] == symbol]["weekStartDate"]
|
||||
),
|
||||
ats[ats["issueSymbolIdentifier"] == symbol]["totalWeeklyShareQuantity"]
|
||||
/ 1_000_000,
|
||||
)
|
||||
|
||||
plt.legend(top_ats_tickers)
|
||||
plt.ylabel("Total Weekly Shares [Million]")
|
||||
plt.grid(b=True, which="major", color="#666666", linestyle="-", alpha=0.2)
|
||||
plt.title("Dark Pool (ATS) growing tickers")
|
||||
plt.gcf().autofmt_xdate()
|
||||
plt.xlabel("Weeks")
|
||||
|
||||
if gtff.USE_ION:
|
||||
plt.ion()
|
||||
|
||||
plt.show()
|
||||
|
||||
|
||||
def darkpool_otc(num: int, promising: int):
|
||||
"""Display dark pool (ATS) data of tickers with growing trades activity
|
||||
|
||||
Parameters
|
||||
----------
|
||||
num : int
|
||||
Number of tickers to filter from entire ATS data based on
|
||||
the sum of the total weekly shares quantity
|
||||
promising : int
|
||||
Number of tickers to display from most promising with
|
||||
better linear regression slope
|
||||
"""
|
||||
df_ats, d_ats_reg = finra_model.getATSdata(num)
|
||||
|
||||
top_ats_tickers = list(
|
||||
dict(sorted(d_ats_reg.items(), key=lambda item: item[1], reverse=True)).keys()
|
||||
)[:promising]
|
||||
|
||||
plot_dark_pools_ats(df_ats, top_ats_tickers)
|
||||
print("")
|
||||
31
gamestonk_terminal/stocks/dark_pool_shorts/quandl_model.py
Normal file
31
gamestonk_terminal/stocks/dark_pool_shorts/quandl_model.py
Normal file
@@ -0,0 +1,31 @@
|
||||
""" Quandl Model """
|
||||
__docformat__ = "numpy"
|
||||
|
||||
import quandl
|
||||
import pandas as pd
|
||||
from gamestonk_terminal import config_terminal as cfg
|
||||
|
||||
|
||||
def get_short_interest(ticker: str, nyse: bool) -> pd.DataFrame:
|
||||
"""Plots the short interest of a stock. This corresponds to the
|
||||
number of shares that have been sold short but have not yet been
|
||||
covered or closed out. Either NASDAQ or NYSE [Source: Quandl]
|
||||
|
||||
Parameters
|
||||
----------
|
||||
ticker : str
|
||||
ticker to get short interest from
|
||||
nyse : bool
|
||||
data from NYSE if true, otherwise NASDAQ
|
||||
|
||||
Returns
|
||||
----------
|
||||
pd.DataFrame
|
||||
short interest volume data
|
||||
"""
|
||||
quandl.ApiConfig.api_key = cfg.API_KEY_QUANDL
|
||||
|
||||
if nyse:
|
||||
return quandl.get(f"FINRA/FNYX_{ticker}")
|
||||
|
||||
return quandl.get(f"FINRA/FNSQ_{ticker}")
|
||||
119
gamestonk_terminal/stocks/dark_pool_shorts/quandl_view.py
Normal file
119
gamestonk_terminal/stocks/dark_pool_shorts/quandl_view.py
Normal file
@@ -0,0 +1,119 @@
|
||||
""" Quandl View """
|
||||
__docformat__ = "numpy"
|
||||
|
||||
import os
|
||||
import matplotlib.ticker
|
||||
from matplotlib import pyplot as plt
|
||||
import pandas as pd
|
||||
from gamestonk_terminal.stocks.dark_pool_shorts import quandl_model
|
||||
from gamestonk_terminal.helper_funcs import (
|
||||
long_number_format,
|
||||
export_data,
|
||||
)
|
||||
|
||||
|
||||
def plot_short_interest(
|
||||
ticker: str, start: str, nyse: bool, days: int, df_short_interest: pd.DataFrame
|
||||
):
|
||||
"""Plots the short interest of a stock. This corresponds to the
|
||||
number of shares that have been sold short but have not yet been
|
||||
covered or closed out. Either NASDAQ or NYSE [Source: Quandl]
|
||||
|
||||
Parameters
|
||||
----------
|
||||
ticker : str
|
||||
ticker to get short interest from
|
||||
start : str
|
||||
start date to start displaying short interest volume
|
||||
nyse : bool
|
||||
data from NYSE if true, otherwise NASDAQ
|
||||
days : int
|
||||
Number of past days to show short interest
|
||||
df_short_interest: pd.DataFrame
|
||||
Short interest dataframe
|
||||
"""
|
||||
df_short_interest = df_short_interest[start:] # type: ignore
|
||||
df_short_interest.columns = [
|
||||
"".join(" " + char if char.isupper() else char.strip() for char in idx).strip()
|
||||
for idx in df_short_interest.columns.tolist()
|
||||
]
|
||||
df_short_interest["% of Volume Shorted"] = round(
|
||||
100 * df_short_interest["Short Volume"] / df_short_interest["Total Volume"],
|
||||
2,
|
||||
)
|
||||
|
||||
_, ax = plt.subplots()
|
||||
ax.bar(df_short_interest.index, df_short_interest["Short Volume"], 0.3, color="r")
|
||||
ax.bar(
|
||||
df_short_interest.index,
|
||||
df_short_interest["Total Volume"] - df_short_interest["Short Volume"],
|
||||
0.3,
|
||||
bottom=df_short_interest["Short Volume"],
|
||||
color="b",
|
||||
)
|
||||
ax.set_ylabel("Shares")
|
||||
ax.set_xlabel("Date")
|
||||
|
||||
if start:
|
||||
ax.set_title(
|
||||
f"{('NASDAQ', 'NYSE')[nyse]} Short Interest on {ticker} from {start.date()}" # type: ignore
|
||||
)
|
||||
else:
|
||||
ax.set_title(f"{('NASDAQ', 'NYSE')[nyse]} Short Interest on {ticker}")
|
||||
|
||||
ax.legend(labels=["Short Volume", "Total Volume"])
|
||||
ax.tick_params(axis="both", which="major")
|
||||
ax.yaxis.set_major_formatter(matplotlib.ticker.EngFormatter())
|
||||
ax_twin = ax.twinx()
|
||||
ax_twin.tick_params(axis="y", colors="green")
|
||||
ax_twin.set_ylabel("Percentage of Volume Shorted", color="green")
|
||||
ax_twin.plot(
|
||||
df_short_interest.index,
|
||||
df_short_interest["% of Volume Shorted"],
|
||||
color="green",
|
||||
)
|
||||
ax_twin.tick_params(axis="y", which="major", color="green")
|
||||
ax_twin.yaxis.set_major_formatter(matplotlib.ticker.FormatStrFormatter("%.0f%%"))
|
||||
plt.xlim([df_short_interest.index[0], df_short_interest.index[-1]])
|
||||
|
||||
df_short_interest["% of Volume Shorted"] = df_short_interest[
|
||||
"% of Volume Shorted"
|
||||
].apply(lambda x: f"{x/100:.2%}")
|
||||
df_short_interest = df_short_interest.applymap(
|
||||
lambda x: long_number_format(x)
|
||||
).sort_index(ascending=False)
|
||||
|
||||
pd.set_option("display.max_colwidth", 70)
|
||||
print(df_short_interest.head(n=days).to_string())
|
||||
print("")
|
||||
plt.show()
|
||||
|
||||
|
||||
def short_interest(ticker: str, start: str, nyse: bool, days: int, export: str):
|
||||
"""Plots the short interest of a stock. This corresponds to the
|
||||
number of shares that have been sold short but have not yet been
|
||||
covered or closed out. Either NASDAQ or NYSE [Source: Quandl]
|
||||
|
||||
Parameters
|
||||
----------
|
||||
ticker : str
|
||||
ticker to get short interest from
|
||||
start : str
|
||||
start date to start displaying short interest volume
|
||||
nyse : bool
|
||||
data from NYSE if true, otherwise NASDAQ
|
||||
days : int
|
||||
Number of past days to show short interest
|
||||
export : str
|
||||
Export dataframe data to csv,json,xlsx file
|
||||
"""
|
||||
df_short_interest = quandl_model.get_short_interest(ticker, nyse)
|
||||
|
||||
plot_short_interest(ticker, start, nyse, days, df_short_interest)
|
||||
|
||||
export_data(
|
||||
export,
|
||||
os.path.dirname(os.path.abspath(__file__)),
|
||||
"shortint(quandl)",
|
||||
df_short_interest,
|
||||
)
|
||||
125
gamestonk_terminal/stocks/dark_pool_shorts/sec_model.py
Normal file
125
gamestonk_terminal/stocks/dark_pool_shorts/sec_model.py
Normal file
@@ -0,0 +1,125 @@
|
||||
""" SEC Model """
|
||||
__docformat__ = "numpy"
|
||||
|
||||
from datetime import datetime
|
||||
import requests
|
||||
import pandas as pd
|
||||
from bs4 import BeautifulSoup
|
||||
from gamestonk_terminal.helper_funcs import get_user_agent
|
||||
|
||||
|
||||
def get_fails_to_deliver(
|
||||
ticker: str,
|
||||
start: datetime,
|
||||
end: datetime,
|
||||
num: int,
|
||||
):
|
||||
"""Display fails-to-deliver data for a given ticker. [Source: SEC]
|
||||
|
||||
Parameters
|
||||
----------
|
||||
ticker : str
|
||||
Stock ticker
|
||||
start : datetime
|
||||
Start of data
|
||||
end : datetime
|
||||
End of data
|
||||
num : int
|
||||
Number of latest fails-to-deliver being printed
|
||||
"""
|
||||
ftds_data = pd.DataFrame()
|
||||
|
||||
# Filter by number of last FTD
|
||||
if num > 0:
|
||||
url_ftds = "https://www.sec.gov/data/foiadocsfailsdatahtm"
|
||||
text_soup_ftds = BeautifulSoup(
|
||||
requests.get(url_ftds, headers={"User-Agent": get_user_agent()}).text,
|
||||
"lxml",
|
||||
)
|
||||
|
||||
table = text_soup_ftds.find("table", {"class": "list"})
|
||||
links = table.findAll("a")
|
||||
link_idx = 0
|
||||
|
||||
while len(ftds_data) < num:
|
||||
if link_idx > len(links):
|
||||
break
|
||||
link = links[link_idx]
|
||||
url = "https://www.sec.gov" + link["href"]
|
||||
all_ftds = pd.read_csv(
|
||||
url,
|
||||
compression="zip",
|
||||
sep="|",
|
||||
engine="python",
|
||||
skipfooter=2,
|
||||
usecols=[0, 2, 3, 5],
|
||||
dtype={"QUANTITY (FAILS)": "int"},
|
||||
)
|
||||
tmp_ftds = all_ftds[all_ftds["SYMBOL"] == ticker]
|
||||
del tmp_ftds["PRICE"]
|
||||
del tmp_ftds["SYMBOL"]
|
||||
# merge the data from this archive
|
||||
ftds_data = pd.concat([ftds_data, tmp_ftds], ignore_index=True)
|
||||
link_idx += 1
|
||||
|
||||
# clip away extra rows
|
||||
ftds_data = ftds_data.sort_values("SETTLEMENT DATE")[-num:]
|
||||
|
||||
ftds_data["SETTLEMENT DATE"] = ftds_data["SETTLEMENT DATE"].apply(
|
||||
lambda x: datetime.strptime(str(x), "%Y%m%d")
|
||||
)
|
||||
|
||||
# Filter by start and end dates for FTD
|
||||
else:
|
||||
base_url = "https://www.sec.gov/files/data/fails-deliver-data/cnsfails"
|
||||
ftd_dates = list()
|
||||
|
||||
for y in range(start.year, end.year + 1):
|
||||
if y < end.year:
|
||||
for m in range(start.month, 13):
|
||||
month = "%02d" % m
|
||||
if m == start.month and y == start.year:
|
||||
if start.day < 16:
|
||||
ftd_dates.append(str(y) + month + "a")
|
||||
ftd_dates.append(str(y) + month + "b")
|
||||
else:
|
||||
ftd_dates.append(str(y) + month + "a")
|
||||
ftd_dates.append(str(y) + month + "b")
|
||||
|
||||
else:
|
||||
for m in range(1, end.month):
|
||||
month = "%02d" % m
|
||||
if m == end.month - 1:
|
||||
ftd_dates.append(str(y) + month + "a")
|
||||
if end.day > 15:
|
||||
ftd_dates.append(str(y) + month + "b")
|
||||
else:
|
||||
ftd_dates.append(str(y) + month + "a")
|
||||
ftd_dates.append(str(y) + month + "b")
|
||||
|
||||
ftd_urls = [base_url + ftd_date + ".zip" for ftd_date in ftd_dates]
|
||||
|
||||
for ftd_link in ftd_urls:
|
||||
all_ftds = pd.read_csv(
|
||||
ftd_link,
|
||||
compression="zip",
|
||||
sep="|",
|
||||
engine="python",
|
||||
skipfooter=2,
|
||||
usecols=[0, 2, 3, 5],
|
||||
dtype={"QUANTITY (FAILS)": "int"},
|
||||
)
|
||||
tmp_ftds = all_ftds[all_ftds["SYMBOL"] == ticker]
|
||||
del tmp_ftds["PRICE"]
|
||||
del tmp_ftds["SYMBOL"]
|
||||
# merge the data from this archive
|
||||
ftds_data = pd.concat([ftds_data, tmp_ftds], ignore_index=True)
|
||||
|
||||
ftds_data["SETTLEMENT DATE"] = ftds_data["SETTLEMENT DATE"].apply(
|
||||
lambda x: datetime.strptime(str(x), "%Y%m%d")
|
||||
)
|
||||
|
||||
ftds_data = ftds_data[ftds_data["SETTLEMENT DATE"] > start]
|
||||
ftds_data = ftds_data[ftds_data["SETTLEMENT DATE"] < end]
|
||||
|
||||
return ftds_data
|
||||
90
gamestonk_terminal/stocks/dark_pool_shorts/sec_view.py
Normal file
90
gamestonk_terminal/stocks/dark_pool_shorts/sec_view.py
Normal file
@@ -0,0 +1,90 @@
|
||||
""" SEC View """
|
||||
__docformat__ = "numpy"
|
||||
|
||||
import os
|
||||
from datetime import datetime, timedelta
|
||||
from tabulate import tabulate
|
||||
import pandas as pd
|
||||
from matplotlib import pyplot as plt
|
||||
import matplotlib.dates as mdates
|
||||
from gamestonk_terminal.stocks.dark_pool_shorts import sec_model
|
||||
from gamestonk_terminal import feature_flags as gtff
|
||||
from gamestonk_terminal.helper_funcs import export_data
|
||||
|
||||
|
||||
def fails_to_deliver(
|
||||
ticker: str,
|
||||
stock: pd.DataFrame,
|
||||
start: datetime,
|
||||
end: datetime,
|
||||
num: int,
|
||||
raw: bool,
|
||||
export: str,
|
||||
):
|
||||
"""Display fails-to-deliver data for a given ticker. [Source: SEC]
|
||||
|
||||
Parameters
|
||||
----------
|
||||
ticker : str
|
||||
Stock ticker
|
||||
stock : pd.DataFrame
|
||||
Stock data
|
||||
start : datetime
|
||||
Start of data
|
||||
end : datetime
|
||||
End of data
|
||||
num : int
|
||||
Number of latest fails-to-deliver being printed
|
||||
raw : bool
|
||||
Print raw data
|
||||
export : str
|
||||
Export dataframe data to csv,json,xlsx file
|
||||
"""
|
||||
ftds_data = sec_model.get_fails_to_deliver(ticker, start, end, num)
|
||||
|
||||
plt.bar(
|
||||
ftds_data["SETTLEMENT DATE"],
|
||||
ftds_data["QUANTITY (FAILS)"] / 1000,
|
||||
)
|
||||
plt.ylabel("Shares [K]")
|
||||
plt.title(f"Fails-to-deliver Data for {ticker}")
|
||||
plt.grid(b=True, which="major", color="#666666", linestyle="-", alpha=0.2)
|
||||
plt.gca().xaxis.set_major_formatter(mdates.DateFormatter("%Y/%m/%d"))
|
||||
plt.gca().xaxis.set_major_locator(mdates.DayLocator(interval=7))
|
||||
plt.gcf().autofmt_xdate()
|
||||
plt.xlabel("Days")
|
||||
|
||||
_ = plt.gca().twinx()
|
||||
|
||||
if num > 0:
|
||||
stock_ftd = stock[stock.index > (datetime.now() - timedelta(days=num + 31))]
|
||||
else:
|
||||
stock_ftd = stock[stock.index > start]
|
||||
stock_ftd = stock_ftd[stock_ftd.index < end]
|
||||
plt.plot(stock_ftd.index, stock_ftd["Adj Close"], color="tab:orange")
|
||||
plt.ylabel("Share Price [$]")
|
||||
|
||||
if gtff.USE_ION:
|
||||
plt.ion()
|
||||
|
||||
plt.show()
|
||||
print("")
|
||||
|
||||
if raw:
|
||||
print(
|
||||
tabulate(
|
||||
ftds_data,
|
||||
headers=ftds_data.columns,
|
||||
tablefmt="fancy_grid",
|
||||
stralign="right",
|
||||
showindex=False,
|
||||
)
|
||||
)
|
||||
print("")
|
||||
|
||||
export_data(
|
||||
export,
|
||||
os.path.dirname(os.path.abspath(__file__)),
|
||||
"ftd",
|
||||
ftds_data.reset_index(),
|
||||
)
|
||||
@@ -0,0 +1,58 @@
|
||||
""" Short Interest View """
|
||||
__docformat__ = "numpy"
|
||||
|
||||
import requests
|
||||
from bs4 import BeautifulSoup
|
||||
import pandas as pd
|
||||
from pandas.core.frame import DataFrame
|
||||
|
||||
from gamestonk_terminal.helper_funcs import get_user_agent
|
||||
|
||||
|
||||
def get_high_short_interest() -> DataFrame:
|
||||
"""Returns a high short interest DataFrame
|
||||
|
||||
Returns
|
||||
-------
|
||||
DataFrame
|
||||
High short interest Dataframe with the following columns:
|
||||
Ticker, Company, Exchange, ShortInt, Float, Outstd, Industry
|
||||
"""
|
||||
url_high_short_interested_stocks = "https://www.highshortinterest.com"
|
||||
|
||||
text_soup_high_short_interested_stocks = BeautifulSoup(
|
||||
requests.get(
|
||||
url_high_short_interested_stocks, headers={"User-Agent": get_user_agent()}
|
||||
).text,
|
||||
"lxml",
|
||||
)
|
||||
|
||||
a_high_short_interest_header = list()
|
||||
for high_short_interest_header in text_soup_high_short_interested_stocks.findAll(
|
||||
"td", {"class": "tblhdr"}
|
||||
):
|
||||
a_high_short_interest_header.append(
|
||||
high_short_interest_header.text.strip("\n").split("\n")[0]
|
||||
)
|
||||
df_high_short_interest = pd.DataFrame(columns=a_high_short_interest_header)
|
||||
df_high_short_interest.loc[0] = ["", "", "", "", "", "", ""]
|
||||
|
||||
stock_list_tr = text_soup_high_short_interested_stocks.find_all("tr")
|
||||
|
||||
shorted_stock_data = list()
|
||||
for a_stock in stock_list_tr:
|
||||
a_stock_txt = a_stock.text
|
||||
|
||||
if a_stock_txt == "":
|
||||
continue
|
||||
|
||||
shorted_stock_data = a_stock_txt.split("\n")
|
||||
|
||||
if len(shorted_stock_data) == 8:
|
||||
df_high_short_interest.loc[
|
||||
len(df_high_short_interest.index)
|
||||
] = shorted_stock_data[:-1]
|
||||
|
||||
shorted_stock_data = list()
|
||||
|
||||
return df_high_short_interest
|
||||
@@ -0,0 +1,40 @@
|
||||
""" Short Interest View """
|
||||
__docformat__ = "numpy"
|
||||
|
||||
import os
|
||||
from tabulate import tabulate
|
||||
from gamestonk_terminal.helper_funcs import export_data
|
||||
|
||||
from gamestonk_terminal.stocks.dark_pool_shorts import shortinterest_model
|
||||
|
||||
|
||||
def high_short_interest(num: int, export: str):
|
||||
"""Prints top N high shorted interest stocks from https://www.highshortinterest.com
|
||||
|
||||
Parameters
|
||||
----------
|
||||
num: int
|
||||
Number of stocks to display
|
||||
export : str
|
||||
Export dataframe data to csv,json,xlsx file
|
||||
"""
|
||||
df_high_short_interest = shortinterest_model.get_high_short_interest()
|
||||
df_high_short_interest = df_high_short_interest.iloc[1:].head(n=num)
|
||||
|
||||
print(
|
||||
tabulate(
|
||||
df_high_short_interest,
|
||||
headers=df_high_short_interest.columns,
|
||||
floatfmt=".2f",
|
||||
showindex=False,
|
||||
tablefmt="fancy_grid",
|
||||
),
|
||||
"\n",
|
||||
)
|
||||
|
||||
export_data(
|
||||
export,
|
||||
os.path.dirname(os.path.abspath(__file__)),
|
||||
"lowfloat",
|
||||
df_high_short_interest,
|
||||
)
|
||||
141
gamestonk_terminal/stocks/dark_pool_shorts/stockgrid_model.py
Normal file
141
gamestonk_terminal/stocks/dark_pool_shorts/stockgrid_model.py
Normal file
@@ -0,0 +1,141 @@
|
||||
""" Stockgrid View """
|
||||
__docformat__ = "numpy"
|
||||
|
||||
from typing import List, Tuple
|
||||
import requests
|
||||
import pandas as pd
|
||||
|
||||
|
||||
def get_dark_pool_short_positions(sort_field: str, ascending: bool) -> pd.DataFrame:
|
||||
"""Get dark pool short positions. [Source: Stockgrid]
|
||||
|
||||
Parameters
|
||||
----------
|
||||
sort_field : str
|
||||
Field for which to sort by, where 'sv': Short Vol. (1M),
|
||||
'sv_pct': Short Vol. %%, 'nsv': Net Short Vol. (1M),
|
||||
'nsv_dollar': Net Short Vol. ($100M), 'dpp': DP Position (1M),
|
||||
'dpp_dollar': DP Position ($1B)
|
||||
ascending : bool
|
||||
Data in ascending order
|
||||
|
||||
Returns
|
||||
----------
|
||||
pd.DataFrame
|
||||
Dark pool short position data
|
||||
"""
|
||||
d_fields_endpoints = {
|
||||
"sv": "Short+Volume",
|
||||
"sv_pct": "Short+Volume+%25",
|
||||
"nsv": "Net+Short+Volume",
|
||||
"nsv_dollar": "Net+Short+Volume+$",
|
||||
"dpp": "Dark+Pools+Position",
|
||||
"dpp_dollar": "Dark+Pools+Position+$",
|
||||
}
|
||||
|
||||
field = d_fields_endpoints[sort_field]
|
||||
|
||||
if ascending:
|
||||
order = "asc"
|
||||
else:
|
||||
order = "desc"
|
||||
|
||||
link = f"https://stockgridapp.herokuapp.com/get_dark_pool_data?top={field}&minmax={order}"
|
||||
|
||||
response = requests.get(link)
|
||||
df = pd.DataFrame(response.json()["data"])
|
||||
|
||||
df = df[
|
||||
[
|
||||
"Ticker",
|
||||
"Date",
|
||||
"Short Volume",
|
||||
"Short Volume %",
|
||||
"Net Short Volume",
|
||||
"Net Short Volume $",
|
||||
"Dark Pools Position",
|
||||
"Dark Pools Position $",
|
||||
]
|
||||
]
|
||||
|
||||
return df
|
||||
|
||||
|
||||
def get_short_interest_days_to_cover(sort_field: str) -> pd.DataFrame:
|
||||
"""Get short interest and days to cover. [Source: Stockgrid]
|
||||
|
||||
Parameters
|
||||
----------
|
||||
sort_field : str
|
||||
Field for which to sort by, where 'float': Float Short %%,
|
||||
'dtc': Days to Cover, 'si': Short Interest
|
||||
|
||||
Returns
|
||||
----------
|
||||
pd.DataFrame
|
||||
Short interest and days to cover data
|
||||
"""
|
||||
link = "https://stockgridapp.herokuapp.com/get_short_interest?top=days"
|
||||
r = requests.get(link)
|
||||
df = pd.DataFrame(r.json()["data"])
|
||||
|
||||
d_fields = {
|
||||
"float": "%Float Short",
|
||||
"dtc": "Days To Cover",
|
||||
"si": "Short Interest",
|
||||
}
|
||||
|
||||
df = df[
|
||||
["Ticker", "Date", "%Float Short", "Days To Cover", "Short Interest"]
|
||||
].sort_values(
|
||||
by=d_fields[sort_field],
|
||||
ascending=bool(sort_field == "dtc"),
|
||||
)
|
||||
|
||||
return df
|
||||
|
||||
|
||||
def get_short_interest_volume(ticker: str) -> Tuple[pd.DataFrame, List]:
|
||||
"""Get price vs short interest volume. [Source: Stockgrid]
|
||||
|
||||
Parameters
|
||||
----------
|
||||
ticker : str
|
||||
Stock to get data from
|
||||
|
||||
Returns
|
||||
----------
|
||||
pd.DataFrame
|
||||
Short interest volume data
|
||||
List
|
||||
Price data
|
||||
"""
|
||||
link = f"https://stockgridapp.herokuapp.com/get_dark_pool_individual_data?ticker={ticker}"
|
||||
response = requests.get(link)
|
||||
|
||||
df = pd.DataFrame(response.json()["individual_short_volume_table"]["data"])
|
||||
df["date"] = pd.to_datetime(df["date"])
|
||||
|
||||
return df, response.json()["prices"]["prices"]
|
||||
|
||||
|
||||
def get_net_short_position(ticker: str) -> pd.DataFrame:
|
||||
"""Get net short position. [Source: Stockgrid]
|
||||
|
||||
Parameters
|
||||
----------
|
||||
ticker: str
|
||||
Stock to get data from
|
||||
|
||||
Returns
|
||||
----------
|
||||
pd.DataFrame
|
||||
Net short position
|
||||
"""
|
||||
link = f"https://stockgridapp.herokuapp.com/get_dark_pool_individual_data?ticker={ticker}"
|
||||
response = requests.get(link)
|
||||
|
||||
df = pd.DataFrame(response.json()["individual_dark_pool_position_data"])
|
||||
df["dates"] = pd.to_datetime(df["dates"])
|
||||
|
||||
return df
|
||||
334
gamestonk_terminal/stocks/dark_pool_shorts/stockgrid_view.py
Normal file
334
gamestonk_terminal/stocks/dark_pool_shorts/stockgrid_view.py
Normal file
@@ -0,0 +1,334 @@
|
||||
""" Stockgrid View """
|
||||
__docformat__ = "numpy"
|
||||
|
||||
import os
|
||||
from datetime import timedelta
|
||||
import matplotlib.pyplot as plt
|
||||
from tabulate import tabulate
|
||||
from gamestonk_terminal.config_plot import PLOT_DPI
|
||||
from gamestonk_terminal.feature_flags import USE_ION
|
||||
from gamestonk_terminal.stocks.dark_pool_shorts import stockgrid_model
|
||||
from gamestonk_terminal.helper_funcs import (
|
||||
plot_autoscale,
|
||||
export_data,
|
||||
)
|
||||
|
||||
|
||||
def dark_pool_short_positions(num: int, sort_field: str, ascending: bool, export: str):
|
||||
"""Get dark pool short positions. [Source: Stockgrid]
|
||||
|
||||
Parameters
|
||||
----------
|
||||
num : int
|
||||
Number of top tickers to show
|
||||
sort_field : str
|
||||
Field for which to sort by, where 'sv': Short Vol. (1M),
|
||||
'sv_pct': Short Vol. %%, 'nsv': Net Short Vol. (1M),
|
||||
'nsv_dollar': Net Short Vol. ($100M), 'dpp': DP Position (1M),
|
||||
'dpp_dollar': DP Position ($1B)
|
||||
ascending : bool
|
||||
Data in ascending order
|
||||
export : str
|
||||
Export dataframe data to csv,json,xlsx file
|
||||
"""
|
||||
df = stockgrid_model.get_dark_pool_short_positions(sort_field, ascending)
|
||||
|
||||
dp_date = df["Date"].values[0]
|
||||
df = df.drop(columns=["Date"])
|
||||
df["Net Short Volume $"] = df["Net Short Volume $"] / 100_000_000
|
||||
df["Short Volume"] = df["Short Volume"] / 1_000_000
|
||||
df["Net Short Volume"] = df["Net Short Volume"] / 1_000_000
|
||||
df["Short Volume %"] = df["Short Volume %"] * 100
|
||||
df["Dark Pools Position $"] = df["Dark Pools Position $"] / (1_000_000_000)
|
||||
df["Dark Pools Position"] = df["Dark Pools Position"] / 1_000_000
|
||||
df.columns = [
|
||||
"Ticker",
|
||||
"Short Vol. (1M)",
|
||||
"Short Vol. %",
|
||||
"Net Short Vol. (1M)",
|
||||
"Net Short Vol. ($100M)",
|
||||
"DP Position (1M)",
|
||||
"DP Position ($1B)",
|
||||
]
|
||||
|
||||
# Assuming that the datetime is the same, which from my experiments seems to be the case
|
||||
print(f"The following data corresponds to the date: {dp_date}")
|
||||
print(
|
||||
tabulate(
|
||||
df.iloc[:num],
|
||||
tablefmt="fancy_grid",
|
||||
floatfmt=".2f",
|
||||
headers=list(df.columns),
|
||||
showindex=False,
|
||||
)
|
||||
)
|
||||
print("")
|
||||
|
||||
export_data(
|
||||
export,
|
||||
os.path.dirname(os.path.abspath(__file__)),
|
||||
"dppos",
|
||||
df,
|
||||
)
|
||||
|
||||
|
||||
def short_interest_days_to_cover(num: int, sort_field: str, export: str):
|
||||
"""Print short interest and days to cover. [Source: Stockgrid]
|
||||
|
||||
Parameters
|
||||
----------
|
||||
num : int
|
||||
Number of top tickers to show
|
||||
sort_field : str
|
||||
Field for which to sort by, where 'float': Float Short %%,
|
||||
'dtc': Days to Cover, 'si': Short Interest
|
||||
export : str
|
||||
Export dataframe data to csv,json,xlsx file
|
||||
"""
|
||||
df = stockgrid_model.get_short_interest_days_to_cover(sort_field)
|
||||
|
||||
dp_date = df["Date"].values[0]
|
||||
df = df.drop(columns=["Date"])
|
||||
df["Short Interest"] = df["Short Interest"] / 1_000_000
|
||||
df.head()
|
||||
df.columns = [
|
||||
"Ticker",
|
||||
"Float Short %",
|
||||
"Days to Cover",
|
||||
"Short Interest (1M)",
|
||||
]
|
||||
|
||||
# Assuming that the datetime is the same, which from my experiments seems to be the case
|
||||
print(f"The following data corresponds to the date: {dp_date}")
|
||||
print(
|
||||
tabulate(
|
||||
df.iloc[:num],
|
||||
tablefmt="fancy_grid",
|
||||
floatfmt=".2f",
|
||||
headers=list(df.columns),
|
||||
showindex=False,
|
||||
)
|
||||
)
|
||||
print("")
|
||||
|
||||
export_data(
|
||||
export,
|
||||
os.path.dirname(os.path.abspath(__file__)),
|
||||
"shortdtc",
|
||||
df,
|
||||
)
|
||||
|
||||
|
||||
def short_interest_volume(ticker: str, num: int, raw: bool, export: str):
|
||||
"""Plot price vs short interest volume. [Source: Stockgrid]
|
||||
|
||||
Parameters
|
||||
----------
|
||||
ticker : str
|
||||
Stock to plot for
|
||||
num : int
|
||||
Number of last open market days to show
|
||||
raw : bool
|
||||
Flag to print raw data instead
|
||||
export : str
|
||||
Export dataframe data to csv,json,xlsx file
|
||||
"""
|
||||
df, prices = stockgrid_model.get_short_interest_volume(ticker)
|
||||
|
||||
if raw:
|
||||
df = df.sort_values(by="date", ascending=False)
|
||||
|
||||
df["Short Vol. (1M)"] = df["short_volume"] / 1_000_000
|
||||
df["Short Vol. %"] = df["short_volume%"] * 100
|
||||
df["Short Exempt Vol. (1K)"] = df["short_exempt_volume"] / 1_000
|
||||
df["Total Vol. (1M)"] = df["total_volume"] / 1_000_000
|
||||
|
||||
df = df[
|
||||
[
|
||||
"date",
|
||||
"Short Vol. (1M)",
|
||||
"Short Vol. %",
|
||||
"Short Exempt Vol. (1K)",
|
||||
"Total Vol. (1M)",
|
||||
]
|
||||
]
|
||||
|
||||
df.date = df.date.dt.date
|
||||
|
||||
print(
|
||||
tabulate(
|
||||
df.iloc[:num],
|
||||
tablefmt="fancy_grid",
|
||||
floatfmt=".2f",
|
||||
headers=list(df.columns),
|
||||
showindex=False,
|
||||
)
|
||||
)
|
||||
else:
|
||||
_, axes = plt.subplots(
|
||||
2,
|
||||
1,
|
||||
figsize=(plot_autoscale()),
|
||||
dpi=PLOT_DPI,
|
||||
gridspec_kw={"height_ratios": [2, 1]},
|
||||
)
|
||||
|
||||
axes[0].bar(
|
||||
df["date"],
|
||||
df["total_volume"] / 1_000_000,
|
||||
width=timedelta(days=1),
|
||||
color="b",
|
||||
alpha=0.4,
|
||||
label="Total Volume",
|
||||
)
|
||||
axes[0].bar(
|
||||
df["date"],
|
||||
df["short_volume"] / 1_000_000,
|
||||
width=timedelta(days=1),
|
||||
color="r",
|
||||
alpha=0.4,
|
||||
label="Short Volume",
|
||||
)
|
||||
|
||||
axes[0].set_ylabel("Volume (1M)")
|
||||
ax2 = axes[0].twinx()
|
||||
ax2.plot(
|
||||
df["date"].values, prices[len(prices) - len(df) :], c="k", label="Price"
|
||||
)
|
||||
ax2.set_ylabel("Price ($)")
|
||||
|
||||
lines, labels = axes[0].get_legend_handles_labels()
|
||||
lines2, labels2 = ax2.get_legend_handles_labels()
|
||||
ax2.legend(lines + lines2, labels + labels2, loc="upper left")
|
||||
|
||||
axes[0].set_xlim(
|
||||
df["date"].values[max(0, len(df) - num)],
|
||||
df["date"].values[len(df) - 1],
|
||||
)
|
||||
|
||||
axes[0].grid()
|
||||
axes[0].ticklabel_format(style="plain", axis="y")
|
||||
plt.title(f"Price vs Short Volume Interest for {ticker}")
|
||||
plt.gcf().autofmt_xdate()
|
||||
|
||||
axes[1].plot(
|
||||
df["date"].values,
|
||||
100 * df["short_volume%"],
|
||||
c="green",
|
||||
label="Short Vol. %",
|
||||
)
|
||||
|
||||
axes[1].set_xlim(
|
||||
df["date"].values[max(0, len(df) - num)],
|
||||
df["date"].values[len(df) - 1],
|
||||
)
|
||||
axes[1].set_ylabel("Short Vol. %")
|
||||
|
||||
axes[1].grid(axis="y")
|
||||
lines, labels = axes[1].get_legend_handles_labels()
|
||||
axes[1].legend(lines, labels, loc="upper left")
|
||||
axes[1].set_ylim([0, 100])
|
||||
|
||||
if USE_ION:
|
||||
plt.ion()
|
||||
|
||||
plt.show()
|
||||
print("")
|
||||
|
||||
export_data(
|
||||
export,
|
||||
os.path.dirname(os.path.abspath(__file__)),
|
||||
"shortint(stockgrid)",
|
||||
df,
|
||||
)
|
||||
|
||||
|
||||
def net_short_position(ticker: str, num: int, raw: bool, export: str):
|
||||
"""Plot net short position. [Source: Stockgrid]
|
||||
|
||||
Parameters
|
||||
----------
|
||||
ticker: str
|
||||
Stock to plot for
|
||||
num : int
|
||||
Number of last open market days to show
|
||||
raw : bool
|
||||
Flag to print raw data instead
|
||||
export : str
|
||||
Export dataframe data to csv,json,xlsx file
|
||||
"""
|
||||
df = stockgrid_model.get_net_short_position(ticker)
|
||||
|
||||
if raw:
|
||||
df = df.sort_values(by="dates", ascending=False)
|
||||
|
||||
df["Net Short Vol. (1k $)"] = df["dollar_net_volume"] / 1_000
|
||||
df["Position (1M $)"] = df["dollar_dp_position"]
|
||||
|
||||
df = df[
|
||||
[
|
||||
"dates",
|
||||
"Net Short Vol. (1k $)",
|
||||
"Position (1M $)",
|
||||
]
|
||||
]
|
||||
|
||||
df["dates"] = df["dates"].dt.date
|
||||
|
||||
print(
|
||||
tabulate(
|
||||
df.iloc[:num],
|
||||
tablefmt="fancy_grid",
|
||||
floatfmt=".2f",
|
||||
headers=list(df.columns),
|
||||
showindex=False,
|
||||
)
|
||||
)
|
||||
|
||||
else:
|
||||
fig = plt.figure(figsize=plot_autoscale(), dpi=PLOT_DPI)
|
||||
|
||||
ax = fig.add_subplot(111)
|
||||
ax.bar(
|
||||
df["dates"],
|
||||
df["dollar_net_volume"] / 1_000,
|
||||
color="r",
|
||||
alpha=0.4,
|
||||
label="Net Short Vol. (1k $)",
|
||||
)
|
||||
ax.set_ylabel("Net Short Vol. (1k $)")
|
||||
|
||||
ax2 = ax.twinx()
|
||||
ax2.plot(
|
||||
df["dates"].values,
|
||||
df["dollar_dp_position"],
|
||||
c="tab:blue",
|
||||
label="Position (1M $)",
|
||||
)
|
||||
ax2.set_ylabel("Position (1M $)")
|
||||
|
||||
lines, labels = ax.get_legend_handles_labels()
|
||||
lines2, labels2 = ax2.get_legend_handles_labels()
|
||||
ax2.legend(lines + lines2, labels + labels2, loc="upper left")
|
||||
|
||||
ax.set_xlim(
|
||||
df["dates"].values[max(0, len(df) - num)],
|
||||
df["dates"].values[len(df) - 1],
|
||||
)
|
||||
|
||||
ax.grid()
|
||||
plt.title(f"Net Short Vol. vs Position for {ticker}")
|
||||
plt.gcf().autofmt_xdate()
|
||||
|
||||
if USE_ION:
|
||||
plt.ion()
|
||||
|
||||
plt.show()
|
||||
print("")
|
||||
|
||||
export_data(
|
||||
export,
|
||||
os.path.dirname(os.path.abspath(__file__)),
|
||||
"shortpos",
|
||||
df,
|
||||
)
|
||||
@@ -23,9 +23,7 @@ from gamestonk_terminal.stocks.discovery import (
|
||||
seeking_alpha_view,
|
||||
shortinterest_view,
|
||||
yahoofinance_view,
|
||||
finra_ats_view,
|
||||
finnhub_view,
|
||||
stockgrid_view,
|
||||
)
|
||||
|
||||
|
||||
@@ -51,11 +49,7 @@ class DiscoveryController:
|
||||
"upcoming",
|
||||
"latest",
|
||||
"trending",
|
||||
"highshort",
|
||||
"lowfloat",
|
||||
"darkpool",
|
||||
"darkshort",
|
||||
"shortvol",
|
||||
]
|
||||
|
||||
CHOICES += CHOICES_COMMANDS
|
||||
@@ -72,6 +66,7 @@ class DiscoveryController:
|
||||
def print_help():
|
||||
"""Print help"""
|
||||
help_text = """https://github.com/GamestonkTerminal/GamestonkTerminal/tree/main/gamestonk_terminal/stocks/discovery
|
||||
|
||||
Discovery:
|
||||
cls clear screen")
|
||||
?/help show this menu again")
|
||||
@@ -92,13 +87,7 @@ Seeking Alpha:
|
||||
latest latest news
|
||||
trending trending news
|
||||
shortinterest.com
|
||||
highshort show top high short interest stocks of over 20% ratio
|
||||
lowfloat show low float stocks under 10M shares float
|
||||
FINRA:
|
||||
darkpool promising tickers based on dark pool shares regression
|
||||
Stockgrid:
|
||||
darkshort dark pool short position
|
||||
shortvol short interest and days to cover
|
||||
"""
|
||||
print(help_text)
|
||||
|
||||
@@ -586,50 +575,6 @@ Stockgrid:
|
||||
except Exception as e:
|
||||
print(e, "\n")
|
||||
|
||||
def call_highshort(self, other_args: List[str]):
|
||||
"""Process highshort command"""
|
||||
parser = argparse.ArgumentParser(
|
||||
add_help=False,
|
||||
formatter_class=argparse.ArgumentDefaultsHelpFormatter,
|
||||
prog="highshort",
|
||||
description="""
|
||||
Print top stocks being more heavily shorted. HighShortInterest.com provides
|
||||
a convenient sorted database of stocks which have a short interest of over
|
||||
20 percent. Additional key data such as the float, number of outstanding shares,
|
||||
and company industry is displayed. Data is presented for the Nasdaq Stock Market,
|
||||
the New York Stock Exchange, and the American Stock Exchange. [Source: www.highshortinterest.com]
|
||||
""",
|
||||
)
|
||||
parser.add_argument(
|
||||
"-n",
|
||||
"--num",
|
||||
action="store",
|
||||
dest="n_num",
|
||||
type=check_positive,
|
||||
default=10,
|
||||
help="Number of top stocks to print.",
|
||||
)
|
||||
parser.add_argument(
|
||||
"--export",
|
||||
choices=["csv", "json", "xlsx"],
|
||||
default="",
|
||||
type=str,
|
||||
dest="export",
|
||||
help="Export dataframe data to csv,json,xlsx file",
|
||||
)
|
||||
try:
|
||||
ns_parser = parse_known_args_and_warn(parser, other_args)
|
||||
if not ns_parser:
|
||||
return
|
||||
|
||||
shortinterest_view.high_short_interest(
|
||||
num=ns_parser.n_num,
|
||||
export=ns_parser.export,
|
||||
)
|
||||
|
||||
except Exception as e:
|
||||
print(e, "\n")
|
||||
|
||||
def call_lowfloat(self, other_args: List[str]):
|
||||
"""Process lowfloat command"""
|
||||
parser = argparse.ArgumentParser(
|
||||
@@ -674,18 +619,6 @@ Stockgrid:
|
||||
except Exception as e:
|
||||
print(e, "\n")
|
||||
|
||||
def call_darkpool(self, other_args: List[str]):
|
||||
"""Process darkpool command"""
|
||||
finra_ats_view.dark_pool(other_args)
|
||||
|
||||
def call_darkshort(self, other_args: List[str]):
|
||||
"""Process darkshort command"""
|
||||
stockgrid_view.darkshort(other_args)
|
||||
|
||||
def call_shortvol(self, other_args: List[str]):
|
||||
"""Process shortvol command"""
|
||||
stockgrid_view.shortvol(other_args)
|
||||
|
||||
|
||||
def menu():
|
||||
"""Discovery Menu"""
|
||||
|
||||
@@ -1,264 +0,0 @@
|
||||
""" FINRA View """
|
||||
__docformat__ = "numpy"
|
||||
|
||||
import argparse
|
||||
from typing import List, Tuple, Dict
|
||||
import requests
|
||||
from scipy import stats
|
||||
import pandas as pd
|
||||
from matplotlib import pyplot as plt
|
||||
from gamestonk_terminal.config_plot import PLOT_DPI
|
||||
from gamestonk_terminal import feature_flags as gtff
|
||||
from gamestonk_terminal.helper_funcs import (
|
||||
parse_known_args_and_warn,
|
||||
plot_autoscale,
|
||||
check_positive,
|
||||
)
|
||||
|
||||
|
||||
def getFINRAweeks(tier, is_ats) -> List:
|
||||
"""Get FINRA weeks
|
||||
|
||||
Parameters
|
||||
----------
|
||||
tier : str
|
||||
Stock tier between T1, T2, or OTCE
|
||||
is_ats : bool
|
||||
ATS data if true, NON-ATS otherwise
|
||||
|
||||
Returns
|
||||
----------
|
||||
List
|
||||
List of response data
|
||||
"""
|
||||
req_hdr = {"Accept": "application/json", "Content-Type": "application/json"}
|
||||
|
||||
req_data = {
|
||||
"compareFilters": [
|
||||
{
|
||||
"compareType": "EQUAL",
|
||||
"fieldName": "summaryTypeCode",
|
||||
"fieldValue": "ATS_W_SMBL" if is_ats else "OTC_W_SMBL",
|
||||
},
|
||||
{
|
||||
"compareType": "EQUAL",
|
||||
"fieldName": "tierIdentifier",
|
||||
"fieldValue": tier,
|
||||
},
|
||||
],
|
||||
"delimiter": "|",
|
||||
"fields": ["weekStartDate"],
|
||||
"limit": 27,
|
||||
"quoteValues": False,
|
||||
"sortFields": ["-weekStartDate"],
|
||||
}
|
||||
|
||||
response = requests.post(
|
||||
"https://api.finra.org/data/group/otcMarket/name/weeklyDownloadDetails",
|
||||
headers=req_hdr,
|
||||
json=req_data,
|
||||
)
|
||||
|
||||
return response.json() if response.status_code == 200 else list()
|
||||
|
||||
|
||||
def getFINRAdata(weekStartDate, tier, ticker, is_ats, offset):
|
||||
req_hdr = {"Accept": "application/json", "Content-Type": "application/json"}
|
||||
|
||||
l_cmp_filters = [
|
||||
{
|
||||
"compareType": "EQUAL",
|
||||
"fieldName": "weekStartDate",
|
||||
"fieldValue": weekStartDate,
|
||||
},
|
||||
{"compareType": "EQUAL", "fieldName": "tierIdentifier", "fieldValue": tier},
|
||||
{
|
||||
"compareType": "EQUAL",
|
||||
"description": "",
|
||||
"fieldName": "summaryTypeCode",
|
||||
"fieldValue": "ATS_W_SMBL" if is_ats else "OTC_W_SMBL",
|
||||
},
|
||||
]
|
||||
|
||||
if ticker:
|
||||
l_cmp_filters.append(
|
||||
{
|
||||
"compareType": "EQUAL",
|
||||
"fieldName": "issueSymbolIdentifier",
|
||||
"fieldValue": ticker,
|
||||
}
|
||||
)
|
||||
|
||||
req_data = {
|
||||
"compareFilters": l_cmp_filters,
|
||||
"delimiter": "|",
|
||||
"fields": [
|
||||
"issueSymbolIdentifier",
|
||||
"totalWeeklyShareQuantity",
|
||||
"totalWeeklyTradeCount",
|
||||
"lastUpdateDate",
|
||||
],
|
||||
"limit": 5000,
|
||||
"offset": offset,
|
||||
"quoteValues": False,
|
||||
"sortFields": ["totalWeeklyShareQuantity"],
|
||||
}
|
||||
|
||||
return requests.post(
|
||||
"https://api.finra.org/data/group/otcMarket/name/weeklySummary",
|
||||
headers=req_hdr,
|
||||
json=req_data,
|
||||
)
|
||||
|
||||
|
||||
def getATSdata(num_tickers_to_filter: int) -> Tuple[pd.DataFrame, Dict]:
|
||||
"""Get all FINRA ATS data, and parse most promising tickers based on linear regression
|
||||
|
||||
Parameters
|
||||
----------
|
||||
num_tickers_to_filter : int
|
||||
Number of tickers to filter from entire ATS data based on the sum of the total weekly shares quantity
|
||||
|
||||
Returns
|
||||
----------
|
||||
pd.DataFrame
|
||||
Dark Pools (ATS) Data
|
||||
Dict
|
||||
Tickers from Dark Pools with better regression slope
|
||||
"""
|
||||
tiers = ["T1", "T2", "OTCE"]
|
||||
df_ats = pd.DataFrame()
|
||||
|
||||
for tier in tiers:
|
||||
print(f"Processing Tier {tier} ...")
|
||||
for d_week in getFINRAweeks(tier, is_ats=True):
|
||||
offset = 0
|
||||
response = getFINRAdata(d_week["weekStartDate"], tier, "", True, offset)
|
||||
l_data = response.json()
|
||||
|
||||
while len(response.json()) == 5000:
|
||||
offset += 5000
|
||||
response = getFINRAdata(d_week["weekStartDate"], tier, "", True, offset)
|
||||
l_data += response.json()
|
||||
|
||||
df_ats_week = pd.DataFrame(l_data)
|
||||
df_ats_week["weekStartDate"] = d_week["weekStartDate"]
|
||||
|
||||
if not df_ats_week.empty:
|
||||
df_ats = df_ats.append(df_ats_week, ignore_index=True)
|
||||
|
||||
df_ats = df_ats.sort_values("weekStartDate")
|
||||
df_ats["weekStartDateInt"] = pd.to_datetime(df_ats["weekStartDate"]).apply(
|
||||
lambda x: x.timestamp()
|
||||
)
|
||||
|
||||
print(f"Processing regression on {num_tickers_to_filter} promising tickers ...")
|
||||
|
||||
d_ats_reg = {}
|
||||
# set(df_ats['issueSymbolIdentifier'].values) this would be iterating through all tickers
|
||||
# but that is extremely time consuming for little reward. A little filtering is done to
|
||||
# speed up search for best ATS tickers
|
||||
for symbol in list(
|
||||
df_ats.groupby("issueSymbolIdentifier")["totalWeeklyShareQuantity"]
|
||||
.sum()
|
||||
.sort_values()[-num_tickers_to_filter:]
|
||||
.index
|
||||
):
|
||||
slope = stats.linregress(
|
||||
df_ats[df_ats["issueSymbolIdentifier"] == symbol][
|
||||
"weekStartDateInt"
|
||||
].values,
|
||||
df_ats[df_ats["issueSymbolIdentifier"] == symbol][
|
||||
"totalWeeklyShareQuantity"
|
||||
].values,
|
||||
)[0]
|
||||
d_ats_reg[symbol] = slope
|
||||
|
||||
return df_ats, d_ats_reg
|
||||
|
||||
|
||||
def plot_dark_pools(ats: pd.DataFrame, top_ats_tickers: List):
|
||||
"""Plots promising tickers based on growing ATS data
|
||||
|
||||
Parameters
|
||||
----------
|
||||
ats : pd.DataFrame
|
||||
Dark Pools (ATS) Data
|
||||
top_ats_tickers : List
|
||||
List of tickers from most promising with better linear regression slope
|
||||
"""
|
||||
plt.figure(figsize=plot_autoscale(), dpi=PLOT_DPI)
|
||||
|
||||
for symbol in top_ats_tickers:
|
||||
plt.plot(
|
||||
pd.to_datetime(
|
||||
ats[ats["issueSymbolIdentifier"] == symbol]["weekStartDate"]
|
||||
),
|
||||
ats[ats["issueSymbolIdentifier"] == symbol]["totalWeeklyShareQuantity"]
|
||||
/ 1_000_000,
|
||||
)
|
||||
|
||||
plt.legend(top_ats_tickers)
|
||||
plt.ylabel("Total Weekly Shares [Million]")
|
||||
plt.grid(b=True, which="major", color="#666666", linestyle="-", alpha=0.2)
|
||||
plt.title("Dark Pool (ATS) growing tickers")
|
||||
plt.gcf().autofmt_xdate()
|
||||
plt.xlabel("Weeks")
|
||||
|
||||
if gtff.USE_ION:
|
||||
plt.ion()
|
||||
|
||||
plt.show()
|
||||
|
||||
|
||||
def dark_pool(other_args: List[str]):
|
||||
"""Display dark pool (ATS) data of tickers with growing trades activity
|
||||
|
||||
Parameters
|
||||
----------
|
||||
other_args : List[str]
|
||||
argparse other args
|
||||
"""
|
||||
parser = argparse.ArgumentParser(
|
||||
add_help=False,
|
||||
formatter_class=argparse.ArgumentDefaultsHelpFormatter,
|
||||
prog="darkpool",
|
||||
description="Display dark pool (ATS) data of tickers with growing trades activity",
|
||||
)
|
||||
parser.add_argument(
|
||||
"-n",
|
||||
"--num",
|
||||
action="store",
|
||||
dest="n_num",
|
||||
type=check_positive,
|
||||
default=1000,
|
||||
help="Number of tickers to filter from entire ATS data based on the sum of the total weekly shares quantity.",
|
||||
)
|
||||
parser.add_argument(
|
||||
"-t",
|
||||
"--top",
|
||||
action="store",
|
||||
dest="n_top",
|
||||
type=check_positive,
|
||||
default=5,
|
||||
help="List of tickers from most promising with better linear regression slope.",
|
||||
)
|
||||
|
||||
try:
|
||||
ns_parser = parse_known_args_and_warn(parser, other_args)
|
||||
if not ns_parser:
|
||||
return
|
||||
|
||||
df_ats, d_ats_reg = getATSdata(ns_parser.n_num)
|
||||
|
||||
top_ats_tickers = list(
|
||||
dict(
|
||||
sorted(d_ats_reg.items(), key=lambda item: item[1], reverse=True)
|
||||
).keys()
|
||||
)[: ns_parser.n_top]
|
||||
|
||||
plot_dark_pools(df_ats, top_ats_tickers)
|
||||
print("")
|
||||
|
||||
except Exception as e:
|
||||
print(e, "\n")
|
||||
@@ -9,56 +9,6 @@ from pandas.core.frame import DataFrame
|
||||
from gamestonk_terminal.helper_funcs import get_user_agent
|
||||
|
||||
|
||||
def get_high_short_interest() -> DataFrame:
|
||||
"""Returns a high short interest DataFrame
|
||||
|
||||
Returns
|
||||
-------
|
||||
DataFrame
|
||||
High short interest Dataframe with the following columns:
|
||||
Ticker, Company, Exchange, ShortInt, Float, Outstd, Industry
|
||||
"""
|
||||
|
||||
url_high_short_interested_stocks = "https://www.highshortinterest.com"
|
||||
|
||||
text_soup_high_short_interested_stocks = BeautifulSoup(
|
||||
requests.get(
|
||||
url_high_short_interested_stocks, headers={"User-Agent": get_user_agent()}
|
||||
).text,
|
||||
"lxml",
|
||||
)
|
||||
|
||||
a_high_short_interest_header = list()
|
||||
for high_short_interest_header in text_soup_high_short_interested_stocks.findAll(
|
||||
"td", {"class": "tblhdr"}
|
||||
):
|
||||
a_high_short_interest_header.append(
|
||||
high_short_interest_header.text.strip("\n").split("\n")[0]
|
||||
)
|
||||
df_high_short_interest = pd.DataFrame(columns=a_high_short_interest_header)
|
||||
df_high_short_interest.loc[0] = ["", "", "", "", "", "", ""]
|
||||
|
||||
stock_list_tr = text_soup_high_short_interested_stocks.find_all("tr")
|
||||
|
||||
shorted_stock_data = list()
|
||||
for a_stock in stock_list_tr:
|
||||
a_stock_txt = a_stock.text
|
||||
|
||||
if a_stock_txt == "":
|
||||
continue
|
||||
|
||||
shorted_stock_data = a_stock_txt.split("\n")
|
||||
|
||||
if len(shorted_stock_data) == 8:
|
||||
df_high_short_interest.loc[
|
||||
len(df_high_short_interest.index)
|
||||
] = shorted_stock_data[:-1]
|
||||
|
||||
shorted_stock_data = list()
|
||||
|
||||
return df_high_short_interest
|
||||
|
||||
|
||||
def get_low_float() -> DataFrame:
|
||||
"""Returns low float DataFrame
|
||||
|
||||
@@ -68,7 +18,6 @@ def get_low_float() -> DataFrame:
|
||||
Low float DataFrame with the following columns:
|
||||
Ticker, Company, Exchange, ShortInt, Float, Outstd, Industry
|
||||
"""
|
||||
|
||||
url_high_short_interested_stocks = "https://www.lowfloat.com"
|
||||
|
||||
text_soup_low_float_stocks = BeautifulSoup(
|
||||
|
||||
@@ -8,38 +8,6 @@ from gamestonk_terminal.helper_funcs import export_data
|
||||
from gamestonk_terminal.stocks.discovery import shortinterest_model
|
||||
|
||||
|
||||
def high_short_interest(num: int, export: str):
|
||||
"""Prints top N high shorted interest stocks from https://www.highshortinterest.com
|
||||
|
||||
Parameters
|
||||
----------
|
||||
num: int
|
||||
Number of stocks to display
|
||||
export : str
|
||||
Export dataframe data to csv,json,xlsx file
|
||||
"""
|
||||
df_high_short_interest = shortinterest_model.get_high_short_interest()
|
||||
df_high_short_interest = df_high_short_interest.iloc[1:].head(n=num)
|
||||
|
||||
print(
|
||||
tabulate(
|
||||
df_high_short_interest,
|
||||
headers=df_high_short_interest.columns,
|
||||
floatfmt=".2f",
|
||||
showindex=False,
|
||||
tablefmt="fancy_grid",
|
||||
),
|
||||
"\n",
|
||||
)
|
||||
|
||||
export_data(
|
||||
export,
|
||||
os.path.dirname(os.path.abspath(__file__)),
|
||||
"lowfloat",
|
||||
df_high_short_interest,
|
||||
)
|
||||
|
||||
|
||||
def low_float(num: int, export: str):
|
||||
"""Prints top N low float stocks from https://www.lowfloat.com
|
||||
|
||||
|
||||
@@ -1,240 +0,0 @@
|
||||
""" Stockgrid View """
|
||||
__docformat__ = "numpy"
|
||||
|
||||
import argparse
|
||||
import os
|
||||
from typing import List
|
||||
import requests
|
||||
import pandas as pd
|
||||
from tabulate import tabulate
|
||||
from gamestonk_terminal.helper_funcs import (
|
||||
parse_known_args_and_warn,
|
||||
check_positive,
|
||||
export_data,
|
||||
)
|
||||
|
||||
|
||||
def darkshort(other_args: List[str]):
|
||||
"""Get dark pool short positions.
|
||||
|
||||
Parameters
|
||||
----------
|
||||
other_args: List[str]
|
||||
Argparse arguments
|
||||
|
||||
"""
|
||||
parser = argparse.ArgumentParser(
|
||||
prog="darkshort",
|
||||
add_help=False,
|
||||
formatter_class=argparse.ArgumentDefaultsHelpFormatter,
|
||||
description="Get dark pool short positions. [Source: Stockgrid]",
|
||||
)
|
||||
parser.add_argument(
|
||||
"-n",
|
||||
"--number",
|
||||
help="Number of top tickers to show",
|
||||
type=check_positive,
|
||||
default=10,
|
||||
dest="num",
|
||||
)
|
||||
parser.add_argument(
|
||||
"-s",
|
||||
"--sort",
|
||||
help="Field for which to sort by, where 'sv': Short Vol. (1M), "
|
||||
"'sv_pct': Short Vol. %%, 'nsv': Net Short Vol. (1M), "
|
||||
"'nsv_dollar': Net Short Vol. ($100M), 'dpp': DP Position (1M), "
|
||||
"'dpp_dollar': DP Position ($1B)",
|
||||
choices=["sv", "sv_pct", "nsv", "nsv_dollar", "dpp", "dpp_dollar"],
|
||||
default="dpp_dollar",
|
||||
dest="sort_field",
|
||||
)
|
||||
parser.add_argument(
|
||||
"-a",
|
||||
"--ascending",
|
||||
action="store_true",
|
||||
default=False,
|
||||
dest="ascending",
|
||||
help="Data in ascending order",
|
||||
)
|
||||
parser.add_argument(
|
||||
"--export",
|
||||
choices=["csv", "json", "xlsx"],
|
||||
default="",
|
||||
dest="export",
|
||||
help="Export dataframe data to csv,json,xlsx file",
|
||||
)
|
||||
|
||||
try:
|
||||
ns_parser = parse_known_args_and_warn(parser, other_args)
|
||||
if not ns_parser:
|
||||
return
|
||||
|
||||
d_fields_endpoints = {
|
||||
"sv": "Short+Volume",
|
||||
"sv_pct": "Short+Volume+%25",
|
||||
"nsv": "Net+Short+Volume",
|
||||
"nsv_dollar": "Net+Short+Volume+$",
|
||||
"dpp": "Dark+Pools+Position",
|
||||
"dpp_dollar": "Dark+Pools+Position+$",
|
||||
}
|
||||
|
||||
field = d_fields_endpoints[ns_parser.sort_field]
|
||||
|
||||
if ns_parser.ascending:
|
||||
order = "asc"
|
||||
else:
|
||||
order = "desc"
|
||||
|
||||
link = f"https://stockgridapp.herokuapp.com/get_dark_pool_data?top={field}&minmax={order}"
|
||||
|
||||
response = requests.get(link)
|
||||
df = pd.DataFrame(response.json()["data"])
|
||||
|
||||
df = df[
|
||||
[
|
||||
"Ticker",
|
||||
"Date",
|
||||
"Short Volume",
|
||||
"Short Volume %",
|
||||
"Net Short Volume",
|
||||
"Net Short Volume $",
|
||||
"Dark Pools Position",
|
||||
"Dark Pools Position $",
|
||||
]
|
||||
]
|
||||
dp_date = df["Date"].values[0]
|
||||
df = df.drop(columns=["Date"])
|
||||
df["Net Short Volume $"] = df["Net Short Volume $"] / 100_000_000
|
||||
df["Short Volume"] = df["Short Volume"] / 1_000_000
|
||||
df["Net Short Volume"] = df["Net Short Volume"] / 1_000_000
|
||||
df["Short Volume %"] = df["Short Volume %"] * 100
|
||||
df["Dark Pools Position $"] = df["Dark Pools Position $"] / (1_000_000_000)
|
||||
df["Dark Pools Position"] = df["Dark Pools Position"] / 1_000_000
|
||||
df.columns = [
|
||||
"Ticker",
|
||||
"Short Vol. (1M)",
|
||||
"Short Vol. %",
|
||||
"Net Short Vol. (1M)",
|
||||
"Net Short Vol. ($100M)",
|
||||
"DP Position (1M)",
|
||||
"DP Position ($1B)",
|
||||
]
|
||||
|
||||
# Assuming that the datetime is the same, which from my experiments seems to be the case
|
||||
print(f"The following data corresponds to the date: {dp_date}")
|
||||
print(
|
||||
tabulate(
|
||||
df.iloc[: ns_parser.num],
|
||||
tablefmt="fancy_grid",
|
||||
floatfmt=".2f",
|
||||
headers=list(df.columns),
|
||||
showindex=False,
|
||||
)
|
||||
)
|
||||
print("")
|
||||
|
||||
export_data(
|
||||
ns_parser.export,
|
||||
os.path.dirname(os.path.abspath(__file__)),
|
||||
"darkshort",
|
||||
df,
|
||||
)
|
||||
|
||||
except Exception as e:
|
||||
print(e, "\n")
|
||||
|
||||
|
||||
def shortvol(other_args: List[str]):
|
||||
"""Print short interest and days to cover
|
||||
|
||||
Parameters
|
||||
----------
|
||||
other_args: List[str]
|
||||
Argparse arguments
|
||||
"""
|
||||
parser = argparse.ArgumentParser(
|
||||
prog="shortvol",
|
||||
add_help=False,
|
||||
formatter_class=argparse.ArgumentDefaultsHelpFormatter,
|
||||
description="Print short interest and days to cover. [Source: Stockgrid]",
|
||||
)
|
||||
parser.add_argument(
|
||||
"-n",
|
||||
"--number",
|
||||
help="Number of top tickers to show",
|
||||
type=check_positive,
|
||||
default=10,
|
||||
dest="num",
|
||||
)
|
||||
parser.add_argument(
|
||||
"-s",
|
||||
"--sort",
|
||||
help="Field for which to sort by, where 'float': Float Short %%, "
|
||||
"'dtc': Days to Cover, 'si': Short Interest",
|
||||
choices=["float", "dtc", "si"],
|
||||
default="float",
|
||||
dest="sort_field",
|
||||
)
|
||||
parser.add_argument(
|
||||
"--export",
|
||||
choices=["csv", "json", "xlsx"],
|
||||
default="",
|
||||
dest="export",
|
||||
help="Export dataframe data to csv,json,xlsx file",
|
||||
)
|
||||
|
||||
try:
|
||||
ns_parser = parse_known_args_and_warn(parser, other_args)
|
||||
if not ns_parser:
|
||||
return
|
||||
|
||||
link = "https://stockgridapp.herokuapp.com/get_short_interest?top=days"
|
||||
r = requests.get(link)
|
||||
df = pd.DataFrame(r.json()["data"])
|
||||
df.head()
|
||||
|
||||
d_fields = {
|
||||
"float": "%Float Short",
|
||||
"dtc": "Days To Cover",
|
||||
"si": "Short Interest",
|
||||
}
|
||||
|
||||
df = df[
|
||||
["Ticker", "Date", "%Float Short", "Days To Cover", "Short Interest"]
|
||||
].sort_values(
|
||||
by=d_fields[ns_parser.sort_field],
|
||||
ascending=bool(ns_parser.sort_field == "dtc"),
|
||||
)
|
||||
dp_date = df["Date"].values[0]
|
||||
df = df.drop(columns=["Date"])
|
||||
df["Short Interest"] = df["Short Interest"] / 1_000_000
|
||||
df.head()
|
||||
df.columns = [
|
||||
"Ticker",
|
||||
"Float Short %",
|
||||
"Days to Cover",
|
||||
"Short Interest (1M)",
|
||||
]
|
||||
|
||||
# Assuming that the datetime is the same, which from my experiments seems to be the case
|
||||
print(f"The following data corresponds to the date: {dp_date}")
|
||||
print(
|
||||
tabulate(
|
||||
df.iloc[: ns_parser.num],
|
||||
tablefmt="fancy_grid",
|
||||
floatfmt=".2f",
|
||||
headers=list(df.columns),
|
||||
showindex=False,
|
||||
)
|
||||
)
|
||||
print("")
|
||||
|
||||
export_data(
|
||||
ns_parser.export,
|
||||
os.path.dirname(os.path.abspath(__file__)),
|
||||
"shortvol",
|
||||
df,
|
||||
)
|
||||
|
||||
except Exception as e:
|
||||
print(e, "\n")
|
||||
@@ -13,11 +13,7 @@ from gamestonk_terminal.stocks.due_diligence import (
|
||||
)
|
||||
from gamestonk_terminal.stocks.due_diligence import finviz_view as fvz_view
|
||||
from gamestonk_terminal.stocks.due_diligence import market_watch_view as mw_view
|
||||
from gamestonk_terminal.stocks.due_diligence import quandl_view as q_view
|
||||
from gamestonk_terminal.stocks.due_diligence import reddit_view as r_view
|
||||
from gamestonk_terminal.stocks.due_diligence import finra_view
|
||||
from gamestonk_terminal.stocks.due_diligence import sec_view
|
||||
from gamestonk_terminal.stocks.due_diligence import stockgrid_dd_view as sg_view
|
||||
from gamestonk_terminal.stocks.due_diligence import finnhub_view
|
||||
from gamestonk_terminal.stocks.due_diligence import csimarket_view
|
||||
from gamestonk_terminal import feature_flags as gtff
|
||||
@@ -36,7 +32,7 @@ class DueDiligenceController:
|
||||
"q",
|
||||
"quit",
|
||||
"red",
|
||||
"short",
|
||||
"sec",
|
||||
"rating",
|
||||
"pt",
|
||||
"rot",
|
||||
@@ -46,11 +42,6 @@ class DueDiligenceController:
|
||||
"news",
|
||||
"analyst",
|
||||
"warnings",
|
||||
"sec",
|
||||
"dp",
|
||||
"ftd",
|
||||
"shortview",
|
||||
"darkpos",
|
||||
"supplier",
|
||||
"customer",
|
||||
]
|
||||
@@ -116,14 +107,9 @@ class DueDiligenceController:
|
||||
print(" ins insider activity over time [Business Insider]")
|
||||
print(" insider insider trading of the company [Finviz]")
|
||||
print(" sec SEC filings [Market Watch]")
|
||||
print(" short short interest [Quandl]")
|
||||
print(
|
||||
" warnings company warnings according to Sean Seah book [Market Watch]"
|
||||
)
|
||||
print(" dp dark pools (ATS) vs OTC data [FINRA]")
|
||||
print(" ftd fails-to-deliver data [SEC]")
|
||||
print(" shortview price vs short interest volume [Stockgrid.io]")
|
||||
print(" darkpos net short vs position [Stockgrid.io]")
|
||||
print(" supplier list of suppliers [csimarket]")
|
||||
print(" customer list of customers [csimarket]")
|
||||
print("")
|
||||
@@ -216,26 +202,6 @@ class DueDiligenceController:
|
||||
"""Process sec command"""
|
||||
mw_view.sec_fillings(other_args, self.ticker)
|
||||
|
||||
def call_short(self, other_args: List[str]):
|
||||
"""Process short command"""
|
||||
q_view.short_interest(other_args, self.ticker, self.start)
|
||||
|
||||
def call_dp(self, other_args: List[str]):
|
||||
"""Process dp command"""
|
||||
finra_view.dark_pool(other_args, self.ticker)
|
||||
|
||||
def call_ftd(self, other_args: List[str]):
|
||||
"""Process ftd command"""
|
||||
sec_view.fails_to_deliver(other_args, self.ticker, self.stock)
|
||||
|
||||
def call_shortview(self, other_args: List[str]):
|
||||
"""Process shortview command"""
|
||||
sg_view.shortview(self.ticker, other_args)
|
||||
|
||||
def call_darkpos(self, other_args: List[str]):
|
||||
"""Process darkpos command"""
|
||||
sg_view.darkpos(self.ticker, other_args)
|
||||
|
||||
def call_supplier(self, other_args: List[str]):
|
||||
"""Process supplier command"""
|
||||
csimarket_view.suppliers(self.ticker, other_args)
|
||||
|
||||
@@ -1,134 +0,0 @@
|
||||
""" Quandl View """
|
||||
__docformat__ = "numpy"
|
||||
|
||||
import argparse
|
||||
from typing import List
|
||||
import quandl
|
||||
from matplotlib import pyplot as plt
|
||||
import matplotlib.ticker
|
||||
import pandas as pd
|
||||
from gamestonk_terminal.helper_funcs import (
|
||||
check_positive,
|
||||
long_number_format,
|
||||
parse_known_args_and_warn,
|
||||
)
|
||||
from gamestonk_terminal import config_terminal as cfg
|
||||
|
||||
|
||||
def short_interest(other_args: List[str], ticker: str, start: str):
|
||||
"""Display short interest for a given ticker and a given start date
|
||||
|
||||
Parameters
|
||||
----------
|
||||
other_args : List[str]
|
||||
argparse other args - ["-d", "10"]
|
||||
ticker : str
|
||||
Stock ticker
|
||||
start : str
|
||||
Start date of the stock data
|
||||
"""
|
||||
parser = argparse.ArgumentParser(
|
||||
add_help=False,
|
||||
formatter_class=argparse.ArgumentDefaultsHelpFormatter,
|
||||
prog="short",
|
||||
description="""
|
||||
Plots the short interest of a stock. This corresponds to the number of shares that
|
||||
have been sold short but have not yet been covered or closed out. Either NASDAQ or NYSE [Source: Quandl]
|
||||
""",
|
||||
)
|
||||
parser.add_argument(
|
||||
"-n",
|
||||
"--nyse",
|
||||
action="store_true",
|
||||
default=False,
|
||||
dest="b_nyse",
|
||||
help="data from NYSE flag.",
|
||||
)
|
||||
parser.add_argument(
|
||||
"-d",
|
||||
"--days",
|
||||
action="store",
|
||||
dest="n_days",
|
||||
type=check_positive,
|
||||
default=10,
|
||||
help="number of latest days to print data.",
|
||||
)
|
||||
try:
|
||||
ns_parser = parse_known_args_and_warn(parser, other_args)
|
||||
if not ns_parser:
|
||||
return
|
||||
|
||||
quandl.ApiConfig.api_key = cfg.API_KEY_QUANDL
|
||||
|
||||
if ns_parser.b_nyse:
|
||||
df_short_interest = quandl.get(f"FINRA/FNYX_{ticker}")
|
||||
else:
|
||||
df_short_interest = quandl.get(f"FINRA/FNSQ_{ticker}")
|
||||
|
||||
df_short_interest = df_short_interest[start:] # type: ignore
|
||||
df_short_interest.columns = [
|
||||
"".join(
|
||||
" " + char if char.isupper() else char.strip() for char in idx
|
||||
).strip()
|
||||
for idx in df_short_interest.columns.tolist()
|
||||
]
|
||||
df_short_interest["% of Volume Shorted"] = round(
|
||||
100 * df_short_interest["Short Volume"] / df_short_interest["Total Volume"],
|
||||
2,
|
||||
)
|
||||
|
||||
_, ax = plt.subplots()
|
||||
ax.bar(
|
||||
df_short_interest.index, df_short_interest["Short Volume"], 0.3, color="r"
|
||||
)
|
||||
ax.bar(
|
||||
df_short_interest.index,
|
||||
df_short_interest["Total Volume"] - df_short_interest["Short Volume"],
|
||||
0.3,
|
||||
bottom=df_short_interest["Short Volume"],
|
||||
color="b",
|
||||
)
|
||||
ax.set_ylabel("Shares")
|
||||
ax.set_xlabel("Date")
|
||||
|
||||
if start:
|
||||
ax.set_title(
|
||||
f"{('NASDAQ', 'NYSE')[ns_parser.b_nyse]} Short Interest on {ticker} from {start.date()}" # type: ignore
|
||||
)
|
||||
else:
|
||||
ax.set_title(
|
||||
f"{('NASDAQ', 'NYSE')[ns_parser.b_nyse]} Short Interest on {ticker}"
|
||||
)
|
||||
|
||||
ax.legend(labels=["Short Volume", "Total Volume"])
|
||||
ax.tick_params(axis="both", which="major")
|
||||
ax.yaxis.set_major_formatter(matplotlib.ticker.EngFormatter())
|
||||
ax_twin = ax.twinx()
|
||||
ax_twin.tick_params(axis="y", colors="green")
|
||||
ax_twin.set_ylabel("Percentage of Volume Shorted", color="green")
|
||||
ax_twin.plot(
|
||||
df_short_interest.index,
|
||||
df_short_interest["% of Volume Shorted"],
|
||||
color="green",
|
||||
)
|
||||
ax_twin.tick_params(axis="y", which="major", color="green")
|
||||
ax_twin.yaxis.set_major_formatter(
|
||||
matplotlib.ticker.FormatStrFormatter("%.0f%%")
|
||||
)
|
||||
plt.xlim([df_short_interest.index[0], df_short_interest.index[-1]])
|
||||
|
||||
df_short_interest["% of Volume Shorted"] = df_short_interest[
|
||||
"% of Volume Shorted"
|
||||
].apply(lambda x: f"{x/100:.2%}")
|
||||
df_short_interest = df_short_interest.applymap(
|
||||
lambda x: long_number_format(x)
|
||||
).sort_index(ascending=False)
|
||||
|
||||
pd.set_option("display.max_colwidth", 70)
|
||||
print(df_short_interest.head(n=ns_parser.n_days).to_string())
|
||||
print("")
|
||||
plt.show()
|
||||
|
||||
except Exception as e:
|
||||
print(e, "\n")
|
||||
return
|
||||
@@ -1,235 +0,0 @@
|
||||
""" SEC View """
|
||||
__docformat__ = "numpy"
|
||||
|
||||
import argparse
|
||||
import os
|
||||
from typing import List
|
||||
from datetime import datetime, timedelta
|
||||
from tabulate import tabulate
|
||||
import requests
|
||||
import pandas as pd
|
||||
from bs4 import BeautifulSoup
|
||||
from matplotlib import pyplot as plt
|
||||
import matplotlib.dates as mdates
|
||||
from gamestonk_terminal import feature_flags as gtff
|
||||
from gamestonk_terminal.helper_funcs import (
|
||||
get_user_agent,
|
||||
check_positive,
|
||||
parse_known_args_and_warn,
|
||||
valid_date,
|
||||
export_data,
|
||||
)
|
||||
|
||||
|
||||
def fails_to_deliver(other_args: List[str], ticker: str, stock: pd.DataFrame):
|
||||
"""Display fails-to-deliver data for a given ticker
|
||||
|
||||
Parameters
|
||||
----------
|
||||
other_args : List[str]
|
||||
argparse other args - ["-n", "10"]
|
||||
ticker : str
|
||||
Stock ticker
|
||||
stock : pd.DataFrame
|
||||
Stock data
|
||||
"""
|
||||
|
||||
parser = argparse.ArgumentParser(
|
||||
add_help=False,
|
||||
prog="ftd",
|
||||
description="""Prints latest fails-to-deliver data. [Source: SEC]""",
|
||||
)
|
||||
parser.add_argument(
|
||||
"-s",
|
||||
"--start",
|
||||
action="store",
|
||||
dest="start",
|
||||
type=valid_date,
|
||||
default=(datetime.now() - timedelta(days=60)).strftime("%Y-%m-%d"),
|
||||
help="start of datetime to see FTD",
|
||||
)
|
||||
parser.add_argument(
|
||||
"-e",
|
||||
"--end",
|
||||
action="store",
|
||||
dest="end",
|
||||
type=valid_date,
|
||||
default=datetime.now().strftime("%Y-%m-%d"),
|
||||
help="end of datetime to see FTD",
|
||||
)
|
||||
parser.add_argument(
|
||||
"-n",
|
||||
"--num",
|
||||
action="store",
|
||||
dest="n_num",
|
||||
type=check_positive,
|
||||
default=0,
|
||||
help="number of latest fails-to-deliver being printed",
|
||||
)
|
||||
parser.add_argument(
|
||||
"--raw",
|
||||
action="store_true",
|
||||
default=False,
|
||||
dest="raw",
|
||||
help="Print raw data.",
|
||||
)
|
||||
parser.add_argument(
|
||||
"--export",
|
||||
choices=["csv", "json", "xlsx"],
|
||||
default="",
|
||||
dest="export",
|
||||
help="Export dataframe data to csv,json,xlsx file",
|
||||
)
|
||||
|
||||
try:
|
||||
ns_parser = parse_known_args_and_warn(parser, other_args)
|
||||
if not ns_parser:
|
||||
return
|
||||
|
||||
ftds_data = pd.DataFrame()
|
||||
|
||||
# Filter by number of last FTD
|
||||
if ns_parser.n_num > 0:
|
||||
url_ftds = "https://www.sec.gov/data/foiadocsfailsdatahtm"
|
||||
text_soup_ftds = BeautifulSoup(
|
||||
requests.get(url_ftds, headers={"User-Agent": get_user_agent()}).text,
|
||||
"lxml",
|
||||
)
|
||||
|
||||
table = text_soup_ftds.find("table", {"class": "list"})
|
||||
links = table.findAll("a")
|
||||
link_idx = 0
|
||||
|
||||
while len(ftds_data) < ns_parser.n_num:
|
||||
if link_idx > len(links):
|
||||
break
|
||||
link = links[link_idx]
|
||||
url = "https://www.sec.gov" + link["href"]
|
||||
all_ftds = pd.read_csv(
|
||||
url,
|
||||
compression="zip",
|
||||
sep="|",
|
||||
engine="python",
|
||||
skipfooter=2,
|
||||
usecols=[0, 2, 3, 5],
|
||||
dtype={"QUANTITY (FAILS)": "int"},
|
||||
)
|
||||
tmp_ftds = all_ftds[all_ftds["SYMBOL"] == ticker]
|
||||
del tmp_ftds["PRICE"]
|
||||
del tmp_ftds["SYMBOL"]
|
||||
# merge the data from this archive
|
||||
ftds_data = pd.concat([ftds_data, tmp_ftds], ignore_index=True)
|
||||
link_idx += 1
|
||||
|
||||
# clip away extra rows
|
||||
ftds_data = ftds_data.sort_values("SETTLEMENT DATE")[-ns_parser.n_num :]
|
||||
|
||||
ftds_data["SETTLEMENT DATE"] = ftds_data["SETTLEMENT DATE"].apply(
|
||||
lambda x: datetime.strptime(str(x), "%Y%m%d")
|
||||
)
|
||||
|
||||
# Filter by start and end dates for FTD
|
||||
else:
|
||||
|
||||
base_url = "https://www.sec.gov/files/data/fails-deliver-data/cnsfails"
|
||||
ftd_dates = list()
|
||||
|
||||
for y in range(ns_parser.start.year, ns_parser.end.year + 1):
|
||||
if y < ns_parser.end.year:
|
||||
for m in range(ns_parser.start.month, 13):
|
||||
month = "%02d" % m
|
||||
if m == ns_parser.start.month and y == ns_parser.start.year:
|
||||
if ns_parser.start.day < 16:
|
||||
ftd_dates.append(str(y) + month + "a")
|
||||
ftd_dates.append(str(y) + month + "b")
|
||||
else:
|
||||
ftd_dates.append(str(y) + month + "a")
|
||||
ftd_dates.append(str(y) + month + "b")
|
||||
|
||||
else:
|
||||
for m in range(1, ns_parser.end.month):
|
||||
month = "%02d" % m
|
||||
if m == ns_parser.end.month - 1:
|
||||
ftd_dates.append(str(y) + month + "a")
|
||||
if ns_parser.end.day > 15:
|
||||
ftd_dates.append(str(y) + month + "b")
|
||||
else:
|
||||
ftd_dates.append(str(y) + month + "a")
|
||||
ftd_dates.append(str(y) + month + "b")
|
||||
|
||||
ftd_urls = [base_url + ftd_date + ".zip" for ftd_date in ftd_dates]
|
||||
|
||||
for ftd_link in ftd_urls:
|
||||
all_ftds = pd.read_csv(
|
||||
ftd_link,
|
||||
compression="zip",
|
||||
sep="|",
|
||||
engine="python",
|
||||
skipfooter=2,
|
||||
usecols=[0, 2, 3, 5],
|
||||
dtype={"QUANTITY (FAILS)": "int"},
|
||||
)
|
||||
tmp_ftds = all_ftds[all_ftds["SYMBOL"] == ticker]
|
||||
del tmp_ftds["PRICE"]
|
||||
del tmp_ftds["SYMBOL"]
|
||||
# merge the data from this archive
|
||||
ftds_data = pd.concat([ftds_data, tmp_ftds], ignore_index=True)
|
||||
|
||||
ftds_data["SETTLEMENT DATE"] = ftds_data["SETTLEMENT DATE"].apply(
|
||||
lambda x: datetime.strptime(str(x), "%Y%m%d")
|
||||
)
|
||||
|
||||
ftds_data = ftds_data[ftds_data["SETTLEMENT DATE"] > ns_parser.start]
|
||||
ftds_data = ftds_data[ftds_data["SETTLEMENT DATE"] < ns_parser.end]
|
||||
|
||||
plt.bar(
|
||||
ftds_data["SETTLEMENT DATE"],
|
||||
ftds_data["QUANTITY (FAILS)"] / 1000,
|
||||
)
|
||||
plt.ylabel("Shares [K]")
|
||||
plt.title(f"Fails-to-deliver Data for {ticker}")
|
||||
plt.grid(b=True, which="major", color="#666666", linestyle="-", alpha=0.2)
|
||||
plt.gca().xaxis.set_major_formatter(mdates.DateFormatter("%Y/%m/%d"))
|
||||
plt.gca().xaxis.set_major_locator(mdates.DayLocator(interval=7))
|
||||
plt.gcf().autofmt_xdate()
|
||||
plt.xlabel("Days")
|
||||
|
||||
_ = plt.gca().twinx()
|
||||
|
||||
if ns_parser.n_num > 0:
|
||||
stock_ftd = stock[
|
||||
stock.index > (datetime.now() - timedelta(days=ns_parser.n_num + 31))
|
||||
]
|
||||
else:
|
||||
stock_ftd = stock[stock.index > ns_parser.start]
|
||||
stock_ftd = stock_ftd[stock_ftd.index < ns_parser.end]
|
||||
plt.plot(stock_ftd.index, stock_ftd["Adj Close"], color="tab:orange")
|
||||
plt.ylabel("Share Price [$]")
|
||||
|
||||
if gtff.USE_ION:
|
||||
plt.ion()
|
||||
|
||||
plt.show()
|
||||
print("")
|
||||
|
||||
if ns_parser.raw:
|
||||
print(
|
||||
tabulate(
|
||||
ftds_data,
|
||||
headers=ftds_data.columns,
|
||||
tablefmt="fancy_grid",
|
||||
stralign="right",
|
||||
showindex=False,
|
||||
)
|
||||
)
|
||||
print("")
|
||||
|
||||
export_data(
|
||||
ns_parser.export,
|
||||
os.path.dirname(os.path.abspath(__file__)),
|
||||
"ftd",
|
||||
ftds_data.reset_index(),
|
||||
)
|
||||
|
||||
except Exception as e:
|
||||
print(e, "\n")
|
||||
@@ -1,308 +0,0 @@
|
||||
"""Stockgrid DD View"""
|
||||
__docformat__ = "numpy"
|
||||
|
||||
import argparse
|
||||
import os
|
||||
from typing import List
|
||||
from datetime import timedelta
|
||||
import requests
|
||||
import pandas as pd
|
||||
import matplotlib.pyplot as plt
|
||||
from tabulate import tabulate
|
||||
from gamestonk_terminal.config_plot import PLOT_DPI
|
||||
from gamestonk_terminal.feature_flags import USE_ION
|
||||
from gamestonk_terminal.helper_funcs import (
|
||||
parse_known_args_and_warn,
|
||||
plot_autoscale,
|
||||
check_positive,
|
||||
export_data,
|
||||
)
|
||||
|
||||
|
||||
def shortview(ticker: str, other_args: List[str]):
|
||||
"""Plot price vs short interest volume
|
||||
|
||||
Parameters
|
||||
----------
|
||||
ticker: str
|
||||
Stock to plot for
|
||||
other_args : List[str]
|
||||
Argparse arguments
|
||||
|
||||
"""
|
||||
parser = argparse.ArgumentParser(
|
||||
prog="shortvol",
|
||||
add_help=False,
|
||||
description="Shows price vs short interest volume. [Source: Stockgrid]",
|
||||
)
|
||||
parser.add_argument(
|
||||
"-n",
|
||||
"--number",
|
||||
help="Number of last open market days to show",
|
||||
type=check_positive,
|
||||
default=10 if "-r" in other_args else 120,
|
||||
dest="num",
|
||||
)
|
||||
parser.add_argument(
|
||||
"-r",
|
||||
action="store_true",
|
||||
default=False,
|
||||
help="Flag to print raw data instead",
|
||||
dest="raw",
|
||||
)
|
||||
parser.add_argument(
|
||||
"--export",
|
||||
choices=["csv", "json", "xlsx"],
|
||||
default="",
|
||||
dest="export",
|
||||
help="Export dataframe data to csv,json,xlsx file",
|
||||
)
|
||||
|
||||
try:
|
||||
ns_parser = parse_known_args_and_warn(parser, other_args)
|
||||
if not ns_parser:
|
||||
return
|
||||
link = f"https://stockgridapp.herokuapp.com/get_dark_pool_individual_data?ticker={ticker}"
|
||||
response = requests.get(link)
|
||||
|
||||
df = pd.DataFrame(response.json()["individual_short_volume_table"]["data"])
|
||||
df["date"] = pd.to_datetime(df["date"])
|
||||
|
||||
if ns_parser.raw:
|
||||
df = df.sort_values(by="date", ascending=False)
|
||||
|
||||
df["Short Vol. (1M)"] = df["short_volume"] / 1_000_000
|
||||
df["Short Vol. %"] = df["short_volume%"] * 100
|
||||
df["Short Exempt Vol. (1K)"] = df["short_exempt_volume"] / 1_000
|
||||
df["Total Vol. (1M)"] = df["total_volume"] / 1_000_000
|
||||
|
||||
df = df[
|
||||
[
|
||||
"date",
|
||||
"Short Vol. (1M)",
|
||||
"Short Vol. %",
|
||||
"Short Exempt Vol. (1K)",
|
||||
"Total Vol. (1M)",
|
||||
]
|
||||
]
|
||||
|
||||
df.date = df.date.dt.date
|
||||
|
||||
print(
|
||||
tabulate(
|
||||
df.iloc[: ns_parser.num],
|
||||
tablefmt="fancy_grid",
|
||||
floatfmt=".2f",
|
||||
headers=list(df.columns),
|
||||
showindex=False,
|
||||
)
|
||||
)
|
||||
else:
|
||||
prices = response.json()["prices"]["prices"]
|
||||
|
||||
_, axes = plt.subplots(
|
||||
2,
|
||||
1,
|
||||
figsize=(plot_autoscale()),
|
||||
dpi=PLOT_DPI,
|
||||
gridspec_kw={"height_ratios": [2, 1]},
|
||||
)
|
||||
|
||||
axes[0].bar(
|
||||
df["date"],
|
||||
df["total_volume"] / 1_000_000,
|
||||
width=timedelta(days=1),
|
||||
color="b",
|
||||
alpha=0.4,
|
||||
label="Total Volume",
|
||||
)
|
||||
axes[0].bar(
|
||||
df["date"],
|
||||
df["short_volume"] / 1_000_000,
|
||||
width=timedelta(days=1),
|
||||
color="r",
|
||||
alpha=0.4,
|
||||
label="Short Volume",
|
||||
)
|
||||
|
||||
axes[0].set_ylabel("Volume (1M)")
|
||||
ax2 = axes[0].twinx()
|
||||
ax2.plot(
|
||||
df["date"].values, prices[len(prices) - len(df) :], c="k", label="Price"
|
||||
)
|
||||
ax2.set_ylabel("Price ($)")
|
||||
|
||||
lines, labels = axes[0].get_legend_handles_labels()
|
||||
lines2, labels2 = ax2.get_legend_handles_labels()
|
||||
ax2.legend(lines + lines2, labels + labels2, loc="upper left")
|
||||
|
||||
axes[0].set_xlim(
|
||||
df["date"].values[max(0, len(df) - ns_parser.num)],
|
||||
df["date"].values[len(df) - 1],
|
||||
)
|
||||
|
||||
axes[0].grid()
|
||||
axes[0].ticklabel_format(style="plain", axis="y")
|
||||
plt.title(f"Price vs Short Volume Interest for {ticker}")
|
||||
plt.gcf().autofmt_xdate()
|
||||
|
||||
axes[1].plot(
|
||||
df["date"].values,
|
||||
100 * df["short_volume%"],
|
||||
c="green",
|
||||
label="Short Vol. %",
|
||||
)
|
||||
|
||||
axes[1].set_xlim(
|
||||
df["date"].values[max(0, len(df) - ns_parser.num)],
|
||||
df["date"].values[len(df) - 1],
|
||||
)
|
||||
axes[1].set_ylabel("Short Vol. %")
|
||||
|
||||
axes[1].grid(axis="y")
|
||||
lines, labels = axes[1].get_legend_handles_labels()
|
||||
axes[1].legend(lines, labels, loc="upper left")
|
||||
axes[1].set_ylim([0, 100])
|
||||
|
||||
if USE_ION:
|
||||
plt.ion()
|
||||
|
||||
plt.show()
|
||||
print("")
|
||||
|
||||
export_data(
|
||||
ns_parser.export,
|
||||
os.path.dirname(os.path.abspath(__file__)),
|
||||
"shortview",
|
||||
df,
|
||||
)
|
||||
|
||||
except Exception as e:
|
||||
print(e, "\n")
|
||||
|
||||
|
||||
def darkpos(ticker: str, other_args: List[str]):
|
||||
"""Plot dark pool position
|
||||
|
||||
Parameters
|
||||
----------
|
||||
ticker: str
|
||||
Stock to plot for
|
||||
other_args : List[str]
|
||||
Argparse arguments
|
||||
|
||||
"""
|
||||
parser = argparse.ArgumentParser(
|
||||
prog="darkpos",
|
||||
add_help=False,
|
||||
description="Shows Net Short Vol. vs Position. [Source: Stockgrid]",
|
||||
)
|
||||
parser.add_argument(
|
||||
"-n",
|
||||
"--number",
|
||||
help="Number of last open market days to show",
|
||||
type=check_positive,
|
||||
default=10 if "-r" in other_args else 120,
|
||||
dest="num",
|
||||
)
|
||||
parser.add_argument(
|
||||
"-r",
|
||||
action="store_true",
|
||||
default=False,
|
||||
help="Flag to print raw data instead",
|
||||
dest="raw",
|
||||
)
|
||||
parser.add_argument(
|
||||
"--export",
|
||||
choices=["csv", "json", "xlsx"],
|
||||
default="",
|
||||
dest="export",
|
||||
help="Export dataframe data to csv,json,xlsx file",
|
||||
)
|
||||
|
||||
try:
|
||||
ns_parser = parse_known_args_and_warn(parser, other_args)
|
||||
if not ns_parser:
|
||||
return
|
||||
link = f"https://stockgridapp.herokuapp.com/get_dark_pool_individual_data?ticker={ticker}"
|
||||
response = requests.get(link)
|
||||
|
||||
df = pd.DataFrame(response.json()["individual_dark_pool_position_data"])
|
||||
df["dates"] = pd.to_datetime(df["dates"])
|
||||
|
||||
if ns_parser.raw:
|
||||
df = df.sort_values(by="dates", ascending=False)
|
||||
|
||||
df["Net Short Vol. (1k $)"] = df["dollar_net_volume"] / 1_000
|
||||
df["Position (1M $)"] = df["dollar_dp_position"]
|
||||
|
||||
df = df[
|
||||
[
|
||||
"dates",
|
||||
"Net Short Vol. (1k $)",
|
||||
"Position (1M $)",
|
||||
]
|
||||
]
|
||||
|
||||
df["dates"] = df["dates"].dt.date
|
||||
|
||||
print(
|
||||
tabulate(
|
||||
df.iloc[: ns_parser.num],
|
||||
tablefmt="fancy_grid",
|
||||
floatfmt=".2f",
|
||||
headers=list(df.columns),
|
||||
showindex=False,
|
||||
)
|
||||
)
|
||||
|
||||
else:
|
||||
fig = plt.figure(figsize=plot_autoscale(), dpi=PLOT_DPI)
|
||||
|
||||
ax = fig.add_subplot(111)
|
||||
ax.bar(
|
||||
df["dates"],
|
||||
df["dollar_net_volume"] / 1_000,
|
||||
color="r",
|
||||
alpha=0.4,
|
||||
label="Net Short Vol. (1k $)",
|
||||
)
|
||||
ax.set_ylabel("Net Short Vol. (1k $)")
|
||||
|
||||
ax2 = ax.twinx()
|
||||
ax2.plot(
|
||||
df["dates"].values,
|
||||
df["dollar_dp_position"],
|
||||
c="tab:blue",
|
||||
label="Position (1M $)",
|
||||
)
|
||||
ax2.set_ylabel("Position (1M $)")
|
||||
|
||||
lines, labels = ax.get_legend_handles_labels()
|
||||
lines2, labels2 = ax2.get_legend_handles_labels()
|
||||
ax2.legend(lines + lines2, labels + labels2, loc="upper left")
|
||||
|
||||
ax.set_xlim(
|
||||
df["dates"].values[max(0, len(df) - ns_parser.num)],
|
||||
df["dates"].values[len(df) - 1],
|
||||
)
|
||||
|
||||
ax.grid()
|
||||
plt.title(f"Net Short Vol. vs Position for {ticker}")
|
||||
plt.gcf().autofmt_xdate()
|
||||
|
||||
if USE_ION:
|
||||
plt.ion()
|
||||
|
||||
plt.show()
|
||||
print("")
|
||||
|
||||
export_data(
|
||||
ns_parser.export,
|
||||
os.path.dirname(os.path.abspath(__file__)),
|
||||
"darkpos",
|
||||
df,
|
||||
)
|
||||
|
||||
except Exception as e:
|
||||
print(e, "\n")
|
||||
@@ -26,6 +26,7 @@ from gamestonk_terminal.stocks.behavioural_analysis import ba_controller
|
||||
from gamestonk_terminal.stocks.residuals_analysis import ra_controller
|
||||
from gamestonk_terminal.stocks.exploratory_data_analysis import eda_controller
|
||||
from gamestonk_terminal.stocks.report import report_controller
|
||||
from gamestonk_terminal.stocks.dark_pool_shorts import dps_controller
|
||||
|
||||
from gamestonk_terminal.options import options_controller
|
||||
|
||||
@@ -65,6 +66,7 @@ class StocksController:
|
||||
"pred",
|
||||
"ra",
|
||||
"disc",
|
||||
"dps",
|
||||
"scr",
|
||||
"ins",
|
||||
"gov",
|
||||
@@ -98,6 +100,7 @@ class StocksController:
|
||||
|
||||
def print_help(self):
|
||||
"""Print help"""
|
||||
|
||||
s_intraday = (f"Intraday {self.interval}", "Daily")[self.interval == "1440min"]
|
||||
if self.ticker and self.start:
|
||||
stock_text = f"{s_intraday} Stock: {self.ticker} (from {self.start.strftime('%Y-%m-%d')})"
|
||||
@@ -126,6 +129,7 @@ Market {('CLOSED', 'OPEN')[b_is_stock_market_open()]}
|
||||
>> options go into options context {'with ' if self.ticker else ''}{self.ticker}
|
||||
|
||||
> disc discover trending stocks, \t e.g. map, sectors, high short interest
|
||||
> dps dark pool and short data, \t e.g. darkpool, short interest, ftd
|
||||
> scr screener stocks, \t\t e.g. overview/performance, using preset filters
|
||||
> ins insider trading, \t e.g.: latest penny stock buys, top officer purchases
|
||||
> gov government menu, \t\t e.g. house trading, contracts, corporate lobbying
|
||||
@@ -255,6 +259,14 @@ Market {('CLOSED', 'OPEN')[b_is_stock_market_open()]}
|
||||
else:
|
||||
return True
|
||||
|
||||
def call_dps(self, _):
|
||||
"""Process dps command"""
|
||||
ret = dps_controller.menu(self.ticker, self.start, self.stock)
|
||||
if ret is False:
|
||||
self.print_help()
|
||||
else:
|
||||
return True
|
||||
|
||||
def call_scr(self, _):
|
||||
"""Process scr command"""
|
||||
ret = screener_controller.menu()
|
||||
|
||||
146
notebooks/templates/dark_pool.ipynb
vendored
146
notebooks/templates/dark_pool.ipynb
vendored
@@ -3,7 +3,7 @@
|
||||
{
|
||||
"cell_type": "code",
|
||||
"execution_count": null,
|
||||
"id": "weighted-pharmacy",
|
||||
"id": "driven-billion",
|
||||
"metadata": {
|
||||
"collapsed": true
|
||||
},
|
||||
@@ -27,7 +27,7 @@
|
||||
{
|
||||
"cell_type": "code",
|
||||
"execution_count": null,
|
||||
"id": "photographic-wings",
|
||||
"id": "intended-sherman",
|
||||
"metadata": {
|
||||
"collapsed": true,
|
||||
"tags": [
|
||||
@@ -43,7 +43,7 @@
|
||||
{
|
||||
"cell_type": "code",
|
||||
"execution_count": null,
|
||||
"id": "successful-tradition",
|
||||
"id": "mounted-phase",
|
||||
"metadata": {
|
||||
"collapsed": true
|
||||
},
|
||||
@@ -55,19 +55,28 @@
|
||||
{
|
||||
"cell_type": "code",
|
||||
"execution_count": null,
|
||||
"id": "recreational-newsletter",
|
||||
"id": "built-second",
|
||||
"metadata": {
|
||||
"collapsed": true
|
||||
},
|
||||
"outputs": [],
|
||||
"source": [
|
||||
"from gamestonk_terminal.common.technical_analysis import trendline_api as trend\n",
|
||||
"from gamestonk_terminal.stocks.due_diligence import finviz_view as finviz"
|
||||
"from gamestonk_terminal.stocks.dark_pool_shorts import (\n",
|
||||
" stockgrid_view,\n",
|
||||
" sec_view,\n",
|
||||
" finra_view,\n",
|
||||
" shortinterest_view\n",
|
||||
")\n",
|
||||
"\n",
|
||||
"from gamestonk_terminal.options import barchart_view, yfinance_model, yfinance_view\n",
|
||||
"from gamestonk_terminal.stocks import stocks_helper\n",
|
||||
"from datetime import datetime, timedelta"
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "markdown",
|
||||
"id": "nervous-edgar",
|
||||
"id": "capable-allergy",
|
||||
"metadata": {},
|
||||
"source": [
|
||||
"## Top 10 Negative Dark Pool Positions"
|
||||
@@ -76,52 +85,90 @@
|
||||
{
|
||||
"cell_type": "code",
|
||||
"execution_count": null,
|
||||
"id": "opponent-atlas",
|
||||
"id": "statewide-debate",
|
||||
"metadata": {
|
||||
"collapsed": true
|
||||
},
|
||||
"outputs": [],
|
||||
"source": [
|
||||
"from gamestonk_terminal.stocks.discovery import stockgrid_view\n",
|
||||
"stockgrid_view.darkshort([\"-a\"])"
|
||||
"stockgrid_view.dark_pool_short_positions(num=10, \n",
|
||||
" sort_field=\"dpp_dollar\", \n",
|
||||
" ascending=True, \n",
|
||||
" export=\"\")"
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "markdown",
|
||||
"id": "faced-stranger",
|
||||
"id": "artificial-tampa",
|
||||
"metadata": {},
|
||||
"source": [
|
||||
"## Previous Ten Days of trading data for the Dark Pool"
|
||||
"## Top 10 Most Highly Shorted Stocks"
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "code",
|
||||
"execution_count": null,
|
||||
"id": "exterior-royal",
|
||||
"id": "smaller-association",
|
||||
"metadata": {
|
||||
"collapsed": true
|
||||
},
|
||||
"outputs": [],
|
||||
"source": [
|
||||
"from gamestonk_terminal.stocks.due_diligence import stockgrid_dd_view\n",
|
||||
"stockgrid_dd_view.darkpos(ticker.upper(), [\"-n\", \"10\", \"-r\"])"
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "code",
|
||||
"execution_count": null,
|
||||
"id": "polar-plain",
|
||||
"metadata": {
|
||||
"collapsed": true
|
||||
},
|
||||
"outputs": [],
|
||||
"source": [
|
||||
"stockgrid_dd_view.shortview(ticker.upper(), [\"-n\", \"10\", \"-r\"])"
|
||||
"shortinterest_view.high_short_interest(num=10,\n",
|
||||
" export=\"\")"
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "markdown",
|
||||
"id": "foster-amendment",
|
||||
"id": "cleared-contemporary",
|
||||
"metadata": {},
|
||||
"source": [
|
||||
"## Dark Pool Activity"
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "code",
|
||||
"execution_count": null,
|
||||
"id": "medical-tomato",
|
||||
"metadata": {
|
||||
"collapsed": true
|
||||
},
|
||||
"outputs": [],
|
||||
"source": [
|
||||
"stockgrid_view.net_short_position(ticker=ticker.upper(), \n",
|
||||
" num=60,\n",
|
||||
" raw=False,\n",
|
||||
" export=\"\")\n",
|
||||
"\n",
|
||||
"stockgrid_view.net_short_position(ticker=ticker.upper(), \n",
|
||||
" num=10,\n",
|
||||
" raw=True,\n",
|
||||
" export=\"\")"
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "code",
|
||||
"execution_count": null,
|
||||
"id": "comprehensive-nashville",
|
||||
"metadata": {
|
||||
"collapsed": true
|
||||
},
|
||||
"outputs": [],
|
||||
"source": [
|
||||
"stockgrid_view.short_interest_volume(ticker=ticker.upper(), \n",
|
||||
" num=60,\n",
|
||||
" raw=False,\n",
|
||||
" export=\"\")\n",
|
||||
"\n",
|
||||
"stockgrid_view.short_interest_volume(ticker=ticker.upper(), \n",
|
||||
" num=10,\n",
|
||||
" raw=True,\n",
|
||||
" export=\"\")"
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "markdown",
|
||||
"id": "decreased-mills",
|
||||
"metadata": {},
|
||||
"source": [
|
||||
"## Options info"
|
||||
@@ -130,47 +177,48 @@
|
||||
{
|
||||
"cell_type": "code",
|
||||
"execution_count": null,
|
||||
"id": "opponent-requirement",
|
||||
"id": "medical-shaft",
|
||||
"metadata": {
|
||||
"collapsed": true
|
||||
},
|
||||
"outputs": [],
|
||||
"source": [
|
||||
"from gamestonk_terminal.options import barchart_view\n",
|
||||
"barchart_view.print_options_data(ticker.upper(), [])"
|
||||
"barchart_view.print_options_data(ticker=ticker.upper(), \n",
|
||||
" export=\"\")"
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "markdown",
|
||||
"id": "junior-paper",
|
||||
"id": "understood-houston",
|
||||
"metadata": {},
|
||||
"source": [
|
||||
"## Put and Call Open Interest Expiring"
|
||||
"## Put and Call Open Interest Expiring next"
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "code",
|
||||
"execution_count": null,
|
||||
"id": "general-reserve",
|
||||
"id": "acute-burning",
|
||||
"metadata": {
|
||||
"collapsed": true
|
||||
},
|
||||
"outputs": [],
|
||||
"source": [
|
||||
"from gamestonk_terminal.options import yfinance_model, yfinance_view\n",
|
||||
"selected_date = yfinance_model.option_expirations(ticker)[0]\n",
|
||||
"\n",
|
||||
"from gamestonk_terminal.options import op_helpers\n",
|
||||
"parsed = op_helpers.oi([\"--source\", \"yf\"])\n",
|
||||
"\n",
|
||||
"#from gamestonk_terminal.options import op_helpers\n",
|
||||
"options = yfinance_model.get_option_chain(ticker, selected_date)\n",
|
||||
"yfinance_view.plot_oi(options.calls, options.puts, ticker, selected_date, parsed)"
|
||||
"\n",
|
||||
"yfinance_view.plot_oi(ticker=ticker,\n",
|
||||
" expiry=selected_date,\n",
|
||||
" min_sp=-1,\n",
|
||||
" max_sp=-1,\n",
|
||||
" calls_only=False,\n",
|
||||
" puts_only=False,\n",
|
||||
" export=\"\")"
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "markdown",
|
||||
"id": "decreased-foster",
|
||||
"id": "convinced-orleans",
|
||||
"metadata": {},
|
||||
"source": [
|
||||
"## Failure-to-deliver (30 days lag)"
|
||||
@@ -179,23 +227,29 @@
|
||||
{
|
||||
"cell_type": "code",
|
||||
"execution_count": null,
|
||||
"id": "armed-ridge",
|
||||
"id": "capital-narrow",
|
||||
"metadata": {
|
||||
"collapsed": true
|
||||
},
|
||||
"outputs": [],
|
||||
"source": [
|
||||
"from gamestonk_terminal.stocks import stocks_helper\n",
|
||||
"_, _, _, stock = stocks_helper.load([\"-t\", ticker], \"\", \"\", 1440, pd.DataFrame())\n",
|
||||
"\n",
|
||||
"from gamestonk_terminal.stocks.due_diligence import sec_view\n",
|
||||
"sec_view.fails_to_deliver([], ticker.upper(), stock)"
|
||||
"sec_view.fails_to_deliver(\n",
|
||||
" ticker=ticker.upper(), \n",
|
||||
" stock=stock,\n",
|
||||
" start=datetime.now() - timedelta(days=60),\n",
|
||||
" end=datetime.now(),\n",
|
||||
" num=0,\n",
|
||||
" raw=False,\n",
|
||||
" export=\"\"\n",
|
||||
")"
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "code",
|
||||
"execution_count": null,
|
||||
"id": "noted-mobile",
|
||||
"id": "above-prior",
|
||||
"metadata": {
|
||||
"collapsed": true
|
||||
},
|
||||
|
||||
@@ -1,4 +1,4 @@
|
||||
""" discovery/short_interest_api.py tests """
|
||||
""" dark_pool_shorts/short_interest_api.py tests """
|
||||
import unittest
|
||||
from unittest import mock
|
||||
|
||||
@@ -8,15 +8,15 @@ from gamestonk_terminal.test_helper import ( # noqa: F401
|
||||
pytest_generate_tests,
|
||||
)
|
||||
|
||||
from gamestonk_terminal.stocks.discovery.shortinterest_model import (
|
||||
get_high_short_interest,
|
||||
get_low_float,
|
||||
)
|
||||
# from gamestonk_terminal.stocks.dark_pool_shorts.shortinterest_model import get_high_short_interest
|
||||
from gamestonk_terminal.stocks.discovery.shortinterest_model import get_low_float
|
||||
|
||||
assertions = unittest.TestCase("__init__")
|
||||
|
||||
|
||||
class TestDiscoveryShortInterestApi:
|
||||
"""
|
||||
# TODO
|
||||
@mock.patch("gamestonk_terminal.stocks.discovery.shortinterest_model.requests")
|
||||
@parameterize_from_file(
|
||||
"test_get_high_short_interest",
|
||||
@@ -35,6 +35,7 @@ class TestDiscoveryShortInterestApi:
|
||||
df_high_short.to_csv().replace("\r\n", "\n"),
|
||||
expected_result.replace("\r\n", "\n"),
|
||||
)
|
||||
"""
|
||||
|
||||
@mock.patch("gamestonk_terminal.stocks.discovery.shortinterest_model.requests")
|
||||
@parameterize_from_file(
|
||||
|
||||
Reference in New Issue
Block a user