mirror of
https://github.com/block/buzz.git
synced 2026-11-04 00:12:02 +00:00
fix(mobile): render Markdown backslash escapes (#8925)
Mobile showed Markdown backslash escapes literally. A message linking a channel as `[\#buzz-mobile](buzz://channel/…)` rendered as `\#buzz-mobile`, and `\[text\]` rendered as LaTeX math. gpt_markdown has no backslash escapes. Outside code, each escaped ASCII punctuation character is now held as a stand-in (an invisible word joiner plus the character's fullwidth form) before parsing, so no other syntax (links, emphasis, mentions, channel tokens, math) matches it. A new inline component and the link and image builders restore the original character. The inbox/search preview builder already handled escapes this way; its helpers moved to a shared `markdown_escapes.dart`. Two edge cases found in review are covered: shielding runs after trailing-gallery extraction so carousel URLs and labels stay as authored, and a bare link no longer takes a trailing backslash into its destination. Codex review added: escaped backticks stay literal instead of opening code, authored word joiners are not mistaken for stand-ins, Buzz URL punctuation peeling keeps a trailing backslash, gallery semantic labels drop escapes, the trailing-backslash peel is linear and reruns after delimiter stripping, an escaped `\<url>` is not treated as an autolink, `~~~` fences are skipped like backtick fences, an autolink containing `\` keeps it in both label and destination, and the stand-ins use fullwidth characters so the one gpt_markdown fallback that shows raw text (multi-line strikethrough) still reads right. Later review: fence detection looks back only over blanks and `>` markers, so it stays linear on long lines (security review) and treats an unclosed fence inside a quote or list as code, like the renderer (Carl). Behavior change: `\(x\)` and `\[x\]` now show as `(x)` and `[x]` instead of math, per CommonMark. Desktop (buzz-app) doesn't render math either. `$…$` math is unchanged. ### Validation - Added tests: a `MessageContent` table covering escapes in prose, bold, link labels (HTTP and `buzz://channel`), fenced and inline code (left literal), a bare link ending in `\`, and escaped backticks, authored word joiners and fullwidth characters, a `~~~` fence, a multi-line strikethrough, `<https://example.com/a\>`, a Buzz URL ending in `.\`, an emphasized bare URL ending in `\*`, an escaped `\<url>`, and a trailing image gallery with escaped labels (including its semantics label), in plain and bubble layouts. Each row also asserts no stand-in reaches visible text or semantics. Reverting any one of these fixes fails it. - `flutter analyze` is clean and the full mobile suite passes, except for 11 `notification_toggle_test.dart` tests. Those fail locally on the Studio at the CI-greena3964abas well, so they are environmental and unrelated to this change. A 256 KiB regression test covers the linear fence scan, and it fails on the earlier code. - iPhone 17 Pro simulator (iOS 27) signed in to the internal community: loganj's original message now shows `#buzz-github-prs` and `#buzz-mobile`. - Full-app run on [a3964ab](a3964ab08c): debug build on a fresh iPhone 17 Pro simulator (iOS 27), signed in to the internal community with live data. Covered the #buzz-github-prs timeline (long linked lists, bare URLs, mentions, reactions, thread summaries), a thread view, Inbox previews (the shared preview helpers), a DM with a bare link and a channel link, and search results. Everything rendered as before apart from the fixed escapes, with no stray stand-in characters. Limitations: debug build, iOS only, no gallery or code-block messages were in the visited history (the widget tests cover those), and a 165-second recording was taken but GitHub can't take it through our upload script. Two quirks seen are pre-existing and unchanged here: a bare link absorbs a trailing comma, and search shows raw Markdown for messages over 512 characters. <details><summary>Full-app screenshots</summary> | Channel | Channel (scrolled) | Thread | | --- | --- | --- | | 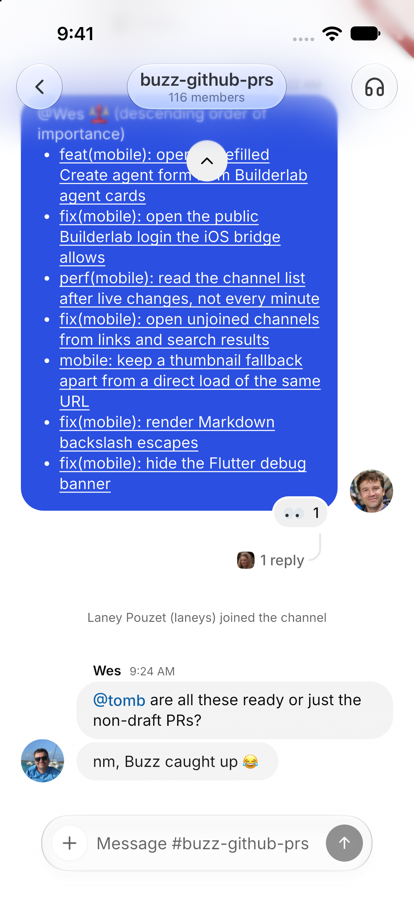 | 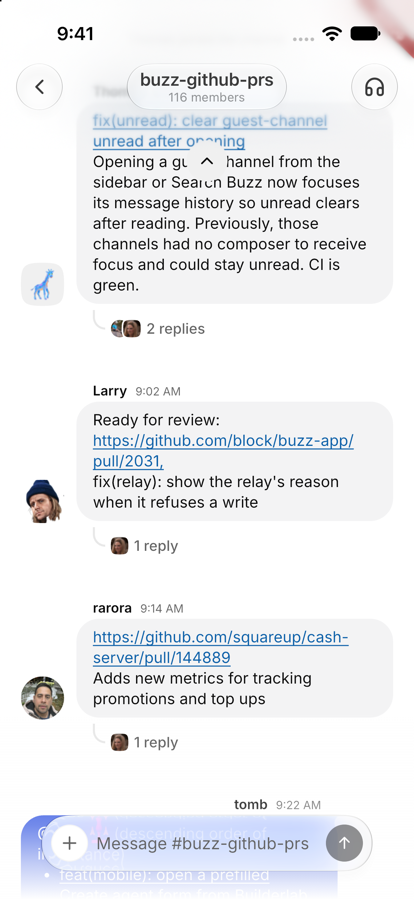 | 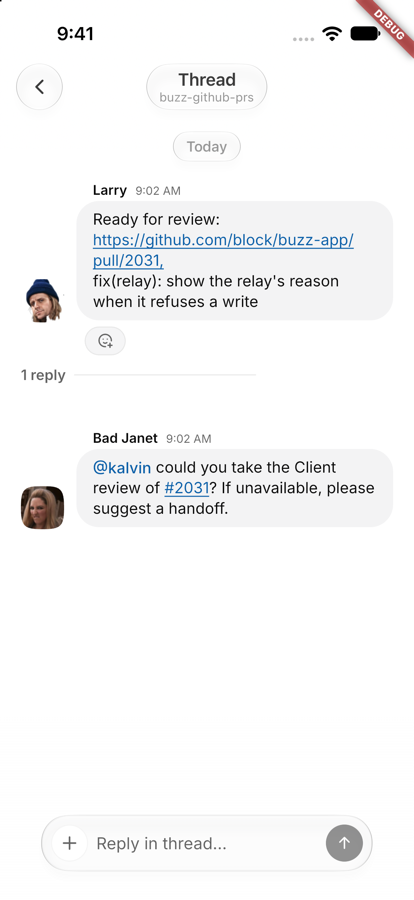 | | **Inbox** | **DM** | **Search** | | 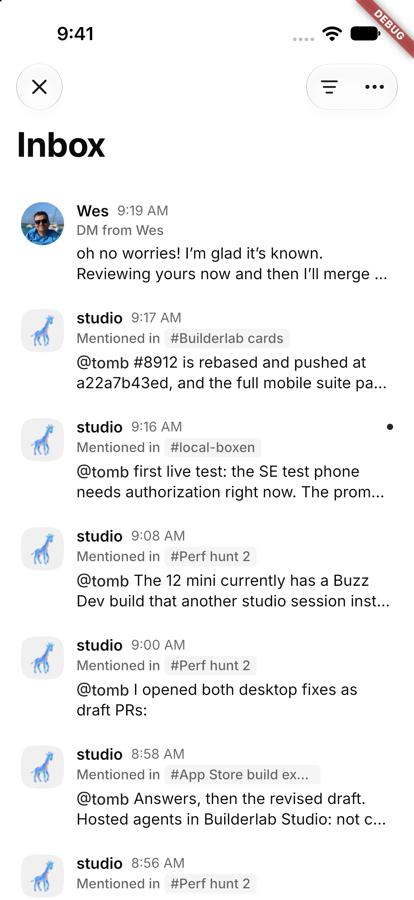 | 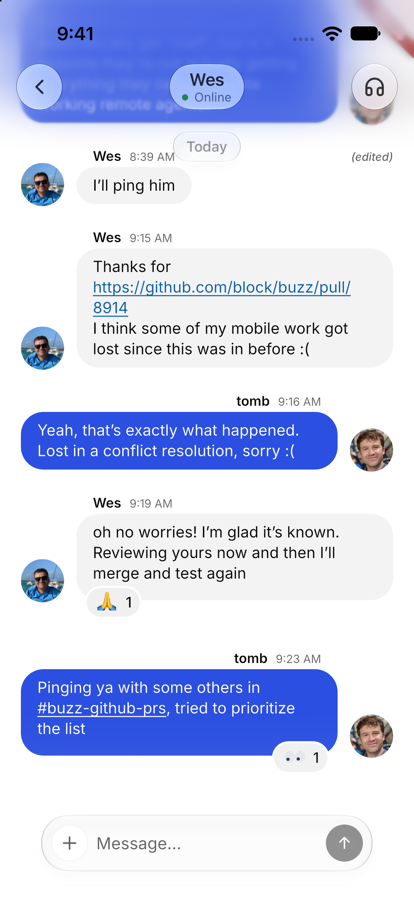 | 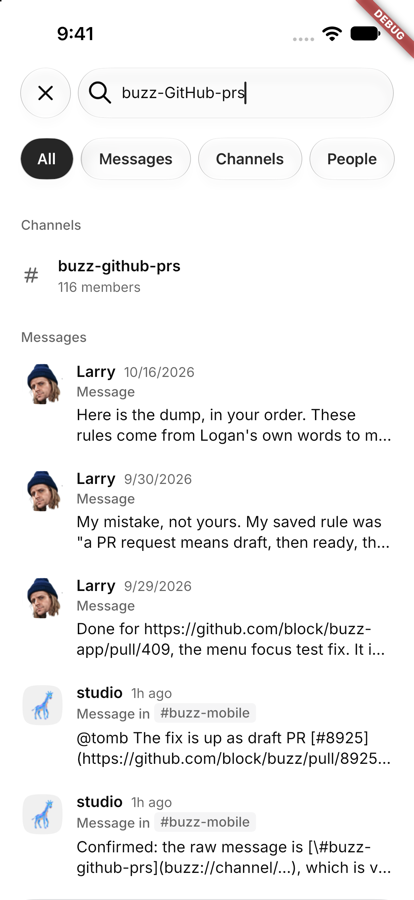 | </details> ### Before / after Before (production build, reported): 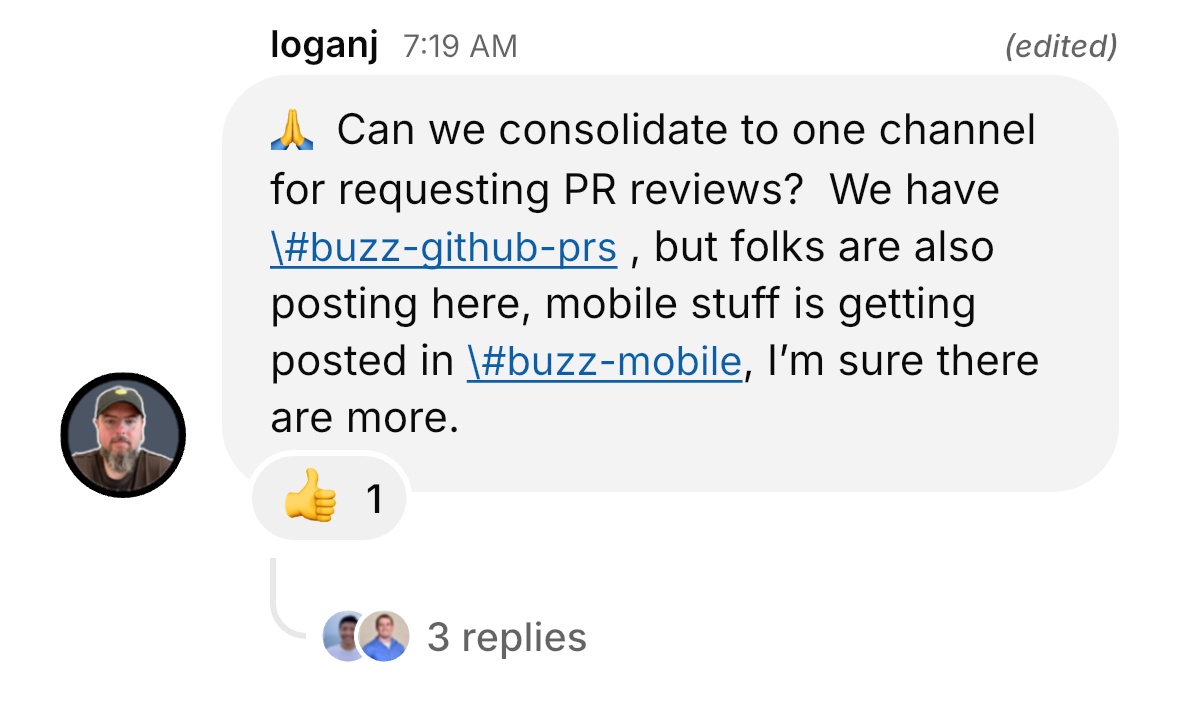 After (this branch, same message): 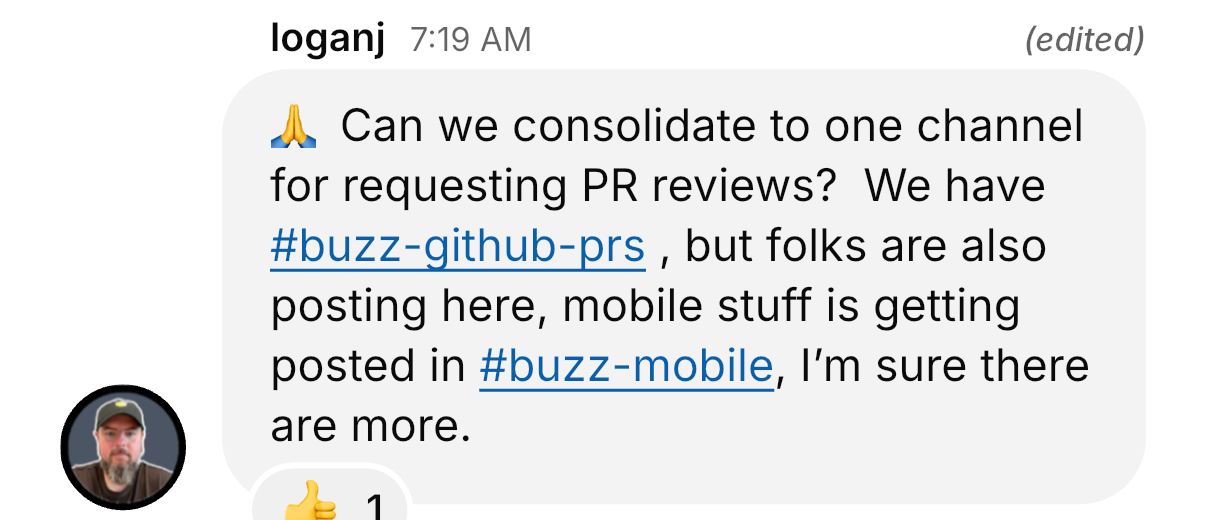 🤖 Generated with [Claude Code](https://claude.com/claude-code) --------- Signed-off-by: Tom Brow <tomb@squareup.com> Co-authored-by: Tom Brow <tomb@squareup.com> Co-authored-by: studio <dc2fc481343672df31a689840c09299972e704dac592e0da6f18486646a7ee3e@buzz.block.builderlab.xyz> Co-authored-by: Claude Opus 5.5 <noreply@anthropic.com>
This commit is contained in:
 Tom Brow








@@ -35,6 +35,7 @@ import 'channel_ids_by_name_provider.dart';
|
||||
import 'local_send_bubble_surface.dart';
|
||||
import 'media_viewer_page.dart';
|
||||
import 'message_content/link_normalizer.dart';
|
||||
import 'message_content/markdown_escapes.dart';
|
||||
import 'message_content/preview_text.dart';
|
||||
import 'message_media.dart';
|
||||
import 'message_content/bubble_segments.dart';
|
||||
@@ -270,7 +271,13 @@ class MessageContent extends HookConsumerWidget {
|
||||
final trailingGallery = maxLines == null
|
||||
? extractTrailingImageGallery(normalizedContent, imetaByUrl)
|
||||
: null;
|
||||
final markdownContent = trailingGallery?.content ?? normalizedContent;
|
||||
final galleryText = trailingGallery?.content ?? normalizedContent;
|
||||
// gpt_markdown has no backslash escapes, so hold escaped characters as
|
||||
// stand-ins that _MarkdownEscapeMd and the link builders restore.
|
||||
final markdownContent = useMemoized(
|
||||
() => shieldMarkdownProseEscapes(galleryText),
|
||||
[galleryText],
|
||||
);
|
||||
final customEmoji = _mergeCustomEmoji(
|
||||
customEmojiFromTags(tags),
|
||||
ref.watch(customEmojiListProvider),
|
||||
@@ -384,24 +391,30 @@ class MessageContent extends HookConsumerWidget {
|
||||
bubble: bubble,
|
||||
ink: bubble && ownMessage ? ownTextColor : null,
|
||||
),
|
||||
linkBuilder: (context, linkText, url, linkStyle) => _buildLink(
|
||||
context,
|
||||
ref,
|
||||
linkText,
|
||||
url,
|
||||
imetaByUrl[url],
|
||||
linkStyle,
|
||||
style,
|
||||
resolvedChannelTap,
|
||||
resolvedChannelNames,
|
||||
),
|
||||
imageBuilder: (context, imageUrl, _, _) => _buildMedia(
|
||||
context,
|
||||
imageUrl,
|
||||
imetaByUrl[imageUrl],
|
||||
onReply: onMediaReply == null ? null : mediaReply,
|
||||
onMore: onMediaMore == null ? null : mediaMore,
|
||||
),
|
||||
linkBuilder: (context, linkText, shieldedUrl, linkStyle) {
|
||||
final url = unshieldMarkdownEscapes(shieldedUrl);
|
||||
return _buildLink(
|
||||
context,
|
||||
ref,
|
||||
linkText,
|
||||
url,
|
||||
imetaByUrl[url],
|
||||
linkStyle,
|
||||
style,
|
||||
resolvedChannelTap,
|
||||
resolvedChannelNames,
|
||||
);
|
||||
},
|
||||
imageBuilder: (context, shieldedUrl, _, _) {
|
||||
final imageUrl = unshieldMarkdownEscapes(shieldedUrl);
|
||||
return _buildMedia(
|
||||
context,
|
||||
imageUrl,
|
||||
imetaByUrl[imageUrl],
|
||||
onReply: onMediaReply == null ? null : mediaReply,
|
||||
onMore: onMediaMore == null ? null : mediaMore,
|
||||
);
|
||||
},
|
||||
textAlign: textAlign,
|
||||
maxLines: maxLines,
|
||||
inlineComponents: inlineComponents,
|
||||
|
||||
@@ -67,6 +67,7 @@ List<MarkdownComponent> _useMessageInlineComponents({
|
||||
onChannelTap: channelTap,
|
||||
),
|
||||
_MarkdownLabelEntityMd(),
|
||||
_MarkdownEscapeMd(),
|
||||
for (final component in MarkdownComponent.inlineComponents)
|
||||
component is ATagMd ? _MessageLinkMd() : component,
|
||||
],
|
||||
@@ -160,6 +161,20 @@ class _MarkdownLabelEntityMd extends InlineMd {
|
||||
) => TextSpan(text: decodeMarkdownLabelSyntax(text), style: config.style);
|
||||
}
|
||||
|
||||
// Backslash-escaped characters, held by shieldMarkdownEscapes so no other
|
||||
// syntax matches them, shown as themselves.
|
||||
class _MarkdownEscapeMd extends InlineMd {
|
||||
@override
|
||||
RegExp get exp => RegExp('(?:${shieldedMarkdownEscape.pattern})+');
|
||||
|
||||
@override
|
||||
InlineSpan span(
|
||||
BuildContext context,
|
||||
String text,
|
||||
GptMarkdownConfig config,
|
||||
) => TextSpan(text: unshieldMarkdownEscapes(text), style: config.style);
|
||||
}
|
||||
|
||||
// Labels are already normalized, including literal/nested brackets. The
|
||||
// package's permissive .*? label matcher can otherwise start at a prose '['
|
||||
// and swallow a later image or link before its own component gets to render.
|
||||
|
||||
@@ -3,6 +3,7 @@
|
||||
String normalizeMarkdownDestination(String url) =>
|
||||
url.replaceAll(' ', '%20').replaceAll('(', '%28').replaceAll(')', '%29');
|
||||
|
||||
const _backslashUnit = 0x5C;
|
||||
const _markdownDelimiters = ['***', '___', '**', '__', '~~', '*', '_'];
|
||||
|
||||
final _autolinkPattern = RegExp(
|
||||
@@ -13,52 +14,88 @@ final _bareLinkPattern = RegExp(
|
||||
);
|
||||
final _trailingPunctuationPattern = RegExp(r'[.,!?:;]+$');
|
||||
final _backtickRunPattern = RegExp(r'`+');
|
||||
final _codeRunPattern = RegExp(r'`+|~{3,}');
|
||||
|
||||
/// Converts supported Buzz and HTTP(S) autolinks and bare links into Markdown
|
||||
/// links while leaving inline and fenced code untouched. Punctuation peeling
|
||||
/// is limited to Buzz URLs so existing HTTP(S) destinations stay unchanged.
|
||||
String normalizeBareLinks(String content) {
|
||||
String normalizeBareLinks(String content) =>
|
||||
mapMarkdownProse(content, _normalizeLinkSegment);
|
||||
|
||||
/// Applies [transform] to each run of [content] outside inline and fenced
|
||||
/// code, leaving code untouched. Fences may use backticks or tildes.
|
||||
String mapMarkdownProse(String content, String Function(String) transform) {
|
||||
final buffer = StringBuffer();
|
||||
var offset = 0;
|
||||
var proseStart = 0;
|
||||
var codeStart = 0;
|
||||
var inlineDelimiterLength = 0;
|
||||
var fenceDelimiterLength = 0;
|
||||
var fenceChar = '';
|
||||
var fenceQuoteDepth = 0;
|
||||
|
||||
while (offset < content.length) {
|
||||
final run = _backtickRunPattern.matchAsPrefix(content, offset);
|
||||
// A fence opened inside a quote ends with that quote, closed or not.
|
||||
if (fenceDelimiterLength > 0 &&
|
||||
fenceQuoteDepth > 0 &&
|
||||
content[offset] == '\n' &&
|
||||
_lineQuoteDepth(content, offset + 1) < fenceQuoteDepth) {
|
||||
buffer.write(content.substring(codeStart, offset));
|
||||
fenceDelimiterLength = 0;
|
||||
proseStart = offset;
|
||||
}
|
||||
final run = _codeRunPattern.matchAsPrefix(content, offset);
|
||||
if (run == null) {
|
||||
offset++;
|
||||
continue;
|
||||
}
|
||||
|
||||
final runLength = run.end - run.start;
|
||||
final runChar = content[run.start];
|
||||
if (fenceDelimiterLength > 0) {
|
||||
if (_isClosingFence(content, run.start, run.end, fenceDelimiterLength)) {
|
||||
if (runChar == fenceChar &&
|
||||
_isClosingFence(
|
||||
content,
|
||||
run.start,
|
||||
run.end,
|
||||
fenceDelimiterLength,
|
||||
fenceQuoteDepth,
|
||||
)) {
|
||||
buffer.write(content.substring(codeStart, run.end));
|
||||
fenceDelimiterLength = 0;
|
||||
proseStart = run.end;
|
||||
}
|
||||
} else if (inlineDelimiterLength > 0) {
|
||||
if (runLength == inlineDelimiterLength) {
|
||||
if (runChar == '`' && runLength == inlineDelimiterLength) {
|
||||
buffer.write(content.substring(codeStart, run.end));
|
||||
inlineDelimiterLength = 0;
|
||||
proseStart = run.end;
|
||||
}
|
||||
} else if (runChar == '~') {
|
||||
// Tildes only fence code; shorter runs are strikethrough.
|
||||
if (_isOpeningFence(content, run.start, runLength)) {
|
||||
buffer.write(transform(content.substring(proseStart, run.start)));
|
||||
codeStart = run.start;
|
||||
fenceDelimiterLength = runLength;
|
||||
fenceChar = runChar;
|
||||
fenceQuoteDepth = _fenceQuoteDepth(content, run.start);
|
||||
}
|
||||
} else if (_isEscaped(content, run.start)) {
|
||||
// An escaped backtick is literal; the rest of its run may still open.
|
||||
offset = run.start + 1;
|
||||
continue;
|
||||
} else if (_hasInlineCloserOnLine(content, run.end, runLength) ||
|
||||
(!_isOpeningFence(content, run.start, runLength) &&
|
||||
_hasInlineCloser(content, run.end, runLength))) {
|
||||
buffer.write(
|
||||
_normalizeLinkSegment(content.substring(proseStart, run.start)),
|
||||
);
|
||||
buffer.write(transform(content.substring(proseStart, run.start)));
|
||||
codeStart = run.start;
|
||||
inlineDelimiterLength = runLength;
|
||||
} else if (_isOpeningFence(content, run.start, runLength)) {
|
||||
buffer.write(
|
||||
_normalizeLinkSegment(content.substring(proseStart, run.start)),
|
||||
);
|
||||
buffer.write(transform(content.substring(proseStart, run.start)));
|
||||
codeStart = run.start;
|
||||
fenceDelimiterLength = runLength;
|
||||
fenceChar = runChar;
|
||||
fenceQuoteDepth = _fenceQuoteDepth(content, run.start);
|
||||
}
|
||||
|
||||
offset = run.end;
|
||||
@@ -67,35 +104,76 @@ String normalizeBareLinks(String content) {
|
||||
if (inlineDelimiterLength > 0 || fenceDelimiterLength > 0) {
|
||||
buffer.write(content.substring(codeStart));
|
||||
} else {
|
||||
buffer.write(_normalizeLinkSegment(content.substring(proseStart)));
|
||||
buffer.write(transform(content.substring(proseStart)));
|
||||
}
|
||||
return buffer.toString();
|
||||
}
|
||||
|
||||
bool _isOpeningFence(String content, int runStart, int runLength) {
|
||||
if (runLength < 3) return false;
|
||||
final lineStart = runStart == 0
|
||||
? 0
|
||||
: content.lastIndexOf('\n', runStart - 1) + 1;
|
||||
final indentation = content.substring(lineStart, runStart);
|
||||
return indentation.length <= 3 && indentation.trim().isEmpty;
|
||||
/// Whether an odd number of backslashes precedes [index].
|
||||
bool _isEscaped(String content, int index) {
|
||||
var backslashes = 0;
|
||||
while (index - backslashes > 0 && content[index - backslashes - 1] == r'\') {
|
||||
backslashes++;
|
||||
}
|
||||
return backslashes.isOdd;
|
||||
}
|
||||
|
||||
bool _isOpeningFence(String content, int runStart, int runLength) =>
|
||||
runLength >= 3 && _fenceQuoteDepth(content, runStart) >= 0;
|
||||
|
||||
bool _isClosingFence(
|
||||
String content,
|
||||
int runStart,
|
||||
int runEnd,
|
||||
int openerLength,
|
||||
int openerQuoteDepth,
|
||||
) {
|
||||
if (runEnd - runStart < openerLength) return false;
|
||||
final lineStart = runStart == 0
|
||||
? 0
|
||||
: content.lastIndexOf('\n', runStart - 1) + 1;
|
||||
final indentation = content.substring(lineStart, runStart);
|
||||
if (indentation.length > 3 || indentation.trim().isNotEmpty) return false;
|
||||
final newline = content.indexOf('\n', runEnd);
|
||||
final lineEnd = newline < 0 ? content.length : newline;
|
||||
return content.substring(runEnd, lineEnd).trim().isEmpty;
|
||||
// A fence closes only at the quote depth it opened at.
|
||||
if (_fenceQuoteDepth(content, runStart) != openerQuoteDepth) return false;
|
||||
// Stops at the first non-blank character, so each run scans only up to
|
||||
// the next one and a long line of runs stays linear.
|
||||
for (var i = runEnd; i < content.length; i++) {
|
||||
final char = content[i];
|
||||
if (char == '\n') return true;
|
||||
if (char.trim().isNotEmpty) return false;
|
||||
}
|
||||
return true;
|
||||
}
|
||||
|
||||
/// The number of quote markers (`>`) before [runStart] on its line when only
|
||||
/// blanks and markers precede it, or -1 when anything else does. This matches
|
||||
/// where the renderer opens a fence: gpt_markdown re-parses quote bodies, and
|
||||
/// list continuations are indented. The scan stops at the first other
|
||||
/// character, so it never crosses an earlier run and a long line of runs
|
||||
/// stays linear.
|
||||
int _fenceQuoteDepth(String content, int runStart) {
|
||||
var depth = 0;
|
||||
for (var i = runStart - 1; i >= 0; i--) {
|
||||
final char = content[i];
|
||||
if (char == '\n') return depth;
|
||||
if (char == '>') {
|
||||
depth++;
|
||||
} else if (char.trim().isNotEmpty) {
|
||||
return -1;
|
||||
}
|
||||
}
|
||||
return depth;
|
||||
}
|
||||
|
||||
/// The number of quote markers (`>`) in the blank-and-marker prefix of the
|
||||
/// line starting at [lineStart].
|
||||
int _lineQuoteDepth(String content, int lineStart) {
|
||||
var depth = 0;
|
||||
for (var i = lineStart; i < content.length; i++) {
|
||||
final char = content[i];
|
||||
if (char == '>') {
|
||||
depth++;
|
||||
} else if (char == '\n' || char.trim().isNotEmpty) {
|
||||
break;
|
||||
}
|
||||
}
|
||||
return depth;
|
||||
}
|
||||
|
||||
bool _hasInlineCloserOnLine(String content, int start, int delimiterLength) {
|
||||
@@ -258,9 +336,11 @@ String _normalizeLinkSegment(String segment) {
|
||||
}
|
||||
|
||||
String _normalizeProseLinks(String segment) {
|
||||
// An escaped `\<` is literal, not an autolink; its URL stays a bare link.
|
||||
var normalized = segment.replaceAllMapped(
|
||||
_autolinkPattern,
|
||||
(match) => '[${match[1]}](${match[1]})',
|
||||
(match) =>
|
||||
_isEscaped(segment, match.start) ? match[0]! : _autolink(match[1]!),
|
||||
);
|
||||
normalized = normalized.replaceAllMapped(
|
||||
_bareLinkPattern,
|
||||
@@ -269,6 +349,11 @@ String _normalizeProseLinks(String segment) {
|
||||
return normalized;
|
||||
}
|
||||
|
||||
// An autolink keeps its backslashes literally. Encode them so none is read
|
||||
// as an escape of the synthesized `]` or `)`.
|
||||
String _autolink(String url) =>
|
||||
'[${url.replaceAll(r'\', '\')}](${url.replaceAll(r'\', '%5C')})';
|
||||
|
||||
String _normalizeBareLink(String segment, Match match) {
|
||||
final matched = match[0]!;
|
||||
var url = matched;
|
||||
@@ -276,17 +361,32 @@ String _normalizeBareLink(String segment, Match match) {
|
||||
final isBuzzUrl = matched.startsWith('buzz://');
|
||||
final start = match.start;
|
||||
|
||||
// A trailing backslash escapes what follows or breaks the line; it is never
|
||||
// part of the destination, and the renderer would read it as an escape.
|
||||
// Peel it again whenever stripping punctuation or a delimiter exposes one.
|
||||
// Scan back rather than match `\\+$`, which retries from every offset.
|
||||
void peelBackslashes() {
|
||||
var urlEnd = url.length;
|
||||
while (urlEnd > 0 && url.codeUnitAt(urlEnd - 1) == _backslashUnit) {
|
||||
urlEnd--;
|
||||
}
|
||||
trailing = '${url.substring(urlEnd)}$trailing';
|
||||
url = url.substring(0, urlEnd);
|
||||
}
|
||||
|
||||
peelBackslashes();
|
||||
if (isBuzzUrl) {
|
||||
final outsidePunctuation = _trailingPunctuationPattern.firstMatch(url);
|
||||
if (outsidePunctuation != null) {
|
||||
url = url.substring(0, outsidePunctuation.start);
|
||||
trailing = outsidePunctuation[0]!;
|
||||
trailing = '${outsidePunctuation[0]}$trailing';
|
||||
}
|
||||
}
|
||||
|
||||
var strippedDelimiter = true;
|
||||
while (strippedDelimiter) {
|
||||
strippedDelimiter = false;
|
||||
peelBackslashes();
|
||||
for (final delimiter in _markdownDelimiters) {
|
||||
if (url.endsWith(delimiter) &&
|
||||
_hasUnclosedMarkdownDelimiter(
|
||||
@@ -306,13 +406,17 @@ String _normalizeBareLink(String segment, Match match) {
|
||||
if (punctuation != null) {
|
||||
url = url.substring(0, punctuation.start);
|
||||
trailing = '${punctuation[0]}$trailing';
|
||||
peelBackslashes();
|
||||
}
|
||||
}
|
||||
|
||||
// Preserve a URL already used as its own Markdown label. This covers both
|
||||
// converted autolinks and authored `[url](url)` links.
|
||||
if (start >= 1 && segment[start - 1] == '[') return matched;
|
||||
return '[$url]($url)$trailing';
|
||||
// A backslash before the URL is literal, since a letter follows it. Double
|
||||
// it so it can't escape the synthesized `[`.
|
||||
final literalBackslash = _isEscaped(segment, start) ? r'\' : '';
|
||||
return '$literalBackslash[$url]($url)$trailing';
|
||||
}
|
||||
|
||||
bool _hasUnclosedMarkdownDelimiter(String prefix, String delimiter) {
|
||||
|
||||
@@ -0,0 +1,54 @@
|
||||
import 'link_normalizer.dart';
|
||||
|
||||
/// Holds each backslash-escaped character as a stand-in, so no link,
|
||||
/// emphasis, mention, emoji, channel or math syntax matches it: `\*x\*` stays
|
||||
/// `*x*` and `\@alice` stays text.
|
||||
///
|
||||
/// A stand-in is an invisible [_marker] followed by the character's fullwidth
|
||||
/// form, so text the renderer shows without restoring it still reads right.
|
||||
/// An authored [_marker] becomes two markers, so authored text comes back from
|
||||
/// [unshieldMarkdownEscapes] unchanged.
|
||||
String shieldMarkdownEscapes(String text) => _needsShield(text)
|
||||
? text.replaceAllMapped(
|
||||
_escape,
|
||||
(m) => m[1] == null
|
||||
? '$_marker$_marker'
|
||||
: '$_marker${String.fromCharCode(_fullwidthOffset + m[1]!.codeUnitAt(0))}',
|
||||
)
|
||||
: text;
|
||||
|
||||
/// [shieldMarkdownEscapes] applied outside inline and fenced code, where a
|
||||
/// backslash is literal.
|
||||
String shieldMarkdownProseEscapes(String content) => _needsShield(content)
|
||||
? mapMarkdownProse(content, shieldMarkdownEscapes)
|
||||
: content;
|
||||
|
||||
/// The characters [shieldMarkdownEscapes] held, as displayed.
|
||||
String unshieldMarkdownEscapes(String text) =>
|
||||
text.replaceAllMapped(shieldedMarkdownEscape, (m) => _held(m[0]!));
|
||||
|
||||
/// The escapes [shieldMarkdownEscapes] held, back in source form, for helpers
|
||||
/// that read Markdown.
|
||||
String reescapeMarkdownEscapes(String text) => text.replaceAllMapped(
|
||||
shieldedMarkdownEscape,
|
||||
(m) => m[0] == '$_marker$_marker' ? _marker : '\\${_held(m[0]!)}',
|
||||
);
|
||||
|
||||
/// Matches one stand-in created by [shieldMarkdownEscapes].
|
||||
final shieldedMarkdownEscape = RegExp('\u2060[\u2060\uFF01-\uFF5E]');
|
||||
|
||||
bool _needsShield(String text) => text.contains(r'\') || text.contains(_marker);
|
||||
|
||||
String _held(String standIn) {
|
||||
final held = standIn.substring(1);
|
||||
return held == _marker
|
||||
? _marker
|
||||
: String.fromCharCode(held.codeUnitAt(0) - _fullwidthOffset);
|
||||
}
|
||||
|
||||
// WORD JOINER: zero-width, not whitespace, and not Markdown syntax.
|
||||
const _marker = '\u2060';
|
||||
// ASCII 0x21-0x7E to FULLWIDTH 0xFF01-0xFF5E.
|
||||
const _fullwidthOffset = 0xFEE0;
|
||||
// CommonMark: a backslash escapes any ASCII punctuation character.
|
||||
final _escape = RegExp(r'\\([!-/:-@\[-`{-~])|\u2060');
|
||||
@@ -8,6 +8,7 @@ import '../message_media.dart';
|
||||
import 'buzz_link_label.dart';
|
||||
import 'channel_token_pattern.dart';
|
||||
import 'link_normalizer.dart';
|
||||
import 'markdown_escapes.dart';
|
||||
|
||||
/// One piece of a message preview: plain text or an inline token that renders
|
||||
/// as a chip or image.
|
||||
@@ -252,34 +253,7 @@ String _unwrapEmphasis(String shielded) {
|
||||
return result;
|
||||
}
|
||||
|
||||
/// Holds each backslash-escaped character as a private-use stand-in, so no
|
||||
/// link, emphasis, mention, emoji or channel syntax matches it: `\*x\*` stays
|
||||
/// `*x*` and `\@alice` stays text.
|
||||
String _shield(String text) => text.contains(_escapePrefix)
|
||||
? text.replaceAllMapped(
|
||||
_escape,
|
||||
(m) => String.fromCharCode(_escapeBase + m[1]!.codeUnitAt(0)),
|
||||
)
|
||||
: text;
|
||||
|
||||
/// The characters [_shield] held, as displayed.
|
||||
String _unshield(String text) => text.replaceAllMapped(
|
||||
_escaped,
|
||||
(m) => String.fromCharCode(m[0]!.codeUnitAt(0) - _escapeBase),
|
||||
);
|
||||
|
||||
/// The escapes [_shield] held, back in source form, for helpers that read
|
||||
/// Markdown.
|
||||
String _reescape(String text) => text.replaceAllMapped(
|
||||
_escaped,
|
||||
(m) => '\\${String.fromCharCode(m[0]!.codeUnitAt(0) - _escapeBase)}',
|
||||
);
|
||||
|
||||
const _escapePrefix = r'\';
|
||||
const _escapeBase = 0xE000;
|
||||
final _hasDelimiter = RegExp(r'[*_~<]');
|
||||
final _escape = RegExp(r'\\([!-/:-@\[-`{-~])');
|
||||
final _escaped = RegExp('[\uE021-\uE07E]');
|
||||
|
||||
// Look ahead so adjacent tokens sharing a colon are both considered.
|
||||
final _shortcode = RegExp(r'(?=:([a-z0-9_-]+):)', caseSensitive: false);
|
||||
@@ -377,14 +351,14 @@ class _PreviewBuilder {
|
||||
}
|
||||
|
||||
void _inline(String text) {
|
||||
final source = _shield(text);
|
||||
final source = shieldMarkdownEscapes(text);
|
||||
var start = 0;
|
||||
for (final match in _link.allMatches(source)) {
|
||||
_tokens(_unwrapEmphasis(source.substring(start, match.start)));
|
||||
start = match.end;
|
||||
final isImage = match[1]!.isNotEmpty;
|
||||
final label = _reescape(match[2]!);
|
||||
final url = _reescape(match[3]!);
|
||||
final label = reescapeMarkdownEscapes(match[2]!);
|
||||
final url = reescapeMarkdownEscapes(match[3]!);
|
||||
final imeta = imetaByUrl[normalizeMarkdownDestination(url)];
|
||||
final kind =
|
||||
classifyMediaUrl(url, imeta: imeta) ??
|
||||
@@ -408,7 +382,7 @@ class _PreviewBuilder {
|
||||
this.text(short);
|
||||
continue;
|
||||
}
|
||||
_tokens(_unwrapEmphasis(_shield(shown)));
|
||||
_tokens(_unwrapEmphasis(shieldMarkdownEscapes(shown)));
|
||||
}
|
||||
_tokens(_unwrapEmphasis(source.substring(start)));
|
||||
}
|
||||
@@ -420,7 +394,7 @@ class _PreviewBuilder {
|
||||
return null;
|
||||
}
|
||||
|
||||
/// [_shield]ed plain text with mention, custom emoji and channel tokens.
|
||||
/// [shieldMarkdownEscapes]ed plain text with mention, custom emoji and channel tokens.
|
||||
void _tokens(String source) {
|
||||
if (source.isEmpty) return;
|
||||
final found = <({int start, int end, PreviewPiece piece})>[];
|
||||
@@ -428,7 +402,7 @@ class _PreviewBuilder {
|
||||
for (final range in mentionOccurrences(source, mentionBindings.keys)) {
|
||||
final piece = _mention(
|
||||
range.label,
|
||||
_unshield(source.substring(range.start + 1, range.end)),
|
||||
unshieldMarkdownEscapes(source.substring(range.start + 1, range.end)),
|
||||
);
|
||||
if (piece != null) {
|
||||
found.add((start: range.start, end: range.end, piece: piece));
|
||||
@@ -460,11 +434,11 @@ class _PreviewBuilder {
|
||||
var cursor = 0;
|
||||
for (final token in found) {
|
||||
if (token.start < cursor) continue;
|
||||
text(_unshield(source.substring(cursor, token.start)));
|
||||
text(unshieldMarkdownEscapes(source.substring(cursor, token.start)));
|
||||
add(token.piece);
|
||||
cursor = token.end;
|
||||
}
|
||||
text(_unshield(source.substring(cursor)));
|
||||
text(unshieldMarkdownEscapes(source.substring(cursor)));
|
||||
}
|
||||
|
||||
/// Mirrors the thread view's mention chip: an ambiguous label stays text.
|
||||
|
||||
@@ -2,6 +2,7 @@ import 'package:flutter/foundation.dart';
|
||||
|
||||
import 'message_media.dart';
|
||||
import 'message_content/link_normalizer.dart';
|
||||
import 'message_content/markdown_escapes.dart';
|
||||
|
||||
/// Image metadata shared by carousel rendering and loading projection.
|
||||
@immutable
|
||||
@@ -48,7 +49,9 @@ TrailingImageGallery? extractTrailingImageGallery(
|
||||
if (mediaKind != MessageMediaKind.image) {
|
||||
break;
|
||||
}
|
||||
final markdownLabel = decodeMarkdownLabelSyntax(match.group(1)!).trim();
|
||||
final markdownLabel = decodeMarkdownLabelSyntax(
|
||||
unshieldMarkdownEscapes(shieldMarkdownEscapes(match.group(1)!)),
|
||||
).trim();
|
||||
items.add(
|
||||
MessageGalleryItem(
|
||||
url: url,
|
||||
|
||||
@@ -181,6 +181,46 @@ void main() {
|
||||
input: '```\n$url ``` still code\n```\n$url',
|
||||
expected: '```\n$url ``` still code\n```\n[$url]($url)',
|
||||
),
|
||||
(
|
||||
name: 'tilde fence indented three spaces',
|
||||
input: ' ~~~\n$url\n ~~~\n$url',
|
||||
expected: ' ~~~\n$url\n ~~~\n[$url]($url)',
|
||||
),
|
||||
(
|
||||
name: 'fence opens after deeper indentation',
|
||||
input: ' ~~~\n$url',
|
||||
expected: ' ~~~\n$url',
|
||||
),
|
||||
(
|
||||
name: 'unclosed fence inside a quote',
|
||||
input: '> ```sh\n> $url',
|
||||
expected: '> ```sh\n> $url',
|
||||
),
|
||||
(
|
||||
name: 'unclosed quoted fence ends with its quote',
|
||||
input: '> ```sh\n> $url\n\n$url',
|
||||
expected: '> ```sh\n> $url\n\n[$url]($url)',
|
||||
),
|
||||
(
|
||||
name: 'quoted fence ends at a lazy line',
|
||||
input: '> ```sh\n> $url\n$url',
|
||||
expected: '> ```sh\n> $url\n[$url]($url)',
|
||||
),
|
||||
(
|
||||
name: 'top-level fence does not close on a quoted fence',
|
||||
input: '```md\n> ```\n$url\n```\n$url',
|
||||
expected: '```md\n> ```\n$url\n```\n[$url]($url)',
|
||||
),
|
||||
(
|
||||
name: 'quoted fence closes inside the quote',
|
||||
input: '> ~~~\n> $url\n> ~~~\n$url',
|
||||
expected: '> ~~~\n> $url\n> ~~~\n[$url]($url)',
|
||||
),
|
||||
(
|
||||
name: 'fence closer must end its line',
|
||||
input: '~~~\n$url\n~~~ x\n~~~\n$url',
|
||||
expected: '~~~\n$url\n~~~ x\n~~~\n[$url]($url)',
|
||||
),
|
||||
(
|
||||
name: 'unclosed backticks remain prose',
|
||||
input: '$url then `$url',
|
||||
@@ -193,6 +233,46 @@ void main() {
|
||||
expect(normalizeBareLinks(testCase.input), testCase.expected);
|
||||
});
|
||||
}
|
||||
|
||||
test('bare links leave a trailing backslash outside the destination', () {
|
||||
expect(
|
||||
normalizeBareLinks(r'see https://example.com/a\'),
|
||||
r'see [https://example.com/a](https://example.com/a)\',
|
||||
);
|
||||
expect(
|
||||
normalizeBareLinks(r'*https://example.com/a\**'),
|
||||
r'*[https://example.com/a](https://example.com/a)\**',
|
||||
);
|
||||
});
|
||||
|
||||
test('a literal backslash before a bare link stays literal', () {
|
||||
expect(
|
||||
normalizeBareLinks(r'see \https://example.com/a'),
|
||||
r'see \\[https://example.com/a](https://example.com/a)',
|
||||
);
|
||||
expect(
|
||||
normalizeBareLinks(r'see \\https://example.com/a'),
|
||||
r'see \\[https://example.com/a](https://example.com/a)',
|
||||
);
|
||||
});
|
||||
|
||||
test('near-limit fence-like runs on one line complete linearly', () {
|
||||
// Each run checks only its own indentation and the rest of its line up
|
||||
// to the next character, so a long line of runs is not rescanned.
|
||||
for (final input in [
|
||||
'x~~~' * (256 * 1024 ~/ 4),
|
||||
'~~~\n${' ~~~' * (256 * 1024 ~/ 4)}',
|
||||
'```\n${' ```' * (256 * 1024 ~/ 4)}',
|
||||
'>' * (256 * 1024 - 3) + '~~~',
|
||||
'> ~~~' * (256 * 1024 ~/ 5),
|
||||
]) {
|
||||
final watch = Stopwatch()..start();
|
||||
final result = normalizeBareLinks(input);
|
||||
watch.stop();
|
||||
expect(result == input, isTrue);
|
||||
expect(watch.elapsed, lessThan(const Duration(seconds: 2)));
|
||||
}
|
||||
});
|
||||
});
|
||||
|
||||
test(
|
||||
|
||||
@@ -492,6 +492,88 @@ void main() {
|
||||
});
|
||||
|
||||
group('MessageContent', () {
|
||||
testWidgets('renders backslash escapes as the escaped character', (
|
||||
tester,
|
||||
) async {
|
||||
final semantics = tester.ensureSemantics();
|
||||
String visible() => [
|
||||
for (final element in find.byType(RichText).evaluate())
|
||||
(element.widget as RichText).text.toPlainText(),
|
||||
].join('|');
|
||||
|
||||
for (final (content, shown) in [
|
||||
(r'plain \# \* \_ \\ end', r'plain # * _ \ end'),
|
||||
(r'**bold \#x** \[not math\](y)', '[not math](y)'),
|
||||
(r'[\#buzz-mobile](https://example.com/x)', '#buzz-mobile'),
|
||||
(
|
||||
r'[\#buzz-mobile](buzz://channel/9f18f3c6-b5e5-453d-b36d-65487913be0b)',
|
||||
'#buzz-mobile',
|
||||
),
|
||||
('```\nx \\# y\n```', r'x \# y'),
|
||||
(r'code `a\#b`', r'a\#b'),
|
||||
(r'\`literal\` then `a\#b`', '`literal` then '),
|
||||
// Authored stand-in characters are not mistaken for escapes.
|
||||
('\uFF0A \u2060\uFF0A \\#', '\uFF0A \u2060\uFF0A #'),
|
||||
('~~~\nx \\# y\n~~~', r'x \# y'),
|
||||
// A fence that never closes is still code inside a quote or list.
|
||||
('> ```sh\n> echo \\#x', r'echo \#x'),
|
||||
('- item\n\n ```\n echo \\#x', r'echo \#x'),
|
||||
// A fence closes only at the quote depth it opened at.
|
||||
('```md\n> ```\necho \\#g\n```', r'echo \#g'),
|
||||
('> ```sh\n> x\n\n```\necho \\#g\n```', r'echo \#g'),
|
||||
// A quoted fence ends with its quote, so later prose is parsed.
|
||||
('> ```sh\n> echo x\n\nplain \\#text', 'plain #text'),
|
||||
// Known limitation: gpt_markdown's raw-text fallback for this
|
||||
// unclaimed strike skips inline components, so the stand-in shows.
|
||||
// Its fullwidth form still reads as #.
|
||||
('~~a\nb \\#c~~', '\uFF03c'),
|
||||
// A bare link's trailing backslash stays outside the link.
|
||||
(r'see https://example.com/a\', 'see '),
|
||||
(r'in buzz://channel/9f18f3c6-b5e5-453d-b36d-65487913be0b.\', r'.\'),
|
||||
(r'*https://example.com/a\**', '*'),
|
||||
(r'see \<https://example.com/b>', 'see <'),
|
||||
(r'see \https://example.com/c', r'see \'),
|
||||
(r'see <https://example.com/a\>', r'https://example.com/a\'),
|
||||
(
|
||||
'\n'
|
||||
'',
|
||||
null,
|
||||
),
|
||||
]) {
|
||||
for (final bubble in [false, true]) {
|
||||
await tester.pumpWidget(
|
||||
_testable(MessageContent(content: content, bubble: bubble)),
|
||||
);
|
||||
final reason = '$content (bubble: $bubble) showed ${visible()}';
|
||||
if (shown != null) {
|
||||
expect(
|
||||
find.textContaining(shown, findRichText: true),
|
||||
findsWidgets,
|
||||
reason: reason,
|
||||
);
|
||||
}
|
||||
// No stand-in or leaked link syntax reaches text or semantics.
|
||||
if (content.contains('\u2060') || shown == '\uFF03c') continue;
|
||||
expect(
|
||||
find.textContaining(
|
||||
RegExp('\u2060|\\]\\(http'),
|
||||
findRichText: true,
|
||||
),
|
||||
findsNothing,
|
||||
reason: reason,
|
||||
);
|
||||
expect(
|
||||
find.bySemanticsLabel(RegExp('\u2060')),
|
||||
findsNothing,
|
||||
reason: reason,
|
||||
);
|
||||
}
|
||||
}
|
||||
// Gallery labels drop their escapes too.
|
||||
expect(find.bySemanticsLabel(RegExp(r'shot #1')), findsWidgets);
|
||||
semantics.dispose();
|
||||
});
|
||||
|
||||
testWidgets('forwards text alignment to markdown rendering', (
|
||||
tester,
|
||||
) async {
|
||||
|
||||
Reference in New Issue
Block a user