mirror of
https://github.com/block/buzz.git
synced 2026-11-06 17:31:19 +00:00
ab8aecd6871f1001392d36f59bf19e258a448472
3260 Commits
| Author | SHA1 | Message | Date | |
|---|---|---|---|---|
 Brad Seiler |
ab8aecd687 |
test(relay): bound live workflow handshake and control reads
Co-authored-by: Codex <codex@openai.com> Signed-off-by: Brad Seiler <seiler@squareup.com> |
||
|
Brad Seiler
|
0ca5a04447 |
test(relay): measure live revocation without Redis delivery
Exercise signed root and audio admission against an isolated running relay, durable direct-member and owner bans, a responsive bystander, and bounded database-failure closure. Co-authored-by: Codex <codex@openai.com> Signed-off-by: Brad Seiler <seiler@squareup.com> |
||
|
Brad Seiler
|
a5e5661010 |
test(relay): import root fixture shared ownership type
Co-authored-by: Codex <codex@openai.com> Signed-off-by: Brad Seiler <seiler@squareup.com> |
||
|
Brad Seiler
|
8382528486 |
test(relay): retain root lifecycle registration during revalidation
Co-authored-by: Codex <codex@openai.com> Signed-off-by: Brad Seiler <seiler@squareup.com> |
||
|
Brad Seiler
|
1b1f5a23f4 |
test(relay): bind durable revocation to socket admission
Authenticate through root and audio handlers before a durable-only ban. Removing either production enrollment call must fail its regression. Co-authored-by: Codex <noreply@openai.com> Signed-off-by: Brad Seiler <seiler@squareup.com> |
||
|
seiler
|
4aaf747ed2 |
refactor(relay): address revalidation review
Restore CommunityDisconnectReason near the top of state.rs and document scan deadline and reconnect-load limitations. Authorization behavior is unchanged. Signed-off-by: seiler <seiler@squareup.com> Co-authored-by: Codex <noreply@openai.com> (cherry picked from commit a4d1ab288d761d44eba25cc62d25b7d2858788dc) Signed-off-by: Brad Seiler <seiler@squareup.com> |
||
|
seiler
|
1b81b01b01 |
Add durable live member authorization checks
Signed-off-by: seiler <seiler@squareup.com> Co-authored-by: Codex <noreply@openai.com> (cherry picked from commit 92f13229ed3038d63f2a2d9c889bfd4c212e38e2) Signed-off-by: Brad Seiler <seiler@squareup.com> |
||
|
Brad Seiler
|
988a9b4de4 |
docs(db): align invitation repair with schema 0075
Co-authored-by: Sarnow <1894dcbafaa4df1ac607a9bf879ac0b7d77fbccb0e0f4619ecc252c8adbad8a2@seiler-test.communities.public.builderlabstaging.xyz> Signed-off-by: Brad Seiler <seiler@squareup.com> |
||
|
Brad Seiler
|
c3f4c01946 |
Add invitation history repair as a separate maintenance change
Revoke historical legacy candidates and clear examined admission markers under the deletion/admission locks. Require separate approval before core deployment and a controlled rollout that prevents new timeout/mute history. Co-authored-by: Codex <noreply@openai.com> Signed-off-by: Brad Seiler <seiler@squareup.com> Signed-off-by: seiler <seiler@squareup.com> Signed-off-by: Brad Seiler <seiler@squareup.com> |
||
|
Tom Brow
|
ec21753e1b |
Make mobile New DM and Add members pick recipients like mention autocomplete (#9065)
The mobile New DM picker listed the first 50 relay profiles alphabetically, mostly identities the viewer doesn't know. It ran its own debounced directory search with no cache, and its rows disappeared on every keystroke until the search returned. Mention autocomplete in the composer already solves the same problem well, so New DM and Add members now use its implementation. Add members was reusing the same New DM directory search. ### What changes - **Same candidates and order as mention autocomplete.** The chooser's candidate building, ranking, row stability, 200 ms debounced search and search cache now back both surfaces. New DM is treated like a stream with no members yet: the viewer's own agents and agents shared with them appear up front, people are found by name, and agents that couldn't answer the viewer are left out. Typing a name shows the same people in the same order as `@name` in a stream. - **Results stay on screen while a search runs.** A query searched before shows its people immediately, and a longer query starts from the shorter query's results. A failed search keeps its rows and adds a retry row below them. - **Presentation matches the mention rows.** Rows show the name, and agents show "agent · managed by …". Npub lines are gone. - **Sheet chrome.** The title is "New DM", like the menu item that opens it. Both pickers keep their grouped cards but drop the "People and agents" and "Selected" section titles and the empty header bands above them (selected recipients stay in their own card at the top with checkmarks on iOS, as chips on Android). The native iOS picker now focuses search once it appears, which iOS used to ignore. In New DM a pick clears the query, as an inserted mention ends its query. - **Add members keeps what is specific to it.** Existing members and members just added are never offered, names are still compared with the channel roster so a same-name candidate is told apart, the query stays after a pick so several matches can be added in a row, and agents that don't answer the viewer can still be added, since a channel can hold them. While the WebSocket reconnects, the relay agent directory and its owners keep their last read in the community instead of going empty, so shared agents already found stay eligible in both New DM and the composer chooser. The debug-only offline preview directory and the old directory listing and search providers are removed, since no picker reads them any more. ### Validation Added tests: the New DM widget journey now drives the real mention search through a fake relay session. It covers the empty-query state, the debounce, rows kept while a longer query searches, cached results shown again at once, selection, chips and submit. The layout journey covers the 50-row cap, and the native-bridge journey covers title, rows without key detail lines, the selection limit and failure handling. The full `mobile/test/features/channels` suite passes. Automated app run (iPhone 17 Pro simulator, iOS 27, debug build, Remote Agents Pilot community): opened New DM from the menu, confirmed the keyboard comes up with only the viewer's own agents listed, searched for people and an agent, selected both and confirmed the query cleared after each pick. Also exercised the composer mention chooser (same results and order for the same query) and the shared Add members sheet (plain style, autofocus, search, query kept after a pick). Captures show real community members, so they're shared internally rather than here. The DM was not actually created, to avoid a stray conversation; submit is covered by the widget tests. 🤖 Generated with [Claude Code](https://claude.com/claude-code) --------- Signed-off-by: Tom Brow <tomb@squareup.com> Co-authored-by: Tom Brow <tomb@squareup.com> Co-authored-by: Claude Opus 5.5 <noreply@anthropic.com> |
||
|
Tom Brow
|
f09956179d |
fix(mobile): keep the composer focused through iOS inactive spells (#9055)
On iPhone, opening Control Center or the app switcher while the composer is focused can leave the keyboard up over a collapsed composer. The orphaned keyboard then stays put while you navigate, for example back from a thread to its channel, and it clips the composer pill. ### Cause iOS reports a zero keyboard inset while the app is inactive and restores the keyboard natively when the app returns. The composer treated any inset drop as a user dismissal: it collapsed, unfocused and removed its text field. When the keyboard came back, it was attached to no Flutter field, so nothing could dismiss it. Flutter's own report of the native side is [flutter/flutter#189051](https://github.com/flutter/flutter/issues/189051). ### Change The composer's keyboard observer ignores metrics while the app is not resumed. iOS reports `resumed` with the inset still at zero and brings the keyboard back a few hundred milliseconds later, so when a keyboard that was up hasn't returned at resume, the composer waits a one-second grace before treating it as dismissed. Any nonzero inset in that window cancels the wait. A restored keyboard leaves the composer expanded and focused; a keyboard that really stayed down still collapses the composer once the grace passes. ### Validation - Extended the existing "returns to the compact capsule when the keyboard drops" widget journey with both inactive cases in the order iOS reports them: resumed at zero with the keyboard returning about 400 ms later (composer stays focused), and resumed with the keyboard staying down (composer collapses after the grace). It fails without the fix and against the first revision of this PR. - Full mobile check and test suite pass. - iOS 27 simulator (iPhone 17 Pro, debug build of the first revision): focused the composer, typed, switched to Settings and back, opened and closed Control Center, sent a message, and left the channel. The composer stayed focused through each interruption, sending kept focus, and leaving dismissed the keyboard. Limitation: the simulator keeps the keyboard inset through these interruptions, so it reproduces neither the original bug nor the resume grace; the on-device inset drop is from the reporter's screen recording and the Flutter issue. Human app testing is waived under the mobile testing exception; the simulator pass above is the automated full-app run. buzz-review-completed 🤖 Generated with [Claude Code](https://claude.com/claude-code) --------- Signed-off-by: Tom Brow <tomb@squareup.com> Co-authored-by: Tom Brow <tomb@squareup.com> Co-authored-by: Claude Opus 5.5 <noreply@anthropic.com> |
||
|
Tom Brow
|
7157a55f5f |
fix(mobile): keep the iOS 27 header blur in long chats (#8971)
On iOS 27, the frosted header in a long conversation could flicker between blurred and sharp, most visibly right after returning to the app. ### Cause The native header mirrors Flutter's scroll depth into a hidden 10,000 pt `UIScrollView` so UIKit can draw its scroll-edge effect. For a reversed chat that depth is the loaded history above the viewport (`extentAfter`), which can exceed the mirror's range in a long channel. Past the end of that content, UIKit finds nothing under the bar and drops the blur and top fade. While the timeline reconnects and catches up, the lazy list's depth estimate moves back and forth across that point, so the header flips between blurred and sharp. ### Fix Cap the depth sent to the mirror at 1,000 pt. Only the first few hundred points change the header (scroll-under material alpha and large-title collapse), so pages behave the same below the cap. ### Validation - Reproduced in an iOS 27 simulator (iPhone 17 Pro) with a debug-only patch that cycled the reported depth through 0, 9,500, 10,500 and 20,000 pt. Without the fix, the header dropped its blur and top fade at the deep values, matching the device recording. With the fix, the blur stayed steady across the same cycle. - Backgrounded and resumed a channel in the simulator with the fixed build. The header stayed blurred through the reconnect and catch-up. - Not yet checked on a physical iOS 27 device; the report came from a device recording. Captures stay in Buzz because they show internal conversations. 🤖 Generated with [Claude Code](https://claude.com/claude-code) Signed-off-by: Tom Brow <tomb@squareup.com> Co-authored-by: Tom Brow <tomb@squareup.com> |
||
|
Tom Brow
|
041956ea44 |
fix(ios): saturate the push dedupe cutoff so extreme timestamps can't crash (#9010)
## Context Follow-up to [#8973](https://github.com/block/buzz/pull/8973), from Codex's [review](https://github.com/block/buzz/pull/8973#discussion_r4458876285) of its final head. The push dedupe cutoff subtracts the 15 minute reorder window from the newest shown time. A signed event can carry any `created_at`. One within 900 seconds of `Int.min` made that subtraction overflow and trap, crashing the Notification Service Extension. The claim was never saved, so every later push crashed the same way while the relay kept returning that event. The relay's own drift check normally rejects such timestamps, but the extension shouldn't depend on that. ## Change The cutoff now uses saturating subtraction (`BuzzNotificationCache.presentationCutoff(after:)`), in both the claim check and retention pruning. ## Validation - New test `testExtremeTimestampsDoNotCrashTheClaim` claims messages dated `Int.min`, `Int.min + 1`, now, and `Int.max`. It checks that each behaves like any other message and nothing crashes. With the plain subtraction restored, it crashes with signal 5 (overflow trap). - Full BuzzPushKit suite: 108 XCTest and 66 Swift Testing tests passed. - Automated app test: not run. This is a two-line arithmetic change inside the extension's cache. The live APNs run on [#8973](https://github.com/block/buzz/pull/8973) covers the flow. 🤖 Generated with [Claude Code](https://claude.com/claude-code) Signed-off-by: Tom Brow <tomb@squareup.com> Co-authored-by: Tom Brow <tomb@squareup.com> Co-authored-by: studio <dc2fc481343672df31a689840c09299972e704dac592e0da6f18486646a7ee3e@buzz.block.builderlab.xyz> Co-authored-by: Claude Opus 5.5 <noreply@anthropic.com> |
||
|
ravarora2
|
7b3c2f95f2 |
fix(mobile): bound notices to loaded message history (#9062)
## Summary Mobile reads system notices older than its loaded message window, even though those notices cannot yet appear. Bound notice reads by the oldest loaded message's timestamp to avoid fetching history outside the loaded time range. A short or empty bounded response finishes that time range, rather than all notice history. Preserve the full boundary second, resume when older message pages load, and keep notices before the first message available at the start of history. Enforce the 2,000-notice cap before fetching reactions. Reuse cached reactions and deletions when older pages reveal their notices. For channels with fewer than 500 notices, scrolling back can now require one bounded notice read per older message page. Previously, one unbounded read covered the channel. ### Related issue Related: #8962, which changed how mobile loads and displays membership notices. No duplicate notice-bound PR found in the open mobile-notice title search. ### Testing Mutation checks: removing the production `since` argument or restoring the old unconditional history-end flag each made all four notice-range cases fail. Command: `cd mobile && flutter test --no-pub --dart-define=BUZZ_PUSH_GATEWAY_URL=https://push.example test/features/channels/channel_notices_journey_test.dart --name 'notice ranges'`. Replacing the captured message cursor with a fabricated maximum ID also fails the empty-range progress regression. Command: `cd mobile && flutter test --no-pub --dart-define=BUZZ_PUSH_GATEWAY_URL=https://push.example test/features/channels/channel_messages_provider_test.dart --name 'an empty notice range'`. A read-only prepared-query check on local Postgres 17.10 used a representative kind-40099 query. It held 22 event-related relation locks with `force_custom_plan` and 99 with `force_generic_plan`. The generic plan pruned seven of eight partitions during execution but retained the broader locks. These results do not establish lock reduction or throughput improvement under the relay's actual cached-plan workload; a relay load test remains pending. Native app scrolling against a live relay and human confirmation remain pending. For the device check, run `just mobile-dev` on a host with an iOS Simulator runtime. Connect to a local test relay and open a channel with more than 150 messages and interleaved topic notices. Scroll back through at least three message pages, then to the start. Check that visible notices remain in order and appear once. Disconnect during a page read, reconnect, and continue scrolling to check recovery. Generated with Codex --------- Signed-off-by: BuzzPRReviewAssistant1 <a581a7e8115222acdc32ffb14bfce55d48c24478d98e155f8eba126b69b83c7b@buzz.block.builderlab.xyz> Co-authored-by: BuzzPRReviewAssistant1 <a581a7e8115222acdc32ffb14bfce55d48c24478d98e155f8eba126b69b83c7b@buzz.block.builderlab.xyz> |
||
|
klopez4212
|
99873459e9 |
Keep sign-in toasts usable at large text sizes (#9057)
At large text sizes, organization sign-in prompts could clip their message and push recovery actions off-screen. Stack actions below the message above 1.3× text, use fixed card corners, and skip the Dynamic Island morph for that layout. Follow-up to #9050, addressing [Wes’s large-text blocker](https://github.com/block/buzz/pull/9050#discussion_r4469530660). Normal-size styling and recovery callbacks are unchanged. Validation: extended existing sign-in/cancel/error journeys at 1×, 2× and 3× using Inter on a 320×568 viewport; assert text lies inside the painted clip and the card stays on-screen. Removing the fix fails all six enlarged-text cases. Mobile checks and full tests run through the push hook. Human device testing of this follow-up is pending. Local Flutter previews at 3× text (320×568): | Before | After | | --- | --- | |  |  | Signed-off-by: kenny lopez <klopez4212@gmail.com> Co-authored-by: Terp <5856f6900e8e0a4e0ea1f4f8d2ee33e4753d2119bc122f94ecafc660b46c0511@buzz.block.builderlab.xyz> |
||
|
klopez4212
|
ce94656b0d |
fix(mobile): use join template for community creation (#9072)
Community creation now uses the same mobile template, borderless iOS input, and keyboard-coordinated transition as joining, replacing the old welcome screen and boxed field. Name validation, separate form drafts, reduced motion, and accessible error announcements are preserved. Validation: analysis and 4,407 Flutter tests pass (45 skipped, four workers); independent review passed. Kenny approved the simulator preview. Agent verification of the full native transition remains pending; the after snapshot below is a Flutter widget render. | Before | After | | --- | --- | |  |  | --------- Signed-off-by: kenny lopez <klopez4212@gmail.com> Co-authored-by: Terp <5856f6900e8e0a4e0ea1f4f8d2ee33e4753d2119bc122f94ecafc660b46c0511@buzz.block.builderlab.xyz> |
||
|
Tom Brow
|
90de03aa63 |
feat(mobile): back up nsec to org builderlab account (#9029)
The Block tenant links a member's existing key to their account the first time it issues them a relay assertion ([#8700](https://github.com/block/buzz/pull/8700)). Mobile never backed that key up. Desktop FI builds back up to the tenant, but on mobile a Block key that lives on just one phone can't be recovered once Block turns backups on. Mobile now backs up the organization relay's key to the organization account: - After every organization assertion, it reads `/v1/buzz/nsec-backups/status`. If the key is already listed, there's nothing to do. - If the bound key isn't listed, it enrolls, seals with HPKE and uploads, using the existing `HostedBackupService`. That service now uses its account client's own origin, so organization and hosted backups never share a pending envelope. Hosted storage keys and receipts don't change. - If the upload's outcome is unknown, the saved envelope is replayed exactly at the next assertion. - A tenant without backups answers 404 (Block production today). That, and other definitive refusals, stop attempts for that account and key until the next launch. Any other failure is retried at a later assertion, after a delay that doubles from 1 minute to at most 1 hour. Assertions renew while the app runs, so retries continue until the tenant lists the key. - Concurrent assertions share one attempt. - iOS 16 can't seal, so it sends nothing. Backup failures never affect the relay connection. There's no UI. As in mobile's hosted onboarding, the backup happens automatically. Desktop asks for an explicit backup choice first, so whether mobile should too is a product call. ### Validation Added tests (`organization_key_backup_test.dart`), which run through real `HostedRelayAuth` assertion issuance with only HTTP faked: - An uncertain upload is replayed with the same envelope at the next assertion, then nothing more is sent in that launch. - A key that's already listed sends no upload and drops a leftover envelope. - A tenant without backups is asked once per launch. - A device that can't seal sends nothing. - A failed status read is retried after the delay, not at the immediate re-assertion. A key the tenant bound to someone else is never uploaded, and its checks keep going at growing intervals. - Two concurrent assertions make one attempt. - A failing seal-capability check sends nothing. Removing the assertion hook fails 4 of the 6 tests. Removing the shared attempt or the retry delay fails its test. Full `mobile-check` and `mobile-test` pass. Device (iPhone 12 mini, release build) against bb-block staging, where backups are configured and the relay enforces NIP-FI, with an existing Block SSO session: - On launch the app asserts, reads backup status and finds this key listed, so it uploads nothing. The relay connection and channel list are unaffected. - A test-only build that ignored the listed shortcut enrolled, sealed with the staging tenant's real KMS-backed key and uploaded, with a stored response in about 360 ms. That re-stored my own test key. - The final build at this head was then reinstalled and relaunched with no backup failure logged. The device's staging community was added in an earlier run, because adding an enforcing organization relay by link is still blocked ([#8791](https://github.com/block/buzz/issues/8791)). An independent agent review ran; its should-fix items are addressed in the second commit. Codex's retry finding is addressed in the third, which changes only failure-path timing; the device-tested success path is unchanged. Wes's optional review notes are addressed in the last three: an exact-timing retry test, backup queues per account origin (a stalled organization backup no longer delays hosted onboarding's backup, with a test), and a subject check on each enrollment and upload request. Full `mobile-check` and `mobile-test` pass at the head. Human testing is waived under the mobile automated-testing policy; the device run above covers the at-risk flows (organization assertion, relay connection, backup status, enrollment, sealing and upload). buzz-review-completed 🤖 Generated with [Claude Code](https://claude.com/claude-code) --------- Signed-off-by: Tom Brow <tomb@squareup.com> Co-authored-by: Tom Brow <tomb@squareup.com> Co-authored-by: Claude Opus 5.5 <noreply@anthropic.com> |
||
|
Brad Seiler
|
a1f79e3aba |
feat(relay): persist NIP-FI upgrades (BUZZ-510) (#8985)
## Summary Record that a community requires NIP-FI and provide an idempotent operator API to enable it and recover the original receipt. Acceptance checks the current owner, host, lifecycle and existing issuer trust in one transaction. It never creates trust. Receipts survive community deletion so an operation UUID cannot be reused. New acceptances default to disabled through `BUZZ_NIP_FI_UPGRADES_ENABLED`. Disabled calls return HTTP 503 `upgrades_disabled`; identical retries and authenticated readback still recover existing receipts. Policy is permanent: stopping new calls or rolling back code does not clear it. Last-issuer removal is refused for required communities, and bulk backfill leaves missing bindings for explicit operator repair. Apply additive migration 0082 before code. Existing communities remain optional. This layer records acceptance and reports only `pending` or `unavailable`; deploy and verify [per-request enforcement](https://github.com/block/buzz/pull/8988) and [session activation](https://github.com/block/buzz/pull/8991) before enabling acceptance. The global enforce floor remains. See [the operator contract](https://github.com/block/buzz/blob/seiler/BUZZ-510/relay-auth-upgrade/docs/community-auth-upgrades.md) for signing, recovery and containment. ### Related issue [BUZZ-510](https://linear.app/squareup/issue/BUZZ-510/relay-persist-community-nip-fi-requirements-and-expose-idempotent). Base of native stack `8989`; retains trunk's enforcement telemetry from [#8974](https://github.com/block/buzz/pull/8974). Includes a separate commit that repairs an observer timing flake in a desktop test required by the repository gate. ### Testing Controlled local regressions detect the old disabled error code and removal of the last issuer with `allow_last=true`; intended source is restored. Full PostgreSQL validation and the updated live relay/admin exercise remain pending. Human acceptance remains open. No deployment or production activation. Generated with Codex --------- Signed-off-by: Brad Seiler <seiler@squareup.com> Co-authored-by: Honor <e0bf479eeebe47dde1e35705212a4df70616a7bc834d907ddfb18cf0405f8b1b@seiler-test.communities.public.builderlabstaging.xyz> |
||
|
Luke Tornquist
|
4813b8cd15 |
relay: time every WebSocket read and every stored EVENT outcome (#9052)
## Summary

Two gaps in relay telemetry: WebSocket reads (`REQ`, NIP-AR sync,
`COUNT`) have no latency or outcome metric, and
`buzz_event_processing_seconds` only measures stored EVENTs that
succeed.

**What this does**
- **`buzz_ws_read_seconds{type, outcome, reason}`** (new histogram).
It's recorded from `access::ReadLog::drop`. Every WebSocket read already
finishes through that one seam, whether it ends `served`, `denied`,
`error`, or `aborted` (future dropped mid-read), so this adds no new
exit paths and changes no handler. Duration runs from the moment the
handler takes the frame until `EOSE` is queued (`REQ`), the initial set
ends (sync), or the total is sent (`COUNT`). `reason` is the existing
fixed denial/error code (`query_timed_out`, `database_error`,
`not_channel_member`, …), or `none`. The histogram's `_count` doubles as
the outcome counter, so one metric gives both read latency and read
failure rate.
- It's recorded *before* the refusal budget check, because the budget
only exists to suppress log lines. When `refused_read` is over budget,
it records the sample without building the log line, so its cost under a
refusal flood stays the same.
- **`buzz_event_processing_seconds{outcome}`**. Before this change it
was recorded only when `ingest_event` returned `Ok`. A store that was
slow *and failing* (statement timeouts, pool exhaustion) produced no
samples, so latency looked better while the store was degrading. It's
now recorded on every persistent-ingest outcome: `accepted`,
`not_accepted` (for example a duplicate), `invalid`, `auth`, `error`.
Queries that sum across all outcomes still work.

**Cardinality.** Every label value is a `&'static str` from a
code-defined set: 3 types × 4 outcomes, with about 25 reasons that only
appear alongside `denied`/`error`. On purpose, there's no `kind` label:
`bounded_kind_label` still admits around 200 values, which is too many
to cross with histogram buckets.

**What got simpler:** `ReadOutcome::parts()` replaces the inline
outcome→label match in `Drop`, so the log line and the metric share one
mapping. There's no new instrumentation seam: the read metric reuses the
access log's lifecycle.

### Related issue

None found. This came out of a monitoring-gap review: without these
signals, alerts can't catch a slow or failing WebSocket read path, or a
failing EVENT store.

### Testing

-
`access::tests::every_read_is_measured_even_when_its_line_is_suppressed`
(unit). It drives the real `ReadLog` constructors and `Drop`: 20
admission refusals against a 16-line budget, a handler denial past the
budget, a `COUNT` error, a served sync and an aborted `REQ`. It asserts
the exact `(type, outcome, reason, samples)` rows. Two mutants each fail
it: removing the over-budget branch in `refused_read`, and moving the
measurement after the budget check in `Drop`.
-
`handlers::event::tests::postgres_tests::event_processing_is_timed_for_accepted_and_refused_ingest`
(Postgres lane). It sends one accepted text note, then a refused one
from a cached-ban sender, through `handle_event`, and asserts one sample
each under `accepted` and `auth` (a ban maps to the `auth` class).
Removing the `Err`-arm measurement fails it.
- Blox gate at `b314df43f2` (tree `4ca9ebc1`): `cargo fmt --check`
clean. The new Postgres test passes, and removing the `Err`-arm
measurement fails it. buzz-relay unit lane (`cargo nextest run -p
buzz-relay --lib --bins`): 1708/1708 passed.
- At `539796bd51` (the same code; only the second commit's test
assertion differs): workspace clippy (`--all-targets -D warnings`)
passed. The new unit test passed, and each of its two mutants failed it.
buzz-relay Postgres lane: 604/605 passed. The one failure was this
test's old `invalid` expectation, which `b314df43f2` corrects.
- CI at `b314df43f2`: both new tests appear in the CI logs as passing
(Rust / Unit Tests, PostgreSQL Domain / PostgreSQL Tests).

🤖 Generated with [Claude Code](https://claude.com/claude-code)

---------

Signed-off-by: Luke Tornquist <tornquist@squareup.com>
Co-authored-by: Elrond <28d6302a099e5225b02c4155ac4236e4912603df2ab08dbfc2f4fef08ce598c8@buzz.block.builderlab.xyz>
Co-authored-by: Claude Opus 5.5 <noreply@anthropic.com>
|
||
|
Luke Tornquist
|
25abfc4117 |
fix(loadgen): bound desktop reads at stop, keep timely EOSEs, model presence and probes (#9016)
## Summary Follow-up to #9005, addressing the review findings that merged unaddressed. None of them affect a relay. `buzz-ws-client` gains one method. Each one skews what the desktop client measures when the relay is slow, which is the case the load generator exists for. - **Reads stop at the stop.** A desktop HTTP read (including NIP-11) now races the run's stop and is abandoned there without being recorded, as EOSE waits already were. Before, a read that outlived the 15 s shutdown grace got its client cancelled and failed an otherwise healthy run. `Fetcher::finish` also keeps the read task's handle until the task ends, so a client cancelled during the join still aborts the task instead of detaching it. - **Root lookups are bounded.** The desktop's seeded-root lookups, for thread recovery and replies, now run under the desktop's 30 s read timeout and stop, not reqwest's 60 s. `roots()` takes an optional bound, and the basic human passes none. If the stop cuts a reply's lookup short, the reply isn't published. That applies to the basic human too: a reply whose root lookup finishes after the stop is dropped. - **An EOSE that arrives in time stays in time.** While a publish waits for its OK, `NostrWsConnection` buffers every other frame. The session loop used to judge EOSE deadlines before reading that buffer, and read one frame per pass. It now handles every frame already in hand (at most 256 per pass) before judging deadlines. Each frame is judged by when it arrived, not when it is read. `NostrWsConnection` keeps each buffered frame's arrival time, and the new `next_event_received` returns it. So an EOSE that arrived after its deadline while an OK wait held it counts as a timeout, and so does a frame that answers the probe late. Past that cap, a pass defers due deadlines, for at most one timeout from the first pass that defers them. While it is deferring, the pass only drains, so another OK wait can't expire an EOSE that's already in hand, and sustained traffic can't postpone a missing EOSE forever. - **Presence and the silence probe.** Both modes now open the app's live-only `presence` route (`{"kinds":[20001],"authors":[…],"since":…,"limit":0}`, up to 256 co-members) alongside the profile and membership routes. As in the app, presence takes no part in establishment: it isn't resumed or carried, and if it fails it doesn't cut a renewal's carry for the other routes. After a tick with no frame since the previous one, they send the app's probe, `REQ probe-N {"kinds":[44100],"#p":[viewer],"limit":0}`, which shows up as `desktop_probe` and is closed at its EOSE. Only frames actually received count, including a publish's OK when it arrives before the probe's deadline. A reaction with no target or a publish whose OK timed out doesn't count. Expiry is judged after the drain against the probe still outstanding. If no frame arrives within the EOSE deadline, the session ends as failed and the client reconnects with backoff. Before this, desktop runs left out presence fan-out and idle-client probes, so they understated load. - **Seed log.** "memberships added (N people)" now reads "memberships ensured", since a rerun adds nobody. - **Docs.** `perf/LOADGEN.md` notes that the six-read cap and flat 30 s timeout are simplifications (the app has neither), and that `legacy` is a lower bound. The pre-fix app also opened a per-channel route for each open or non-member channel and re-sent every route each tick, and the model leaves both out. Not done: an explicit count of REQs abandoned at a renewal (report polish; planned cancellations still aren't errors). ### What got simpler Reads abandoned at the stop now go through one helper, `run::bounded`, which the desktop reads and the root lookup share. Before, each read had its own timeout and its own stop check. `global_reqs` returns the routes the client actually opens, not a fixed pair. The probe and presence routes add one `Route` variant, one op and about 40 lines of session code. `Route::establishes` is now the one place that says which routes take part in establishment, replacing the two `Replay` special cases. "Heard" used to be inferred by comparing activity schedules before and after each step. It now comes from frames only, so `publish` reports whether the relay answered and that comparison is gone. ## Testing On a Blox workstation, at the tree of this PR's head: - `cargo fmt --all -- --check`, `cargo clippy -p buzz-test-client -p buzz-ws-client -p buzz-cli --all-targets -- -D warnings` - `cargo test -p buzz-test-client --lib` (parallel) and `cargo test -p buzz-ws-client`, plus the `loadgen::desktop` tests five more times New tests, each confirmed to fail when its fix is reverted: - `a_read_in_flight_at_the_stop_is_abandoned_not_waited_for`: an 8 s roster read at the stop. Without the stop race the client outlives `drive`'s 5 s stop limit. - `a_cancelled_finish_still_aborts_the_read_task`: aborting `finish()` mid-join ends the read task. With the old `take()`, the task is detached. - `an_eose_in_time_is_not_expired_behind_a_slow_ok`: EOSEs at 1.2 s, publish OKs at 3.5 s, deadline 2.5 s. Without the drain, all four routes time out. - `a_silent_tick_probes_and_an_unanswered_probe_reconnects`: the first connection never answers its probe, so the client reconnects and its next probe is answered. - `a_probe_answered_behind_a_late_ok_does_not_reconnect`: the probe's EOSE arrives in time, but it sits behind a heartbeat whose OK comes after the probe's deadline. With expiry judged against a deadline captured before the drain, the session fails and reconnects. - `a_publish_ok_in_time_answers_an_outstanding_probe`: no probe EOSE ever arrives, and heartbeat OKs answer each probe. - `a_reaction_with_no_target_is_not_heard_as_a_frame`: targetless reactions several times a second still leave the tick silent, so it probes. - `a_reply_whose_root_lookup_the_stop_cut_short_is_not_published`: the stop cuts an 8 s root search short, and OKs are withheld. No `kind 9` EVENT reaches the relay, and the client returns promptly. - `a_backlog_defers_deadlines_for_at_most_one_timeout`: the deferral bound and its reset. - `a_long_backlog_behind_slow_oks_keeps_its_timely_eoses`: 600 replayed events per REQ behind 3.5 s OKs, with a 1.5 s deadline and heartbeats every second. The test fails if the deferral is timed from the REQ instead of from the first pass that defers, and it fails if a second OK wait can run between the deferred passes. - `presence_is_a_live_only_global_only_while_someone_is_watched`: the route's order and its live-only filter in both modes, and that it's absent with nobody watched. - `a_late_eose_is_not_answered_behind_a_slow_ok`: the timely case above with EOSEs at 3 s instead, so all four routes time out, not succeed. - `a_probe_answered_late_behind_a_slow_ok_reconnects`: a probe's EOSE arrives 0.2 s after its deadline while a heartbeat waits for its OK, so the session fails and reconnects. The test also checks that a heartbeat followed that probe on the same connection, so the test can't pass on a probe that simply went unanswered. - `an_answered_probe_is_closed_at_its_eose`: `CLOSE probe-1` goes out before any next probe. - `routes_establish_once_and_a_renewal_holds_them_until_a_cut` gains a case: a renewal where presence times out keeps the other routes carried and establishes nothing. Each new test fails when its fix is reverted (seven mutants in the first round and six in the review round, run on Blox). The test harness now has a tick override that can go below the scenario's 1 s floor, and records EVENT frames by kind. The fake relay sends a REQ's replayed events after the REQ's delay, not before, and the fake API's slow reads sleep in `block_in_place`. No existing test changed behavior. Existing expectations moved for the presence route (one more live EOSE per client) and for reads now abandoned at the stop. 🤖 Generated with [Claude Code](https://claude.com/claude-code) --------- Signed-off-by: Luke Tornquist <tornquist@squareup.com> Co-authored-by: Elrond <28d6302a099e5225b02c4155ac4236e4912603df2ab08dbfc2f4fef08ce598c8@buzz.block.builderlab.xyz> Co-authored-by: Claude Opus 5.5 <noreply@anthropic.com> |
||
|
klopez4212
|
5b738eb647 |
Restyle mobile organization sign-in prompts as toasts (#9050)
Replace the mobile organization sign-in bottom card with the existing top toast treatment. Use shorter status copy, a solid-red Cancel button with white text in both modes, and stacked Retry / Use a different account buttons for denied access with 12 pt side and bottom padding. The account-switch action uses a dark secondary treatment. Recovery callbacks and visibility rules are preserved. Validation: `just mobile-install mobile-check mobile-test`; widget journeys cover sign-in/cancel/completion, saved-session errors, account switching at 200% text size, and transient-toast coordination. The cancel regression was verified to fail with its callback disabled. Local Flutter previews using production widgets, with synthetic state; not device captures. Manual test: sign in, cancel, retry, and switch accounts after denied access; verify each action remains reachable and the toast clears after successful sign-in. Before:  | Light mode · 375 pt | Dark mode · 375 pt | | --- | --- | |  |  | --------- Signed-off-by: kenny lopez <klopez4212@gmail.com> Co-authored-by: Terp <5856f6900e8e0a4e0ea1f4f8d2ee33e4753d2119bc122f94ecafc660b46c0511@buzz.block.builderlab.xyz> |
||
|
klopez4212
|
0bdad8ea96 |
mobile: simplify verified profiles and prioritize full names (#9051)
Simplifies mobile identity presentation: removes verification checkmarks from messages, threads, mentions and profiles, plus issuer/time/disclaimer copy. Profiles show the community-verified full name as the title and the display name below, with fallback when no full name exists. Validation: mobile formatting/analysis, full Flutter suite (4,401 passed, 45 skipped), all 4 unconfigured-push checks, and pre-push hooks passed. Independent review found no blockers. Device and human visual checks pending. <details> <summary>Before / after snapshots</summary> Real Flutter profile widget with synthetic data, light/dark themes; widget previews, not device screenshots. Images are PR attachments only. | Theme | Before | After | | --- | --- | --- | | Light |  |  | | Dark |  |  | </details> <details> <summary>Inline messages — before / after</summary> Actual Flutter channel and thread widgets with synthetic verified-user data; local widget previews, not device screenshots. | Screen | Before | After | | --- | --- | --- | | Channel · light |  |  | | Channel · dark |  |  | | Thread · light |  |  | | Thread · dark |  |  | </details> Signed-off-by: kenny lopez <klopez4212@gmail.com> Co-authored-by: Terp <5856f6900e8e0a4e0ea1f4f8d2ee33e4753d2119bc122f94ecafc660b46c0511@buzz.block.builderlab.xyz> |
||
|
John Matthew Tennant
|
f9ef721e68 |
fix(media): keep transparency in image thumbnails with WebP (#9003)
## Summary
This fixes transparent images showing a black background. Image
thumbnails were always JPEG, which can't store transparency, so a
transparent PNG or GIF upload, such as an agent avatar, rendered on
black wherever a client showed its thumbnail.
The relay now writes a lossy WebP thumbnail at `{sha256}.thumb.webp`,
which keeps transparency, alongside the existing `{sha256}.thumb.jpg`:
- **Encoding:** the WebP comes from libwebp through the `webp` crate,
built from vendored C source, so the relay needs no system library. A
GIF uses its first frame.
- **Upload responses:** the upload descriptor's `thumb`, and its
per-tenant rewrite, point to the WebP.
- **JPEG kept:** installed clients derive `.thumb.jpg` themselves, so
the relay keeps writing it until clients move to WebP with a JPEG
fallback. Existing images still have only their JPEG thumbnail.
- **Serving:** `/media/` serves both variants, each with its own content
type. Other `.thumb.*` extensions still return 404.
- **imeta:** a `thumb` may name either variant, and the relay checks
that the named object exists.
- **Storage sweep:** the bucket taxonomy counts both variants as the
image's thumbnail bytes instead of classifying `.thumb.webp` as unknown.
| 320px thumbnail | JPEG | PNG | lossy WebP (q80) |
|---|---|---|---|
| Transparent avatar (starter-team `fizz.png`) | 11.3 KB, black
background | 65.1 KB | 13.8 KB |
| Opaque avatar (`sprout-agent.png`) | 23.6 KB | 156.5 KB | 12.3 KB |
| Screenshot (`channel-thread.png`) | 13.4 KB | 62.5 KB | 6.4 KB |
Encoding a WebP thumbnail takes 3 to 20 ms.
### Related issue
Supersedes #8772, which served a PNG at the `.thumb.jpg` path.
### Testing
Red/green against a local relay on `:3000`, built from the branch under
test, with Postgres, Redis and MinIO from `docker compose`:
```bash
cargo test -p buzz-test-client --test e2e_media test_transparent_png_thumbnail_is_webp_with_alpha -- --ignored
cargo test -p buzz-test-client --test e2e_media_extended test_ws_imeta_webp_thumb -- --ignored
```
- **On `main`:** both tests fail. The descriptor's `thumb` is
`.thumb.jpg`, and the WebSocket send is rejected with `invalid: imeta
thumb must be a local .thumb.jpg path`.
- **On this branch:** both tests pass:
- Uploading a half-transparent PNG returns a `thumb` ending
`.thumb.webp`.
- HEAD and GET on that URL return `Content-Type: image/webp`.
- The decoded thumbnail keeps alpha 0 on the transparent half and alpha
255 on the opaque half.
- `.thumb.jpg` still returns `image/jpeg`.
- A kind 9 message whose imeta `thumb` names the `.thumb.webp` is
accepted.
## Screenshots
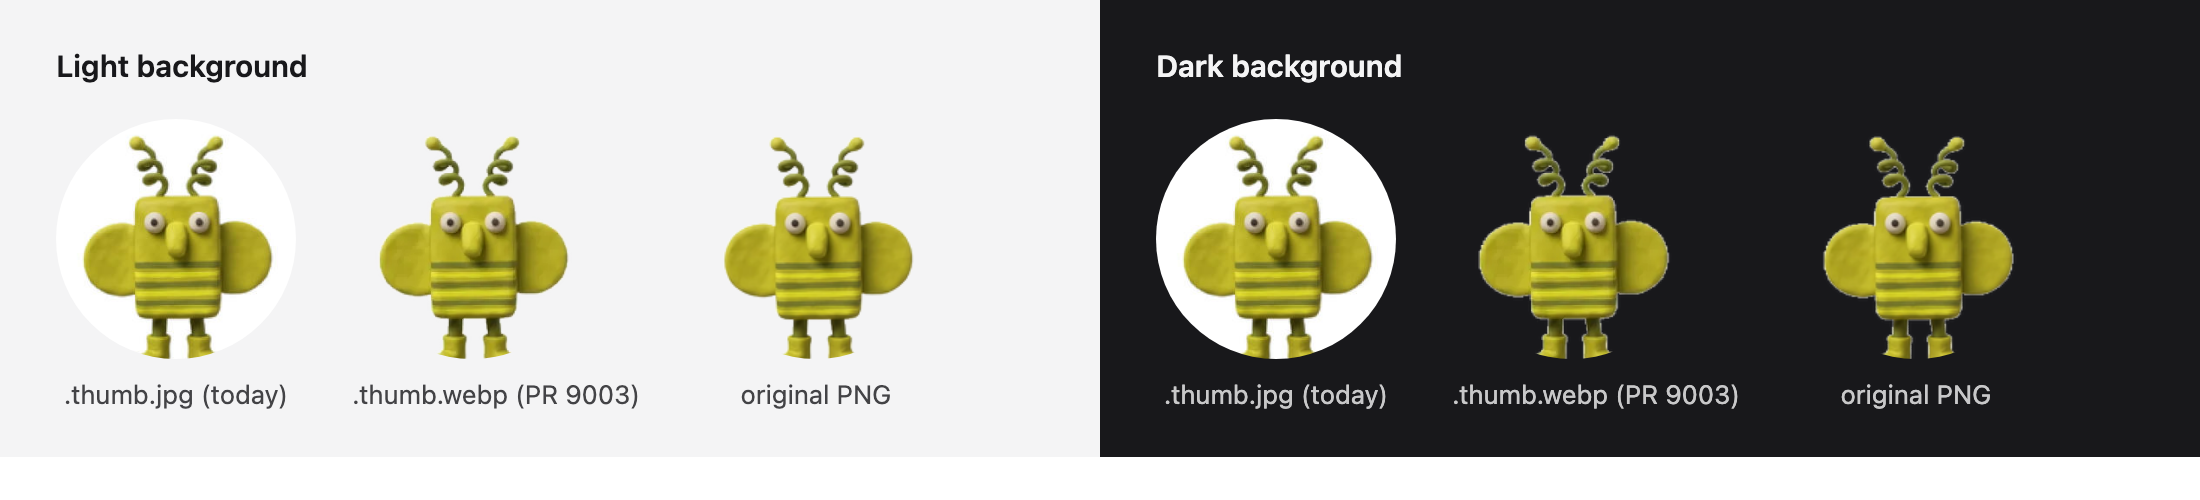
The starter-team `fizz.png` avatar uploaded to a relay built from this
branch. Both thumbnails are shown as round avatars beside the original
PNG. `.thumb.jpg` fills the transparent area with a solid disc, and
`.thumb.webp` keeps the transparency.
🤖 Generated with [Claude Code](https://claude.com/claude-code)
---------
Signed-off-by: John Matthew Tennant <jtennant@squareup.com>
Co-authored-by: Simone <0828be588d5c9c4d092c5b1cf01761d5aef63d6b104807fd8e8284d517dd1a99@buzz.block.builderlab.xyz>
Co-authored-by: Claude Opus 5.5 <noreply@anthropic.com>
mobile-v0.28.0-rc.1
|
||
|
Luke Tornquist
|
d21f0c0fdb |
perf(relay): keep 1 s read caches warm when the pool is saturated (#9012)
## What The relay's 1-second read caches (restriction state, tenant host, open channels) now date each entry from when the read checked out its pool connection, not from when the cache miss began. Concurrent misses on the restriction and tenant-host caches now share one database read. The open-channels cache already did this. ## Why Each of these caches serves an entry for 1 s after "the read that produced it began". Today that start time is taken before waiting for a pool connection. Once pool waits reach about a second (for example, many clients reconnecting at once), every entry is already expired by the time it lands. The cache hit rate falls toward zero exactly when the pool is saturated, so every request does its own read. Those reads queue for the same connections, which stretches the waits further. Requests that time out in the pool then fail closed (`internal error checking restriction state`, `community active check failed; refusing the socket`), and their clients reconnect and add more load. In a local synthetic reconnect load test with a 50-connection pool: - the restriction cache served fewer than one request in five from cache; - the tenant-host cache, which has a single key for the whole deployment, missed more often than it hit; - the open-channels cache missed hundreds of thousands of times on expired entries. ## How - **Stamp at checkout.** `buzz_db::ReadAt<T>` carries a value plus the instant its connection was checked out. The statement's snapshot is no older than that instant, so serving the value for 1 s after it keeps the documented staleness bound, however long the read queued. Three `*_read_at` methods return it: `moderation_restriction_state_read_at`, `lookup_community_by_host_read_at` and `get_listed_open_channel_ids_read_at`. The existing methods now call these and drop the value's timestamp. Each operation keeps one datastore span under its existing name, carried by the `*_read_at` method. - **Share concurrent misses.** `SharedReads<K>` is the per-key gate the open-channels cache already used, moved into its own module. The open-channels cache, the restriction cache and the tenant-host cache now all use it. The first miss reads; the others wait for it, then recheck the cache. A waiter waits for at most the writer pool's acquire timeout plus `SHARED_READ_STATEMENT_WAIT` (1 s). That covers the leader's own wait for a connection, which is what grows in a storm, so waiters keep sharing its read instead of queueing duplicate reads behind it. A failed or cancelled leader releases its waiters at once. A leader whose statement hangs stalls them for at most 1 s past the acquire timeout, never the statement timeout. - **Reject hosts no community can have.** `bind_community` rejects a host longer than `communities.host VARCHAR(255)` can hold (`buzz_core::tenant::MAX_HOST_LEN`, counted in characters) as unmapped, next to the empty-host check. An unauthenticated caller's arbitrarily long host therefore never reaches a resolver, cache, gate or the database. No staleness bound changes: every entry is still served for at most 1 s after its read's snapshot. Invalidation paths are unchanged. A read in flight at an invalidation can still refill the old row for at most that bound, as documented today. ## What got simpler The open-channels gate's hand-rolled `try_lock`/`timeout` block is replaced by `SharedReads::turn`. One gate implementation now serves three caches instead of one implementation that only one cache had. The gate's wait is set once per gate rather than passed at each call site. Provisioning and host binding share one `MAX_HOST_LEN` instead of a private constant. ## Tests - `shared_reads::tests`: one caller reads while the rest wait; a waiter gives up on a hung read after its bound. - `concurrent_restriction_and_host_misses_share_the_in_flight_read`: waiters on both caches use the leader's entry; with an unreachable database, any waiter that read on its own would fail. - `postgres_tests::cache_misses_behind_a_held_pool_share_one_fresh_read`: with a one-connection pool held for longer than every max age, eight concurrent misses on each of the three caches cost one database read, and each entry still lands fresh. - `tenant::tests::an_overlong_host_fails_closed_before_the_resolver`: a host over the limit fails as unmapped with no gate entry and no lookup; a host at the limit, including one in multibyte characters, is still looked up. - Mutation-checked: each of the following turns these tests red: stamping any of the three entries before the pool wait, dropping either new waiter path, letting waiters give up after the cache's max age, dropping the host length check, or counting the host length in bytes. 🤖 Generated with [Claude Code](https://claude.com/claude-code) --------- Signed-off-by: Luke Tornquist <tornquist@squareup.com> Co-authored-by: Elrond <28d6302a099e5225b02c4155ac4236e4912603df2ab08dbfc2f4fef08ce598c8@buzz.block.builderlab.xyz> Co-authored-by: Claude Opus 5.5 <noreply@anthropic.com> |
||
|
klopez4212
|
49fcab3324 | mobile: refine message avatars, metadata and reply gestures (#9046) | ||
|
morgmart
|
0dd778f800 |
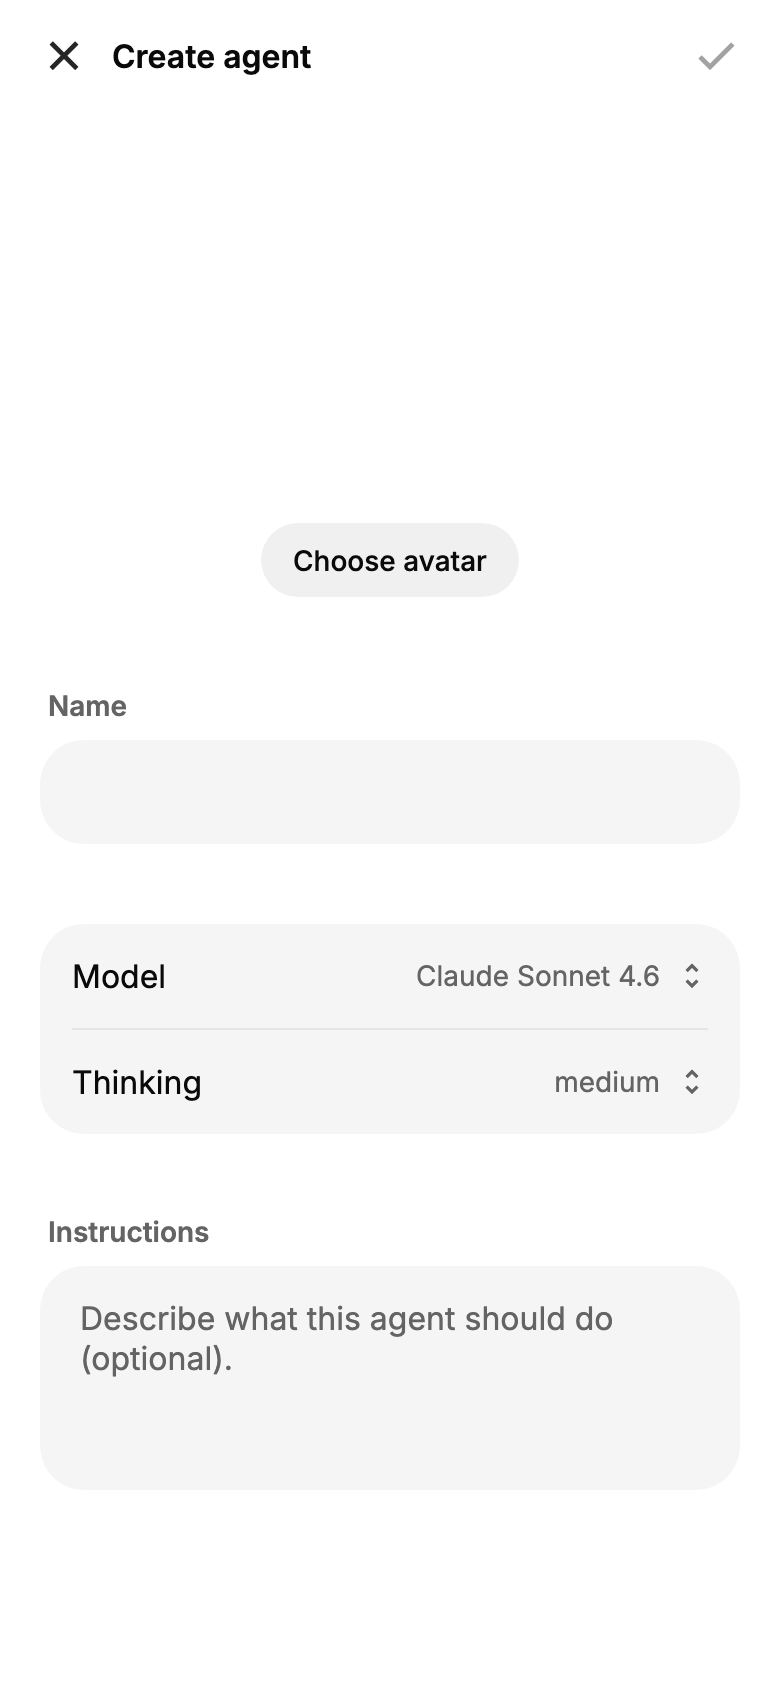
mobile: start new agents on Sonnet at medium effort (#9034)
## Summary
The mobile create-agent screen opened with model and thinking effort
blank, so the easiest path was picking from the full catalog, expensive
models included. A new agent now starts on the first Sonnet model the
catalog offers, at medium effort when that model supports it. People can
still change either one.
- An agent link that suggests a model still wins when Builderlab offers
that model.
- A setup resumed after a failure keeps the choice it saved.
- If the catalog has no Sonnet model, both start blank like today. If
the Sonnet model has no medium effort, only effort is left blank.
Builderlab doesn't send a default or pricing, so the app matches on
"sonnet" in the model id rather than pinning a version. That keeps
working when the catalog moves to a newer Sonnet.
## Screenshots
Captured from the widget test harness with a catalog listing Opus first,
then Sonnet. The avatar preview is blank because the test doesn't load
network images.
| Narrow, light | Narrow, dark | Wide, light |
| --- | --- | --- |
| 
| 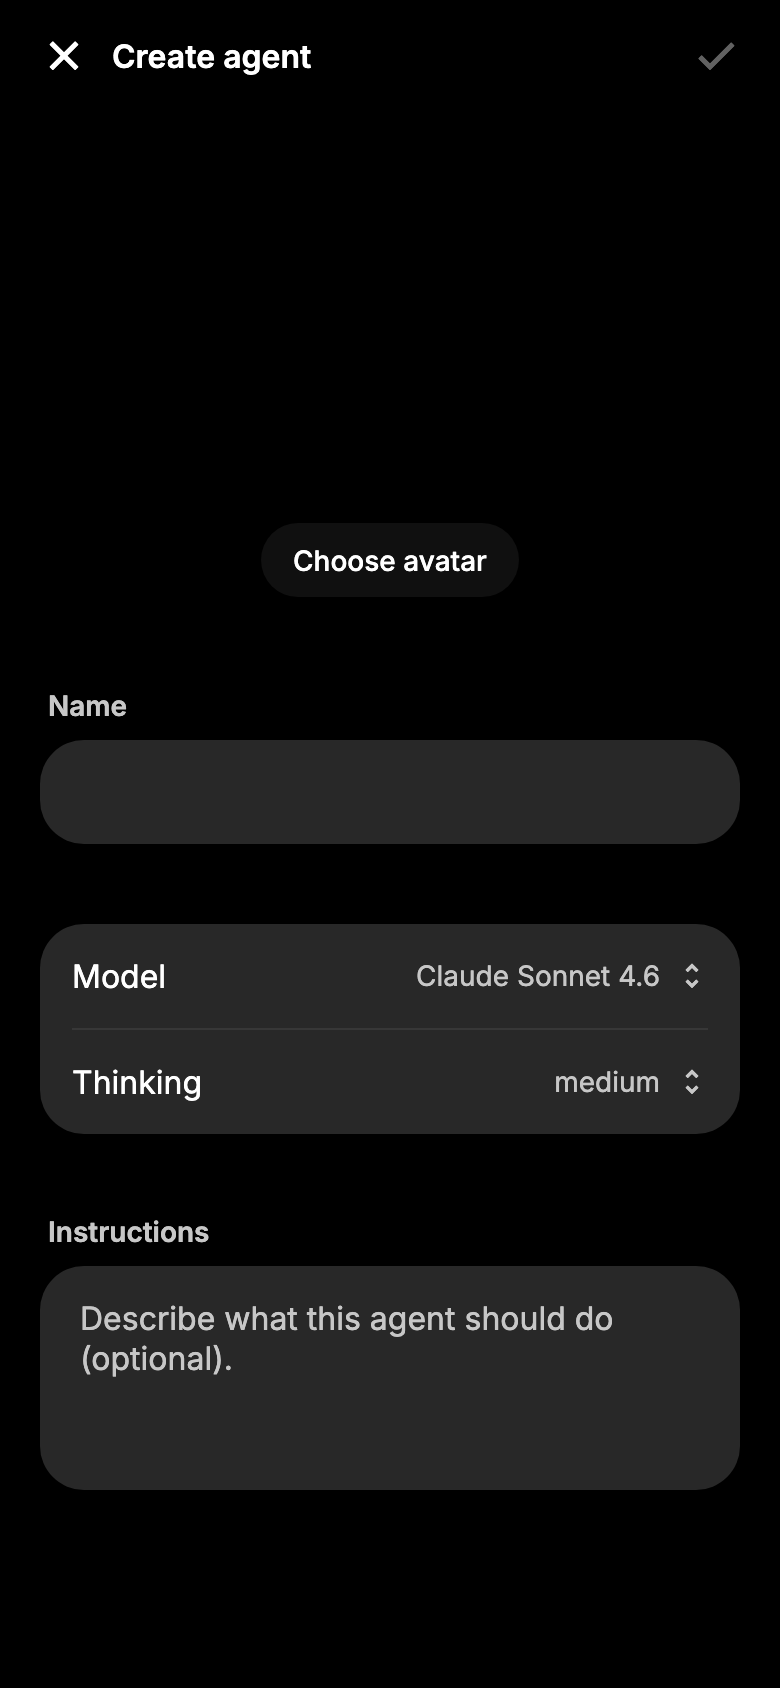
| 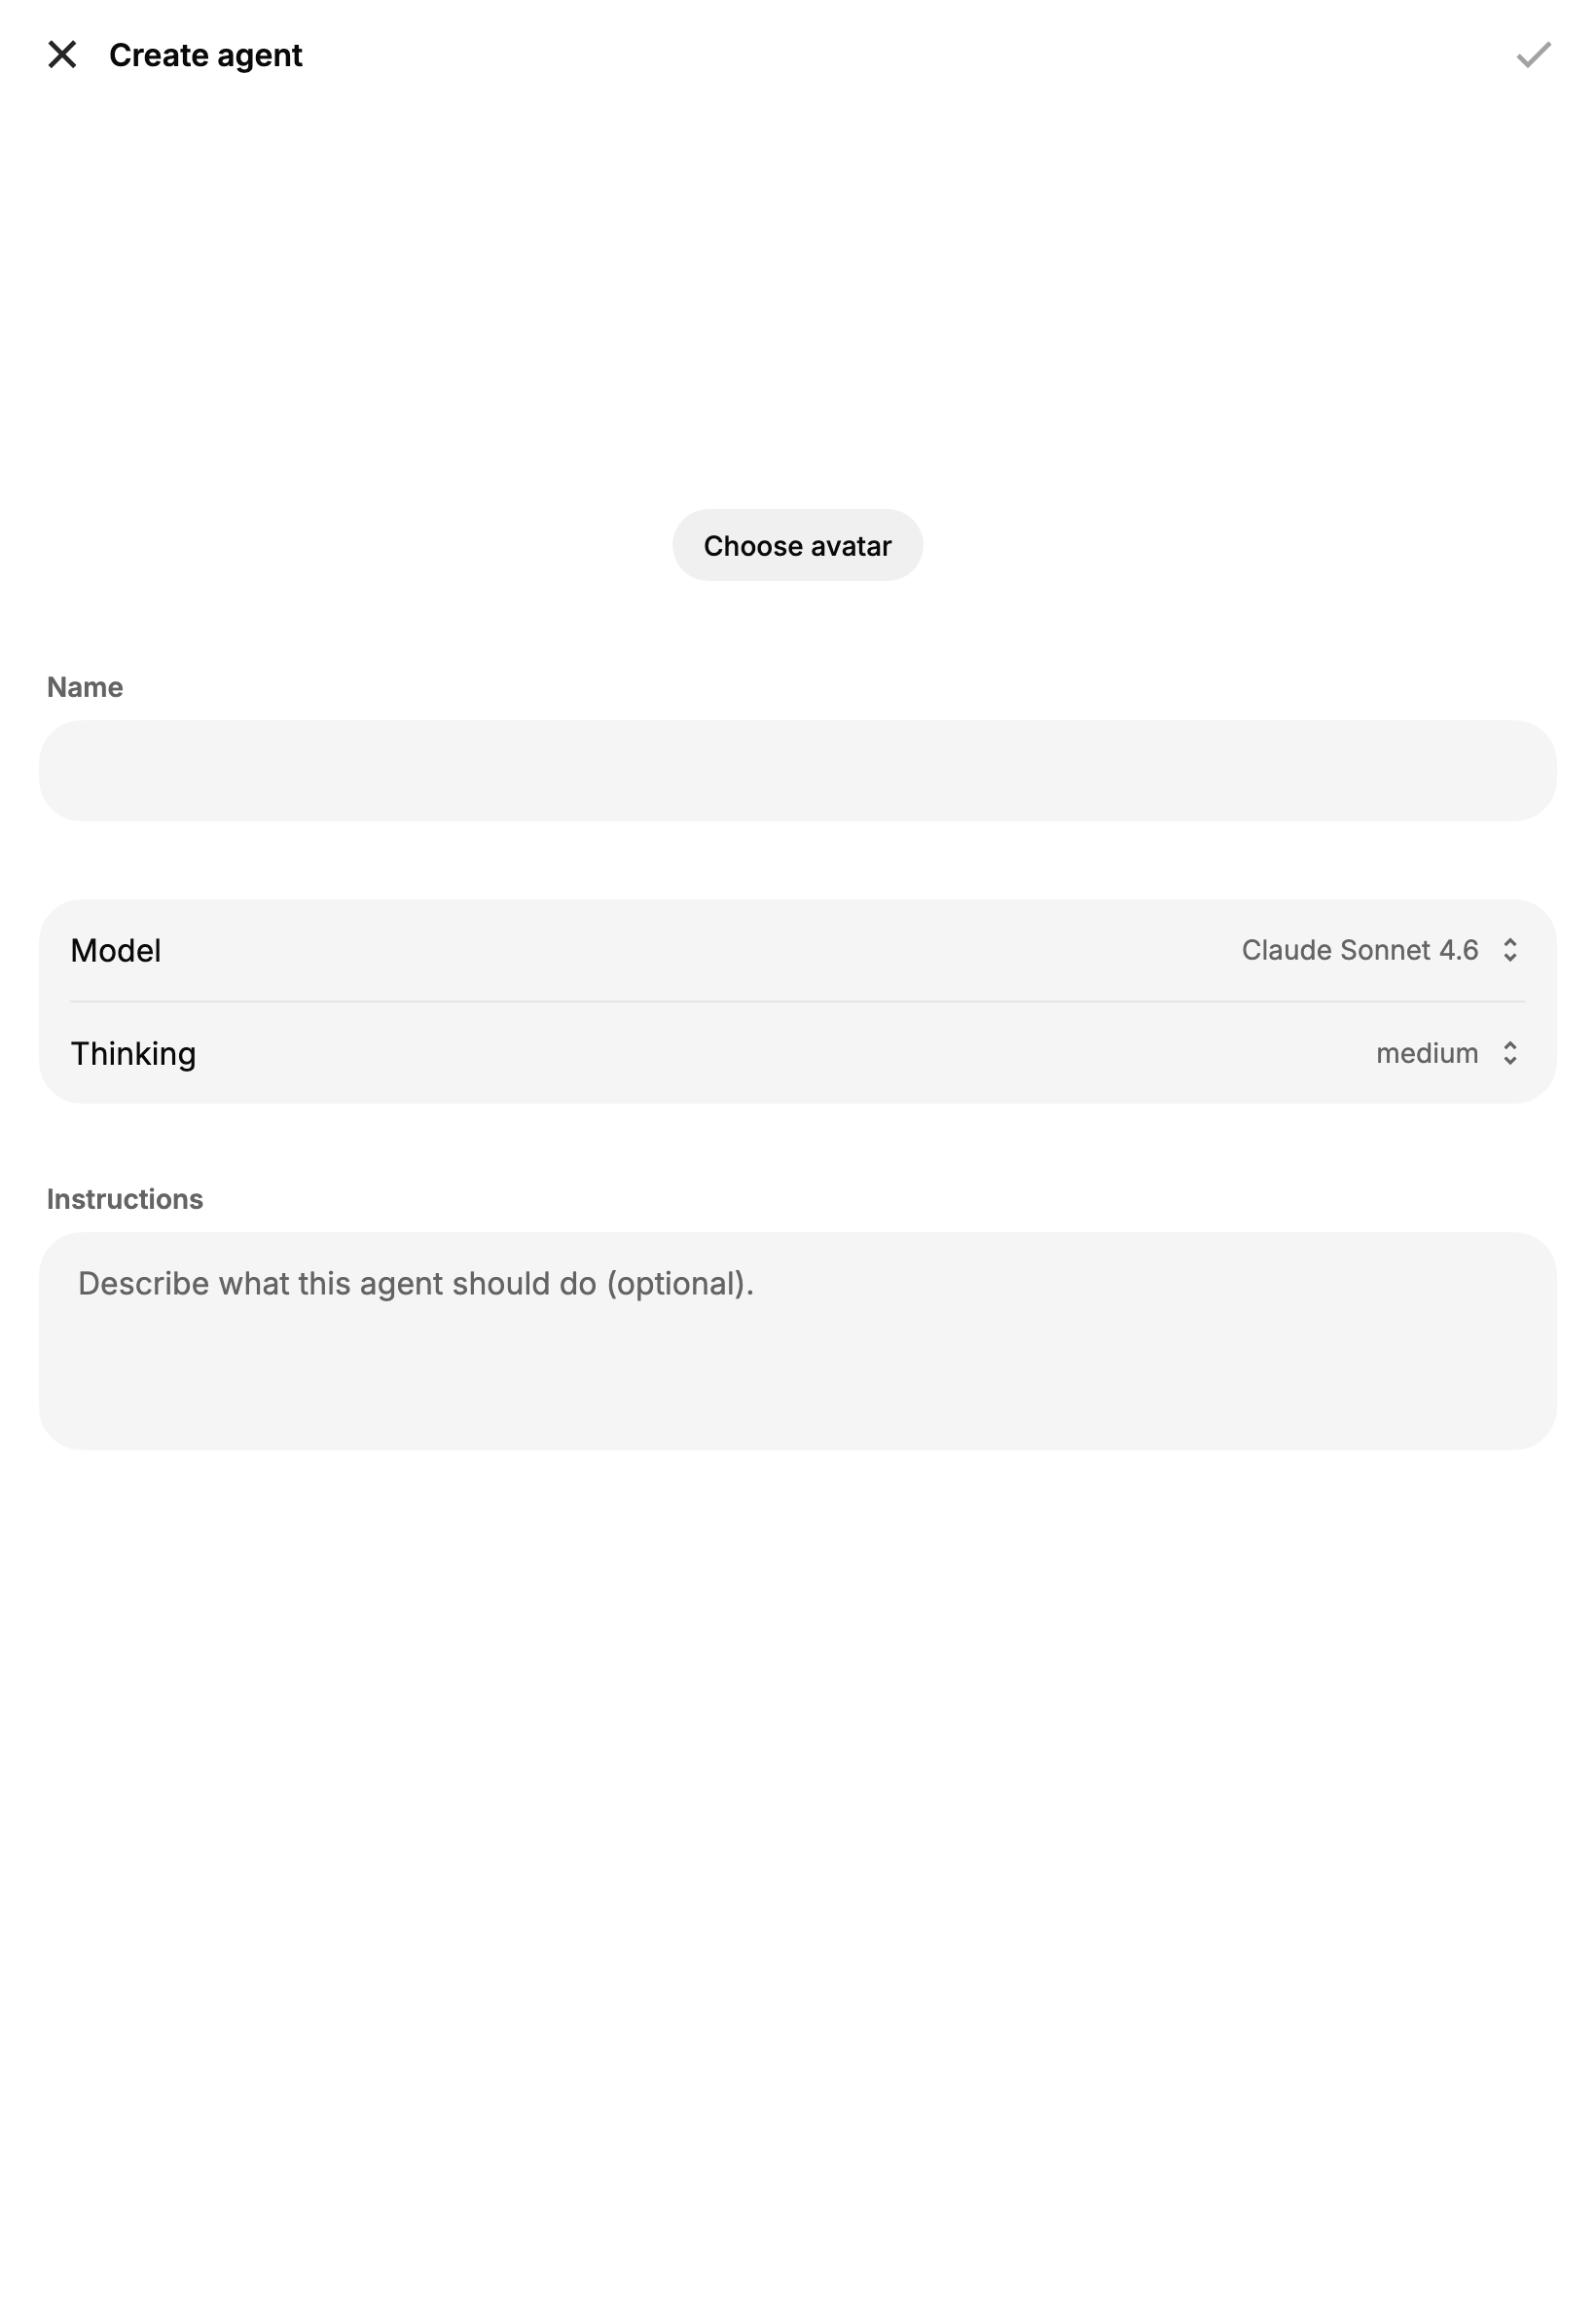
|
## Testing
- New unit tests cover the default, missing medium effort, no Sonnet,
draft model wins, and a draft model the catalog lacks.
- A new widget test checks the form opens on Sonnet at medium and only
needs a name before Create.
- Full mobile suite passes locally with the CI dart-defines
(`BUZZ_PUSH_GATEWAY_URL`, `BUZZ_AUTH_DOMAINS`) at
mobile-v0.27.0-rc.21
|
||
|
Tom Brow
|
f04fa0904c |
fix(mobile): close the community switcher when the org relay refuses the key (#9042)
## Summary Follow-up to #9028 (merged). #9028 closes the community switcher before content loads when organization sign-in is needed, but it checks the session status once. When the session is signed in and the relay then refuses the paired key (`AccountFailure.denied`, which #9001 now saves on purpose), the Home banner offers **Retry** and **Use a different account**, yet the switcher keeps covering it until the 20s "taking longer" timeout. - `organizationSignInPromptVisible()` in `shared/hosted/organization_sign_in.dart` is now the single rule for when the banner has an action. The banner uses it, and so does the switcher. - The switcher listens to the sign-in session and relay auth while it waits for content, and closes as soon as the rule turns true. Listeners are removed on every exit, including the timeout, and the content wait stops listening once the prompt wins. - Relay failures stay scoped to the new community's relay and pubkey, so a stale failure from the previous community can't close the switcher. - `checking` no longer closes the switcher early (the banner is hidden then); a later transition to signed out still does. ### Related issue Related to #9001, #9009 and #9028. No duplicate PR found. ### Testing - New widget test: signed in, switch to an organization relay with content pending, then the relay refuses the key, and the switcher closes. It fails with #9028's one-shot check. - `flutter analyze` is clean. The full mobile suite passes except 10 push and notification tests, which fail the same way on plain `main` on this Mac (local environment; CI covers them). - Pushed with `--no-verify` because of those 10 local failures. 🤖 Generated with [Claude Code](https://claude.com/claude-code) Signed-off-by: Tom Brow <tomb@squareup.com> Co-authored-by: Tom Brow <tomb@squareup.com> Co-authored-by: studio <dc2fc481343672df31a689840c09299972e704dac592e0da6f18486646a7ee3e@buzz.block.builderlab.xyz> Co-authored-by: Claude Opus 5.5 <noreply@anthropic.com> |
||
|
Daniel Rouleau
|
ba7d7825ea |
fix(mobile): show organization sign-in after pairing (#9028)
## Summary Show organization sign-in after pairing. The community chooser closes before it waits for content when the organization session needs sign-in. A long press on **Scan a QR code** reveals the pairing-code option. ### Related issue Related to [#9001](https://github.com/block/buzz/pull/9001) and [#9009](https://github.com/block/buzz/pull/9009). No duplicate PR found. ### Testing On an iPhone 17 Pro simulator, paired with the Block relay using a build that includes both related PRs. The app showed **Sign in** on Home. Completing sign-in remains to be verified.  Generated with Codex Signed-off-by: Daniel Rouleau <drouleau@squareup.com> Co-authored-by: Zerra <345e287bf58aae2b5a483f744e2e362b7f7eea918b4c4427f7a1b3494881d475@buzz.block.builderlab.xyz> |
||
|
Daniel Rouleau
|
14037e3278 |
fix(mobile): show progress after pairing QR scans (#9009)
## Summary After a pairing QR scan, the app shows connection progress until code entry or a connection error. A WebSocket handshake that remains pending stops after ten seconds. Cancel is available until storage starts. It resets pairing and restores the entry form. Pasted codes remain available after an error or cancellation. Back navigation stays blocked during identity transfer and storage. Cancel on Send identity to desktop returns to Settings, so another attempt starts through the authorization step. ### Related issue Related to [#9001](https://github.com/block/buzz/pull/9001), which covers organization sign-in after identity transfer. This change covers the earlier connection stage. ### Testing A simulator build with PR #9001 completes identity transfer and saves the community. The community chooser still blocks organization sign-in. [PR #9028](https://github.com/block/buzz/pull/9028) covers that step. Physical iPhone testing and successful real-relay checks in light and dark mode remain pending. On a build with this change, scan a desktop pairing QR code. Check that progress appears, Cancel returns to the entry form, and a fresh attempt reaches code entry. Paste a pairing code, cancel during connection, and check that the form keeps the code. Test a failed connection and retry. In Settings, open Send identity to desktop, start a recovery connection, and cancel. Check that Settings appears and another attempt asks for authorization. Camera recognition speed and the reported intermittent phone network failure remain unverified. Generated with Codex --------- Signed-off-by: Daniel Rouleau <drouleau@squareup.com> Co-authored-by: Sol <c35e7cc95f6fdbfb7e861dccc02bdca567b6d6b20f16b5115c3c6ae082bbeede@buzz.block.builderlab.xyz> |
||
|
Matt Toohey
|
069cb9a0fe |
fix(desktop): hold a deep-linked message against bottom settles (#8742)
## Summary A product fix for the most frequent unfixed desktop E2E flake, `message-target-highlight.spec.ts:79`. A deep-linked message now holds its place against bottom settles until the reader scrolls. This is one of six PRs split from the reviewed `flakey-tests` branch (siblings below). - **Runs:** it failed in all 7 main runs whose SHA carries every earlier flake fix (40969965981, 40970005965, 40970053997, 40980258899, 40980404335, 40980513346, 40983029157). It also failed in 26 jobs since those fixes landed, on main and on PRs #8235, #8239, #8241, #8666 and #8680. Only the two cases that pick `mounted[2]` fail: "same channel, row loaded off screen" (15 jobs) and "other channel, row further up" (11 jobs). The target scrolls in and flashes, then the timeline lands on the newest message. `stillOnScreen` at :179 reads false (twice it was `flashedOnScreen` at :153). ### Cause The failure videos (run 40983029157, Smoke shard 6) show that the thread panel opening is a precondition, not the trigger. A later floor report moved the target: `TimelineMessageList`'s `onScroll` reported within 32 px of the bottom, during or after the older-page load that only a `mounted[2]` target sets off. `onVirtualizerAtBottomStateChange(true)` reset the anchor to at-bottom. Then the split-panel settle, the viewport-resize settle or the next append settle pinned the timeline to the floor. Which Virtua layout pass emits the floor report is still unidentified. ### Change Accepting a virtual route target sets `targetHoldRef` in `useAnchoredScroll`. Only the two `targetMessageId` paths set it, via `holdTarget`. The public `scrollToMessage`, which the oldest-unread pill and find-in-channel use, doesn't hold, and it replaces any earlier hold. While the hold is set: - The split-panel and viewport-resize settles are skipped. - A floor report still updates `isAtBottom` and the new-message count, but keeps the message anchor, so live appends don't settle either. - A commit that changes the newest message sets `isAtBottom` false and clears `virtualizerAtBottomRef`. It adds the rows after the previous newest one to the new-message count. So the "Jump to latest" / "N new messages" pill still appears for rows below the fold (Review-Proven Rule 6). A history page that fills the gap below a cold target raises no pill, and neither does deleting the newest message. - Viewport reflow re-centres the target through `virtualScrollToMessage`. It runs from the resize observer and when the split panel opens or closes. The hold is released by reader scroll input: a wheel, a touch drag, a pointerdown on the scroller itself, or a scroll key. Those listeners already cancel bottom intent in `useVirtualizedBottomSettle`, and this PR shares them as `listenForReaderScroll`. Jump to latest, the reader's own send and a channel change also release it. A release at the floor restores the at-bottom anchor, so the timeline follows live messages again. `onTargetReached` does not release the hold. ### Known limits - Programmatic scrolls (focus moves, `scrollTop` writes) don't release the hold, but a find or unread-pill jump replaces it. A resize after such a scroll re-centres the target. - ChannelPane's composer-height settle still calls `scrollToBottom` within 32 px of the floor, which releases the hold. - Live messages that arrive under a hold near the floor aren't followed until reader input, Jump to latest or the reader's own send. The pill shows them, with their count. - Under the hold, only rows after the previous newest message count. A same-second row that sorts just ahead of it raises no pill until a later row lands. - Agent review raised two optional gaps, and scrolling recovers from both: - If the previous newest message is deleted and a new row arrives in the same deferred commit, 0 rows are counted. - A thread reply sent with "also send to channel" doesn't arm the bottom intent, so it shows as "1 new message" instead of being followed. ### Related issue None found. ### Testing `useAnchoredScroll.lifecycle.test.mjs` replays the CI sequence: accept a route target, clear it, open the split panel, report the floor, resize and append a live message. It asserts no bottom settle, a re-centre on the panel opening and on the resize, and the pill on the append. Further cases cover: - each release path; - a find jump on a held timeline; - a descendant pointerdown keeping the hold; - a gap-fill page and deleting the newest message, neither of which raises the pill. The split-panel and viewport-resize policy tables each gain a held row. Mutations were run over the lifecycle file and both policy tables (29 tests, all pass intact). Each of the 20 mutations fails at least one test: | Mutation | Tests that fail | |---|---| | Hold never set (the old behaviour) | 12 | | Split-panel settle ignores the hold | 13 | | Viewport-resize settle ignores the hold | 13 | | Floor report resets a held anchor | 12 | | No split-panel re-centre | 12 | | No viewport-resize re-centre | 12 | | Reader input doesn't release the hold | 6 | | Held append raises no pill | 2 | The commit message lists the other 12, each failing 1 or 2 tests. `pnpm typecheck` and `pnpm check` pass. All 46 tests in the files that import the touched modules pass. Only hosted CI can show whether the spec now holds in Smoke shard 6 and in Flake Check's repeats, because Playwright was not run locally. It also has to show that `scroll-history.spec.ts` and the other timeline specs keep bottom-follow working. Pushed with `git push --no-verify`, because the pre-push suites fail when the laptop is under load. ### Readiness and human check An agent review of the combined `flakey-tests` branch (b432453af) found no blockers. This changes desktop app behaviour, so it needs a human in-app check before `buzz-review-completed` is added. Suggested check, in `just dev` against a channel with a few pages of history: 1. Open a message link (a mention or search hit) to a message several screens up, once in the same channel and once from another channel. The message should flash and stay on screen after older history loads, including when the thread panel opens or closes, or the window is resized. 2. With the target still held, have someone post in the channel. The timeline stays put, and the pill reads "1 new message". 3. Wheel-scroll to the bottom, or click Jump to latest. The next message that arrives is followed. ### Siblings - #8739 ci: Hermit fetch deadline and sccache fallback - #8740 test(relay): thread_window aux-page hold and `api::media` Postgres tests - #8741 test(mobile): RunnerTests title fade and alert wait - #8743 test(desktop): four specs racing scroll settles and focus - #8744 test(desktop): five settle classes and remote-owned-mentions 🤖 Generated with [Claude Code](https://claude.com/claude-code) --------- Signed-off-by: Matt Toohey <contact@matttoohey.com> Co-authored-by: Claude Opus 5.5 <noreply@anthropic.com> |
||
|
Logan Johnson
|
1055f79d04 |
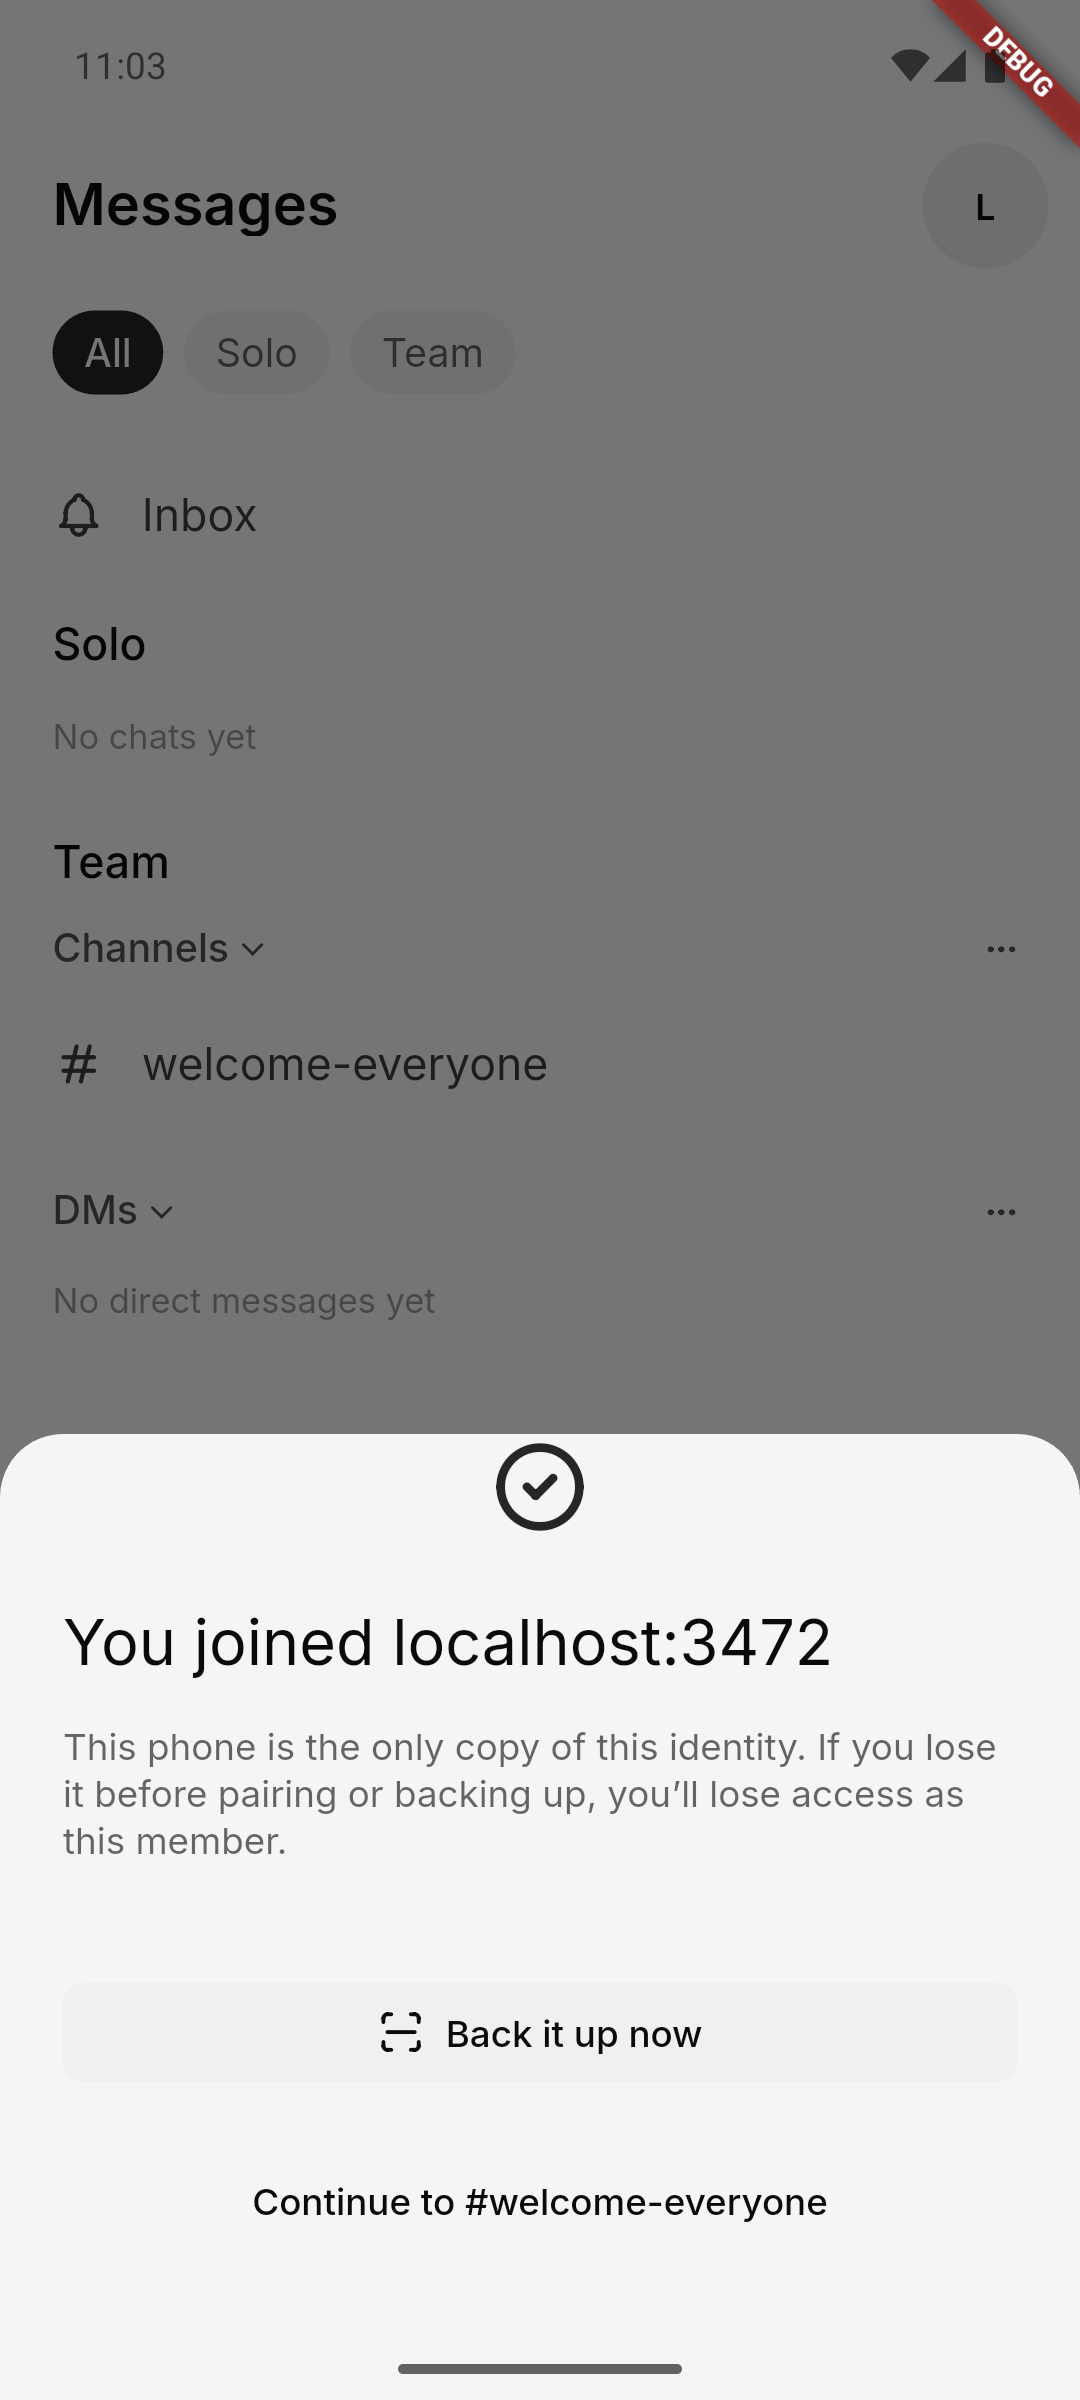
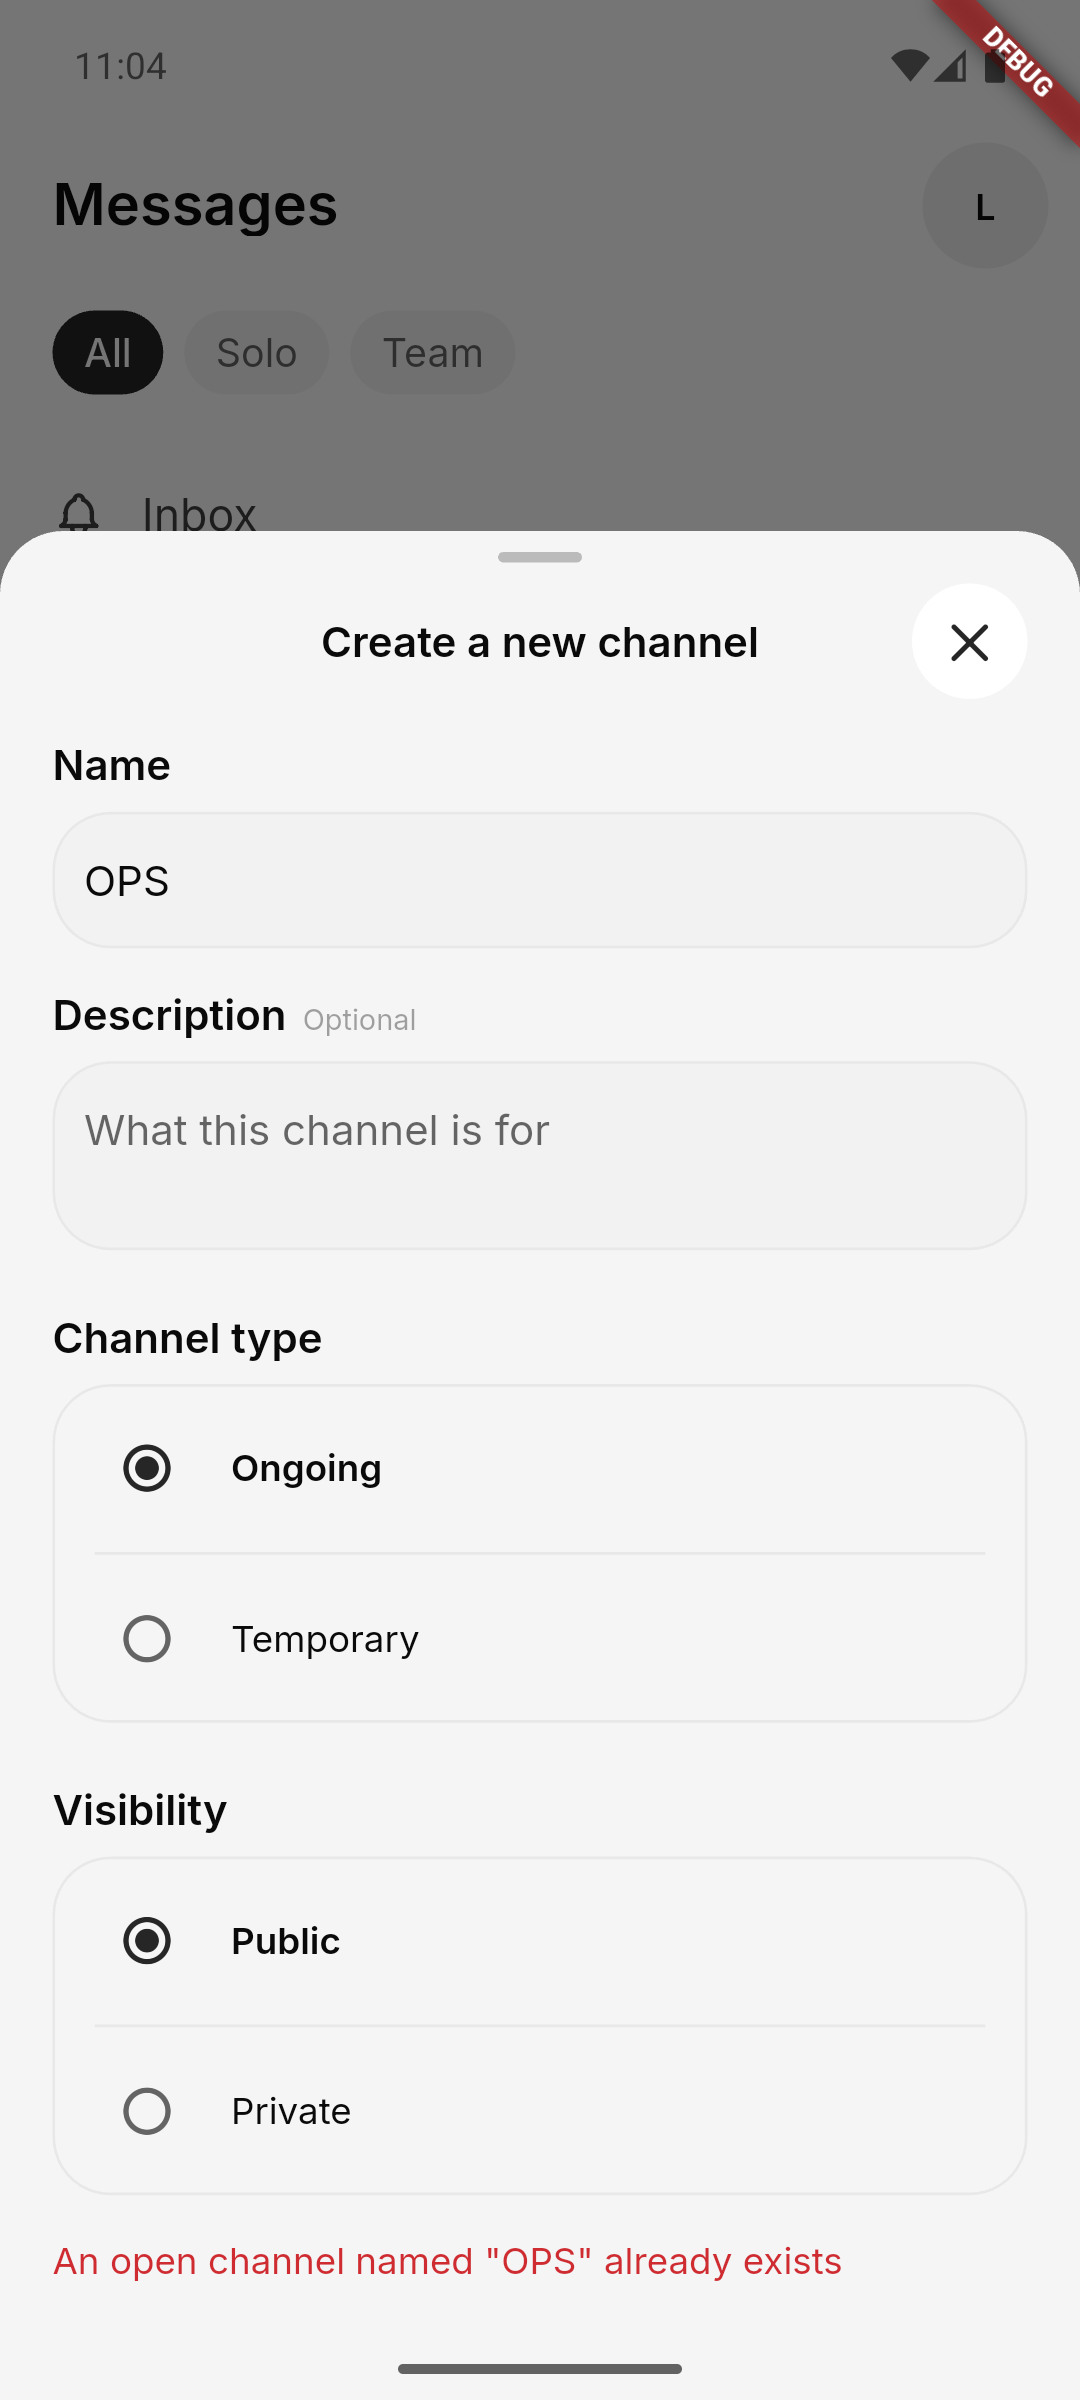
fix(mobile): show a taken channel name plainly and keep invites working (#8807)
## Summary
The relay is starting to refuse a new open channel when another channel
in the community already has that name
(https://github.com/block/buzz/pull/8782). Mobile handled that refusal
badly in two places:
- **Creating a channel with a taken name** showed raw error text:
`Exception: invalid: an open channel named "Launch" already exists`. The
create sheet now shows `An open channel named "Launch" already exists`
and stays open, so the user can pick another name.
- **Joining a community by invite could fail.** After an invite join,
the app joins two starter channels, `#general` and `#welcome-everyone`,
and creates either one if it can't find it. If an archived channel or a
forum already holds one of those names, the relay now refuses the
create, and the whole join failed. Now the app skips a starter whose
name is held by a channel it can't use, and the join succeeds. If the
holder is a live channel the app didn't see at first, the app joins that
channel.
Screenshots from an Android emulator against a local relay built from
https://github.com/block/buzz/pull/8782 are in the Testing section.
## Details
- **Error text.** A new `relayErrorMessage` helper
(`lib/shared/relay/relay_closed_policy.dart`) removes the `Exception: `
wrapper and the relay's machine prefix (`invalid:`, `blocked:`,
`duplicate:` and the other standard prefixes), then capitalizes the
first letter. Only the create sheet uses it. The other error paths are
unchanged.
- **Starter channels** (`ensureStarterChannels` in `lib/app.dart`).
After a taken-name refusal, the app reloads the channel list and looks
for the channel that holds the name:
- A live open stream with that name: join it.
- An archived channel or a forum: skip that starter. An archived channel
can't be joined, and a forum is the wrong type for a starter.
- No visible holder: fail as before. The setup stays retryable, because
the holder may not be visible yet.
- **Which channel counts as the holder.** Only a channel that can hold
the name under the relay's rule counts: open, not unlisted, a stream or
forum. Channels now carry the relay's "unlisted" flag for this. An
unlisted channel with the same name (for example, an unlisted forum the
user is in) doesn't hold the name, so the app doesn't skip the starter
because of it.
- **A starter that was archived.** Desktop and mobile create each
starter at the same fixed id. When the starter at that id is archived,
the relay refuses a new create there with `invalid: channel is
archived`. The app treats that as an archived starter and skips it,
unless a live channel with the name exists. When the relay answers
`duplicate` and the reload doesn't show the channel, the app reads the
channel at the fixed id and skips the starter only if that channel is
archived.
- If `#welcome-everyone` is skipped, the join opens no particular
channel. Both callers already handle that.
### Related issue
None found. Client side of https://github.com/block/buzz/pull/8782.
### Testing
Android emulator, debug build of
|
||
|
Tom Brow
|
38a5d9a1ff |
mobile: tap the settings version footer to copy it (#9021)
## Summary The version line at the bottom of mobile Settings (for example `v0.27.0 (36)`) couldn't be copied, which made it awkward to paste into bug reports. Tapping it now copies the whole string and shows a "Version copied" toast, matching the existing "Copy public key" row. It's keyboard-focusable and has a 48dp tap target. Partial selection isn't supported; it's whole-string only.  ### Related issue N/A ### Validation - Added test: tapping the footer, or reaching it with Tab and pressing Enter, puts `v0.16.0 (432)` on the clipboard and shows the toast. The test also checks that the tap target is at least 48dp tall. - `just mobile-check` and `just mobile-test` pass. - Automated simulator run (debug build, iOS 27): opened Settings, tapped the version, confirmed via `simctl pbpaste` that the clipboard held the exact footer text and the toast appeared; then confirmed the neighboring "Copy public key" row still copies the npub and Settings still closes. Human testing waived per the mobile testing exception. A full recording was posted in Buzz instead of here because it shows internal channel names. 🤖 Generated with [Claude Code](https://claude.com/claude-code) buzz-review-completed --------- Signed-off-by: Tom Brow <tomb@squareup.com> Co-authored-by: Tom Brow <tomb@squareup.com> Co-authored-by: studio <dc2fc481343672df31a689840c09299972e704dac592e0da6f18486646a7ee3e@buzz.block.builderlab.xyz> Co-authored-by: Claude Opus 5.5 <noreply@anthropic.com> |
||
|
Kalvin C
|
3d26ed7dfd |
feat(relay): match verified names in profile search (#9019)
## Summary `POST /profiles/search` only matches kind:0 `name` and `display_name`. In communities that publish NIP-FI verified profiles, a person's surname or directory username often appears only in their relay-signed kind:30382, so typeahead cannot find them by it. - Where the community advertises verified profiles, the search also matches the `display_name`, `username` and `full_name` tags of each current kind:30382 head signed by the relay key. - Verified names need a trailing prefix of at least three characters, as in NIP-50, so a short prefix doesn't make the relay rank every verified head. kind:0 keeps one-character typeahead. Lookups from heads to `events` also match `created_at`, so Postgres prunes to one partition. - Results are paged by person. Each person returns their current kind:0, when they have one, then their current kind:30382, when they have one, whichever matched. A person is ranked by their best match across both sources, using the existing tiers. - NIP-11 `federated_identity.public_profile` gains `searchable: true`, so clients can rely on the response instead of a separate kind:30382 read. - Migration `0081` adds a GIN expression index over the head's name tags on `nip_fi_profile_heads` (built-in `jsonb_path_query_first` and `to_tsvector`, no new functions). The table holds one row per verified person. Like `0078`, the migration builds the index only while the table is empty; populated databases prebuild it with `CREATE INDEX CONCURRENTLY` (`docs/profile-search.md`), and the migration then checks it is valid and has the expected definition. Compatibility: the request schema is unchanged. Existing clients that keep only kind:0 events work as before and also find people who match only by verified name. Trust stays pinned to the relay `self` key; the event shape follows NIP-85 user assertions, but discovery is relay-advertised rather than kind:10040. ## Testing - `buzz-search` Postgres integration: new `profile_names_match_verified_names` covers forged-key heads, replaced heads, other communities, people without kind:0, per-person grouping, paging, and words split across sources; the existing profile-name tests pass unchanged. The test fails when the author filter is inverted. - `buzz-relay` end to end in enforce mode: `profile_search_matches_verified_names_where_advertised` publishes through the real writer and finds the person by surname only where verified profiles are advertised. - Desired-state and migration index definitions match. - `profile_names_use_verified_name_index` asserts the search scans the new index. Migration `0081` checked against an empty table, a rerun, a populated table without the index (raises), the documented concurrent prebuild, and an index with a different definition (raises). - Latency, 50k people each with a kind:0 and a verified head, release build, local Postgres, best of 5, 30 people per page: 11–22 ms with verified names versus 1–8 ms kind:0 only. `EXPLAIN` shows a bitmap scan on the new index. 🤖 Generated with [Claude Code](https://claude.com/claude-code) --------- Signed-off-by: Kalvin Chau <kalvin@block.xyz> Co-authored-by: Claude Opus 5.5 <noreply@anthropic.com> |
||
|
Spencer Lewis
|
83d0bd3203 |
fix(mobile): stop QR pairing to organization relays from hanging (#9001)
## Problem

Pairing a phone to an organization relay by QR (for example Block's
`buzz.block.builderlab.xyz`) never finishes. After the codes match and
the phone confirms, it sits on the loading surface. About 2 minutes
later it returns to the welcome screen with "Lost connection to pairing
relay." The desktop stays on "Finishing pairing on your phone…". This
reproduces every time on Buzz 0.27.0, iOS 27.2, with desktop 0.7.7
(internal tracking: AIDA-2420).

There are two causes:

1. **Validation can never pass for organization relays.** After the
payload arrives, `_validateCredentials` opens a plain `RelaySocket`
without a `Nostr-Federated-Identity` assertion. Organization relays
refuse that upgrade with HTTP 401 until organization sign-in, which a
freshly pairing phone hasn't done.
2. **The failure hangs instead of erroring.** `RelaySocket.connect()`
catches the failed `ready` but keeps `_channel`. The validator's
`finally` then awaits `disconnect()` → `sink.close()` on a channel that
never opened, and that never completes. The phone waits until the
pairing relay's 120 s connection cap closes the socket, and
`_handleDisconnected` reports that as a lost connection.

Standalone repro with `web_socket_channel` 3.0.3 against the real relay:

```
ready failed: ... was not upgraded to websocket, HTTP status code: 401
sink.close() DID NOT COMPLETE within 30s (hang)
```

## Change

- `RelaySocket.connect()` drops a channel whose upgrade failed.
- `disconnect()` waits at most `RelaySocket.closeTimeout` (2 s). An
upgrade that is still pending (connect timeout 10 s) can outlive
pairing's 8 s validation deadline, and its close never completes either.
- `PairingNotifier` skips the pre-sign-in check for
`OrganizationEnvironment.protects` relays. Admission is left to the
saved community's session and the existing organization sign-in banner,
which matches how the hosted branch already defers admission. The
predicate is injectable (`organizationRelay`) for tests. Other relays
are still validated before saving.

Trade-off: an identity that the organization relay would reject is now
saved, and that rejection only surfaces after organization sign-in. The
hosted path has the same property.

## Related issue

No existing GitHub issue covers this failure; searched open issues and
PRs for pairing relay, lost connection and `_validateCredentials`.
Closest:

- #8043 / #8060 cover the same `_validateCredentials` path from the
other side: a failed connect currently returns normally. They're
complementary. With #8060 merged, organization relays would fail pairing
with an explicit 401 instead of hanging, and this PR keeps them out of
that pre-check. Whichever merges second needs a small rebase in
`_validateCredentials`.
- #3181 is a different failure in the same flow.

## Testing

- New `relay_socket_liveness_test` cases check that `disconnect()`
completes in three situations: after a refused (401) upgrade, after a
timed-out handshake, and while the upgrade is still pending.
- New `pairing_provider_test` case: a malformed key is rejected locally
before anything is saved, an organization relay is saved without the
relay check, and a non-organization relay is still validated and
rejected.
- Each new test fails with its fix removed. The failures were
"disconnect() hung on a channel that never opened", "disconnect() hung
on a pending upgrade", and `validated` being true.
- `just mobile-check` and `just mobile-test` pass: 4229 passed, 40
skipped.
- **Simulator run (iOS 27.0 simulator, iPhone 18 Pro, Block organization
dart-defines) against desktop 0.7.7 on `buzz.block.builderlab.xyz`:**
pairing completed (desktop reported the phone paired; identity
transferred; community saved) instead of hanging until the pairing relay
closed. The app then showed the organization sign-in banner and opened
browser sign-in for block.builderlab.xyz, as expected. Okta in the
simulator requires FastPass, so the final relay connection after sign-in
was not exercised there.
- Human device testing is still pending.

## Follow-up

- Test on a real phone with an organization build. The simulator
couldn't complete Okta FastPass, so the relay connection after
organization sign-in still needs checking.

---------

Signed-off-by: Spencer Lewis <slewis@squareup.com>
Co-authored-by: Claude Opus 5.5 <noreply@anthropic.com>
mobile-v0.27.0-rc.20 |
||
|
Tom Brow
|
1bef1da77d |
fix(mobile): show newly created remote agents in the new-chat picker (#9030)
After creating a remote agent on mobile (for example in onboarding), the agent doesn't appear in the Solo **New chat** agent picker. Mentioning it in a channel, or restarting the app, works around this. The picker's agent list (`meAssistantsProvider`) is loaded once and kept for the app session. Creating a remote agent publishes its owner registration (kind 30177), and Beekeeper publishes the agent's attested profile, but nothing told the cached list to reload. So the new agent stayed missing until something unrelated (a relay reconnect or an app restart) rebuilt the list. With this change, the list reloads whenever this device publishes or removes a remote agent registration, using the controller's existing `registrationRevision`. Agents created on another device still show up only after the next reload, as before. ### Validation - Added test: `Solo agent choices reload after this device creates an agent` (hosted build) creates an agent through the real `RemoteAgentController.create` path and checks that the picker's list includes it. It fails without the fix (list stays empty) and passes with it. - Full mobile suite passes, and so do the hosted-build `shared`, `features/agents` and `features/channels/me` suites. Analyzer and format are clean. - Automated simulator pass on the fixed build (signed in to a Builderlab-hosted community): opened **New chat**, the picker listed all 7 agents, picked one, opened an existing Solo chat and the Agents page, then reopened the picker and it still loaded correctly. Human testing is waived per the repository's mobile testing exception. - Limitation: I didn't create a real remote agent on the simulator, because its Builderlab web sign-in stalled. The create → picker path is covered by the added test. 🤖 Generated with [Claude Code](https://claude.com/claude-code) Signed-off-by: Tom Brow <tomb@squareup.com> Co-authored-by: Tom Brow <tomb@squareup.com> Co-authored-by: Claude Opus 5.5 <noreply@anthropic.com> |
||
|
Will Pfleger
|
b14899ffb1 |
docs(nip-fa): define agent grant, assertion and revocation routes (#9015)
Adds wire formats to NIP-FA for agent keys acting under an owner-authorized grant. - **Agent keys**: the owner authorization is a NIP-OA `auth` tag the adapter verifies against the owner's bound key; adapters accept empty conditions and refuse conditions they don't support. An adapter that operates an agent itself may keep its grant internally. - **Agent grant** (`POST /v1/nip-fi/agent-grant`): an RFC 8693 token exchange of the owner's adapter session (as `subject_token`), the agent key's NIP-98 proof in `Nostr-Authorization`, and the NIP-OA tag for an opaque agent grant. Defines neutral token types `urn:nostr:params:oauth:token-type:nip-fa-session` and `urn:nostr:params:oauth:token-type:nip-fi-agent-grant`. An invalid or unacceptable `subject_token` is `400 invalid_request` per RFC 8693 §2.2.2. Grant lifetime is adapter policy. Enrollment replaces earlier grants; an agent key's owner never changes, and a revoked key cannot be enrolled again. - **Agent assertion** (`POST /v1/nip-fi/agent-assertion`): the grant as Bearer plus the agent's NIP-98 proof; same body and checks as `/v1/identity/assertions`, returning `nip-fi-agent+jwt`. `exp` is not capped by any session, and clients check `iss` against the grant's issuer. `401 invalid_grant` discards the grant; an unauthorized relay is `403 authorization_denied`, as on the human route. - **Agent revocation** (`POST /v1/nip-fi/agent-revoke`): the owner's session revokes one agent by pubkey and invalidates its grants and disconnects it through the NIP-FI admin disconnect API; single-field form, 1024-byte limit, idempotent. - Proofs are single-use on the grant and assertion routes. - **NIP-FI assertion transport**: the agent-grant `subject_token` is the one exception to Bearer-only session transport. - **Security considerations**: origin, redirect and logging rules for agent grants. NIP-FI is unchanged: its "Agent keys" section and out-of-scope list are consistent with these routes. --------- Signed-off-by: Will Pfleger <wpfleger@block.xyz> |
||
|
Luke Tornquist
|
865b150371 | fix(db): use ScratchDb in the storage usage delivery test (#9032) | ||
|
Tom Brow
|
9f88eb9c45 |
mobile: hide self-joins and leaves, collapse membership runs like desktop (#8962)
Busy channels fill the mobile timeline with page after page of small "X joined the channel along with Y and N others" and "X added Y to the channel" rows. Desktop now hides most of that ([buzz-app#2258](https://github.com/block/buzz-app/pull/2258)). This brings mobile's membership notices in line with desktop's current rules (`membershipRows` / `membershipDescription` in buzz-app `src/features/messages/membership-rows.ts`). ### Behavior - **Only explicit changes show.** Self-joins and voluntary leaves are hidden. That covers both relay leave shapes: a normal Leave (kind 9022, actor only) and removing yourself (kind 9001, with a target). Additions by someone else and removals still show. - **One row per run.** Each uninterrupted run of additions and removals becomes one row, whatever the elapsed time, local day or actor. Messages and other channel events (topic, archive, huddles) still split runs. - **Each person appears once**, under their latest change in the run. - **Wording:** - One adder: "Alice added Bob, Carol and N others to the channel. See all" (unchanged) - One remover: "Alice removed Bob ... from the channel" (unchanged) - Several adders: "Bob, Carol and N others were added to the channel". It no longer says they "joined". - Additions and removals together, or several removers: "Bob and 4 others were added · Dan was removed". Each "N others" opens that list. Mobile keeps its "See all" sheet in place of desktop's hover popover. ### Validation - Added tests: - unit tests for hiding self-joins and both leave shapes - grouping across hours, days and actors - runs split by messages and other channel events - a channel page journey with a self-join, a 9022 leave, a 9001 leave, additions by two people hours apart and a removal: it renders one mixed row, and the "1 other" sheet works - a several-adders wording test - Updated tests that previously relied on visible self-joins or leaves. - Full mobile suite (`just mobile-test`) and `flutter analyze` pass. - Automated full-app run on an iPhone 17 Pro simulator, signed in to a hosted community: - The home list and a 33-member channel with membership history load. Self-joins are gone, messages flow without them, and a two-adder run reads "X and Y were added to the channel". - Scrolling back through history and opening and closing a thread work. - Captures are not attached because they show internal names. - Limitation: the internal community now rejects the simulator's websocket without hosted sign-in, so the 1,500-member channel wasn't re-checked on this head. - Human testing is waived per the owner's standing policy. 🤖 Generated with [Claude Code](https://claude.com/claude-code) --------- Signed-off-by: Tom Brow <tomb@squareup.com> Co-authored-by: Tom Brow <tomb@squareup.com> Co-authored-by: Claude Opus 5.5 <noreply@anthropic.com> Co-authored-by: studio <dc2fc481343672df31a689840c09299972e704dac592e0da6f18486646a7ee3e@buzz.block.builderlab.xyz> |
||
|
Tyler
|
dafe31bfe5 | feat(mobile): persist frontier-only NIP-RS read state across devices and restarts (#8998) | ||
|
Will Pfleger
|
0a06c0b3cb |
feat(relay): log reads, logins and connections on access target (#8376)
🤖 Adds an access log for relay reads, logins, connections and HTTP requests on the dedicated `buzz_relay::access` target. It writes to stdout, not `audit_log`, so reads never take the audit advisory lock. The log is shaped for volume: one line per HTTP request, one line per WebSocket read, and one line per WebSocket connection. ## Lines per operation | Operation | Lines | |---|---| | HTTP request on a matched route | 1 (`http`), except the skip list below | | HTTP request matching no route | 1 (`http`, `route="<unmatched>"`) at status 400 and above, otherwise none | | WebSocket connection | 1 (`close`, carrying the login) | | WebSocket `REQ` / `COUNT` / NIP-AR sync | 1 each (`req` / `count` / `sync`), plus the `buzz_ws_reads_total` counter | | WebSocket NIP-42 login | 1 (`auth`) per decided or cut-off attempt, capped after the decision as below | | Audio login | 1 (`auth`, at its final admission check) | | WebSocket `EVENT` | 1 (`Event ingested`, not on the access target) | ## HTTP requests One middleware, `http_access_log`, writes every HTTP line. It sits between `track_metrics` and `http_trace_layer`, so rebuilt errors, body-limit refusals and localhost refusals all reach it. It writes the line when the response is ready, which is not proof the body was delivered. A request dropped before then logs `request=aborted` at WARN with no `status`. - Every line carries `route` (the matched route template, never the raw path), `peer_addr` when the listener has one, `status`, `time_to_response_ms` and `http_method` (the HTTP verb). The verb stays on the line itself because the `http.request` span is absent under an access-only filter and when a pending request is dropped. - Handlers record what they learn on the request's `AccessSlot`: the login (`method`, `pubkey`, `pubkey_verified`, `community`), the decision, the filter summary, and the route's own fields. The decision is `outcome` (`success` / `denied` / `failed` / `challenged`) with a fixed `reason`, or `undecided` when the route recorded none. A refusal is final: a later admission doesn't replace it, so a replayed NIP-98 proof that verifies and is then refused logs `failed` / `nip98_replay`. - `outcome` describes the login. What the route did is in `status` and the route's fields: a rejected `/events` write logs `outcome=success` with `status=400`, `accepted=false` and its `reject_reason`. - Route fields: - `/query` and `/count`: the filter summary and `result_count`. An incremental `/query` response (`{changes:[...]}`) counts its changes, removals included. Artifact reads record their summary before the query runs, so a read dropped mid-query keeps it. - `/events`: `accepted`, `kind`, `event_id`, and on a refused write the parse `category` / `line` / `column` or a fixed `reject_reason` (such as `invalid` or `restricted`), never the ingest message. - Invite mint: `invite_id`, `expires_at` and `max_uses`. Invite claim: `joined`. - Admin feedback attachment reads: `feedback_id` and `attachment_sha256`. With `BUZZ_ADMIN_AUTH=disabled` they log `method=network_trusted` with no key, and Host or Origin refusals log their fixed reason. - Every other route logs only the login fields. - No field can hold an invite code, a token, or a Blossom read hash. Media routes log the `/media/{sha256_ext}` template. - Skip list: NIP-11 and other non-upgrade requests on `/`, `/info`, `/.well-known/nostr.json`, `/health`, `/_liveness`, `/_readiness`, and the SPA and static files the relay serves when enabled (web assets, invite landing pages, git web pages, the admin bundle) at any status. Successful WebSocket upgrades (101) log no `http` line. Refusals before the upgrade on `/` and the audio path log one, with the status actually sent. - Routes that aren't Nostr-key logins (the command-token disconnect endpoint, the workflow webhook, the git server's internal callback) log `outcome=undecided` with no key. - Dev-mode `X-Pubkey` requests log `method=x_pubkey`, `pubkey_verified=false`. - A successful `/query` or `/count` that returned nothing (`result_count=0`) logs at DEBUG: on staging, 93% of `/query` lines were empty polls. Denied, failed, aborted and error reads, reads with no `result_count`, writes and logins keep their levels. - Other successful lines and git's credential-less first request (`challenged`, with its 401) are INFO. Refusals, statuses of 400 and above, and aborted requests are WARN. In Enforce mode the line records the remapped status (for example 403). Denial bodies and headers are unchanged. ## WebSocket reads - `REQ` / `COUNT` / `sync` lines carry `pubkey`, `conn_id`, `sub_id`, the filter summary, the outcome (`served` / `denied` / `aborted` / `error` plus a fixed reason), and `events_queued` (REQ and sync) or `count` (a COUNT that counted). A `REQ` is `served` only once its EOSE is queued to the client. A read logs WARN only when it ends in `error`. `served`, `denied` and `aborted` are INFO, since `aborted` means the read ended before completing: the client disconnected or sent CLOSE, a same-ID `REQ` replaced it, or the session was cancelled. - A NIP-AR sync subscription writes its `sync` line when its initial set completes, not when live delivery ends. Its summary is the registered live filter (kinds and channels, never artifact predicates), and `events_queued` counts the initial set. - `REQ` lines stay at INFO even when empty at EOSE, because the subscription can still deliver live events later. - Filter summary, shared with HTTP `/query` and `/count`: `kinds`, channel ids, authors and `p` values each list the first 10 distinct values. The exact `kind_count` / `channel_count` / `author_count` / `p_count` (summed per filter) appears only when the list is `*` or shows fewer values than the filters held. A dimension that any filter leaves open logs `*`. `since` / `until` / `limit` take the widest bound and are absent when any filter leaves them open, so no field understates what the read covered. `ids` is a count only. NIP-50 search logs `search: true`, never the text. Only well-formed channel ids and pubkeys are listed. An artifact read's summary uses only the standard dimensions of each raw filter, so artifact predicates and client-defined tags (such as `#1`) are never logged. The summary is skipped when the access target is off. Under `=warn`, every WARN line, HTTP or WebSocket, still carries it. - Per connection, only the first 16 reads that are refused before they run (`auth_required`, quota, concurrency, overload) or denied are logged. The rest are counted as `reads_suppressed` on the close line. A refusal that arrives after the close line has been written, from a read still running when the client left, logs its own line, so every refusal is either logged or counted, never both. Served reads are never capped. ## WebSocket read counter `buzz_ws_reads_total{type="req"|"count"|"sync"}` counts every parsed `REQ`, `COUNT` and NIP-AR sync frame before admission, exported at zero from startup. It is a metric, so it counts at any `RUST_LOG`, including production's current `error`. ## WebSocket logins A NIP-42 login writes one `auth` line when it is decided. A successful login logs INFO `outcome=success` at its commit point, decided under the connection's close-reason lock, so a disconnect racing the login (session expiry, admin disconnect, revocation, ban or roster removal) either wins, and the login logs no success, or loses and closes the connection right after the success line. A refused or failed login writes one WARN `auth` line with `outcome`, a fixed `reason` from the shared `AuthReason` code set, `pubkey` and `pubkey_verified`. Root WebSocket `auth` lines carry `peer_addr`. AUTH frames after the login is decided are capped at 16 per connection, and the rest are counted as `auth_suppressed`. An attempt cut off by close or session expiry logs `aborted`. Audio logins log one `auth` line at their final admission check. ## Connections The close line is the connection's only line. It is owned by the upgraded socket, so it is written exactly once however the connection ends: a normal close, a refusal while checking the community is active (`refused=not_admitted`), the connection limit (`refused=connection_limit`), or the handler being dropped. It carries `conn_id`, `community`, `peer_addr`, `duration_ms`, the login, `events_queued` / `bytes_queued` (frames the writer accepted and flushed, not client delivery), and the two suppression counters. ## Error text - Database errors log as `DbError::kind()` (SQLSTATE or variant), including the command-executor event insert. Search errors, on both read paths and in the search-cancel task, log as `SearchError::kind()` / the same SQLx classifier. Workflow database and webhook errors log as their codes, since webhook URLs can be secrets. - Git NIP-98 failures log a fixed code. Git subprocess stderr moved to DEBUG because hook output can contain message text. ## Operator notes `.env.example` documents the target, its `event` values (`http`, `auth`, `req`, `count`, `sync`, `close`), the skip list, the levels, and how to turn it down: `buzz_relay::access=warn` keeps refusals, errors and aborted HTTP requests, and of WebSocket reads only those that end in `error`, and `=off` drops everything. It also lists the removed lines: `NIP-42 auth successful/failed`, `WebSocket connection established/closed`, `event=connect`, `HTTP bridge request`, `Event ingested via pipeline`, `relay invite minted`, `relay member added via invite`, `admin feedback attachment read`, and `addr` (now `peer_addr`). JSON lines no longer repeat the current span as `span`, since `spans` already ends with it. A line logged under an explicit `parent:` span loses that parent's fields. The default OTel export filter sets `buzz_relay::access=off`, so access lines aren't exported a second time as span events. `peer_addr` is the TCP peer. `BUZZ_CLIENT_IP_HEADER` optionally names a request header (for example `cf-connecting-ip` behind Cloudflare or `x-real-ip` behind nginx, matched case-insensitively). When set, `http`, `auth` (root and audio), `close` and connection-limit lines also log `client_ip`: the rightmost comma-separated entry of the header's last field, only if it parses as an IP address. It never replaces `peer_addr`, and it is only trustworthy when every request arrives through a proxy that overwrites the header. --------- Signed-off-by: Duncan <dcfd242e557282d7a1e2cf2e6877522682f1e5c6156dc92ca7d90eaedd3b0f95@buzz.block.builderlab.xyz> Signed-off-by: Will Pfleger <pfleger.will@gmail.com> Signed-off-by: Will Pfleger <wpfleger@block.xyz> Co-authored-by: Duncan <dcfd242e557282d7a1e2cf2e6877522682f1e5c6156dc92ca7d90eaedd3b0f95@buzz.block.builderlab.xyz> |
||
|
Shu Hui
|
fa7a3bfbda |
feat(relay): push per-community storage usage to kgoose (#8714)
### Why?
To bill hosted communities for storage in Orb, kgoose needs
per-community storage usage. The relay already computes it in a daily
snapshot, but nothing delivered it anywhere.

## Summary
- Adds opt-in `BUZZ_STORAGE_USAGE_URL`. When it is set, one
leader-elected relay pod checks every 5 minutes for a new storage
snapshot and POSTs it to kgoose's `POST /v1/buzz/storage-usage/record`
(squareup/cash-server#144285) in consecutive batches of up to 50
communities until every community is sent.
- Each batch is `{measured_at, communities: [{community_host,
storage_bytes, storage_objects}]}`. Active communities with no stored
bytes are reported as zero, and re-sends are safe because kgoose bills
each community once per UTC day.
- Retries on 408, 429, 5xx, and transport errors. No migration;
documented in `docs/storage-accounting.md`. kgoose authenticates the
relay as the `buzz` mesh service, so the relay needs mesh egress to
kgoose-builderbot.

### Related issue
None found. Complements #7899 (snapshot history in the DB). Receiving
endpoint: squareup/cash-server#144285.

### Testing
Unit tests cover batching, retry and reject handling, zero-filling, and
a real HTTP delivery that checks the exact kgoose request body. A
Postgres-gated DB test covers the new reads. End to end, a local relay
delivered to a fake endpoint once per new snapshot.

🤖 Generated with [Claude Code](https://claude.com/claude-code)

---------

Signed-off-by: Shu Hui <shu@squareup.com>
Co-authored-by: Claude Opus 5.5 (1M context) <noreply@anthropic.com>
|
||
|
klopez4212
|
8312419652 |
fix(mobile): size reply labels correctly with Bold Text (#9013)
System Bold Text made single-participant reply labels such as “12 replies” wrap or truncate: the handoff measured normal-weight glyphs, then rendered bold glyphs inside that narrower box. Resolve the inherited text style and platform bold override before measuring, and use that same style for rendering. Addresses the fix-before-merge blocker identified by [Tom's agent on #8987](https://github.com/block/buzz/pull/8987#issuecomment-6611883349), specifically [the Bold Text finding](https://github.com/block/buzz/pull/8987#discussion_r4458491084). Tom classified unloaded-root typing, legacy reply-only paging, and working-state label clipping as acceptable later follow-ups; those remain outside this patch. Validation: - Regression loads the bundled Inter font (the default test font masks weight differences), toggles Bold Text off/on/off, and covers idle/working footers at 1x/2x scale. All four cases failed before the production fix. - Formatting and full analysis passed; 4,252 Flutter tests passed (44 skipped), plus 4 unconfigured-push tests. All 27 crypto tests passed. Mandatory push hooks passed. - Self-review found no blockers in this narrow change. Draft pending app/human verification required by AGENTS.md. To verify: enable system Bold Text, open a channel with a single-participant thread, and confirm “12 replies” remains complete; repeat with enlarged text and toggle Bold Text off. No physical-device validation is claimed. Signed-off-by: kenny lopez <klopez4212@gmail.com> Co-authored-by: Terp <5856f6900e8e0a4e0ea1f4f8d2ee33e4753d2119bc122f94ecafc660b46c0511@buzz.block.builderlab.xyz> |
||
|
Salman Mohammed
|
6847882b14 |
fix(relay): stop logging unmapped-host NIP-FI denials as server failures (#8997)
## What this does In enforce mode, a request whose Host maps to no community gets NIP-FI's `authorization_unavailable` 503 (`docs/nips/NIP-FI.md`, Rejection and privacy table). tower-http's default classifier treats every 5xx as a failure, so each of these requests also logs a `tower_http::trace::on_failure` error. That line has no host or path, only `503` and `latency: 0 ms`. When a scanner probes a host this relay doesn't serve, it produces thousands of these lines in a minute, and they trip error-rate alerts even though nothing is down. This PR keeps the wire response the same and stops counting these denials as server failures: - `nip_fi_core::community_denial` builds the same `http_denial` response. When the Host is confirmed unmapped, it adds an internal `UnresolvedHost` response extension. Extensions never reach the wire, so the NIP-FI denial contract ([FI-TRACE-DENIAL-ORACLE]) still holds. - Each site that turns a community-resolution failure into a denial now uses it: - the router guard (`nip_fi_assertion_guard`) - the WebSocket upgrade (`check_nip_fi_at_upgrade`) - HTTP admission, for routes the guard exempts (`Stage::Community`) - The HTTP trace layer now uses `RelayResponseClassifier`. It treats marked responses as expected and keeps tower-http's 5xx-is-failure rule for everything else. Other 503s still log as failures. That includes an unavailable JWKS key source on a mapped host, `deny_protected`, a stale snapshot, and a failed database lookup. ## Why not return 4xx for unmapped hosts? NIP-FI.md maps "community/Host resolution unavailable" to 503, and `nip_fi_enforce_unmapped_host_is_503_before_verification` pins that ruling. Changing the status would be a spec change. This PR only changes how the relay logs these denials. ## Database community source With `BUZZ_NIP_FI_COMMUNITY_SOURCE=database`, a not-found host and a failed lookup (DB error, timeout, shed waiter) return the same denial class. The marker is set only when the host is confirmed unmapped: a missing Host, a non-bindable host, or a live negative-cache entry. Resolver outages stay unmarked and still log as failures. With the `env` source, every resolution failure means the host is unmapped, so it is always marked. ## Testing - `nip_fi_enforce_unmapped_host_is_503_before_verification` (guard, root upgrade, audio upgrade) and `enforce_unmapped_host_is_503_before_nip98_and_verifier` (HTTP admission) now also assert the marker. Mutation check: removing the guard marker turns the router test red. - New `nip_fi_mapped_host_dependency_503_is_not_marked_unresolved`: a mapped-host 503 from an unavailable key source is unmarked and still classified as a failure. - New `relay_response_classifier_skips_only_unresolved_host_denials`: covers marked 503, unmarked 503, 500, 200 and 401. - New `only_confirmed_unmapped_hosts_are_marked_as_expected_denials` (database source, all three sites): a negative-cached host and a non-bindable host are marked; a bound host whose lookup fails is not. Mutation check: marking every database failure turns it red. - `cargo clippy -p buzz-relay --all-targets -D warnings` is clean, and the pre-push `rust-tests` lane passed. - Local relay, before and after. Setup: enforce mode, `RUST_LOG=error`, one mapped host, JWKS unreachable on purpose. Both builds got the same requests: | Request | Status (both builds) | `on_failure` errors before | after | |---|---|---|---| | Unmapped host, 4 protected paths | 503 | 4 | 0 | | Unmapped host, WebSocket upgrade on `/` | 503 | 1 | 0 | | Mapped host, no assertion | 401 | 0 | 0 | | Mapped host, well-formed JWT, JWKS unreachable | 503 | 1 | 1 | | Unmapped host, `/assets/` path and `POST /api/invites/claim` | 404 | 0 | 0 | 🤖 Generated with [Claude Code](https://claude.com/claude-code) --------- Signed-off-by: Salman Mohammed <smohammed@squareup.com> Co-authored-by: opus <f038cc09b32a776e7d95b65c267e9d851777ee2b6cdbd46a48edba01b1d10ebd@buzz.block.builderlab.xyz> Co-authored-by: Claude Opus 5.5 <noreply@anthropic.com> |
||
|
morgmart
|
c24b0f472e |
Open the new Bestie's chat after creating it (#8972)
Stacked on #8957 (Kenny's Bestie onboarding). In #8957, tapping the empty Bestie slot opens Create agent, and saving a first agent makes it Bestie, but you land back on home and need a second tap to start talking. This takes you straight into the new Bestie's chat once creation finishes, which matches where the group DM landed: pick a name and avatar first, then you're chatting with it. - Creating a first agent from the empty slot opens its chat. - Cancelling, or creating an agent that doesn't become Bestie (you already own others), still returns home as before. - The slot stays disabled while the create flow is open, so a double tap during the account check can't open it twice. - Opening an existing Bestie is unchanged; that code just moved into a shared step. Validation: new widget test covers both the create and cancel paths, and it fails without the change. The mobile widget tests touched by the launcher pass (508), and `flutter analyze` is clean on the changed files. Not yet checked: creating an agent on a real device. #8957's recording also stops before submit, so the real create → chat handoff (including how long the new agent takes to appear) still needs a device run. --------- Signed-off-by: morgmart <98432065+morgmart@users.noreply.github.com> Signed-off-by: kenny lopez <klopez4212@gmail.com> Signed-off-by: Tom Brow <tomb@squareup.com> Co-authored-by: Carl <carl@agents.local> Co-authored-by: kenny lopez <klopez4212@gmail.com> Co-authored-by: Terp <5856f6900e8e0a4e0ea1f4f8d2ee33e4753d2119bc122f94ecafc660b46c0511@buzz.block.builderlab.xyz> Co-authored-by: Tom Brow <tomb@squareup.com> Co-authored-by: Morgarita <6e967af659416160ab4f2fd56d74c8c6f273791ee7bfc9468a1be37c387947be@buzz.block.builderlab.xyz> Co-authored-by: Claude Opus 5.5 <noreply@anthropic.com> |
||
|
Luke Tornquist
|
152441ae0a |
feat(loadgen): model desktop clients and large-community shape (#9005)
## Summary

The load generator models every community as many small open channels,
and every human as a bare WebSocket client: four REQs, a little history,
then nothing until the run ends. Large deployments don't look like that.
They have thousands of people in a few communities, a handful of very
wide channels, and some people in hundreds of channels. Their desktop
clients also make most of their relay requests over HTTP and on timers.
This PR adds opt-in scenario knobs for both, so a run can reproduce that
shape and compare the desktop client before and after its recent
request-volume fixes.

Every new key defaults to the previous behavior. Existing scenarios
parse, assign members and run exactly as before.

### Shape

| Key | Default | Meaning |
|---|---|---|
| `shape.private_channels` | `false` | `seed` creates channels private
and adds every member with kind:9000 before posting history. Members are
the humans and agents assigned to each channel up to the largest ramp
step, plus the hot thread's root and authors. Events carry up to 100
members each and run `seed_concurrency` at a time. A rerun adds nobody
new, and any member the relay refuses fails the seed. |
| `shape.wide_channels` | `0` | The first K channels of each community
are wide channels. |
| `population.wide_member_fraction` | `0.0` | Share of humans that join
every wide channel on top of their own. |
| `population.wide_activity_share` | unset | Share of its typing,
messages and reactions a member of the wide channels sends there; the
rest goes to its regular channels. Unset keeps the uniform pick, which
sends half of a 3-wide/3-regular member's traffic to the wide channels
and makes fan-out, not reads, the bottleneck. |
| `population.tiers` | `[]` | `[{ fraction, channels }]`: that share of
humans joins `channels` channels instead of `channels_per_member`. |

Assignment is deterministic by global index, so `seed` and every
`--shard` agree without coordination. With no wide channels and no tiers
it is the old assignment, and a test pins that.

### Desktop clients (`[desktop]`)

| Key | Default | Meaning |
|---|---|---|
| `fraction` | `0.0` | Share of humans that run the desktop model
instead of the basic human. |
| `mode` | `"current"` | `legacy` is the client before its volume fixes;
`current` is after them. |
| `windows`, `threads` | `3`, `1` | Open channel windows and threads,
which are refreshed on connect. |
| `tick_secs` | `60` | Recovery tick period. |
| `backstop_secs` | `900` | `current` only: each tick item (subscription
replacement, roster, unread repair) waits this long since it last ran. |
| `renewal_secs` | `0` | Identity renewal period. `0` disables renewal,
and the first renewal is jittered. |

A desktop human keeps the basic human's presence, typing, messages and
reactions. What it adds:

- **Cold start.** It reads NIP-11 and opens its profile and membership
subscriptions. Its channel subscriptions are batched per mode:
  - up to 10 channels: one replaying batch;
  - `legacy` with more than 10: one per-channel batch per 10 channels;
- `current` with more than 10: a live-only subscription per 2048
channels, plus replays of 10 that are closed at EOSE.

It also makes the app's HTTP reads: roster, channel names, sidebar,
profiles, statuses, emoji, read state, unread repair, reminders, window
catch-up plus notices for each window, and root plus thread page for
each thread. A window catch-up follows the cursor in the relay's window
bounds (kind 39006) for up to five older pages, until the bounds say
history is exhausted.
- **Route establishment.** `legacy` makes every read as it connects.
`current` reads NIP-11, names and sidebar up front, and the rest as each
subscription reaches EOSE, by its replay outcome. A replay of 500
events, a missed deadline, or the live-only batch over 10 channels is a
cut, and so is a route the previous connection never caught up. Only an
EOSE catches a route up: one recovered after a missed deadline cannot be
resumed or carried by the next connection.
  - A continuous profile route skips its read (unless one is owed).
- A continuous membership route only repairs unreads, without the
read-state snapshot, unless a snapshot read failed since; then it runs
the full repair.
- A cut global reads in full, and channel routes always recover windows
and threads.
- **Ticks and renewals.** These follow each mode:
- `legacy`: every tick replaces subscriptions and rereads roster and
unreads, and a renewal is a full reconnect;
- `current`: tick items wait for the backstop, measured from the last
replacement, the last successful roster read, and the last full unread
repair. A failed roster read, unread repair or read-state snapshot is
owed and retries on the next tick; snapshot debt is tracked apart from
repair debt, so a repair without the snapshot never settles it. A
renewal carries its routes: nothing is read while every replay keeps
continuity, and once one is cut every route establishes as on a
reconnect. With more than 10 channels the live-only batch is always cut,
so the channels recover and unreads are repaired, but globals are not
reread.
- **Reporting.** Each request type is its own op (`desktop_roster`,
`desktop_unread`, `desktop_replay_eose`, …).
- **Bounds.** At most 4 REQs set up at once, with a 10 s EOSE timeout. A
tick replacement that misses it is closed, the batch it would have
replaced stays, and the next tick retries. At most 6 HTTP reads in
flight, with a 30 s timeout. A read that comes due while the same read
is running or queued is not added again, and each read leaves the
running set as soon as it settles, so a failed read can retry while a
slow one is still under way. Connects and failed sessions back off. A
stop abandons pending EOSE waits without counting them as failures.
- **Not modeled.** The app also establishes channel routes when a tick
replacement reaches EOSE; the generator does not.

`perf/LOADGEN.md` documents the knobs and the model.
`perf/scenarios/local-desktop.toml` is a short local example with every
knob on.

## What got simpler

- `human()`'s schedule loop (presence, typing, messages, reactions,
session end) moved into one `Activity`. The basic and desktop humans
share it, so neither client duplicates the schedule. The basic human's
random draw order is unchanged.
- Membership stays in one place. `member_channels` remains the single
assignment function, and `channel_members` derives from it rather than
from a second formula, so seeding and the clients can't drift apart.

The desktop model is a new concept: about 1,420 lines of model in its
own module, plus about 1,300 lines of tests. Everything else goes
through existing seams: `Stats`/`Op`, `connect`, `Backoff`, `observe`,
`roots` and `Net`.

Identified debt, not fixed here: CI's `test-unit` runs `buzz-test-client
--lib` with the filter `loadgen::`, so the five crate-root `tests::` in
`lib.rs` (relay message parsing, auth and text event building,
`collect_until_eose`) never run in CI. That gap predates this PR, which
doesn't touch `lib.rs`.

## Testing

- `cargo fmt --check`, `cargo clippy -p buzz-test-client --all-targets
-- -D warnings`, and `cargo test -p buzz-test-client` (plain parallel):
84 lib tests pass.
- Wide activity: a seeded `Rng` over 100k picks gives each share within
1%, and an unset share makes the identical draws to before. A run
against a loopback relay checks that a human's typing lands only in its
regular channels at share 0, and only in its wide channels at share 1.
- Scenario: validation of every new key; deterministic wide-channel and
tier assignment that honors the fractions; `channel_members` inverts the
assignment up to the peak; the default assignment is unchanged; the
shipped scenarios parse.
- Seed: with private channels, a fake relay sees the following, in
order:
  - every 9007 before any 9000, and every 9000 before any post;
  - owner signatures;
  - ≤100 members per event;
  - exactly the expected members per channel;
  - posts authored by channel members.

  A refused member fails the seed, and open channels add nobody.
- Desktop: request planning, window bounds validation, route
establishment, and tick and owed-read rules are unit-tested. End-to-end
tests drive clients against loopback WS and HTTP fakes. The WS fake
replays a planned number of events per subscription and can delay an
EOSE or drop a connection. The HTTP fake answers window pages with
relay-signed bounds, an older aux event and equal-timestamp rows,
refuses unknown cursors, and can fail a read once. They check:
- exact cold-start counts per op for `legacy` and `current` at 5 and 25
channels;
- a window catch-up sends the head, then exactly the bounds' cursor
(`until` + `before_id` of the last row, not the older aux event), and
stops when the bounds say history is exhausted even though that page
came back full;
- after a `current` renewal, 499 replayed events everywhere read nothing
over HTTP; 500 on the channel batch adds channel recovery plus a covered
unread repair; 500 on membership adds roster, read state, unread and
reminders plus channel recovery; 500 on profiles adds profiles, statuses
and emoji plus channel recovery and a covered repair;
- after a dropped connection, complete global replays read only NIP-11,
channel recovery and a covered repair; truncated ones reread both
globals in full;
- with renewals shorter than the backstop, read-state snapshots still
recur at the backstop;
- a tick replacement past its EOSE deadline is closed, the old batch
stays, the next tick replaces it, and one batch wire stays open;
- a failed roster and unread read retry on the next tick, and successful
reads do not run again;
- a failed roster read retries on the next tick while an unrelated slow
read is still running;
- after a failed snapshot, a continuous membership establishment before
any tick still reads the snapshot;
- a route whose EOSE missed its deadline is recovered, and after a
renewal with a complete replay it is recovered in full again rather than
carried;
- `legacy` ticks replace batches (new REQ before the CLOSE of the old
one) and reread;
- `current` ticks do nothing until the backstop, then replace live-only;
  - `legacy` renewals are full reconnects;
- `current` renewals carry small sessions without rereading globals or
channels, and recover channels in large ones.

Each of the nine review-fix tests was checked against a mutant that
restores the old behavior, and every mutant fails its test.
- Smoke: a local relay with Postgres and Redis. I ran `seed` twice, then
`run` of `local-desktop.toml` (60 s) once per mode.
- Both seeds were accepted (780 of 780 posts each), including private
channels and memberships for 340 people. Neither run aborted, no client
was cancelled, and no op recorded an error.
  - Each run used 18 desktop clients:

    | op | `current` | `legacy` |
    |---|---|---|
    | `desktop_live_eose` | 266 | 483 |
    | `desktop_replay_eose` | 24 | 0 |
    | `desktop_roster` | 72 | 289 |
    | `desktop_read_state` / `desktop_unread` | 72 / 99 | 289 / 289 |
    | `desktop_profiles` | 18 | 73 |
    | `desktop_nip11` | 18 | 73 |
    | `desktop_window` | 372 | 596 |

Window reads are below the first smoke (406 and 1086) because catch-ups
stop where the relay's bounds say history is exhausted, rather than
paging while pages came back full. They are above the previous revision
(179 and 470) because each read now leaves the running set as soon as it
settles, so a channel recovery is no longer dropped as a duplicate of a
read that already finished inside a still-running batch.
- The first smoke caught two relay contract mismatches that the fakes
had missed:
    - top-level window pages need `before_id` with `until`;
    - the read-state snapshot answers with an object.

    Both are fixed, and the fakes now enforce both.

🤖 Generated with [Claude Code](https://claude.com/claude-code)

---------

Signed-off-by: Luke Tornquist <tornquist@squareup.com>
Co-authored-by: Elrond <28d6302a099e5225b02c4155ac4236e4912603df2ab08dbfc2f4fef08ce598c8@buzz.block.builderlab.xyz>
Co-authored-by: Claude Opus 5.5 <noreply@anthropic.com>
|
||
|
Luke Tornquist
|
88697f1c59 |
fix(relay): apply kind 5 / 9005 deletions atomically (#8944)
## Summary Kind 5 and 9005 deletions now store the event and soft-delete their targets in one transaction. Before this PR the deletion committed first. The target soft-delete ran afterwards as a best-effort side effect, and a failure there was only logged. Resending the deletion then returned `duplicate:` without retrying. A crash between the two commits had the same result. Either way the relay accepted a deletion while its target stayed live. The bridge `include_aux` closure still compensates for those rows. Its second hop returns deletions of the reactions and edits it found, so clients can cancel them. This PR keeps that hop, because rows already torn this way can't be repaired by a resend: - Ingest rejects events more than 900 seconds from server time. - Clients don't resend deletions that were accepted. - During a rolling deploy, old pods keep writing torn rows until they are replaced. Dropping the hop waits for a follow-up, once existing torn rows have had a verified repair and no old writers remain. ### Changes - **Atomic deletion.** Kind 9005, and kind 5 with `e` targets, go through `Db::insert_deletion_event`, driven by `side_effects::persist_deletion`. The write stores the event and its mentions, soft-deletes the targets and updates their thread counters. It follows the existing `persisted_atomically` path used for workflow deletion and kinds 9000/9002. - A failure stores nothing and rejects the event, so the client can resend. - A resend of a stored deletion inside the ingest window soft-deletes any target still live and is dispatched as inserted. It doesn't repair older rows. - Live 39005, reaction-table cleanup and the 9005 system message still run after the commit and stay best-effort. - Kind 5 deletions of `a` coordinates stay a side effect. - **Closure unchanged.** The channel window and legacy thread-reply paths keep both hops, and the docs (`docs/bridge-channel-window.md`, `docs/nips/NIP-CW.md`) are unchanged. ### What got simpler Deletion no longer has a window where the event is accepted but not applied. `handle_standard_deletion_event` is now only the `a`-coordinate path. Target planning and soft-delete for `e` targets live in one place, `persist_deletion`. ### Follow-ups (not in this PR) - Repair the existing torn rows: soft-delete the live targets of stored kind 5 / 9005 `e` deletions and fix their thread counters. Then drop the closure's deletion-of-aux hop. - Hop 1 still probes every partition once per row id. A partition bound or the indexed `reactions` table would cut that. ### Related issue N/A, found while investigating relay database CPU. ### Testing - `torn_deletions_still_cancel_live_targets_in_both_windows` (bridge Postgres) stores kind 5 and 9005 deletions without soft-deleting their reaction and edit targets. It queries the channel window and the legacy thread path with `include_aux`, without a resend, and asserts each live target comes back with its deletion. - `insert_deletion_event_target_failure_stores_nothing_and_resend_applies` (buzz-db Postgres) uses a trigger to make the target's soft-delete fail. It asserts nothing is stored and the target is unchanged, then that a resend applies both. - `insert_deletion_event_resend_repairs_a_live_target` (buzz-db Postgres): a resend repairs a deletion stored without its target's soft-delete, and a further resend changes nothing. - `failed_target_soft_delete_stores_nothing` and `resent_deletion_repairs_a_live_target` (relay Postgres) cover the same two cases through ingest, for kinds 5 and 9005. - `test_channel_window_rows_overlays_and_exact_multiple_exhaustion` (`e2e_nostr_interop`, Relay E2E lane) deletes its reaction and asserts the reaction leaves the closure. - Blox: fmt, clippy (`buzz-db`, `buzz-relay`, `buzz-test-client`), and the `buzz-db` and `buzz-relay` Postgres lanes. 🤖 Generated with [Claude Code](https://claude.com/claude-code) --------- Signed-off-by: Luke Tornquist <tornquist@squareup.com> Co-authored-by: Elrond <28d6302a099e5225b02c4155ac4236e4912603df2ab08dbfc2f4fef08ce598c8@buzz.block.builderlab.xyz> Co-authored-by: Claude Opus 5.5 <noreply@anthropic.com> |
||
|
Luke Tornquist
|
b8b425e8b1 |
fix(db): drop a superseded head's mention rows with it (#8948)
## Summary

Replacing a replaceable or addressable event soft-deletes the previous
head, but its `event_mentions` rows stayed behind. Only the hard-delete
kinds (read-state and mesh status) removed theirs, in a separate
statement. No mention-index read (`#p` filters and feeds) returns a
soft-deleted event, so those rows are pure cost: every `#p` read walks
them and throws them away.

A kind:39002 roster republish leaves one dead row per channel member, so
a large channel piles them up with every join. Relay-emitted replaceable
lists with p-tags do the same.

The statement that retires the old head now deletes that head's mention
rows as well, through a data-modifying CTE over `RETURNING id`, on all
three supersede paths:
- the relay's kind:39002 roster writer
(`LockedMemberSnapshot::replace_member_event`)
- `replace_addressable_event` (kind 0/3/10000–19999, including the
relay-signed kind:13535 list)
- the NIP-33 parameterized path

Because the CTE covers every row the retire statement touches, a
coordinate that somehow had more than one live row also gets cleaned up.
The shared `superseded_with_mentions_sql!` macro sits at the crate root
so all three mention-indexing replacement paths use the same statement.
The kind:13534 membership-list and push-lease writers also retire heads,
with a bare `UPDATE`, but neither indexes p-tags, so they leave no
mention rows.

## What got simpler

The hard-delete special case (`if hard_delete_superseded { DELETE FROM
event_mentions … }`) is gone. Both retire statements go through one
macro, so a head and its mention rows leave together on all three paths.

## Not in this PR

- Mention rows already left behind by earlier supersedes.
`docs/database.md` rules out data backfills in migrations, so these get
cleaned up out of band, in batches.
- Other soft-delete paths (NIP-09 deletion, moderation, channel deletion
retiring its 39000–39002 events) also keep mention rows. They are
low-volume, and are noted here as identified debt.

## Tests

`superseded_heads_drop_their_mention_rows` (pg) has one table row per
supersede path: the member-snapshot roster writer (lock, replace,
release), the addressable path, the NIP-33 path, and the two NIP-33
kinds that are hard-deleted (NIP-RS read state and mesh status). In each
case the old head keeps zero mention rows and the new head is indexed.
Soft-delete rows check that the old head stays soft-deleted, and
hard-delete rows check that it is gone. Reverting the macro, any single
call site, or the hard-delete statement alone fails this test.

🤖 Generated with [Claude Code](https://claude.com/claude-code)

---------

Signed-off-by: Luke Tornquist <tornquist@squareup.com>
Co-authored-by: Elrond <28d6302a099e5225b02c4155ac4236e4912603df2ab08dbfc2f4fef08ce598c8@buzz.block.builderlab.xyz>
Co-authored-by: Claude Opus 5.5 <noreply@anthropic.com>
|
||
|
Luke Tornquist
|
298a555e34 |
perf(db): bind the channel scope as one array (#8946)
## Summary Event reads scoped to a set of channels pushed one bind parameter per channel: `channel_id IN ($5, $6, …)`. This applies to a viewer's access scope, which the relay adds to every REQ and `/query` without an `#h`, and to explicit multi-value `#h` filters. As a result, the SQL text depended on the viewer's channel count, and every count was a separate prepared statement. That caused two problems in production: - **Re-planning on every call.** A connection rarely reused a cached plan for these reads, so Postgres planned each one again. With no `since`, the plan covers every `events` partition. For `#p` mention reads (the `event_mentions` join), planning took far longer than executing the query. - **Hidden cost.** Monitoring that groups by statement split one query into one row per channel count, so its total cost never showed up in a single place. This PR binds the set as `channel_id = ANY($n)`, so one statement serves every channel count. On a production replica, the same query prepared with `ANY($5)` moved to Postgres's cached generic plan by its sixth run. Planning time dropped to near zero, and that plan was no slower than the custom one. ## What changed - `push_channel_scope` in `crates/buzz-db/src/store/event.rs` builds the channel-scope predicate as one array bind. - `build_query_events_sql` and `count_events_sql` each had their own copy of this block. Both now call the helper. - Semantics are unchanged: - Access scope still keeps channel-less global events. - Explicit `#h` still matches only the requested channels. - An empty set still means "no channels". ## What got simpler Two duplicated 20-line blocks became one helper. The statement count for channel-scoped reads no longer grows with channel count. ## Generic-plan exposure These statements were already persistent prepared statements, so a cached generic plan was always possible whenever the connection's statement cache held one. This change makes that reuse consistent; it doesn't introduce generic plans. Tag-value reads (`has_tag_values`) still run unnamed, as before. Plain (non-`#p`) access-scoped reads stay on custom plans. A production replica, with a viewer in hundreds of channels, ran the plain page read repeatedly under the default `plan_cache_mode`, and every run used the custom ordered index scan. Postgres estimated the generic plan as far more expensive, and when forced, it was orders of magnitude slower. Postgres switches only when the generic plan is no costlier than the average custom plan, so it never chose this one. The generic plan's cost comes from the `LIMIT` and `kind` values it can't see, not from the array length, and the per-arity `IN (…)` statements had the same blind spot. ## Tests - `channel_scope_sql_does_not_depend_on_channel_count` (unit): for the `#p` join and plain reads, for access scope and explicit `#h`, in both the page SELECT and the COUNT, the SQL for 1 channel equals the SQL for 40 channels. It also checks that the SQL uses `ANY(` and that global rows are retained only for access scope. - `channel_scoped_mention_reads_share_one_prepared_statement` (Postgres): on one connection, access-scoped `#p` reads with 1, 2 and 3 channels leave exactly one prepared `event_mentions` statement. With one mention per channel, one global mention, and one in an unscoped channel, every scope of 0–3 channels, with and without globals, returns and counts exactly its own rows. - The existing scope semantics tests still pass: - `access_scope_is_applied_before_historical_page_limit` - the explicit multi-channel `#h` page and count test - Mutation: reverting the helper to one bind per channel fails both new tests. ## Identified debt (not in this PR) - `get_last_message_at_bulk` still builds an `IN (…)` list per channel. It's a separate, lower-volume statement. - Superseded versions of replaceable roster events (kind 39002) keep their `event_mentions` rows. On large channels, a viewer's roster mention rows grow with every membership change. That's a follow-up. 🤖 Generated with [Claude Code](https://claude.com/claude-code) --------- Signed-off-by: Luke Tornquist <tornquist@squareup.com> Co-authored-by: Elrond <28d6302a099e5225b02c4155ac4236e4912603df2ab08dbfc2f4fef08ce598c8@buzz.block.builderlab.xyz> Co-authored-by: Claude Opus 5.5 <noreply@anthropic.com> |
||
|
Will Pfleger
|
f6198f6997 |
feat(relay): record NIP-FI enforce denials at parity with shadow (#8974)
## What this does

In enforce mode, NIP-FI denials used to be returned without a reason
counter or a log line. This PR records enforce denials with the same
`WouldDeny` reasons, label sets and log fields as shadow. **Admission
behavior does not change**: statuses, close codes and frame order are
all the same.

- **`buzz_nip_fi_enforce_total{route,stage,outcome,community}`**: the
same shape as `buzz_nip_fi_shadow_total`, including an `admit`/`admit`
stage, so `1 - admit/total` is the enforce denial rate. Each socket or
HTTP request gets exactly one verdict.
-
**`buzz_nip_fi_enforce_session_end_total{route,reason=expired|revoked,community}`**:
once per admitted session.
- **`buzz_nip_fi_enforce_strict_proof_total{route,outcome,community}`**:
the outcome of the proof check that actually decided the request.
Nothing is verified twice.
- **Log lines** `nip-fi enforce deny` and `nip-fi enforce session end`
(info, `mode="enforce"`, from `buzz_relay::nip_fi_shadow`). Shadow's
`nip-fi shadow would-deny` gains `mode="shadow"`. Neither mode logs
admits.

### How each verdict is recorded once
- **Sockets (root, audio).** `EnforceSession` moves Pending →
Admitted(pubkey) → Ended under one std mutex, and records inside the
lock with no awaits.
  - Root admits at its AUTH commit; audio admits at its join commit.
- A refusal for a non-NIP-FI reason retires the session without a
record. Audio retires it before rollback.
- A deadline the effect gate sees before the expiry worker is claimed at
that seam.
- **Ends.** Revocation and expiry are recorded only by the terminal
transition that wins (`publish_authorization_denied`), and only while
the socket isn't already cancelled. A community close or cancellation
that wins first records nothing.
- **HTTP.** The router guard scopes each enforced request with one
verdict. An agent token's verdict is deferred to the end of the request:
- the first owner-decided refusal is the verdict, otherwise the request
was admitted;
- membership rechecks, batches, Git success and early returns each count
once.
- **Owner provenance** comes from the decision itself
(`BanVerdict{outcome,source}` from one `restriction_state` read), with
no rereads.
- Reasons: `owner_banned`, `owner_ban_unavailable`, `not_stored_owner`,
`owner_link_unavailable`.
- When the agent's own ban read fails and there's a token owner, the
result is `owner/unavailable`, as shadow records it.
- A ban or failed restriction read that ingest catches on `POST /events`
after membership passed replaces the request's admit with `owner/denied`
when the owner's row decided the ban, or `owner/unavailable` on a failed
read. An agent's own ban is not recorded as its owner's.

## Shadow-to-enforce map

| Shadow signal | Enforce counterpart |
|---|---|
| `buzz_nip_fi_shadow_total` denials: upgrade, guard, HTTP admission,
AUTH pairing, deny set, stale binding | `buzz_nip_fi_enforce_total` with
the same stage/outcome, plus a `nip-fi enforce deny` line |
| `buzz_nip_fi_shadow_total` owner stage: ws, audio, http | the same,
from the original decision: root/audio ban seam and owner link; HTTP
`enforce_membership`, smart Git, Git settings, buzz/v1 ban reread |
| `buzz_nip_fi_shadow_total` `deadline/session_deadline` (pending) |
`EnforceSession::expire`, from the worker's winning terminal or the
effect gate that saw it first |
| `buzz_nip_fi_shadow_total` admit |
`buzz_nip_fi_enforce_total{stage="admit",outcome="admit"}`, one per
socket or request |
| `buzz_nip_fi_shadow_session_end_total{reason=expired\|revoked}` |
`buzz_nip_fi_enforce_session_end_total`, same labels |
| `buzz_nip_fi_shadow_strict_proof_total` |
`buzz_nip_fi_enforce_strict_proof_total`, from the deciding check (a
rejection is the route's 403, or 401 when the proof is missing) |
| `buzz_nip_fi_shadow_disconnect_total{admin,accepted}` |
`buzz_nip_fi_disconnect_total` (`api/nip_fi.rs:160`) |
| `buzz_nip_fi_shadow_disconnect_total{admin,propagation_failure}` |
`buzz_nip_fi_disconnect_propagation_failures_total`
(`api/nip_fi.rs:180–185`) |
| `buzz_nip_fi_shadow_disconnect_total{admin,capacity}` |
`buzz_nip_fi_disconnect_capacity_rejections_total`
(`api/nip_fi.rs:196–201`) |
| `buzz_nip_fi_shadow_disconnect_total{cross_pod,capacity}` |
`buzz_nip_fi_cross_pod_capacity_exceeded_total`
(`api/nip_fi.rs:433–434`) |
| `buzz_nip_fi_shadow_disconnect_total{cross_pod,poison}` |
`buzz_nip_fi_cross_pod_shard_poison_total` (`api/nip_fi.rs:442–443`) |
| `buzz_nip_fi_shadow_disconnect_total{cross_pod,lag}` |
`buzz_nip_fi_disconnect_lag_total` (`main.rs:1596–1602`) |

The enforce series was renamed from `buzz_nip_fi_enforce_denied_total`
to `buzz_nip_fi_enforce_total` when it gained the `admit` stage.

## Tests

Infra-free, in the `test-unit` lane:
- `state::enforce_end_is_recorded_only_by_the_winning_terminal`: root
scan, audio scan and deadline, each against a community close or
cancellation first and FI first.
- `nip_fi_http::enforce_strict_proof_records_the_deciding_check_once`:
pass and reject, and no record when cardinality refuses.
-
`nip_fi_shadow_session::audio_owner_link_refusal_shares_roots_seam_and_reasons`:
calls the shared owner-link helper with route `audio`, not a huddle
socket.
- The existing shadow, upgrade, router and HTTP enforce tests.

Postgres lane:
-
`handlers::auth::enforce_root_auth_records_owner_refusals_from_one_decision`:
clean admit then `expired` through the real expiry worker; banned token
owner, banned stored owner, other stored owner and a failed ban read;
authorization reads counted from the decision only.
-
`handlers::auth::enforce_root_deadline_seen_by_the_gate_first_is_recorded_once`:
both orderings.
- `audio::handler::enforce_join_commit_is_the_audio_admission`: drives
the join-commit seam directly, not a huddle socket or the expiry worker:
committed then expired; archived with an expiry held inside the
rollback; gate-first deadline.
-
`api::bridge::token_owner_reaches_membership_on_every_nip_fi_http_route`:
one verdict per request on every NIP-FI HTTP route, including sidebar,
read-state, Blossom and Git, for an owner ban, a stored-owner conflict
and a clear owner.
-
`api::bridge::token_owner_ban_reread_is_the_fixed_nip_fi_denial_on_http`:
own ban, owner ban and unavailable at the reread, on sidebar and Git
settings.
-
`api::bridge::token_owner_publish_ban_is_the_fixed_nip_fi_denial_on_http`:
a late ban or failed read on `POST /events` at the write, typing,
moderation and relay-admin checks records exactly one owner denial and
no admit when only the owner is banned, and no owner denial when the
agent alone or both are banned.
-
`audio::handler::tests::already_expired_audio_bootstrap_records_the_deadline`:
an already-expired bootstrap records `deadline/session_deadline`, not a
deny-set denial.

Each new test names the mutation that turns it red. These were run red:
- deleting root's `session.admit(pubkey)`
- deleting audio's commit `session.admit(pubkey)`
- deleting `effect_refused`
- deleting enforce from `retire_shadow`
- deleting the commit seam's `expire`
- deleting the cancellation guard
- deleting the own-read-failure provenance

---------

Signed-off-by: Will Pfleger <pfleger.will@gmail.com>
Signed-off-by: Will Pfleger <wpfleger@block.xyz>
Co-authored-by: Duncan <dcfd242e557282d7a1e2cf2e6877522682f1e5c6156dc92ca7d90eaedd3b0f95@buzz.block.builderlab.xyz>
mobile-v0.27.0-rc.19
|
||
|
Tom Brow
|
bf13f7c83b |
fix(ios): mint NIP-FI assertions in the notification extension (#8982)
Organization relays that enforce NIP-FI (federated identity) require a `Nostr-Federated-Identity` assertion on `/query`. The iOS notification service extension signed its `/query` with NIP-98 only, so the relay answered `401` and every push from an enforcing organization relay showed the generic "You have a new message." body. The app already mints these assertions in Dart from its organization account session, but that session lives in the app's own keychain, and assertions last minutes, so a cached one is useless by the time a push arrives. This change lets the extension mint its own: - **App:** whenever the organization `BuilderlabAccountClient` adopts or clears its session, the app writes or deletes a device-only keychain item in the group it already shares with the extension. The item holds the organization origin, the session credential and the organization's exact relay hosts (from `BUZZ_ORGANIZATION_RELAYS`). Builds without an organization never write it. - **Extension:** for a community whose relay host is one of those exact hosts, `BuzzRelayAssertionIssuer` requests an assertion from the organization issuer (`/api/goose/v1/buzz/identity/assertions`, session credential plus NIP-98 with the community's account key, the same request the app makes), checks it was issued for that key, and caches it in-process until 30 seconds before expiry. Both `/query` paths (message lookup and sender/channel enrichment) send it. Other relays get no header and never see the session. - Signing out awaits removal of the shared copy and fails if removal fails; each restore that finds no session retries the removal. - If issuance fails or the user is signed out, the extension sends the query without the header and the relay refuses it, which keeps today's generic fallback. Not covered here: relay-hosted avatars on enforcing relays still load without the assertion (the notification text and title are unaffected), hosted Builderlab communities, and Android. ### Validation Added tests: - `testOrganizationRelayQueriesCarryMintedAssertion`: against a stub relay that answers `401` without the assertion, two organization pushes resolve with message body and sender name from a single issuance, a non-organization relay gets neither the header nor the session, and after sign-out the notification falls back. Removing the header from the query path makes this test fail. - `testOrganizationAssertionIssuanceFailuresSendNoHeader`: refused, wrong-key, expired and header-injection responses produce no header. Subdomains and other ports of the organization relay host are never sent the session. - `builderlab_account_test.dart`: the shared copy follows exchange, restore and clear; a failed removal fails sign-out, and the next restore retries it. Focused existing validation: the full BuzzPushKit suite, the hosted Dart tests, `flutter analyze`, and an iOS device build of the app and extension. Not yet validated: a live push from the Block relay on a device. ## Before merge Live device push test: waived by Tom (2026-11-03). 🤖 Generated with [Claude Code](https://claude.com/claude-code) --------- Signed-off-by: Tom Brow <tomb@squareup.com> Co-authored-by: Tom Brow <tomb@squareup.com> Co-authored-by: Claude Opus 5.5 <noreply@anthropic.com> |