mirror of
https://github.com/block/buzz.git
synced 2026-11-14 13:21:02 +00:00
c97c85d8faee7aee989f5a110e38cd38eff551b2
3479 Commits
| Author | SHA1 | Message | Date | |
|---|---|---|---|---|
 Tom Brow |
c97c85d8fa |
perf(mobile): load only the directory when search opens (#9466)
Opening search on a list that is already loaded refreshed the whole
channel list to get the open-channel directory: the membership rosters
(kind 39002), member channel metadata, hidden DMs, Huddle starts, DM
names and the latest messages of every joined channel, then the
directory pages. Only the directory was what search needed; everything
else was already in the list and kept current by live updates.
Search now reads only the directory pages and merges them into the
current list: every channel you are not a member of is rebuilt from the
fresh directory (latest revision per channel, open and non-DM only, the
same rules as a full refresh), and joined channels keep their entries
untouched. When the list has not loaded yet, the full refresh runs as
before.
Races:
- A directory-only load is fenced by scope alone (community, identity,
disposal), not by the list-refresh generation, so it neither retires an
in-flight membership refresh nor is retired by one. A community or
identity switch retires it: its response is discarded and it no longer
owns its loading status, so returning to the first community (before or
after the old request ends) lets search load the directory again.
- Directory loads are ordered among themselves: only the newest one
writes the directory and its load status, so an older full refresh
cannot overwrite a newer search load and vice versa.
- A list refresh that merged an older directory and then installs after
a search load landed re-merges the newer directory, so the open channel
search just found does not disappear.
- A list refresh no longer resets a live directory-only load's status to
idle (that reset existed because a refresh used to discard the in-flight
directory, which it no longer does for this kind of load). A load
retired by a scope switch is not live, so the reset still applies to the
status it left behind.
## Results
iPhone 12 mini, profile build, Builderlab account. Typing a query into
search on a loaded list, more than 30 seconds after the last directory
load (two runs each, same numbers both times):
| | HTTP per search | What it read |
| --- | --- | --- |
| main | 3.59 MB | rosters 1.53 MB, channel metadata and directory 1.26
MB, latest messages 0.80 MB |
| This change | 1.26 MB | directory pages only |
Unjoined open channels still appear in results with their Open badge.
## Regressions
The tradeoff we accept: on a search open, joined channels' member
counts, unread badges and latest-message times are not re-read; they
show what the last full refresh found, as updated by live events since.
Live join and leave notices, metadata changes and new messages still
apply as they arrive, and the next ordinary refresh (launch, reconnect,
resume, pull to refresh) re-reads everything. The case that differs is a
change that live delivery missed on a healthy connection (for example a
roster change made while a live chunk was briefly refused): before,
opening search happened to repair it; now the next ordinary refresh
does.
Nothing else changes: open channels are listed under the same visibility
rules, a failed directory load still reports its error to search and
keeps the cached discovery, and the first load is unchanged.
## Testing
- Full mobile suite passes; `flutter analyze` clean.
- New tests: a search load on a loaded list issues only directory
queries (no roster, member metadata, hidden-DM, Huddle or message
reads), lists the new open channel, drops one that became private and
keeps the joined channel object unchanged; a membership refresh during
the load is kept and does not reset its status; a list refresh that
merged the directory before a search load landed keeps the newer
directory; a community switch discards the response; returning to the
first community, both while the old request is in flight and after it
ended, loads the directory again.
- Automated device run on the iPhone 12 mini: launch, two search
sessions typing a query, results list joined and unjoined open channels,
close and reopen search. Rerun on
|
||
|
Tom Brow
|
5f1cd67985 |
perf(mobile): stop rebuilding Home's channel list when a route covers it (#9459)
Opening any route or sheet above Home (search, a message's action menu, a profile sheet, Activity, Settings) rebuilt Home's whole channel list twice: once when the route started covering Home and once when it finished. On a phone the open channel sits inside Home's conversation pane, so a sheet over a channel (long-press menu, profile) did the same. `HomePage` and `ChannelsPage` read `ModalRoute.of(context)` in their own builds, which depends on every part of the route's state (whether it's current, whether it's offstage, and so on). `ChannelsPage` also depended on the whole `DuoToolbarScope`, whose `active` flag flips whenever a route covers the pane, through `frostedAppBarHeight`. Every channel row and the Solo section depended on `ConversationPaneScope` for the selected channel, and that scope notified all of them when its route-dependent `active` flag flipped. Each of those rebuilt a fresh channel inventory, including Solo rows that had scrolled away, which resubscribed their typing feeds for 30 seconds. Now: - Home's native controls (Activity bell, tab bar, Duo rail) read the route in a small `_NativeControlsGate` leaf, so only they rebuild when Home is covered. - `ChannelsPage` mirrors route currency into its header suppression notifier from a `_RouteCurrencySync` leaf above the header, so the header still switches in the same frame. The two "wait until this route is current again" loops read the same notifier. - `DuoToolbarScope` is an `InheritedModel` with a strip-only lookup, `maybeStripOf`. The frosted header's height and `ChannelsPage` use it, so `active` changes no longer reach them. Every other reader keeps `maybeOf` and its current behavior. - `ConversationPaneScope`'s `active` flag lives in its own private inherited widget, read only by `isActiveOf`. Rows that only need the controller no longer rebuild when it flips. - Opening a channel looks up the conversation pane instead of depending on it. ### Validation New test: opening and closing a sheet above Home rebuilds neither `HomePage`, `ChannelsPage` nor any channel row. It fails without this change. Full mobile test suite, `flutter analyze` and the file-size check pass. On the iPhone 12 mini (profile build, Builderlab): Same scripted run on `main` and on this branch (search opened and closed 3 times, then a message's long-press menu and a profile sheet over an open channel): | | main | this branch | | --- | --- | --- | | Widget builds per search open | 126 to 350 | 56 to 60 | | Build time per search open | 79 to 90 ms | 29 to 41 ms | | Build time, long-press menu open | 64 ms | 17 ms | | Typing subscriptions reopened by the sheets | 9 (about 80 KB of messages downloaded) | 0 | The menu, profile sheet, channel header and Home's tab bar and Activity button behaved the same in both runs. ### Regressions None expected. The native controls and header switch from the same route state as before, in the same frame. A `DuoToolbarScope` strip change still reaches the header and the channel list. --------- Signed-off-by: Tom Brow <tomb@squareup.com> Co-authored-by: Tom Brow <tomb@squareup.com> Co-authored-by: studio <dc2fc481343672df31a689840c09299972e704dac592e0da6f18486646a7ee3e@buzz.block.builderlab.xyz> Co-authored-by: studio <dc2fc481343672df31a689840c09299972e704dac592e0da6f18486646a7ee3e@localhost> |
||
|
Tom Brow
|
3764a2e4d5 |
perf(mobile): ask typing subscriptions only for the typing window (#9454)
Every channel that shows a typing indicator (the open channel, and each Solo row on the home list) subscribes for typing and message events with `limit: 10` and no `since`, so each subscribe replays that channel's last 10 stored messages. The handler then ignores every one of them that is older than the 8 second typing window, so the replay only costs bytes. On an iPhone 12 mini signed in to Builderlab, seven Solo rows made this about 66 KB of kind 9 messages on each cold start, and again on each resubscribe. The subscription now asks only for events inside the typing window (`since` = now minus 8 s), which are the only ones the handler can act on. ### Validation New test: the typing subscription asks for history starting 8 s before it subscribes. It fails without this change. Full mobile test suite and `flutter analyze` pass. On the iPhone 12 mini (profile build with this change, signed in to Builderlab), stored and live events on the typing subscriptions in the first minute or more after a cold start: | | Subscriptions | Kind 9 messages | Typing events | | --- | --- | --- | --- | | Before (60 s) | 7 | 74 (66.6 KB) | 26 (15.6 KB) | | After (80 s) | 8 | 2 (1.5 KB) | 29 (17.8 KB) | Typing events are mostly live ones from agents working in Solo chats, so they stay about the same. The automated run covered a cold start to the home list and its Solo rows. ### Regressions - A device clock running more than 8 s fast can make the relay skip a message that would have ended an indicator. That indicator still clears when its 8 s window ends, and the handler already drops events it considers older than the window, so the same skew loses the same events today. Signed-off-by: Tom Brow <tomb@squareup.com> Co-authored-by: Tom Brow <tomb@squareup.com> Co-authored-by: studio <dc2fc481343672df31a689840c09299972e704dac592e0da6f18486646a7ee3e@buzz.block.builderlab.xyz> |
||
|
Tom Brow
|
11ea8c928e |
perf(mobile): skip avatar URL parsing for non-HTTP URLs (#9448)
Every avatar build checks its URL: `parseAnimatedAvatarUrl` scans for the `#buzz-anim=` fragment and parses both halves, and `usesInsetAgentArtwork` also runs `Uri.tryParse` and a regex. For an ordinary URL that's a few microseconds. Some profile pictures are `data:image/png;base64,...` URLs, though, and those cost about 0.7 ms per check for 100 KB on a Mac, because the fragment search and `Uri` normalization read the whole string. Channel screens, the native navigation bar payload and the DM header portrait run these checks on every build, so a channel with such members pays for them frame after frame. Both functions can only answer yes for an HTTP(S) URL, so they now first look at the first six characters and return early unless the URL starts with `http:` or `https:` (in any case). A data URL is turned away without reading the rest of it. The authority is still checked by `Uri` as before, which also accepts backslashes there (`https:\\host`). ### Validation Added test pinning the answers this check must keep: an `https://` preset poster is inset artwork in any case and with backslash authorities (`https:\\`, `https:/\`, `https:\/`), while `http://`, a leading space, a data URL, an empty string and null are not; an animated avatar URL still is. Existing animated avatar tests (including a data-URL poster with a `#buzz-anim=` fragment) pass; full mobile test suite and `flutter analyze` pass. On an iPhone 12 mini signed in to Block's Builderlab (instrumented profile build), opening a channel whose members include two data-URL avatars (100 KB and 150 KB): over the first 7 seconds, the CPU profile spent 69 ms in these checks before this change and none with it (0 of 647 samples). ### Regressions None expected. Every URL the new check turns away already got the same answer before: `_isHttpUrl` and the preset check both need scheme `http` or `https`, which `Uri` only reports for a string that starts with `http:` or `https:` (it lowercases the scheme, so case doesn't matter, and a leading space already parsed to no scheme). Reviewers compared the old and new functions on several thousand generated URLs (case, whitespace, IDN, punycode, backslash forms) and found no differences. --------- Signed-off-by: Tom Brow <tomb@squareup.com> Co-authored-by: Tom Brow <tomb@squareup.com> Co-authored-by: studio <dc2fc481343672df31a689840c09299972e704dac592e0da6f18486646a7ee3e@buzz.block.builderlab.xyz> |
||
|
Tom Brow
|
5e52fa9831 |
perf(mobile): download the identity archive list only when it changed (#9445)
Every reconnect refetches the community's identity archive list (kind 13535) so the agent pickers stay current. On Block's Builderlab that list is about 228 KB, and it is downloaded again on every resume even though it rarely changes. The provider now remembers the last verified list per community and relay authority, and asks the relay only for a newer one (`since` the known list's `created_at` plus one). When nothing newer exists it reuses the known list, as the same set instance so watchers (mention candidates, search, the Agents page, channel details, the members sheet) don't rebuild. A newer list replaces it after the same verification as before. A list that fails any check, including its signature, yields no archived identities and drops the remembered one. ### Validation Provider tests: a refresh with an unchanged list sends `since`, keeps the known set and leaves the hidden set's listeners untouched; a newer list replaces it and becomes the new baseline; every invalid list (wrong signer, missing `-` marker, bad signature) starting from a warm cache drops the remembered list, so a following empty answer hides nobody. Each new step fails with its fix reverted. The existing verification, community-switch and deadline tests pass with the relay fake now honoring `since`. Full mobile test suite (4803 passed) and `flutter analyze` pass. On an iPhone 12 mini signed in to Block's Builderlab (instrumented profile build), a resume after 60 s in the background downloaded the 228 KB list each time before this change. ### Regressions **Accepted tradeoff: a same-second list can be missed.** The cursor assumes each list the relay publishes is stamped strictly later than the previous one. The relay nearly always does this (`publish_nipia_archival_list` stamps past the current head and republishes on drift), but two lists published within one second can share a `created_at`, and NIP-IA then keeps the one with the lower id. If the app already holds the other one, it misses the replacement until a later list arrives (the next archive or unarchive) or the app restarts. Meanwhile a just-archived or just-unarchived agent can show wrongly in pickers and search, never in history. We accept this for the bandwidth and resume-time win; a relay follow-up that stamps each list under the replacement lock and makes the rule a NIP-IA MUST removes the case. The same bound applies if a relay's database is restored to an older list: the app keeps its newer one until the relay publishes a list newer than it, or the app restarts. A failed or timed-out fetch still hides nobody, as before. --------- Signed-off-by: Tom Brow <tomb@squareup.com> Co-authored-by: Tom Brow <tomb@squareup.com> |
||
|
Tom Brow
|
9e40bf5d79 |
perf(mobile): don't treat a Control Center pull as a resume (#9443)
Pulling down Control Center or Notification Center, answering a system alert, or glancing at the app switcher moves the app to `inactive` and straight back to `resumed`. The app never leaves the foreground and the socket stays connected, but every resume listener treated it as a return from the background. Each glance re-read the channel list (memberships, metadata, unread catch-up), the four settings documents (mutes, stars, sections, sort) and the Me groups, and tore down and rebuilt the community presence subscription. On a heavy Builderlab account that is about 2.6 MB per glance. This adds `appForegroundProvider`, which follows the app lifecycle but ignores `inactive`. The resume refreshes and both presence providers watch it instead of the raw lifecycle, so they run only when the app actually comes back from the background. Camera capture keeps watching the raw lifecycle, since it has to release the camera while the app is inactive. ### Validation Added tests: the channel sync journey test now pulls the app through `inactive` and back without leaving the foreground and expects no membership read; it fails without this change (2 reads instead of 1). The existing resume and background cases in that test still pass unchanged. A second step lets a failed list read's retry come due while the app is `inactive`; it is read then, not left for a resume that no longer comes (it fails without the read gate change, 8 reads instead of 9). Full mobile test suite passes. On an iPhone 12 mini signed in to Block's Builderlab (instrumented profile build), pulling Control Center down and dismissing it: | | Downloaded after dismissing it | | --- | --- | | Before | 2.6 MB (rosters 1.5 MB, latest messages 0.7 MB, channel metadata 183 KB, settings, presence resubscribe) | | After | 6.5 KB (live typing and presence only) | The same run covered cold start, 5 minutes idle on Messages, and a resume after 60 s in the background; the resume still refreshed the channel list, read state and settings documents as before (2.8 MB HTTP, 2.1 MB WebSocket). ### Regressions None expected. A real return from the background still goes through `hidden`/`paused` first, so it triggers every refresh it did before. The only behavior change is for `inactive` alone: no refetch, and the user's presence no longer flips through a republish of `online`. A channel-list read that comes due during `inactive` (a membership notice or a retry) now runs then instead of waiting for a resume, since the socket is still connected. A missed live event during a Control Center glance is still caught by the next real resume or reconnect, as before for any time in the foreground. --------- Signed-off-by: Tom Brow <tomb@squareup.com> Co-authored-by: Tom Brow <tomb@squareup.com> Co-authored-by: studio <dc2fc481343672df31a689840c09299972e704dac592e0da6f18486646a7ee3e@localhost> |
||
|
Tom Brow
|
15c65c76d9 |
fix(mobile): keep a superseded roster read out of the offline snapshot (#9452)
The channel member list keeps a snapshot of the last roster it read, which it shows while the relay is disconnected. When two roster updates arrive close together, the member list starts a read for each. If the first read answered after the second, it still wrote its older roster over the snapshot. The live list stayed correct, but once the app went offline it showed the older roster: for example, a member just removed, or a bot role just changed, came back. A read that a later read has replaced no longer writes the snapshot. The snapshot cache numbers each read of a channel's roster, and only the latest read for that channel may write. A read that ends because nothing is watching the list any more (the user leaves the screen mid-read, or a one-off lookup such as sending a message) still writes, since its roster is the newest one. ### Validation New tests, which fail without this change: - Two roster updates arrive, the second read answers first and the first answers after it, with a roster, with no roster event, or with an empty roster. Once disconnected, the member list still shows the newer roster. - A roster update arrives and the user leaves before its read answers. Once disconnected, the member list shows that newer roster. (This passes on main and guards against fencing on disposal, which an earlier version of this PR did.) The rest of the channel management tests pass unchanged. Full mobile test suite and `flutter analyze` pass. The race itself needs two roster reads to answer out of order and then a disconnect, which a device run can't reliably produce. An automated run on an iPhone 12 mini signed in to Block's Builderlab (profile build of this head) covered the roster paths it touches: cold start, searching for and opening buzz-mobile, its details (86 members) and its member list (49 people, roles shown), scrolling it, backgrounding the app for 60 seconds, resuming, and reopening the member list, which loaded the same roster. ### Regressions None. A replaced read's result was already discarded for the live list; now it is also kept out of the offline snapshot. Reads that nothing replaced write the snapshot as before. --------- Signed-off-by: Tom Brow <tomb@squareup.com> Co-authored-by: Tom Brow <tomb@squareup.com> Co-authored-by: corey <2dafccf60ea6d431a568f6d67fc60016c1b2a51e415e09dc8b213b8e3606cf54@buzz.block.builderlab.xyz> Co-authored-by: studio <dc2fc481343672df31a689840c09299972e704dac592e0da6f18486646a7ee3e@buzz.block.builderlab.xyz> Co-authored-by: perfie <1fc92b08616bef6025a30fa24528ba2417d2a0c82f2c67b62e7f912089235028@buzz.block.builderlab.xyz> |
||
|
Tom Brow
|
99e65b6c22 |
perf(mobile): read channel bot roles from the member list (#9451)
Every channel view read the channel's member roster (kind 39002) twice: once for the member list (`channelMembersProvider`) and once for bot roles (`channelBotPubkeysProvider`, which feeds agent mention styling). Both sent the same `kinds:[39002] #d:[channel] limit:1` query, and both re-ran it on every roster update. Screens that show messages from several channels did this per channel: opening Activity read 10 rosters twice each. Bot roles now come from `channelMembersProvider`, so each channel's roster is fetched once. While the relay is disconnected, bot roles now come from the member list's last loaded roster instead of going empty, so agent mentions keep their styling offline. ### Validation New test: watching both the member list and bot roles for a channel fetches the roster once and both report the bot. It fails without this change (two fetches). The existing bot-role tests (live updates, subscription cleanup, working bots) pass unchanged. The channel page test for a bot-role replay used a fixed member list alongside live bot roles, which can no longer differ; it now reads both from its fake relay. Full mobile test suite and `flutter analyze` pass. On an iPhone 12 mini signed in to Block's Builderlab (instrumented profile build), opening Activity right after launch read 10 channel rosters once each (25.7 KB) instead of twice (51.5 KB), and opening a channel read its roster once instead of twice. Agent messages kept their agent styling. The same automated run covered cold start, opening and scrolling Activity, scrolling the home list, opening buzz-mobile-tomb-review (a channel with agent members) and returning home. ### Regressions None expected. Bot roles now refresh when the member list does (on roster updates and after a reconnect) rather than on every relay session state change, which only drops redundant refetches. Signed-off-by: Tom Brow <tomb@squareup.com> Co-authored-by: Tom Brow <tomb@squareup.com> Co-authored-by: studio <dc2fc481343672df31a689840c09299972e704dac592e0da6f18486646a7ee3e@buzz.block.builderlab.xyz> |
||
|
Tom Brow
|
3dcdf1c056 |
perf(mobile): read Activity once per reconnect (#9455)
Activity watched the whole relay session state, so it rebuilt, and downloaded its whole feed again, for every socket state on the way back from a reconnect: disconnected, reconnecting (once per attempt) and connected. Only the last of those reads could subscribe live; the others were thrown away. On an iPhone 12 mini signed in to Builderlab, every resume after the background grace period read the 25 KB feed three times. Activity now reads again once per new connection, the way the profile provider already does: it listens for the session becoming connected and rebuilds then. Losing the connection no longer rebuilds it, so the feed it already shows stays until the reconnect read replaces it. ### Validation New test: a disconnected, two reconnecting and a connected state read the feed once. It fails without this change (four reads). Full mobile test suite and `flutter analyze` pass. On the iPhone 12 mini (profile build with this change, signed in to Builderlab), 60 s in the background, then the first 20 s after resuming: | | Activity feed reads | Bytes | | --- | --- | --- | | Before | 3 | 74.8 KB | | After | 1 | 25.0 KB | After the resume, Activity's live subscriptions opened again, and opening Activity showed the mention posted just before the resume. The automated run covered a cold start, the home list, a 60 s background, the resume and opening Activity. ### Regressions - While the relay is unreachable, Activity keeps showing the feed it last read instead of reading over HTTP on each socket state. Once the socket connects again it reads and subscribes as before. Signed-off-by: Tom Brow <tomb@squareup.com> Co-authored-by: Tom Brow <tomb@squareup.com> Co-authored-by: studio <dc2fc481343672df31a689840c09299972e704dac592e0da6f18486646a7ee3e@buzz.block.builderlab.xyz> |
||
|
Tom Brow
|
04af7081c8 |
fix(mobile): offer role controls for agents (#9475)
Mobile hides every role control for a channel member whose role is
`bot`. On relays running [#8494 bot role from
owner](https://github.com/block/buzz/pull/8494), any agent with a
recorded owner is reported as `bot` whenever it holds an ordinary role.
So if an admin demotes an owned agent from admin to member, the
refreshed roster says `bot` and mobile no longer offers "Make channel
admin": the demotion can't be undone from mobile.

This change gives agents the same role controls as people, matching
desktop:

- The member profile actions offer "Make channel admin" for `bot`
members. "Change to member" still appears only for admins and guests, so
an agent that is already ordinary isn't offered it.
- The members sheet shows the Role selector for agents, with Member
selected for `bot` (the two are permission-equivalent). The row label
still reads "Agent".

**Rollout:** ship this in a mobile release before relays with #8494
deploy.

Review discussion: [buzz-mobile-tomb-review-work
thread](buzz://message?channel=95213a25-483a-458b-9bc3-71891fa5aef6&id=4714950ee67bf04464a59c1deb3470972c0809c7be780183da6b4a2e77243714).

### Regressions

None expected. The relay already accepts admin, member and guest for
agents (owned agents can hold admin today), so the newly shown actions
submit role changes it accepts. On current relays an agent added as
`bot` now also shows these controls; tapping Member on its selector is a
no-op because Member is already selected.

### Validation

Changed tests: the profile-actions role table now expects "Make channel
admin" for `bot`; the promote, demote journey continues with the
refreshed role coming back as `bot` and expects promotion to be offered
again; the members-sheet agent row expects the Role selector with Member
selected.

Full mobile suite: 4,828 passed, 70 skipped, 1 failed. The failure,
`video_controls_test.dart` "iOS timeline requests native Liquid Glass
and fades with the toolbar", is unrelated media-viewer code; it passed
when rerun on its own, and the pre-push hook's full mobile run passed.

Simulator check against a live relay: an agent added with the `bot`
role, viewed by the channel owner in its member profile.

| Before | After |
| --- | --- |
| <img alt="before"
src="https://github.com/user-attachments/assets/2503ae98-b198-46c3-85c9-0b85dae2c4ae"
width="300"> | <img alt="after"
src="https://github.com/user-attachments/assets/82abf55a-de56-45aa-86c5-7917877e388e"
width="300"> |

Signed-off-by: Tom Brow <tomb@squareup.com>
Co-authored-by: Tom Brow <tomb@squareup.com>
Co-authored-by: studio <dc2fc481343672df31a689840c09299972e704dac592e0da6f18486646a7ee3e@buzz.block.builderlab.xyz>
mobile-v1.2.0-rc.1 |
||
|
Tom Brow
|
b6db61faa0 |
perf(mobile): stop rebuilding the native nav bar on every scrolled frame (#9458)
On iOS, `FrostedAppBar` built its native `IosNavigationBar` inside the `ValueListenableBuilder` for the page's scroll offset, so every scrolled frame rebuilt the bar. Each rebuild `jsonEncode`s the whole native payload to see whether it changed, and that payload carries the header's avatars: base64 image data, and the data URLs of people whose profile picture is one (100 KB or more each). The bar already follows the offset itself, through its own listener that sends `scroll` to UIKit, so none of that work was needed. The bar is now built once per `FrostedAppBar` build, outside the offset builder. Scrolling still rebuilds the positioned frame around it (its height follows the large title), but passes the same bar widget, so Flutter skips it. ### Validation New test: scrolling a `FrostedScaffold` page leaves the same `IosNavigationBar` instance in the tree. It fails without this change. Full mobile test suite, `flutter analyze` and the file-size check pass. On the iPhone 12 mini (profile build, Builderlab), opening a busy channel whose header shows member avatars, and scrolling history with 10 swipes (about 30 seconds): | | `IosNavigationBar.build` (CPU samples) | BUILD total | LAYOUT total | UI frame time total | | --- | --- | --- | --- | --- | | Before | 1,581 ms | 3,304 ms | 3,514 ms | 7,013 ms | | After | 0 ms (no samples) | 591 ms | 748 ms | 4,718 ms | The remaining long frames (up to 130 ms) are older history loading in, and are the same before and after. The automated run covered a cold start, search, opening the channel from a search result, and scrolling its history. ### Regressions None expected. The bar's inputs don't depend on the offset; only the frame's height and animation duration do, and those still update per frame. Signed-off-by: Tom Brow <tomb@squareup.com> Co-authored-by: Tom Brow <tomb@squareup.com> Co-authored-by: studio <dc2fc481343672df31a689840c09299972e704dac592e0da6f18486646a7ee3e@buzz.block.builderlab.xyz> |
||
|
Tom Brow
|
93bbd452a7 |
perf(mobile): keep verified-name batches open as people are added (#9450)
Verified names are read in subscriptions of up to 128 people. Each time
someone new was tracked, the batches were rebuilt from the whole tracked
list, so the last partial batch got a new identity, was closed, and was
reopened with everyone in it plus the newcomer. Profiles show up a few
at a time (search results, channel members, mentions), so the same
records were read again and again. Past 1,024 tracked people, each
newcomer evicts the oldest, which shifts every batch boundary, so every
batch was closed and all 1,024 records were read again.
Now an open batch stays open as long as all its people are still
tracked. Newly tracked people get a batch of their own. A batch that
loses someone to eviction, or that the relay retried, is replaced as
before, and so is a batch whose person was evicted and tracked again
before the batch was re-checked, so their check mark and cached name are
re-read. Once four batches are smaller than 128, the next addition
merges the smallest of them with the newcomers until they fill a batch
(at least one, so no fifth small batch appears). The subscription count
stays within four of the minimum, and a merge re-reads at most 128 plus
the largest small batch.
People already checked also stay checked while a newcomer's batch opens;
before, the reopened batch briefly unchecked them.
### Validation
New tests: tracking one more person opens a batch with only that person,
and the people already checked stay checked throughout; with four small
batches of 64 open, one more person merges two of them into a full batch
and leaves the other two open; a large addition past four small batches
still retires one; tracking one more person at the 1,024 limit re-reads
only the batch that lost the oldest person; a person evicted and tracked
again before the sync is re-read and checked; and a re-tracked person
keeps their verified name when the cached-name limit trims it. Existing
batch, eviction, retry and reconnect tests pass unchanged (one comment
updated). Full mobile test suite and `flutter analyze` pass.
On an iPhone 12 mini signed in to Block's Builderlab (instrumented
profile build of
|
||
|
Tom Brow
|
9fc2b33320 |
perf(mobile): read only changed custom emoji sets on reconnect (#9446)
Once anything has read the custom emoji palette (opening any channel does), every reconnect refetches every member's kind 30030 emoji set. On Block's Builderlab that is 123 sets, about 1 MB, on every resume, though the sets rarely change. The provider also watched the whole session state, not just its status. The palette now keeps the sets it has read per author and, on a reconnect, asks only for sets written since shortly before the previous read (`since` reaching back `relayCrossDeviceSkewSeconds`, the window the unread catch-up already uses for events other devices write). A newer set replaces the known one for its author, with the relay's order for a same-second tie (the lower event id wins); the palette is the union as before, recomputed only when a set changes, so a reconnect that brings nothing new republishes the identical list and rebuilds nothing. A community or account switch (a new relay client) starts over with a full read. Two side benefits: the loaded palette stays visible while disconnected (before, it was empty until the full read finished, so `:shortcode:`s in visible messages briefly showed as text on resume), and the palette no longer refetches on every reconnect attempt during backoff, only on status changes. ### Validation Added test: the first read has no `since`; a reconnect with nothing new sends a `since` and keeps the palette as the identical list; a new member's set and a replaced set both arrive in the window and update it; a same-second replacement wins with a lower id and is ignored with a higher one. It fails without this change. Existing emoji picker tests pass; full mobile test suite and `flutter analyze` pass. On an iPhone 12 mini signed in to Block's Builderlab (instrumented profile build): after opening a channel, a resume after 60 s in the background downloaded the 1 MB of sets again (kind 30030, 123 events). With this change the same resume sent the read with a `since` and got no events back, so the 1 MB was not downloaded again; the first read when opening the channel is unchanged (123 sets, 1 MB). ### Regressions A set removed with a NIP-09 deletion (rather than replaced) stays in the palette until the app restarts, since a deletion isn't a newer set. Buzz clients edit a set by replacing it (desktop removes a shortcode by republishing the set), so that only affects other clients, and desktop's emoji directory keeps deleted sets the same way. A set written by a device whose clock is more than 30 minutes behind is missed until restart, the same bound the unread catch-up accepts. --------- Signed-off-by: Tom Brow <tomb@squareup.com> Co-authored-by: Tom Brow <tomb@squareup.com> Co-authored-by: studio <dc2fc481343672df31a689840c09299972e704dac592e0da6f18486646a7ee3e@localhost> |
||
|
Tom Brow
|
237a39fe76 |
perf(mobile): keep latest-message times on a directory load (#9457)
Opening search loads the channel directory when it is older than 30 seconds. That load reruns the whole channel list read, including each channel's latest messages (up to 20 per channel, 1 per DM), even though the list is already showing and its live subscriptions keep those times current. On an iPhone 12 mini signed in to Block's Builderlab, the latest-message part was about 700 KB of every search open. A directory load now skips the latest-message read when a channel list is already loaded and keeps the loaded times, the same as the background list reads already do. The first load, when no list is showing yet, still reads them. Both reads still fetch latest messages for member channels the list did not already show (for example a DM opened on another device), so those get a time instead of sorting last in Recent; before, background list reads left them without one. If that read hits the relay deadline, the list is marked for a full read and retried with backoff, as a timed-out full read was before. ### Validation New test: with a loaded list, a directory load sends no latest-message requests, adds the directory channel and keeps the member channel's latest-message time. It fails without this change. A second test: a DM first listed by a directory load, holding only our own message (which unread catch-up skips), gets its latest-message time. It fails without the newly-listed read. Its deadline row (the read that first lists the DM times out) checks that the backoff retry dates the DM; it fails if either the revalidation flag or the retry is removed. Full mobile test suite, `flutter analyze` and the file-size check pass. To stay under the 1200-line limit, `_advanceLastMessageAt` moved unchanged into `channel_unread_catch_up.dart`. On the iPhone 12 mini (profile build, signed in to Builderlab), opening search 90 seconds after a cold start and typing "buzz": | | Latest messages | All relay HTTP | | --- | --- | --- | | Before | 704 KB | 3.56 MB | | After | 0 | 2.86 MB | The automated run covered a cold start, the home list, opening search, channel results for the query, and closing search back to the home list with the same order. ### Regressions - A directory load with a loaded list no longer refreshes cached DM display names; the next full list read (pull to refresh, cold start, or a channel action) still does, as for background list reads. - A latest-message time the live subscriptions missed (for example while the socket was down) is not corrected by opening search; the next full list read corrects it. --------- Signed-off-by: Tom Brow <tomb@squareup.com> Co-authored-by: Tom Brow <tomb@squareup.com> Co-authored-by: studio <dc2fc481343672df31a689840c09299972e704dac592e0da6f18486646a7ee3e@buzz.block.builderlab.xyz> |
||
|
Tom Brow
|
a540e7bd30 |
perf(mobile): don't refetch profiles that are already on the wire (#9447)
`UserCacheNotifier.preload` skipped profiles already queued but not ones already on the wire. Opening a channel preloads the same people from several places (compose bar, DM header, member list); a preload that arrives while the first batch is in flight queues those people again, and the next batch downloads their profiles a second time. On Block's Builderlab, opening one channel sent the same 77-author kind 0 request twice, 521 KB each. A preload now leaves out profiles whose batch is in flight and waits for that batch instead. Only profiles that are neither cached, queued nor in flight start a new batch. ### Validation Added test: while a batch for `a` and `b` is on the wire, preloads for `b` and for `b, c` send one more request, for `c` only, and all three preloads complete once their profiles arrive. It fails without this change (the second request asks for `b` again). Existing user cache tests pass; full mobile test suite and `flutter analyze` pass. On an iPhone 12 mini signed in to Block's Builderlab (instrumented profile build), opening two channels in a row: before this change the second channel downloaded its 77 members' profiles twice (1,019 KB of kind 0 events), and the first downloaded its 43 twice (50 KB). With it, each downloaded them once: 509 KB and 25 KB. ### Regressions None expected. A caller whose profiles are in flight now waits for that batch instead of a new one, so it resolves no later than before; a failed in-flight batch reports failure to it, as its own batch would have. --------- Signed-off-by: Tom Brow <tomb@squareup.com> Co-authored-by: Tom Brow <tomb@squareup.com> Co-authored-by: studio <dc2fc481343672df31a689840c09299972e704dac592e0da6f18486646a7ee3e@localhost> |
||
|
Tom Brow
|
d1a8c3607d |
perf(mobile): use HTTP/2 on Android through app-wide Cronet engines (#9435)
Follows #8897 (iOS HTTP/2), now on main. ## What Android gets the same app-wide shared sessions as iOS, backed by Cronet (`cronet_http`) instead of `NSURLSession`: - One Cronet engine per traffic class (API, media), so requests to a host multiplex over one HTTP/2 connection and gzip is inflated natively, off the Dart isolate. - HTTP/2 on, HTTP cache off, QUIC off. QUIC would be a separate behavior change, and `cronet_http`'s changelog lists DNS failures with QUIC on cellular. - Streamed uploads (media and voice notes) stay on `dart:io` on Android: `CronetClient` reads a request body into memory before sending it, which would break upload progress and copy large attachments in full. - If no Cronet provider is available (no Google Play services), the engine fails to build and the app keeps `dart:io`, as today. - Transport error classification covers Cronet failures alongside `NSURLSession` ones, so invite and pairing errors keep their friendly messages. ## Measurements Android emulator (API 36, arm64), profile builds of this branch and main, signed in to the Feedback community. 8 cold starts per build, alternating builds in blocks of 4. Times are for relay `/query` requests started in the first 8 s. | | main (`dart:io`) | this branch (Cronet) | |---|---|---| | First query response | 6.99 s | 1.99 s | | Startup burst settled | 8.36 s | 2.78 s | | Burst after the first connection | 1.44 s | 0.77 s | | Query latency after the first connection, median / p90 | 165 / 1567 ms | 106 / 158 ms | **Unexplained stall:** most of main's startup gap is a ~5 s stall before its first response on every cold start. Its cause is unconfirmed; my guess is `dart:io` loading its CA store on the emulator, which HTTP/2 itself wouldn't fix, so the first two rows likely overstate the win on real devices. The rows after the first connection exclude the stall and are the fairer comparison. I also tried emulated EDGE throttling, but the emulator's throttle did not slow its traffic, so there are no slow-link numbers yet. ## Regressions None found. Devices without Play services keep `dart:io`. Cleartext `http://` requests keep the handle's own `dart:io` client, as on iOS. ## Testing - Full mobile suite passes (`flutter test`, 4784 tests). - Automated app run on the emulator: onboarding, Feedback nsec import, channel and DM list load, and 16 cold starts with request timing. Media loading wasn't separately exercised. - No visible UI change, so no screenshots. --------- Signed-off-by: Tom Brow <tomb@squareup.com> Co-authored-by: Tom Brow <tomb@squareup.com> |
||
|
Tom Brow
|
36fa0fe318 |
perf(mobile): subscribe to presence only for people on screen (#9444)
The mobile app subscribed to every presence event in the community, though it only shows presence for people on screen. It now subscribes only to the people it tracks. ### Validation **Impact:** on an iPhone 12 mini signed in to Block's Builderlab, 5 minutes idle on Messages: | | Presence downloaded | All WebSocket traffic | | --- | --- | --- | | Before | 2.9 MB (8153 events) | 3.1 MB | | After | 3.6 KB (10 events) | 66 KB | That's about 35 MB per hour saved at Builderlab's presence rate (about 27 events per second). Measured on an instrumented profile build of the first revision, [ |
||
|
Ian Oberst
|
359839f70b |
feat(db): label advisory-lock metrics with the locked event kind (#9472)
## Why

On one deployment,
`buzz_db_advisory_lock_wait_seconds{lock_type="replacement"}` added up
to about 245,000 seconds of wait in 7 days. The metric cannot say which
coordinates wait. Replacement locks serialize writers of one `(kind,
pubkey[, d_tag | channel])` coordinate. Relay-owned lists (kinds 13535,
39000–39002) go through the same generic replacement paths as user
replaceables (kinds 0, 3, 10002, 30078, …). The 13534 membership list
takes its coordinate lock under `lock_type="membership"`. Before we
change how these lists are stored, we need to know which kinds the wait
comes from.

## What

- `buzz_db_advisory_lock_wait_seconds` and
`buzz_db_advisory_lock_acquisitions_total` get a `kind` label.
- Locks keyed by an event coordinate record that coordinate's kind,
through the new `observe_event_lock(lock_type, kind, …)`. This covers
all 4 replacement call sites (parameterized replace,
`take_replacement_lock` for addressable replace and group-state
snapshots, the kind:39002 member snapshot, and workflow deletion) and
the kind:13534 membership-list lock. The 13534 lock keeps
`lock_type="membership"`, so totals by `lock_type` do not change.
- All other locks record `kind="none"`, and their call sites do not
change. `observe_advisory_lock` has a `debug_assert` that rejects
`LockType::Replacement`, so a replacement lock cannot lose its kind by
mistake.
- `buzz_core::kind::registered_kind_label(kind)` gives the label value:
the decimal kind when it is in `ALL_KINDS`, otherwise `other`.

## Change to the #6700 label contract

#6700 says no database metric carries event kinds, and
`observability_source.rs` enforces this with a blanket ban on `"kind"
=>`. This PR makes one narrow exception: the two advisory-lock metrics.

- **Bounded:** the value set is the kind registry, not request data. Of
the 135 registered kinds, 39 are replaceable or addressable and can
reach a replacement lock. Any other kind a client sends becomes `other`.
Non-replacement locks are always `none`. New series in the worst case:
39 kinds × 4 outcomes, for the histogram and the counter.
- **Not sensitive:** no community, pubkey, coordinate, or d-tag is
attached. The kind of a replacement lock does not expose any of those.
- **The guard is narrowed, not removed:** `"kind" =>` must appear
exactly twice, inside the advisory-lock observer `observe_lock`, whose
kind must come from `registered_kind_label` inside `observe_event_lock`.
It is still forbidden everywhere else in `observability.rs` and in the
datastore tracing macro. The #7195 guard that forbids a literal
`"other"` in `observability.rs` is unchanged, because the fallback lives
in `buzz-core`.

## Dashboards and alerts

Both metrics gain a label, so existing selectors keep working:
`lock_type="replacement"` still matches every replacement series,
because Prometheus and Datadog selectors match on a subset of labels. A
consumer is affected only if it depends on the exact label set:

- Recording rules or panels that read a series without aggregating it
now get one series per kind. Aggregate with `sum by (lock_type, outcome)
(...)` to keep the old shape.
- Vector matching with `on(lock_type, outcome)` or `ignoring(...)` now
has more series on one side. Aggregate before the join.

To read the new attribution, group by `kind`, for example `sum by
(lock_type, kind) (rate(buzz_db_advisory_lock_wait_seconds_sum[5m]))`.
No consumer in this repository depends on the exact label set.

## Tests

- `buzz-core`: `registered_kind_label_bounds_unregistered_kinds` checks
that a registered kind passes through and that an unregistered or
negative kind becomes `other`.
- `buzz-db` recorder test: checks the replacement series for a
registered kind (`13534`) and an unregistered kind (`other`), and the
`kind="none"` series for a membership lock, on both metrics.
- `kindless_observer_rejects_replacement_locks`: the `debug_assert`
guard panics.
- `membership_list_lock_records_the_roster_kind` (Postgres): a 13534
list write records exactly one `membership` acquisition with
`kind="13534"`.
- `group_state_replacement_takes_its_lock_once` (Postgres): now counts
acquisitions only under the written kind. It expects `kind="39000"` for
the group-state snapshot path and `kind="0"` for
`replace_addressable_event`, so if `take_replacement_lock` drops or
swaps the kind, the count becomes 0 and the test fails.
- `observability_source.rs`: the narrowed guard described above.

Commands run:

- `cargo clippy --workspace --all-targets -- -D warnings`
- `cargo test -p buzz-core --lib`
- `cargo test -p buzz-db --lib`
- `cargo test -p buzz-db --test observability_source`
- `scripts/postgres-test-run.sh -p buzz-db --lib --tests` (the CI
PostgreSQL lane, run locally)

## Local relay check

The relay ran from this branch against an isolated database. `/metrics`
showed one series per locked kind after each write:

- `users set-profile`: `replacement`, `kind="0"`
- `users set-status`: `replacement`, `kind="30315"`
- `channels create`: `replacement`, `kind="39000"`, `"39001"`, `"39002"`
- `channels add-member`: `replacement`, `kind="39002"`
- `agents archive`: `replacement`, `kind="13535"`
- `moderation ban`: `replacement`, `kind="30622"`, plus `membership`,
`kind="none"`
- Invite mint and claim
(`e2e_relay::test_invite_mint_and_claim_admits_new_pubkey`):
`membership`, `kind="13534"`
- Background loops: `deletion` and `partition_maintenance`,
`kind="none"`

`buzz_db_advisory_lock_wait_seconds_count` matched
`buzz_db_advisory_lock_acquisitions_total` for every series. The author
also tested it against the local relay.

buzz-review-completed

🤖 Generated with [Claude Code](https://claude.com/claude-code)

Signed-off-by: Ian Oberst <ioberst@block.xyz>
Co-authored-by: Ian Oberst <ioberst@block.xyz>
Co-authored-by: Claude Opus 5.5 <noreply@anthropic.com>
|
||
|
Wes
|
59ae028a36 |
fix(mobile): require Builderlab consent for existing identities (#8823)
Existing mobile identities entering the Builderlab hosted flow now require confirmation before the app reserves the account’s identity slot, binds the identity, or uploads its secret key. Cancelling leaves saved community keys usable and allows another identity to be selected, including after restart. Imported keys remain tentative until approval; paired keys remain safely retained outside the account slot. The confirmation shows the receiving account’s verified email and public key, explains that Builderlab can decrypt the backup and signed-in account users can recover it, and discloses that the app cannot change the linked identity later. **Cancel setup** stops future work without claiming to undo earlier binding or an upload whose acknowledgement was lost. The user can sign out; missing account identification blocks confirmation. Browser-initiated binding uses **Link and continue**, with explicit bind-only wording and no upload. Fresh keys generated in the current hosted attempt use ordinary onboarding without an extra backup prompt. Interrupted attempts without a confirmed backup ask again; approval is deliberately not persisted or carried across retries, cancellation, restart, account changes, or a replaced flow. Confirmed matching backup receipts skip the backup prompt. Cloud recovery and organization-managed backup are separate flows and are not changed here; this PR does not resolve server-side consent or recovery-authorization policy. Updated against main through `ce42853982` (#9418). Integration commit `dfb29fe5e7` includes the landed Hickory security fix and the shared workflow-test/runner repair. The consent implementation is unchanged from Carl’s reviewed `e11025ebed`; the CI merge preserves its configured public consent journeys. Validation at `e11025ebed`: 96 focused tests across eight files passed with public hosted domains configured; Flutter analysis passed. In an isolated source/Git/build copy, removing pre-adoption consent, bypassing the upload gate, and removing stale-confirmation checks each failed the consent journeys; restoring the code passed. Carl’s independent source review found no blockers. Mandatory hooks and hosted mobile CI passed, including both consent journeys in the configured public lane. Integration validation at `dfb29fe5e7`: 99 focused tests passed; one additional fullscreen-onboarding test failed its background community-admission assertion. An isolated clean-main control at `ce42853982` reproduces the same failure with the same expected/actual values. All consent journeys passed. Required commit and push hooks passed, including mobile analysis and the broader default mobile suite. Hosted CI is green at `dfb29fe5e7` ([run 43320753801](https://github.com/block/buzz/actions/runs/43320753801)). Security and the previously failing Rust/workflow gates now pass. The Mobile Checks log confirms both consent journeys executed successfully; that run has no pending checks. Review follow-up `ac9ac9be35`, integrated with main `279a31daac` at current head `1acfd2dff6`, is test-only: the browser journey now restores a saved account key without a receipt, cancels without binding, restarts and requires explicit approval before `/verify`. Both consent journeys passed again after integration using the updated CI settings. Disabling only the production bind gate in an isolated source/Git/build copy now fails the added step; restoring it passes. Mandatory commit/push hooks passed. Hosted CI is green at `1acfd2dff6` ([run 43343333843](https://github.com/block/buzz/actions/runs/43343333843)); no failing or pending checks remain. The Mobile Checks log confirms both consent journeys executed successfully, including the extended browser-binding journey. Carl’s latest review on `dfb29fe5e7` found no production blockers; its recommended test gap is addressed by this follow-up. Native-device and human acceptance have not been recorded here; the author’s ready-for-review setting is preserved. Try it: with two saved self-hosted keys, connect to Builderlab, select A, cancel, restart, then select B. Check the receiving account and key before approval. Repeat with an imported/paired key and a browser bind link; cancel must not reserve or bind the new selection. After an interrupted upload, cancellation must describe that earlier effects may remain. Confirm that ordinary brand-new onboarding has no extra backup step. --------- Signed-off-by: Wes <wesbillman@users.noreply.github.com> Co-authored-by: Brain <1a02c72794dcd0f07058a353bc3a81f4028b8c77c92c87fce6d5c8b85970a20b@buzz.block.builderlab.xyz> |
||
|
Tom Brow
|
a2d4ba0267 |
feat(mobile): use HTTP/2 on iOS through app-wide URLSessions (#8897)
On iOS, Buzz's HTTP traffic now uses HTTP/2. Dart's `dart:io` client speaks only HTTP/1.1, so every feature's client opened its own connections to the relay, which sits behind Cloudflare and offers HTTP/2. On a slow link those extra handshakes, and the HTTP/1.1 head-of-line queueing, are a large share of cold-start time. ### What changes - iOS HTTP goes through two app-wide `NSURLSession`s via [cupertino_http](https://pub.dev/packages/cupertino_http) (`lib/shared/http/app_http_client.dart`): one for API traffic (relay queries, NIP-11, account, admission, pairing) and one for media (image/video/voice downloads and uploads). Requests to a host multiplex over one connection per session. Media has its own session so image bytes can't starve queries on a shared HTTP/2 connection: in prototype measurements with a single shared session, the channel-list batch query finished *later* than on HTTP/1.1. - Callers keep owning and closing their clients; on iOS `close()` leaves the shared session open. Both sessions are ephemeral with no URL cache and no cookies, so apart from the protocol (and native gzip, inflated off the Dart isolate) behavior matches `dart:io`. - Android, and tests, keep `http.Client()` unchanged, including `http.runWithClient` overrides. - Because closing a client no longer cancels a request on a shared session, the relay query client (both `/query` posts and bounded snapshot reads) and the dev push-lease fetch abort their request on timeout instead. - Non-`https` requests (`http://` media and community icons from other clients, local dev relays) stay on the handle's own `dart:io` client, because App Transport Security would block cleartext loads through URLSession. An HTTPS URL that redirects to `http://` is the one case that newly fails on iOS (URLSession follows the redirect and ATS blocks the downgrade); we accept that rather than follow redirects in Dart. - URLSession failures arrive as `NSErrorClientException`, not `SocketException`, so pairing and invite-join error messages now also recognize `NSURLErrorDomain` offline, TLS and timeout codes. - cupertino_http 3.0.1+ requires native_toolchain_c 0.19 and hooks 2.x, so `buzz_secp256k1` moves to those. Its build hook compiles unchanged. ### What gets better, and what doesn't get worse - **Better:** on a slow link, requests reuse one warm connection per session instead of paying TCP+TLS setup each time, so they complete where `main` times out (see the table). On Wi-Fi, small queries are slightly faster. - **Not worse:** request semantics, caching (none) and cookies (none) match `dart:io`; Android and tests are untouched; timed-out requests are aborted so they can't keep using bandwidth on the shared connection; offline errors keep their friendly messages. The accepted regression is HTTPS-to-HTTP redirects on iOS, above. WebSockets stay on `dart:io`. Android (Cronet) is a possible follow-up using the same seam. ### Validation Added tests: shared-session handles don't close the session; off iOS the transport honors `http.runWithClient`; NSURLError code classification; timed-out relay queries and bounded snapshot reads abort their request; cleartext requests stay off the shared session. Focused existing validation: full mobile suite (the only failures are 11 push/notification tests that fail identically on `main` on the same machine), `flutter analyze`, `buzz_secp256k1` package tests (27/27), and an iOS release build. On-device A/B on an iPhone 12 mini against the internal prod relay over WARP, comparing cold starts of `main` and this branch (profile builds with local-only request timing, 3 cold starts each): | | `main` | this branch | |---|---|---| | Wi-Fi: first query done (median) | 0.31s | 0.25s | | Wi-Fi: small-query latency (median) | 0.22s | 0.18s | | NLC Edge: requests completed in 90s | 0, 0, 0 (29–30 failed) | 12, 14, 16 (5–7 failed) | | NLC Edge: first request done | never | 6.3–7.0s | On Wi-Fi the two are about even. Under Edge, every HTTP/1.1 request on `main` hit its timeout while still opening a connection, and each retry started a fresh TCP+TLS handshake. The branch reuses one connection, so queries complete. Connection counts weren't measured on the device, since no proxy was in the path. Cold-cache demo on an iOS simulator (this branch, app caches and cached prefs wiped before launch): avatars, community icons, channel lists, public channel images, a DM image and custom emoji, video playback, reactions, and an image and video upload with progress all load. The DM image and clip are synthetic test media. https://github.com/user-attachments/assets/039d1a25-46f2-4e0e-b147-f96d0cfabd40 buzz-review-completed (agent review and device validation done; the human-test step is not applicable under Tom's standing exception for mobile changes) --------- Signed-off-by: Tom Brow <tomb@squareup.com> Co-authored-by: Tom Brow <tomb@squareup.com> Co-authored-by: studio <dc2fc481343672df31a689840c09299972e704dac592e0da6f18486646a7ee3e@buzz.block.builderlab.xyz> Co-authored-by: Claude Opus 5.5 <noreply@anthropic.com> |
||
|
Jordan Mecom
|
1fb33e4545 |
fix(relay): publish a git push only when refs changed; check the protocol by refinement (#9425)
## Summary This PR is stacked on #9064. It does two things to the Git-on-object-storage code in `buzz-relay`. It replaces the TLA+ model of the push protocol with one that states what the protocol is supposed to implement and checks that it does. It also changes the rule by which the relay decides whether to publish a push, because the new model shows that the rule #9064 introduces still publishes requests in which git accepted nothing. ### Relationship to #9064 The branch is `main`, then the two commits of #9064, then four commits of this PR: the specification work, the publish-rule change, a review fix merged from #9429, and a fix to `check.sh`. A merge of `main` follows them; it was needed because `main` changed `Justfile`, which #9429 also edits, after the branch point. The first two commits are #9064's, replayed onto current `main` without conflicts and otherwise unchanged. The base of this PR stays `main` because #9064's branch is about 200 commits behind it. Once #9064 merges, this branch can be rebased and the diff shrinks to the last four commits. Until then, review the commits after the first two. This PR keeps two of #9064's three changes as they are: the `published_at` stamp that orders kind:30618 events by the manifest chain, and `protect_landed`, which lets a landed conditional write stand when the serving lease lapses after it. It replaces the third, the publish rule. ### The publish rule #9064 publishes when git exits 0 and the status report has an `ok` line or no `ng` line. That handles a push in which one ref is updated and another refused. The report, however, is not evidence of what git did. - git exits 0 for a request that carries no commands, and for a push the pre-receive hook declined. A decline is reported only to a client that negotiated `report-status`. For a request with no commands, and for a decline when the client did not negotiate a report, there is no `ng` line. The relay then writes the pointer and emits a relay-signed kind:30618 event that names the caller as pusher, although the push policy approved nothing. - The report is read from a stream whose framing the client's capabilities determine, so the decision depends on parsing a client-shaped stream. The decision is now taken from the workspace. `push_disposition` compares the refs after receive-pack with the refs the workspace was hydrated from. Unchanged refs are answered with git's own output and nothing is published. Changed refs are published if git exited normally. Changed refs after an abnormal exit fail the request. The snapshot that is compared is the one `cas_publish` publishes, so git's per-ref report is true of the published state. The status-report scanner and its tests are removed, and the ref-name conflict case they covered moves into the table-driven test described below. Three smaller changes follow. The ref-snapshot parser now fails closed: output that was not UTF-8 used to read as an empty ref set and a malformed line was skipped, and either would publish a manifest that lacks refs. `manifest_changed` in `finalize_push` could not be false and is removed. Taking the snapshot before the publish decision moved its resource-limit error (snapshot larger than 4 MiB, or more refs than a manifest may hold) onto a path that answered 500; #9429 restores the 413 the publish path gave before and adds `snapshot_resource_limit_answers_413`. ### What the specification work adds - `docs/spec/GitRefDB.tla` is the specification: a ref database in which a push takes effect in one step, is applied only if authorized and only against the old values it names, and is reported truthfully. - `docs/spec/GitOnObjectStore.tla` is the protocol: several refs, an object graph with reachability, packs, compaction, the pre-receive hook, the publish decision, the default-branch setter, repository creation, and a reader. `git receive-pack` is represented by a stated contract rather than modeled internally. - The correctness statement is `Refines`: every behavior of the protocol is a behavior of the specification. TLC checks it together with the store invariants (fence, reader completeness, closure of published manifests). - `docs/spec/check.sh` pins TLC 1.7.4 by SHA-256 and runs 28 checks. Eight instances must pass. Nineteen seeded design errors must each be detected with the violation named for them. One coverage check confirms that a behavior the properties depend on (git reporting `ok` for a command that changes nothing) is reachable. A name passed to `check.sh` that is not a check is an error, so a misspelled selection cannot report success. - Both earlier publish rules are among the seeded errors: the original rule (exit 0 and no `ng`) and #9064's status-report rule. For each, TLC reports a publication the policy did not approve (`PublishIsAuthorizedChange`) and a violation of `Refines`. - `docs/spec/GitPushPath.qnt`, the Quint model from #9064 that covers the serving lease and the event timestamps, is extended. The publish rule becomes a parameter with three values, a request may carry no commands or come from a client without a status report, and a new invariant, `publicationChangesRefs`, states that a published manifest differs in its refs from the one it replaces. The implemented rule satisfies all four invariants; the status-report rule violates the new one with a zero-command request. - `docs/spec/lean/GitPointer.lean` is a Lean 4 proof, with no dependencies, of the pointer discipline for any number of clients, refs and objects: the fence, closure, that every pointer change is a legal step from the value it replaces, that the length of the pointer's predecessor chain equals the number of pointer writes, and that a successful conditional write implies no intervening write. - `.github/workflows/spec.yml` runs TLC and Lean when a file under `docs/spec/` changes. On this PR's first run the TLC job took 10 minutes 19 seconds and the Lean job 22 seconds. Quint is not run in CI. - `docs/git-on-object-storage.md` is revised to match. The push listing follows the implemented order. The verification section separates definitions, assumptions, results checked by TLC, results proved in Lean, results checked with Quint, evidence about the implementation, and limitations. The invariant names cited by code comments and by migration 0002 are kept as aliases in the TLA+ module. ### Assumptions and limitations The TLC results hold for the bounded instances in `check.sh`, not for arbitrary sizes. The Lean proof is unbounded but covers the pointer discipline only, not the refinement. The Quint results are from random simulation (2,000,000 runs of at most 14 steps) and a bounded symbolic check (8 steps, Apalache); neither is a proof for unbounded runs. All of them rest on the assumptions named in the document: the object store's conditional-write semantics, ETag equality implying body equality, no SHA-256 collision among the values that occur, the stated contract for `git receive-pack`, and the policy endpoint deciding authorization. The correspondence between the models and the Rust code is established by reading the code and by the tests below; it is not mechanized. The document states one assumption that #9064's ordering fix depends on and that no model covers (Assumption C1). A manifest whose parent carries no `published_at` (the empty manifest written when a repository is announced, or a manifest written before the field existed) is stamped with the writing instance's current time plus one second. Its event is selected over the parent's only if that value exceeds the parent event's `created_at`, which was taken from the clock of the instance that emitted it. This holds when one instance handles both, and otherwise when the writing instance's clock is not behind the other's by more than the time elapsed between the two events. The assumption concerns one write per repository. The document lists its removal as a proposed extension, for example by having the first push after an unstamped manifest read the stored event's `created_at` and exceed it. ### Related issue Related to #2621 (CI for the formal models). This adds the TLC job for the git model and a Lean job; it does not cover the Tamarin models or the NIP-PL scripts, so it should not close that issue. ### Testing Run locally on the restacked branch: - `docs/spec/check.sh`: 28 checks, each with the expected result (8 pass, 19 seeded errors violate the named property, 1 coverage witness reached). About three minutes on 16 cores; the largest instance has 6,773,286 distinct states. - `lake build` in `docs/spec/lean` (Lean 4.33.1): succeeds. The safety theorems depend only on `propext`, `Classical.choice` and `Quot.sound`. - Quint 0.33.0, `GitPushPath.qnt`: `quint run --main fixed --invariant safety --max-steps 14 --max-samples 2000000 --seed 0x1` reports no violation; `quint verify --main fixed --invariant safety --max-steps 8` (Apalache 0.62.1) reports no violation; each single-defect module produces the counterexample the document lists. - `cargo fmt --all -- --check` and `cargo clippy -p buzz-relay --all-targets -- -D warnings`: clean. - `cargo nextest run -p buzz-relay --lib -E 'test(/^api: |
||
|
Evan Broderick
|
642ce4165c |
fix(mobile): show shared chats under Solo (#9348)
## Summary Mobile puts agent-created and shared Solo chats under Team because it checks who created the chat. Show unarchived Solo chats the viewer belongs to under Solo and exclude them from Team. Preserve membership checks, guest read-only access, legacy chats, and owner-only composing. This changes mobile classification; it needs no relay changes or data migration. **Desktop:** <img width="557" height="695" alt="Screenshot 2026-11-11 at 10 00 07 AM" src="https://github.com/user-attachments/assets/d338fa19-7b6f-4b52-a3a6-061025216ed3" /> **Mobile (missing solo chats created by agents):** <img width="423" height="754" alt="Screenshot 2026-11-12 at 11 19 47 AM" src="https://github.com/user-attachments/assets/18b5da75-38e9-4cca-906c-d0a949cc8cbb" /> ### Code Changes Separate Solo list and unread classification from owner-only composing. Add regression coverage for shared and agent-created chats, Team exclusion, membership/archive filters, legacy chats, and ordinary sending from Solo. ### Related issue Related: #8963 adds mobile access controls and Solo sharing. This PR fixes the separate Solo/Team placement mismatch. No duplicate found in searches for mobile Solo issues and PRs. ### Testing Independent agent review found no blockers. Device testing could not be completed. Android emulators stalled at launch, iOS Simulator sign-in was blocked, and iPhone installation required capabilities unavailable to the Personal Team. Shared Solo placement and sending remain unverified in an authenticated app; before/after screenshots remain pending. Remaining manual checks: - Have an agent create a Solo chat and include the viewer as a member. - Confirm it appears once under Solo and is absent from Team. - Open it, send a message, and confirm owner-only Solo settings are absent. Generated with Codex --------- Signed-off-by: Evan Broderick <ebroderick@squareup.com> Signed-off-by: Tom Brow <tomb@squareup.com> Co-authored-by: coder <e509b66797ba43fd355dc12801a0c1ba376b06924147c65abdafa7ababcf8e2e@buzz.block.builderlab.xyz> Co-authored-by: Tom Brow <tomb@block.xyz> Co-authored-by: Tom Brow <tomb@squareup.com> Co-authored-by: studio <dc2fc481343672df31a689840c09299972e704dac592e0da6f18486646a7ee3e@buzz.block.builderlab.xyz> |
||
|
Matt Toohey
|
8436d226c8 |
chore(release): release Buzz Desktop version 0.5.29 (#9456)
## Buzz Desktop release v0.5.29 - **Frozen main:** `41587e0284f277d13e5d3a40b169c1dcd54d2894` - **Reviewed candidate:** `69826ed72499fc3adb49c17a4e63302f4d256e26` - **Previous desktop release:** `desktop-v0.5.28` - **Proposed immutable tag:** `desktop-v0.5.29` This PR may be **squash merged** after the Desktop Release Candidate check and all protected-branch checks pass. Merging authorizes publication of the exact reviewed candidate; later or unrelated changes on `main` cannot alter it. The checked-in changelog accounts for every non-merge commit in the release range. The Desktop tag points to the reviewed candidate commit, not the later squash commit. Publication remains bound to that immutable candidate tag. Signed-off-by: Will Pfleger <wpfleger@block.xyz> Co-authored-by: Will Pfleger <wpfleger@block.xyz> Co-authored-by: Release Automation <release-automation@users.noreply.github.com> |
||
|
Tom Brow
|
41587e0284 |
feat(mobile): render messages with gpt_markdown 1.3.4 plusparse (#8945)
Message Markdown on mobile moves from gpt_markdown 1.2.1's legacy regex
pipeline to the CommonMark parser that 1.3 added ("plusparse"). Before
this, passing `inlineComponents` (now deprecated, removed in 2.0.0) kept
every message on the legacy pipeline.
### What changes for users
Rendering moves closer to desktop (react-markdown + remark-gfm):
- `_italic_` and `__bold__` work, backslash escapes and HTML entities
decode, and `[a [b] c](url)` labels are correct.
- Inline code follows CommonMark pairing: `"```npm install```"` in a
sentence is inline code, and four-backtick fences work.
- Setext headings, reference links, footnotes, `~~~` fences, `1)` lists
and CommonMark list/quote continuation render.
- HTML comments are hidden, as on desktop.
- `\[`, `\]`, `\(` and `\)` stay literal, as on desktop. Plusparse
hard-codes them as LaTeX delimiters, so they're written as entities
before rendering.
- Side effect: an unfenced `__init__` now renders as bold "init", and a
line over `---` becomes a heading, same as desktop.
Device benchmark (iPhone SE, profile build, 600 synthetic messages, 3
launches per build): scrolling spends 9% less time building, and frames
with more than 8 ms of build drop from 63 to 22. Jumping onto unbuilt
messages is 11% cheaper, and raster time is unchanged.
App size: the release app grows about 4.6 MB uncompressed (80.6 to 85.2
MB), mostly Dart code from the new math and highlighting packages.
### Before and after
Synthetic messages that reproduce differences found in real channel
history, rendered through `MessageContent` on main and on this branch:

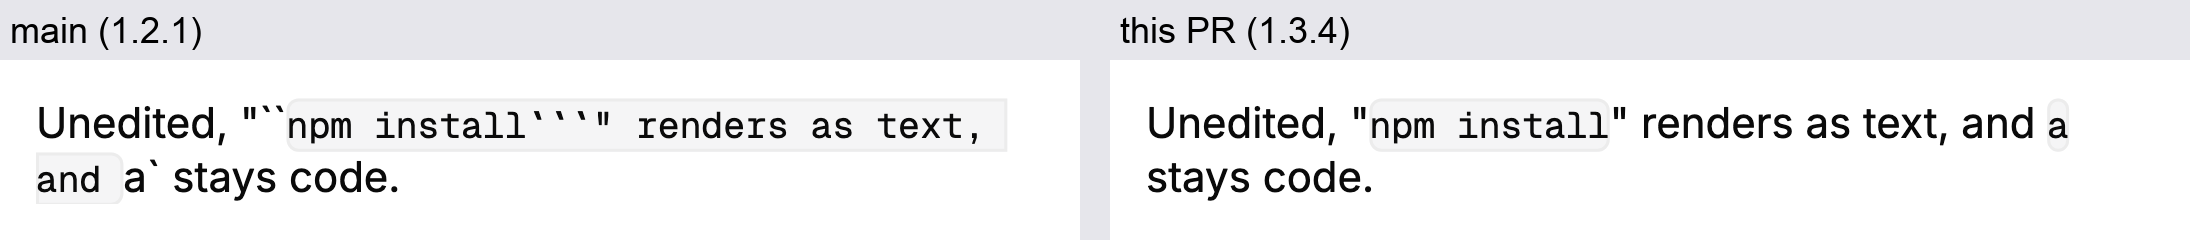
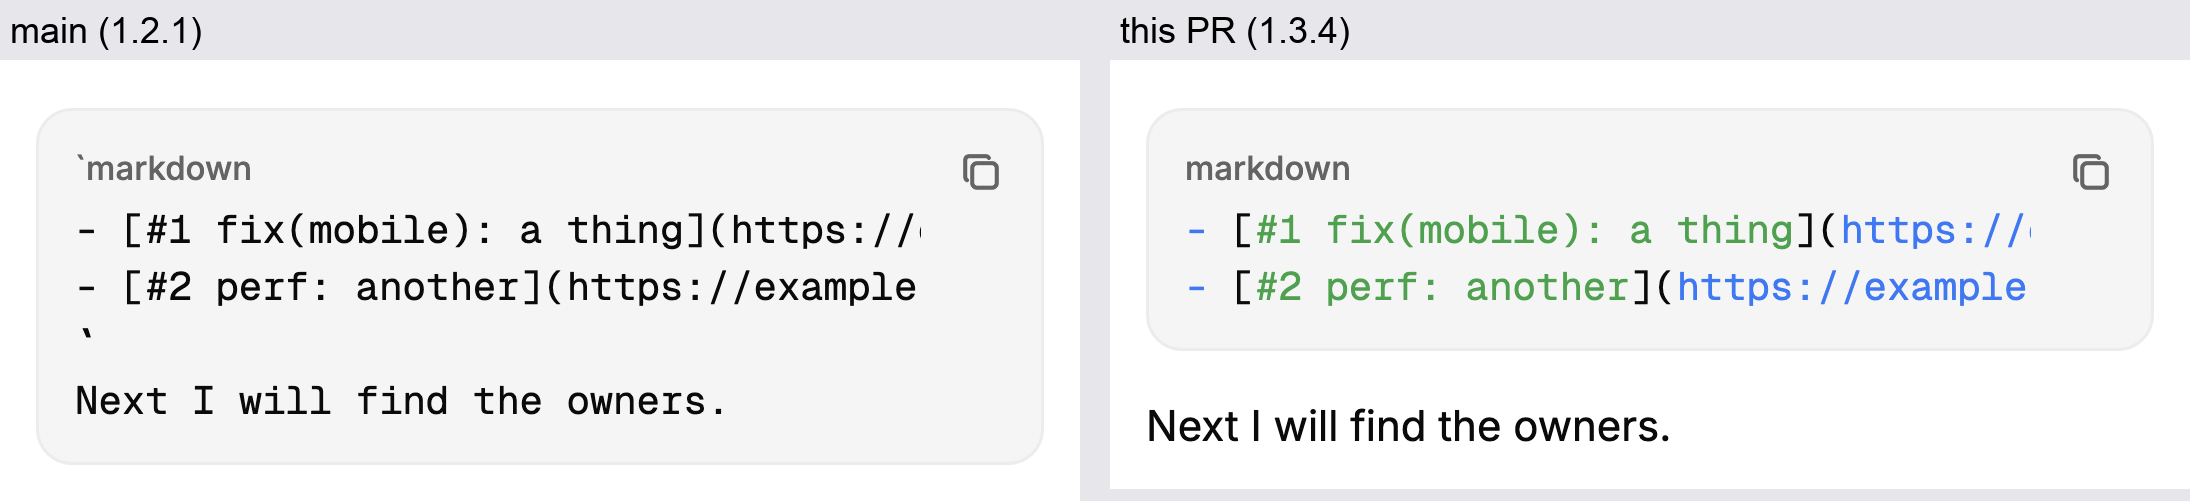
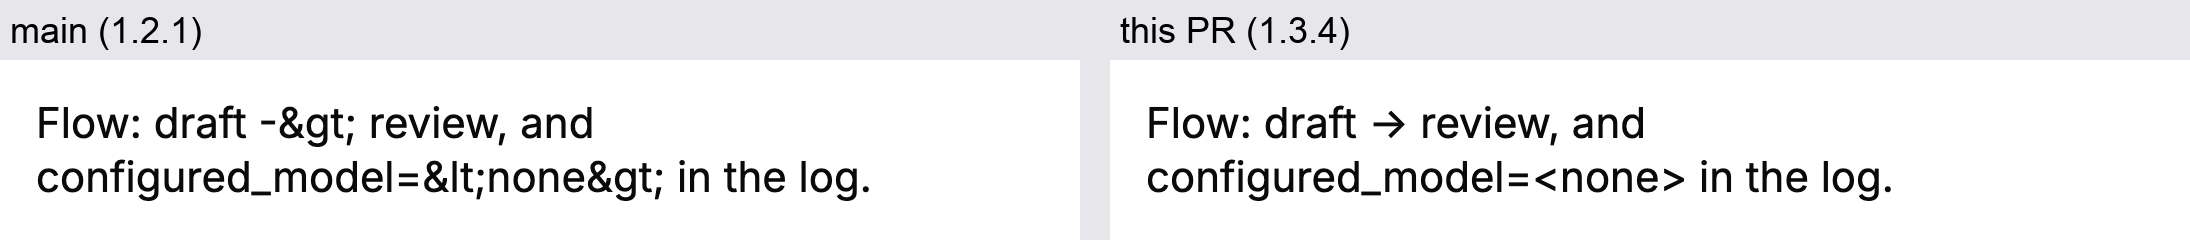
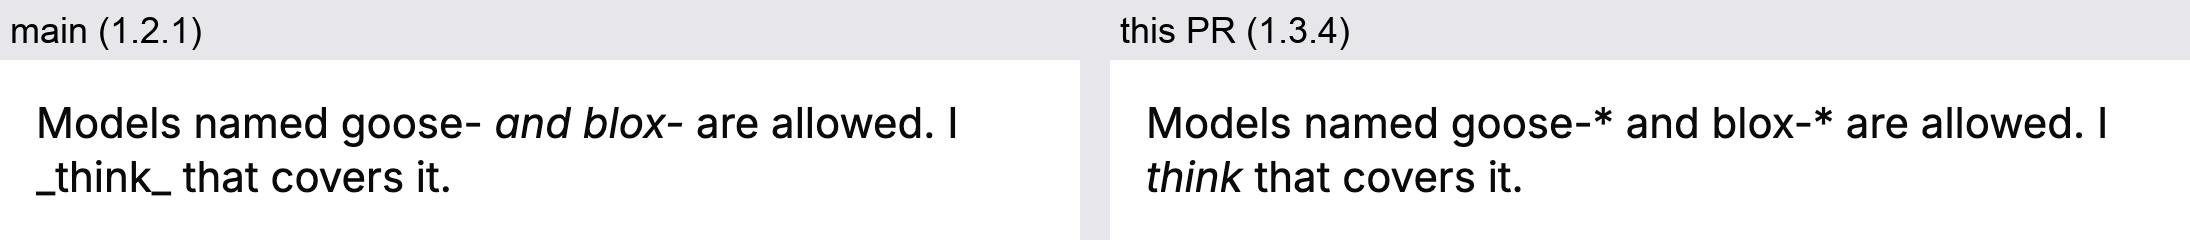
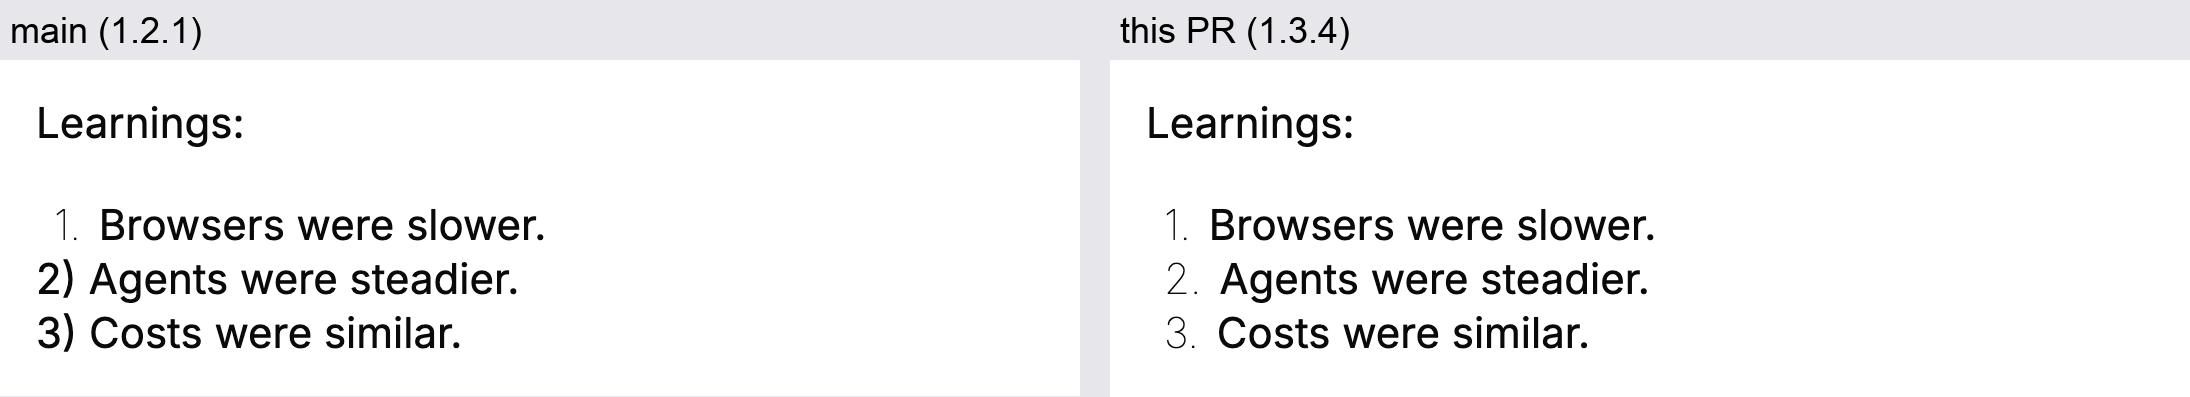
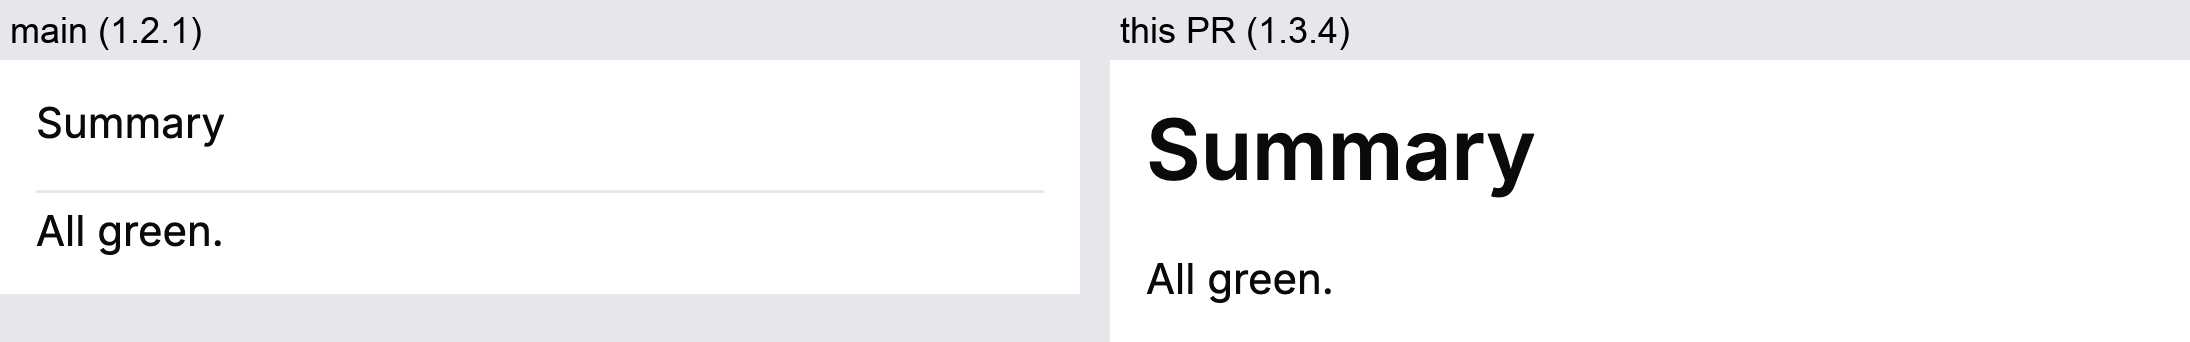

### Demo
A scroll through synthetic messages covering common formatting
(headings, lists, quotes, links, highlighted code, a table, a task list,
escapes), recorded on an iPhone 17 Pro simulator running this branch:
https://github.com/user-attachments/assets/bdc9680c-d20b-41ec-8e1a-a5b51c602f9d
### How
- Mentions, custom emoji and `#channel` tokens are `InlinePattern`s.
Links go through `inlineLinkBuilder` into the existing `_buildLink`, so
chips, media links and taps are unchanged.
- Removed workarounds the parser makes unnecessary:
- the render-path escape shielding from #8925
- the `_MarkdownEscapeMd`, `_MarkdownLabelEntityMd` and `_MessageLinkMd`
components
- the zero-width prefix before a leading `#channel`
Plain-text previews and gallery helpers keep their own escape handling.
`normalizeBareLinks` stays because attachment and gallery detection
depend on its output. Bubble segmentation unescapes a link destination
itself before its imeta lookup, since content no longer arrives
shielded.
- Kept desktop parity where plusparse differs from GFM:
- a table typed directly under a caption line gets a blank line inserted
before it, since plusparse can't start a table mid-paragraph
- `> [!NOTE]` quotes render as quotes (`alertBuilder` returns
`asBlockQuote()`), since desktop has no alerts
- `mapMarkdownProse` now ends an unclosed backtick run at its paragraph.
Before, it could pair with a run in a later block and flip code and
prose for the rest of the message.
- Synthesized autolink labels escape backslashes instead of using
`\`, which the parser leaves undecoded in a URL-shaped label.
- Repo/PR/issue chips keep their own semantics node.
- Forum card previews clip at their 120 px cap instead of overflowing:
blocks now lay out as a column.
- Pinned to exactly 1.3.4. 1.4.0 renders HTML by default and themes
through the separate `material_ui` package, which would need a theme
bridge.
### Validation
- Full mobile suite passes and analyze is clean at
|
||
|
Sanket Kanjalkar
|
bd031a05af |
fix(acp): bound observer retention by bytes (#7987) (#9436)
Replaces #9366 on a branch in this repository and resolves its conflicts
with main.
## Summary
The ACP observer kept up to 1,000 raw events in both replay and live
buffers. Large valid messages could retain gigabytes before downstream
trimming ran.
Fit telemetry before either buffer retains it. Cap replay at 4 MiB of
serialized JSON and keep the existing live window. Its per-event limit
bounds live JSON below 64 MiB.
Preserve the CPU and locking improvements from #9381: prepare large
payloads and copy snapshots outside the replay lock. Finalize sequence
and timestamp with publication. Account for that final metadata,
including sequence digit-width changes, in the byte limit.
The tradeoffs are extra work per emit, shorter replay history for large
events, and elided oversized telemetry. Agent protocol messages remain
unchanged.
### Related issue
Fixes #7987. Existing publisher byte limits act downstream of these
buffers.
### Testing
The opt-in probe exercises the real in-process emit, snapshot and
stalled-subscriber paths:
```sh
CARGO_INCREMENTAL=0 CARGO_PROFILE_RELEASE_LTO=thin CARGO_PROFILE_RELEASE_CODEGEN_UNITS=4 \
cargo test --release -p buzz-acp --lib observer::tests::retention_probe -- --exact --ignored --nocapture
```
Compared baseline `a314975ce` with candidate `c2df3cb56` on macOS arm64,
Rust 1.98.1. The baseline observer, fitter, workspace manifest and
lockfile match the candidate's parent `8f3f4e266`. Both arms use
`opt-level=3`, thin LTO and four codegen units, with incremental
compilation and compiler-cache wrappers off. This profile is fixed for
the comparison; this PR does not change build settings.
Values are medians of three fresh-process runs per version and workload,
in alternating order. Peak RSS comes from `/usr/bin/time -l` around each
test executable; compilation is excluded. Each version was rebuilt
separately and its executable and workload identity verified.
| Workload | Peak RSS before → after | Emit time per event before →
after |
| --- | --- | --- |
| 10,000 × 1 KiB | 14.0 → 14.1 MiB | 0.47 → 0.89 µs |
| 1,000 × 60,000 bytes | 199.4 → 80.8 MiB | 8.54 → 22.53 µs |
| 1,000 × 1 MiB | 3,025.8 → 26.4 MiB | 123.50 → 307.89 µs |
For the 1 MiB workload, replay JSON fell from 1,000.2 MiB to 3.997 MiB.
Live JSON fell from 1,000.2 MiB to 5.91 MiB. Replay retained 676 fitted
events; the live subscriber received all 1,000.
Emit time includes payload construction. Peak RSS includes snapshot and
receive copies made by the probe. JSON budgets are not exact heap
limits. These local measurements show the memory/CPU tradeoff;
concurrent producer throughput and native app latency were not
benchmarked. See [the probe
instructions](
|
||
|
Sanket Kanjalkar
|
471ca6b1ae |
Tune release codegen for faster/smaller binaries (#9434)
Replaces #9424 with the same release-profile change on a branch in this repository so the review workflows can run. ## Summary Reduce release codegen units from 16 to 4 and enable thin link-time optimization (LTO). Local measurements show about **7% smaller binaries**, with a **14% increase in dependency-cached release rebuild time** (+3.1 seconds). Clean release build time was roughly flat. `codegen-units = 4` seems like a good balance. With thin LTO fixed, one unit cut stripped sizes a further 7–10%, but increased clean build time by 38% and cached release rebuild time by 67.5%. CPU and Activity trials showed no clear speedup. Fewer codegen units let LLVM optimize larger portions of each crate together. Lower counts typically favor runtime performance and smaller binaries over compilation speed. Thin LTO also enables optimization across crate boundaries. Runtime gains depend on the workload. Release keeps `opt-level = 3`, the highest numeric optimization level and Cargo's existing default. Development builds stay unchanged. Keep the custom `ci` profile at 16 codegen units with LTO off, preserving its existing settings. Sprig keeps its separate size-focused profile. CI jobs that use ordinary `--release` will use the new settings. These measurements cover `buzz` and `buzz-acp`, not the desktop bundle. The desktop app has its own Cargo workspace; its bundled CLI picks up this change after a pin update. Our end-to-end runtime trials were broadly flat; the measurements below demonstrate the size and build-time tradeoff. ### Related issue N/A — no duplicate release LTO/codegen PR found. This PR contains only the profile change and is independent of #9413. ### Testing #### Baseline versus four codegen units Compared identical source and lockfile at `b4de4479485fc3d57628ed509ed40c4278e63132`, using Rust 1.98.1 on an Apple M5 Max (18 cores, 128 GiB RAM). Both arms used `opt-level=3`, disabled incremental compilation and no compiler-cache wrapper. The baseline used LTO off and 16 codegen units; the candidate used thin LTO and four. | Median / artifact | Baseline | Thin LTO, 4 units | Change | | --- | ---: | ---: | ---: | | Clean release build (2 runs each) | 47.98 s | 46.71 s | -2.7% | | Dependency-cached release rebuild (3 each) | 22.55 s | 25.68 s | +13.9% | | No-op release build (5 each) | 0.469 s | 0.461 s | Roughly unchanged | | `buzz` executable | 14.516 MiB | 13.580 MiB | -6.4% | | `buzz-acp` executable | 14.580 MiB | 13.487 MiB | -7.5% | Build command: `cargo build --offline --locked --release -p buzz-acp -p buzz-cli --timings`. Set `CARGO_INCREMENTAL=0`, `CARGO_PROFILE_RELEASE_LTO=false|thin` and `CARGO_PROFILE_RELEASE_CODEGEN_UNITS=16|4` for each arm, with separate `CARGO_TARGET_DIR` directories. Clean runs used empty build directories in sequential ABBA order, with downloaded dependencies and filesystem caches warm. Rebuilds cleaned only `buzz-acp` and `buzz-cli` outside the timed region. Sizes are Cargo-built executables before the desktop packager's stripping step. Stripping copies with `xcrun strip -S -x` kept the size benefit: `buzz` fell from 12.550 to 11.805 MiB (-5.9%), and `buzz-acp` from 12.360 to 11.501 MiB (-7.0%). This does not measure a signed desktop installer. Both release executables passed `--help` smoke checks. Profile inspection confirmed the custom `ci` and `sprig` settings are unchanged. #### One codegen unit versus four A separate follow-up compared four versus one on `a314975ce7bf9aa00baebfef874b6e69474a95cf`, which includes the merged observer CPU/locking changes (#9381). Both arms used thin LTO, `opt-level=3`, the same Rust 1.98.1 toolchain and hardware, and identical source and lockfile. This is a separate source snapshot from the first comparison; the tables should not be combined into a three-arm comparison. | Median / artifact | Thin LTO, 4 units | Thin LTO, 1 unit | Change | | --- | ---: | ---: | ---: | | Clean release build (2 runs each) | 45.93 s | 63.35 s | +37.9% | | Dependency-cached release rebuild (3 each) | 22.38 s | 37.48 s | +67.5% | | Stripped `buzz` | 11.789 MiB | 10.923 MiB | -7.3% | | Stripped `buzz-acp` | 11.485 MiB | 10.320 MiB | -10.1% | | Activity p95 latency (median of 5 runs each) | 952 ms | 961 ms | No clear change | Both sets of binaries were stripped identically with `xcrun strip -S -x`. Repeat the build command above with `CARGO_PROFILE_RELEASE_LTO=thin` and `CARGO_PROFILE_RELEASE_CODEGEN_UNITS=4` or `1`, retaining the same cache and ordering controls. All 60 CPU trials and 10 Activity trials passed. The CPU cases exercised production packing and queue ingestion functions; their differences were within run variation. Activity exercised real ACP subprocesses, observer publication, signing/encryption, the browser broker and production UI against a modeled relay. All 500 markers rendered exactly once, and all 2,250 heavy events were delivered. Its one-second publication interval limits visible latency; these local results are not production percentiles. Generated with AI assistance --------- Signed-off-by: Sanket Kanjalkar <sanketk@squareup.com> Co-authored-by: Codex <codex@openai.com> |
||
|
Kalvin C
|
1fc6a71ef9 |
feat(desktop): add dismissible banner pointing to the new buzz app (#9379)
## Summary The Buzz 1.0 desktop app now lives in [block/buzz-app](https://github.com/block/buzz-app). This adds a banner to the 0.X desktop app that tells users, and lets them download the new app's installer without leaving the app. - A full-width banner sits under the top chrome: "A new Buzz app is here! This version is being retired, so grab the new one whenever you get a chance." - **Upgrade** downloads the installer for this machine inside the app. A dialog shows the progress, then the saved file's name and folder with **Show in Finder** (worded per platform) and **Done**. The file goes to the Downloads folder and is revealed in the file manager. It is never opened, mounted or run. - **Cancel**, Escape or the dialog's close button stops a running download and removes the partial file. - When no installer can be resolved for this machine (unsupported platform, or the manifest fetch fails or is slow), **Upgrade** opens `https://buzz.xyz` in the browser instead. - **More info** opens the [upgrade guide](https://github.com/block/buzz-app/blob/main/docs/upgrading.md) in the browser. - Dismissing (×, labelled "Remind me later") stores a timestamp in `localStorage`. The banner is read once per mount, so it comes back on the next launch (or community switch) once 24h have passed. - It is hidden in the huddle room window. ## Demo https://github.com/user-attachments/assets/1f1916e8-f32d-4ec0-8e60-fe7c85dd4a57 Recorded on macOS (Apple Silicon) from a native debug build with the real Rust backend: a full download, **Done**, then a second download cancelled part-way. - The network is throttled through a local proxy so the progress stays visible. Unthrottled, the installer arrives in about two seconds. - The app was launched with a scratch home folder, so the path in the dialog is a scratch path, and the Finder window that the reveal opens is left out of the recording. - Presses are accessibility presses, marked with an orange ring. The OS cursor is not shown. ## How the download works - **Which installer:** a Tauri command reports this install's key (`macos-arm64`, `macos-x64`, `windows-x64`, `linux-appimage` or `linux-deb`). The webview reads the matching entry from the [buzz-app download manifest](https://raw.githubusercontent.com/block/buzz-app/download-feed/downloads.json) once per banner mount. - **Validation:** Rust re-validates the URL on every call. It must be `https://github.com/block/buzz-app/releases/download/<tag>/<file>`, with a restricted tag and file-name character set and the extension this machine installs. The webview names a URL and nothing else. - **Redirects:** a dedicated HTTPS-only client follows at most 5 redirects, and only to `github.com`, `objects.githubusercontent.com` or `release-assets.githubusercontent.com`. - **Limits:** 512 MiB, 15 s to connect, 30 s for headers, 30 s without a byte, 60 min in total. One download at a time. - **Saving:** the body is written to `<name>.<random>.part` in the Downloads folder, then renamed to `<name>` (or `<name> (1)` and so on) without ever replacing an existing file. The partial file is removed on failure, on cancel and at app exit. A partial left by a crash or force-quit is removed on the next launch. - **Downloaded-from-the-internet marking:** macOS gets the `com.apple.quarantine` attribute a browser would write, and Windows gets the Mark of the Web (`Zone.Identifier`). If the mark cannot be written, the download fails and the file is not kept. - **Failures:** the dialog says what went wrong in plain words. Transient failures lead with **Try again**. Failures a retry cannot fix lead with **Download in browser**, which opens the validated installer URL. ## Testing - Unit: `deprecationBannerVisibility.test.mjs`, `newAppInstaller.test.mjs` (manifest and URL rules), `newAppInstallerDownload.test.mjs` (dialog state), and a jsdom test of the download hook. - Rust: `new_app_installer_tests.rs` covers URL validation, the redirect policy, limits, naming without overwrite, cancel and shutdown cleanup, launch cleanup, and the quarantine and Mark of the Web values. CI runs this crate's tests on Linux and on `windows-latest`, so the Mark of the Web test writes a real alternate data stream there. The quarantine test runs on macOS only, which CI builds but does not test. - Smoke: `tests/e2e/deprecation-banner.spec.ts` drives the banner, the download dialog, each failure's actions, cancel and the keyboard paths against the mock bridge. - Native, macOS arm64 debug build: the download was saved with `com.apple.quarantine` set and revealed in Finder; cancel removed the partial; the download kept running while the window was hidden; SIGTERM and a menu quit mid-download removed the partial; after a force kill the next launch removed it. Not verified by hand: - The Windows and Linux flows in a running app, including SmartScreen on Windows. - The Gatekeeper prompt when opening the downloaded DMG, and the macOS Downloads-folder consent prompt, which need a signed build. 🤖 Generated with [Claude Code](https://claude.com/claude-code) --------- Signed-off-by: Kalvin Chau <kalvin@block.xyz> Signed-off-by: Matt Toohey <contact@matttoohey.com> Co-authored-by: Claude Opus 5.5 <noreply@anthropic.com> Co-authored-by: Matt Toohey <contact@matttoohey.com> |
||
|
Tom Brow
|
3d3f9cf153 |
fix(mobile): keep publishing presence while the app is open (#9441)
Mobile stopped publishing presence on November 1. The heartbeat in
`PresenceNotifier` only runs while something holds `presenceProvider`,
and its last always-mounted watcher was the app-bar `ProfileAvatar`,
deleted as dead code in [#8880 dead code
cleanup](https://github.com/block/buzz/pull/8880). Since then the app
sends "online" only while Settings is open, stops when Settings closes,
and never sends "away" when backgrounded. Other people see a phone user
as offline (or stuck on whatever Settings last sent).
This keeps the provider alive from the signed-in shell, next to the
other app-wide `ref.listen` keep-alives in `app.dart`.
Found during a combined performance and network hunt on a physical
iPhone SE running main ([
|
||
|
Tom Brow
|
2b428f56b8 |
feat(mobile): share into Buzz from the iOS share sheet (#9433)
Lets people share screenshots, screen recordings, photos, URLs and text from any iOS app into Buzz. Today Buzz doesn't appear in the share sheet at all. - **Plain Buzz icon:** opens a new Solo chat with the items in its composer. - **Suggested conversation:** iOS offers channels and DMs the person recently sent top-level messages in. Choosing one opens that conversation with the items in its composer. When the conversation is already open, the share goes to that page's composer instead of opening a second one; if another page covers it, Buzz stays where it is and shows "Go back to that conversation to finish sharing", and the items join the draft when the person goes back. - The share extension has no UI and sends nothing. It copies the items into the app group and opens Buzz, which prefills the normal composer, so drafts, attachments, mentions and failed-send handling all stay the app's (see [the ADR](https://github.com/block/buzz/blob/mobile-share-extension-design/docs/adr/0003-share-hands-off-to-the-conversation.md)). - If the conversation already has a draft, Buzz asks whether to add the shared items to it or replace it. - A share to a conversation that's no longer available (a removed community or channel, or an unreadable share) shows "That conversation isn't available". A share while signed out shows "Sign in to share". Suggestions come from an outgoing `INSendMessageIntent` the app donates after a top-level send or a new Solo chat. The notification extension no longer donates incoming messages, so receiving a message never makes a conversation a suggestion; it still turns the push into a communication notification with the sender's avatar. Both use the same conversation identifier, now the plain community and channel IDs instead of a hash, because the extension needs to hand the identifier back to the app. | Before | After | | --- | --- | | <img alt="Share sheet without Buzz" src="https://github.com/user-attachments/assets/452fac1b-7e87-44c3-a442-099f78d0e07b" width="300"> | <img alt="Share sheet with Buzz" src="https://github.com/user-attachments/assets/54b9775d-29b4-49a5-8ab9-5fda8718a02f" width="300"> | | Buzz icon: new Solo chat | Suggested DM with a draft | After Add | | --- | --- | --- | | <img alt="New Solo chat with the shared photo" src="https://github.com/user-attachments/assets/c5da4d8b-1dd8-4e30-9e92-9dba515b3623" width="250"> | <img alt="Add to your draft prompt" src="https://github.com/user-attachments/assets/2f879f8a-3b9f-48e0-b963-2828e90dc9fe" width="250"> | <img alt="Draft with the shared link and photo added" src="https://github.com/user-attachments/assets/12832006-85c5-4447-98b5-62932552c931" width="250"> | https://github.com/user-attachments/assets/b9d380fa-e802-4ed7-89a8-592a03784c8f ### Regressions - Nothing changes for people who never use the share sheet, except that sending a top-level message or starting a Solo chat now makes one local `INInteraction.donate` call (skipped while the age restriction is on, which still purges every interaction). - Communication notifications look the same. Dropping the incoming donation removes work (and a deletion fence) from the notification extension's time budget. - The share hand-off reuses the existing deep link dispatcher. A share link is a new link type; notification and message links take the same paths as before. ### Validation - Added tests: - Dispatcher hand-off: a share to a suggested channel opens it with the shared text and files; shares to a removed community, an unlisted channel, an unknown manifest version or a missing manifest show the error and delete the pending share; share links accept only the extension's UUID ids. - Composer delivery: with an existing draft, Add appends the shared text on a new line and attaches the file, Replace clears the draft first, and the app group copy is deleted either way. - Notification presenter: specializes the notification from the intent, or falls back to the ordinary content when that throws (replaces the donation and deletion-fence tests). - Full mobile Flutter suite and BuzzPushKit Swift tests pass. - Automated app run on an iPhone 17 Pro simulator (iOS 27, dev relay test community), recorded above: sent a DM, shared a photo from Photos with the Buzz icon from a cold start (new Solo chat with the photo attached), then handed a link and photo to a DM that had a draft and chose Add. Also checked that a share's pending files are deleted after delivery. - Limitation: the iOS simulator never shows share-sheet conversation suggestions (it has no `coreduetd`), so the suggested-DM step in the video is staged by writing the same pending share and link the extension writes. Choosing a real suggestion still needs a check on a device. - Known gaps, all confined to sharing: suggestions have no avatar image yet; a suggestion for a conversation left after signing out shows "isn't available"; choosing Later in the unfinished-chat dialog keeps the share until the next new chat; and a pending share the app never receives (for example when Buzz doesn't open) stays in the app group. ### Before merge - [x] On a real iPhone, choose a suggested conversation in the share sheet and confirm the shared items open in that conversation's composer (the simulator can't show suggestions). Waived before merge: the managed test iPhone shows no share-sheet suggestions for any app, so this will be checked on a personal phone after landing. --------- Signed-off-by: Tom Brow <tomb@squareup.com> Co-authored-by: Tom Brow <tomb@squareup.com> |
||
|
Kalvin C
|
3c0adc1882 |
fix(mobile): qualify every namesake mention and keep authored mention casing (#9325)
## problem When a message mentions two different identities that share a display name, the mobile composer qualified only the later selection as `@Name (<64-hex>)` and left the first one bare. A qualified occurrence denies the plain name on render, so the first mention rendered as plain text on mobile and desktop. `MessageContent` also displayed every mention in the lowercased binding key rather than its authored spelling. ## change - `mention_bindings.dart`: - `selectedMentionLabel` qualifies a selection whenever another selected identity shares its name, without regard to case. - `namesakeRequalifications` and `renameMentions` qualify earlier plain selections. Each occurrence keeps its authored spelling, and occurrences in code stay as typed. - `compose_bar/helpers.dart` and `compose_bar_widget.dart`: - Selecting a namesake qualifies earlier same-name mentions before the new label is inserted, keeping the caret in place. - Occurrences inside code that the composer styles are skipped: single-backtick spans and closed triple-backtick fences, found by the same walk the editor uses to draw them. A key whose occurrence stays in code remains bound beside its qualified label, so its recipient still sends. - `agent_mention_prefill.dart`: automatic addressing qualifies every same-name agent it inserts. - `message_content.dart`: mentions render in their authored spelling, and bindings still resolve case-insensitively. - `docs/mention-editor.md`: describes the behavior, including that Markdown code forms the composer does not style (tilde fences, indented code) are qualified like prose. ## tests - `mention_bindings_test.dart`: requalification, spelling preservation and code exclusion. - Composer journeys: - picker selections qualify both namesakes and send both keys; - styled code (fences, list fences, spans, spans after bold or italics) stays as typed while surrounding prose is qualified; - a selection left only in code keeps its recipient; - automatic prefill of two same-name agents qualifies both. - `message_content_exact_mentions_test.dart`: authored casing with case-insensitive resolution. - `just mobile-check mobile-test` passes. - Real relay: composed bodies exchanged through a local relay render as correctly targeted chips in desktop and in Flutter `MessageContent`. --------- Signed-off-by: Kalvin Chau <kalvin@block.xyz> Signed-off-by: Tom Brow <tomb@squareup.com> Co-authored-by: Claude Opus 5.5 <noreply@anthropic.com> Co-authored-by: goose-wayne <ae6b377e5b6d090ee22558d19246413a5731628a127e25371111badfd4861535@buzz.block.builderlab.xyz> Co-authored-by: Tom Brow <tomb@squareup.com> Co-authored-by: peon <9ac6794b000690b7e814eb1805ad32405d0bec7d52838de3a86cf967565dacc0@buzz.block.builderlab.xyz> |
||
|
Tom Brow
|
bf3bdd0eae |
fix(mobile): match browser GIF timing in the iOS reaction sheet (#9437)
The two follow-ups from the pre-review of [#9432 GIF frame timing](https://github.com/block/buzz/pull/9432), rebased onto main now that it has landed. **iOS reaction details sheet.** The sheet decodes custom emoji natively (`NativeMessageImageLoader.decode`) and timed each frame as `max(0.02, delay)`, so with [#9432 GIF frame timing](https://github.com/block/buzz/pull/9432) a GIF with 0 or 1 cs delays plays at 100 ms per frame in the timeline chip but 20 ms per frame in the sheet opened from it. The decoder now shows frames of 10 ms or less for 100 ms, as browsers and `MediaImageProvider` do, and keeps longer frames as written. The 20 ms floor goes with it: browsers keep 11 to 19 ms frames as written too. **Provider-level test.** The existing tests call `withBrowserFrameTiming` directly, so removing the provider's call to it left the suite green. A new test resolves a GIF through `MediaImageProvider` with a mock HTTP client and pumps the scheduler's app frames at explicit timestamps: the 10 ms first frame is still showing at 50 ms and is replaced at 100 ms. ### Regressions None expected. The sheet already summed the frame delays into one `UIImage.animatedImage` duration, so only the per-frame value changes, and only for frames of 10 ms or less, which ran at 20 ms before. Still images and longer frames decode as before. The Dart test drives frame callbacks with explicit timestamps rather than waiting on wall-clock time. ### Validation Added tests: `NativeMessageImageLoaderDecodeTests` in RunnerTests (a 0, 1, 2, 5 cs GIF decodes to a 0.27 s animation; a one-frame GIF stays still) and `withBrowserFrameTiming is applied to the frames MediaImageProvider plays` in `media_image_test.dart`, which fails when the provider's call is removed (the second frame shows at 50 ms). Full mobile suite: 4,780 tests passed. `flutter analyze`: no issues. RunnerTests `NativeMessageImageLoaderDecodeTests` and `NativeReactionDetailsTests`: all five pass on an iPhone 17 simulator (Xcode build-for-testing of the Debug simulator app). No full-app run: the change is one delay value in a decoder and is covered by the unit tests above. Signed-off-by: Tom Brow <tomb@squareup.com> Co-authored-by: Tom Brow <tomb@squareup.com> Co-authored-by: judge <7615ec4b7ddf99f0bb48e913297f99f8f772d289a1c9ef54e1d906dd55a93ba8@sprout-oss.stage.blox.sqprod.co> |
||
|
Kalvin C
|
0bbcf3e7c2 |
fix(mobile): play short-delay animation frames at browser speed (#9432)
Some animated custom emoji play far faster on mobile than on desktop. Browsers show any animation frame with a delay of 10 ms or less for 100 ms. Firefox started this ([bug 207059](https://bugzilla.mozilla.org/show_bug.cgi?id=207059)). Chromium copied it (decoder comment: "use a duration of 100 ms for any frames that specify a duration of <= 10 ms"), and so did WebKit ([changeset 73295](https://trac.webkit.org/changeset/73295/webkit)). Flutter uses the delay as written ([flutter/flutter#130684](https://github.com/flutter/flutter/issues/130684)), so a GIF with 0 or 1 centisecond delays runs at the display refresh rate on mobile and at 10 fps on desktop. `MediaImageProvider` now wraps multi-frame codecs so frames of 10 ms or less get 100 ms. Every other frame keeps its own delay. Still images are passed through unchanged. Custom emoji, avatars and attachments all render through this provider. **Tests:** `flutter test test/shared/relay/media_image_test.dart` passes (24/24), and `flutter analyze` reports no issues on the changed files. The new test decodes a GIF with delays of 0, 1, 2 and 5 cs and expects 100, 100, 20 and 50 ms. It fails when the wrapper is removed. 🤖 Generated with [Claude Code](https://claude.com/claude-code) Signed-off-by: Kalvin Chau <kalvin@block.xyz> Co-authored-by: Claude Opus 5.5 <noreply@anthropic.com> |
||
|
Luke Tornquist
|
279a31daac |
buzz-search: read profile names without the profile_name_fields function (#9397)
## What

This is phase 1 of 2 for retiring the plpgsql function
`profile_name_fields(text)`. Its only caller, profile name search
(`search_profile_names`), now gets `name` and `display_name` from an
inline SQL expression (`PROFILE_NAME_FIELDS` in
`crates/buzz-search/src/query.rs`) instead.

The function's exception handler made unreadable kind:0 content have no
names rather than fail the search. The inline version keeps that
guarantee in two steps:

- **`pg_input_is_valid(content, 'jsonb')`** rejects the soft parse
errors: a `\^@` escape, a lone surrogate, a huge number, and malformed
JSON.
- **A bracket bound for deep nesting.** PostgreSQL's JSON parser is
recursive. Past about 10k levels at the default `max_stack_depth`, it
raises `stack depth limit exceeded`, and `pg_input_is_valid` does not
catch that. I confirmed this on PG 17: depth 10k is fine and 20k raises.
So content with more than 4096 `[` and `{` is never parsed and has no
names. The count bounds the depth. Ingest already rejects kind:0 content
nested deeper than 128 levels (serde_json), so this only matters for
content stored another way.

`OFFSET 0` keeps the parse from being copied into each reference to
`doc`, so each candidate row is parsed once, plus one validity pass. The
plpgsql function also parsed each row once.

**Behavior change (edge only):** a kind:0 with more than 4096 brackets,
even inside strings, is no longer findable by name. Real profiles don't
come close, and a `picture` data URL is base64 with no brackets.

`pg_input_is_valid` needs PostgreSQL 16 or later. CI runs 16, and the
dev compose runs 17.

**Phase 2 (not here):** a migration and desired-state change drops the
function, its `schema/functions/` file and its `schema.sql` entry once
this release has shipped.

## Tests

- `profile_names_survive_unparsable_content` already stores a `\^@`
profile, a lone-surrogate profile, a `1e1000000` profile and a 60k-deep
profile next to a plain one, and requires the search to return only the
plain one. It now also covers the bound itself: a profile with exactly
4096 brackets, all but one inside a string, is still found.
- Must-fail mutants, each run on Blox: bracket bound removed (the search
fails with a stack overflow), validity check removed, bound tightened by
one, and the string-type check loosened.

## What got simpler

Profile search no longer depends on a database function. Name extraction
lives next to the rest of the search SQL it feeds.

## Verification

Blox, at `be0db303ea90033cc2c37ac8f8f07c27f4b08e31` (clean tree):

| Gate | Result |
|---|---|
| `cargo fmt --all --check` | pass |
| `cargo clippy -p buzz-search --all-targets -- -D warnings` | pass |
| `cargo nextest run -p buzz-search --lib` | 4/4 |
| `scripts/postgres-test-run.sh -p buzz-search --tests -E
'test(/profile_names/)'` | 4/4 |
| Must-fail mutants (no bound, no validity check, bound tightened by
one, non-string names allowed) | 4/4 killed |

Probe on PostgreSQL 17.11: `pg_input_is_valid` returns false for `\^@`,
a lone surrogate, `1e1000000` and truncated JSON; nesting depth 10k is
valid; depth 20k raises `stack depth limit exceeded`. CI runs the full
Postgres lanes.

🤖 Generated with [Claude Code](https://claude.com/claude-code)


buzz-review-completed

---------

Signed-off-by: Luke Tornquist <tornquist@squareup.com>
Co-authored-by: Elrond <28d6302a099e5225b02c4155ac4236e4912603df2ab08dbfc2f4fef08ce598c8@buzz.block.builderlab.xyz>
Co-authored-by: Claude Opus 5.5 <noreply@anthropic.com>
|
||
|
Luke Tornquist
|
745f7dac7c |
buzz-db: build the community deletion lock key in Rust (#9396)
## What This is phase 1 of 2 for retiring the SQL function `community_deletion_lock_key(uuid)`. Every relay caller now builds the lock name in Rust, with `buzz_db::deletion::community_deletion_lock_key(CommunityId) -> String`. It then locks with the built-in `hashtextextended($1, 0)`, the same pattern the other advisory locks here use (`channel_ttl_lock_key`, `push_gate_lock_key`). The string is byte-for-byte the one the function hashes (`'buzz-community-deletion:' || target::text`), so the lock is identical. Old and new relays, and the fence functions still in the database (`community_write_allowed`, `assert_community_write_allowed`), keep excluding each other during a rolling deploy. - **Production callers:** exclusive `lock_community_deletion`, shared `lock_community_deletion_shared`, and the bulk shared lock in `bind_nip_fi_issuers_to_active`. The bulk lock now binds a `text[]` of keys, sorted by community id in Rust and locked `WITH ORDINALITY`. That keeps the old `ORDER BY id` lock order, because `Uuid` and Postgres `uuid` both compare bytewise. - **Startup check:** `validate_serving_catalog_on` no longer requires the function to exist, so the phase-2 drop can't make this release refuse to serve or delete. - **Tests and docs:** test lock holders use the helper. `docs/database.md` gives repair scripts the inline expression, which keeps working after the drop. - The test-schema shims in `api/bridge.rs` and `handlers/ingest.rs` stay. Test schemas still copy the fence functions that call the function. **Phase 2 (not here):** a migration and desired-state change drops the function after this release is fully deployed and the fence functions are gone (#8323). It also removes the two test shims. ## Tests - `deletion::postgres_tests::community_deletion_lock_key_matches_the_sql_function` checks that `hashtextextended(rust_key, 0)` equals `community_deletion_lock_key(uuid)` for the nil UUID, the max UUID and 64 random ones. - `migration_schema_fence_objects_are_optional_for_serving_and_deletion` already drops the universal fence objects by hand. It now also drops `community_deletion_lock_key(UUID)`. With both present and absent, it runs the startup and readiness checks, serving leases (shared lock), `bind_nip_fi_issuers_to_active` (bulk shared lock) and `lock_community_deletion` (exclusive lock). Must-fail mutants, each run on Blox against its guarding test: a changed key prefix, the shared, exclusive and bulk locks reverted to the SQL function, and the startup check requiring the function again. ## What got simpler No relay code path calls a database function to build this lock any more. The key has one definition in Rust instead of one in SQL plus about 20 SQL call sites. One fewer object stands between the schema and declarative-only management (`docs/database.md` Rule 1). ## Verification Blox, at `3020a44148d942f1502395640730cd0548a76400` (clean tree): | Gate | Result | |---|---| | `cargo fmt --all --check` | pass | | `cargo clippy -p buzz-db -p buzz-relay --all-targets -- -D warnings` | pass | | `cargo nextest run -p buzz-db --lib` | 214/214 | | `scripts/postgres-test-run.sh -p buzz-db --lib` over `deletion::postgres_tests`, `nip_fi_binding::postgres_tests` and the reaction and channel-member lock tests | 101/101 | | Must-fail mutants (prefix, shared, exclusive, bulk, startup check) | 5/5 killed | CI runs the full Postgres lanes. 🤖 Generated with [Claude Code](https://claude.com/claude-code) buzz-review-completed Signed-off-by: Luke Tornquist <tornquist@squareup.com> Co-authored-by: Elrond <28d6302a099e5225b02c4155ac4236e4912603df2ab08dbfc2f4fef08ce598c8@buzz.block.builderlab.xyz> Co-authored-by: Claude Opus 5.5 <noreply@anthropic.com> |
||
|
Will Pfleger
|
630922a9e1 |
fix(cli): pair for the active community, skip stopped desktops, accept a bare relay host (#9417)
## Summary Fixes to `buzz auth desktop pair` and relay selection: - **`pair` skips desktops that aren't running.** A desktop that exited without removing its advertisement no longer counts toward "several Buzz desktops are running". It uses the same running test as `probe`, where only a transport failure means not running. - **`--relay` is global**, so `buzz auth desktop pair --relay …` works and the flag shows in subcommand help. - **A bare host means `https://`** for `--relay` and `BUZZ_RELAY_URL`. An explicit `http://`, `ws://` or `wss://` stays as typed. - **`pair` with no relay sends `[client]`.** The desktop pairs for its active community and returns the bound relays, which the CLI stores. An older desktop answers `invalid_request`, which the CLI reports as "this Buzz can't pick a community; pass --relay". - **`docs/local-credential-provider.md`**: covers the one-parameter `pair`, `unavailable` when no community is active, the older-provider fallback, skipping stale advertisements, and a lapsed sign-in keeping the pairing instead of revoking it. - The existing `concurrent_pair_and_unpair…` test now fails after 60s instead of hanging when the held pair request never reaches the mock desktop. - The CLI tests that run the real `lsof` same-user check now take turns. A nextest test group, `desktop-same-user-check`, serializes the whole `desktop_provider::` module for the pre-push hook. Most of its tests reach the check, and the few that don't run serially too. A test-only lock around the check does the same in `cargo test`. Waiting for a turn doesn't count against the request timeout. The check and its 5s limit are unchanged. `list_tells_a_stale_advertisement_from_a_rejection` keeps the in-cap `retry_after` of 30 and times from the desktop's first answer, so waiting for a turn isn't counted. The desktop half is block/buzz-app#3386. ## Testing - New tests: `pair_skips_a_desktop_that_is_not_running`, `an_older_desktop_asks_for_a_relay`, `relay_flag_is_global_and_a_bare_host_means_https`, plus updated relay-selection cases. - `cargo test -p buzz-cli --locked -- --test-threads=4` passes: 689 tests, both with default threads and with `--test-threads=4`, and under the pre-push hook's nextest run. --------- Signed-off-by: Will Pfleger <wpfleger@block.xyz> Co-authored-by: Hayt <211b96e6a2b7f45fd4047988976c7bbbeeda0c15f3ae7b32eec20834b5a55118@buzz.block.builderlab.xyz> |
||
|
Tom Brow
|
8f3f4e266a |
test(mobile): run push tests without a gateway dart-define (#9423)
A plain `cd mobile && flutter test` failed 11 push and notification tests on a clean checkout of main, while CI passed. Agents running the full suite kept reporting them as "pre-existing, also fails on main", which hides real regressions in the same files. ### Root cause Push is gated on the compile-time `BUZZ_PUSH_GATEWAY_URL` define (`Env.pushGatewayConfigured`, since [#7261 configurable gateway](https://github.com/block/buzz/pull/7261) made the gateway optional). Without it the app is a push-less build: `readBuzzPushEndpointGrants()` returns no grants and `buzzPushLifecycleEnabled()` is false. CI's mobile shards, `just mobile-test` and the lefthook pre-push lane (which runs `just mobile-test`) all pass `--dart-define=BUZZ_PUSH_GATEWAY_URL=https://push.example`; a bare `flutter test` passes nothing. Each of the 11 was checked against that: - `notification_toggle_test` (5 cases) and `push_lease_revocation_outbox_test` "hosted relay assertion": no endpoint grants without a gateway (`Bad state: No element` at the grant lookup, `No endpoint grant exists for push lease tombstone`). - `push_bridge_test` "reads and exposes persisted endpoint grants" and "debug enrollment carries the configured relay and gateway URLs": the bridge returns `[]` before calling native (`Expected: an object with length of <1>, Actual: []`). - `push_bootstrap_test` "default push requires relay capability" and "new community starts registration": the lifecycle is disabled, so registration never starts (`Expected <1>, Actual <0>`). - `push_bridge_test` "development push gateway matches the compiled configuration": a stale test. It expected a `https://push.buzz.xyz` default that [#7261 configurable gateway](https://github.com/block/buzz/pull/7261) removed from the app; under CI's define both sides equal `push.example`, so it could never fail there. The same files pass on the same Mac with the define, so nothing is environmental. The `Unexpected native call takePendingNotificationResponse` log is unrelated noise: the toggle test's native mock didn't answer that call, which logs (and is caught) in CI too. ### Fix Tests get the gateway from a test hook instead of the define. `Env.pushGatewayUrl` becomes a getter over the compiled value with a `@visibleForTesting` `debugPushGatewayUrlOverride` (the same pattern as `debugUriStreamOverride`), and `test/flutter_test_config.dart` sets it for every test file. `push_unconfigured_build_test` sets it to `''`, so it runs in the main suite instead of being skipped there and run separately. CI, the Justfile, `scripts/flake-check.mjs` and the AGENTS/README check commands drop the define, so CI, `just mobile-test`, pre-push and a bare `flutter test` run the same thing. I chose this over documenting a canonical command because the define can't be made automatic: `flutter test` has no config file for defines, so any doc fix still leaves the obvious command red. A test hook makes every invocation agree. The stale test is replaced by one in the push-less file that binds the production read: with the override cleared, `Env.pushGatewayUrl` must equal the compiled `BUZZ_PUSH_GATEWAY_URL`. Now that CI compiles without the define, it fails if the app regains a built-in gateway default, which the old test never could. The toggle test's mock answers `takePendingNotificationResponse` with no pending response. What gets better: one test mode everywhere, and the push-less tests run in every run. Nothing gets worse: production reads the same compiled value (the override is never set outside tests, and an `aot-snapshot` probe shows AOT still folds the getter to the compiled constant and drops push-only code when the define is absent), and every test still runs in the push-capable mode CI used before. ### Validation - On a fresh origin/main worktree with the Hermit toolchain, a bare `flutter test` failed exactly these 11; the same files passed on the same machine with the define. - After the fix, the pre-push `just mobile-check` and `just mobile-test` (now a bare `flutter test` plus the recipe and secp256k1 checks) pass, with the push-less tests running instead of skipped. `scripts/flake-check.test.mjs` passes. - Falsifiability: re-adding a `defaultValue` to the compiled gateway fails the new no-default test, and removing `flutter_test_config.dart` brings back the other 10 failures. - Unrelated: an earlier full run also failed `community_provider_test` "discard orphan snapshots and image caches", which waits 500 ms for a background directory delete. The Mac was running other full suites at the time; the file passed 8 of 8 runs alone, with and without the define. It is not touched here. Signed-off-by: Tom Brow <tomb@squareup.com> Co-authored-by: Tom Brow <tomb@squareup.com> Co-authored-by: studio <dc2fc481343672df31a689840c09299972e704dac592e0da6f18486646a7ee3e@buzz.block.builderlab.xyz> |
||
|
Tom Brow
|
5bfbda4c33 |
fix(mobile): never pop Home when archiving from channel settings (#9387)
Archive, Leave, Unarchive and Delete in channel settings wait for the relay, then close the settings sheet by popping whatever route is on top of the root navigator. If the user closes the sheet themselves during that wait (for example: long-press a chat on Home, Archive, confirm, then tap the close button), that pop lands on Home instead. The navigator ends up empty: a blank white or black screen with no controls and no way back short of killing the app. ### Change - **Close only the route that offered the action.** (Main has since gained the same guard; after merging main, this part of the diff is a comment plus the tests below.) After the action completes, the settings sheet or page closes itself only if it is still on top, with its "close the conversation too" result, as before. If the user opened something over it meanwhile (for example a member's profile), it stays open under that route, which keeps working. If the user already dismissed it, nothing is popped. The sheet still closes on its own after a successful archive. - **Home can no longer be popped.** The app's root route refuses pops. A stray pop that reaches it is reported through `FlutterError.reportError` (which fails widget tests) and ignored, so no other caller can leave an empty navigator either. Local-history pops on the root route (a drawer or persistent bottom sheet) still close normally. The root route still rebuilds from the current auth state, so sign-in and sign-out transitions are unchanged. ### What changes for the user Only the case where a settings action finishes after the user moved on: - Settings dismissed mid-flight: before, the completion popped whatever was on top (Home, the conversation, a thread or a profile). Now nothing is popped. - Something opened over settings mid-flight: before, the completion popped that new route and left settings open. Now that route stays, and settings stays open under it, as on main. That settings page shows the channel as it was before the action (for example still offering Archive after an archive, or a channel that is gone after Delete or Leave), as on main. Settings following lifecycle changes is part of the follow-up below. - Delete or Leave from the pushed settings page, then back out before the relay answers: before, the stray pop happened to close the conversation. Now the conversation stays open until the user leaves it (Leave and Archive show the read-only notice; a deleted conversation keeps showing its last state). Closing it reliably needs the conversation to notice its channel is gone, which is a follow-up. Pops that reach Home were always a bug and are now refused. Every other pop (sheets, pushed pages, system back above Home) takes the same path as before. ### Validation Added tests: - Channel actions sheet journey: confirm Archive with the relay call still pending, close the sheet, then let the archive finish. Home stays. A second pass leaves the sheet open and checks it closes by itself once the archive completes. Fails on the old code with Home popped. - Conversation journey: open settings from a conversation, confirm Archive with the relay call pending, open a member's profile, then let the archive finish. The profile stays open and current, and its Message action still opens the DM. Fails if the completion pops the top route, and fails if it removes the covered settings page (the profile loses the context it navigates from). - Root route: normal push and pop still work, a drawer on Home closes on back, and popping Home is refused, reported, and Home stays on screen. Full mobile test suite and `mobile-check` pass, including after merging main. Automated app run at [mobile-v1.1.0-rc.3 |
||
|
Sanket Kanjalkar
|
a314975ce7 |
perf(acp): reduce observer CPU and lock overhead (#9381)
## Summary The Agent Client Protocol (ACP) observer records agent activity for the owner's viewer. Sizing currently allocates JSON strings and rescans whole frames for each trimmed field. Count JSON bytes directly, reuse fitted sizes, and count changed fields when cheaper. Skip raw-message copies for disabled observers and copy replay payloads outside the mutex. Keep sequence numbers, timestamps, replay insertion, and publication under one lock to preserve replay/live ordering. This adds one `Arc` allocation per replay entry, and snapshots pin entries until copying completes. Replay retains the existing 1,000-event limit. ### Related issue Related to #7987. This PR targets `main` independently of #9366, which owns the byte-budget fix. The changes overlap in observer plumbing, so the second PR to land will need a rebase. ### Testing The new ignored probe exercises the production publish queue. Timing includes template clones and queue ingestion, before encryption. Five alternating fresh release processes per arm/case compared `75d38b6c2` with this commit on a busy host. Every pair retained identical queue bytes and event counts. ```sh cargo test --release -p buzz-acp --lib observer::perf_tests::publish_queue_probe -- --exact --ignored --nocapture ``` Set `BUZZ_OBSERVER_PROBE_EVENTS`, `BUZZ_OBSERVER_PROBE_BYTES`, and `BUZZ_OBSERVER_PROBE_FIELDS` for each row. Medians: | Events / string bytes per event / fields | Before | After | | --- | ---: | ---: | | 200 / 1 MiB / 64 | 5605 ms | 228 ms | | 1,000 / 1 MiB / 1 | 714 ms | 352 ms | | 10,000 / 1 KiB / 1 | 13.01 ms | 6.90 ms | A separate 20-trial integration run used the same production Chromium app build (`block/buzz-app@128cd4c2`) and four real ACP subprocesses. Three peers emitted 225 synthetic messages over five seconds, each with 1 MiB across 64 strings. A fourth emitted 50 markers, 100 ms apart. Each arm/mode used five fresh processes and browser contexts, with alternating arm order. The real observer, publisher, encryption/signing, browser broker, and Activity UI ran through a modeled relay transport. Marker timing used one controller clock, from release through transcript DOM commit plus two animation frames. Observer timestamps were not the timing origin. Observation-enabled medians: | Metric | Before | After | | --- | ---: | ---: | | Rust CPU time | 4.49 s | 0.45 s | | Marker-to-render p95 | 4471 ms | 1018 ms | | Sampled peak RSS | 342.3 MiB | 296.9 MiB | All 500 enabled-mode markers rendered exactly once; all 2,250 large events were delivered with the existing payload elision. Observation-disabled CPU stayed roughly flat (0.13 s to 0.12 s). The controlled publication-order regression also fails original `main` and passes this commit. These are stress-workload measurements, not a general app speedup. Native hosting and deployed-relay performance remain unmeasured. The publish cadence remains one frame per second. No CI timing threshold was added. Generated with Codex Signed-off-by: Sanket Kanjalkar <sanketk@squareup.com> Co-authored-by: Codex <codex@openai.com> |
||
|
Luke Tornquist
|
ce42853982 |
ci: fix main — stale RunCause call sites and Playwright on ubuntu-26.04 (#9418)
## Summary
Two separate CI breaks are hitting every PR right now. Each one blocks a
required check, and neither fix can go green on its own, so this PR
fixes both.
**1. Rust test targets stopped compiling on main at fc8c8022.** #9227
added a required `RunCause` argument to `create_workflow_run` and a
`may_direct_agents` flag to `ActionSink::send_message`. Two tests that
merged around the same time still used the old signatures:
- `attach_rejects_run_from_another_workflow` in
`crates/buzz-db/src/store/workflow.rs` (from #8317)
- the agent-DM refusal test in `crates/buzz-relay/src/workflow_sink.rs`
(from #9371)
Each PR passed CI on its own base. Together they break Rust Lint, Unit
Tests, Windows Rust and the Desktop E2E Relay artifact build (main CI
run 43291564834). The fix passes `RunCause::Schedule` and `true`,
matching the neighbouring tests. Neither test is about run cause or
agent mentions, so neither assertion changes.
**2. Desktop E2E Integration fails on GitHub's new Ubuntu 26.04
runners.** `ubuntu-latest` is rolling to 26.04, and Playwright 1.60 (our
lockfile) fails with `Playwright does not support chromium on
ubuntu26.04-x64`. Playwright 1.61 is the first release that knows
ubuntu26.04. This PR bumps `@playwright/test` to `^1.65.0` in
`desktop/`, `web/` and `admin-web/` and regenerates `pnpm-lock.yaml`. It
also pins every `ubuntu-latest` job in `ci.yml` and `_ci-*.yml` to
`ubuntu-26.04`, so the next runner image change arrives in a reviewed
diff. macOS and Windows jobs are unchanged.
The newer Chromium bundled with Playwright 1.65 changed two smoke specs.
It reports Tailwind's `items-end` as `align-items: flow-end`
(`doctor-states` now accepts `flex-end` or `flow-end`), and it draws the
textarea resize grip differently, so the
`workflow-template-variable-autocomplete` baseline is refreshed from the
ubuntu-26.04 CI output.
It also exposed a timing race in `profile.spec.ts` "owned agent profile
stays in parity": when the Message click lands while the profile panel
is still settling, Playwright's scroll-into-view retry scrolls the
profile body, which hides the owned-agent action row (aria-hidden +
inert) for good. The test now pins the body to the top and waits for the
row before clicking (12/12 repeats plus the full profile spec pass on
Linux).
## Verification
- `cargo clippy -p buzz-db -p buzz-relay --tests -- -D warnings` is
clean on
|
||
|
Tom Brow
|
60b7fb8178 |
fix(mobile): keep shortcut taps and the member picker from wedging (#9388)
Follow-up to review notes on [#9360 Home Screen shortcuts](https://github.com/block/buzz/pull/9360). These are fixes for rare races, with no visible change. - **The member picker can't wedge.** UIKit ignores a dismiss that arrives mid-transition (the sheet still animating in, or during an interactive swipe-down) and never runs its completion. The picker coordinator queues every later present behind that completion, so New DM and Add members then opened nothing for the rest of the session. Dismiss now waits for the transition to finish, then dismisses whatever is still presented. - **A shortcut tap reaches Dart once.** The native bridge both buffered a tap and sent it, so a tap during cold launch could arrive twice and run again after Home had already handled it. Now a tap is buffered only until Dart first takes the pending one, and after that it is sent directly. - **Signing out drops a waiting tap.** Removing Home clears a tap that is still waiting (for example on a Bestie that is still loading), so it can't run in the next account's Home. Not included: carrying the Bestie's pubkey in the shortcut item, so a stale "Message Alice" falls back to Agents rather than opening the current Bestie. It's optional, and it would change the bridge's payload shared with the lock screen widgets in [#9373 lock screen widgets](https://github.com/block/buzz/pull/9373). ### Validation - The Home shortcut journey gains a step: a tap waiting while the app is inactive is cleared when Home goes away. The step fails with the teardown guard removed. - Automated simulator run (iPhone 17 Pro, iOS 27, signed in to a Builderlab test community), driving the app icon's quick actions on the Home Screen: - New DM from a conversation opens the picker. New DM again, with the picker already open, replaces it. New chat over the picker closes it and opens a draft, and New DM after that opens the picker again (it doesn't get stuck). - Message (Bestie) opens the Bestie conversation. - Cold launch through New chat opens exactly one New chat screen. Back returns to Messages. buzz-review-completed Signed-off-by: Tom Brow <tomb@squareup.com> Co-authored-by: Tom Brow <tomb@squareup.com> Co-authored-by: Claude Opus 5.5 <noreply@anthropic.com> |
||
|
Tom Brow
|
defc2d5ea3 |
fix(mobile/ios): close notification code blocks only at line-ending fences (#9349)
Follow-up to [#9346 notification message text](https://github.com/block/buzz/pull/9346), from [Kyle's review](https://github.com/block/buzz/pull/9346#discussion_r4539634396). A fenced code block that contains three backticks, such as a `"```"` string literal, closed at those backticks. The rest of its code then got the prose rules, so `"**literal**"` lost its asterisks in the notification. A fenced block now closes only at a fence at least as long as its opening fence that ends its line, as in CommonMark and the in-app preview. Along the way, fences the old regex handled loosely are now consistent with the app: a block fenced with four or more backticks keeps its code (and can hold a three-backtick fence), and a block's opening line is dropped as its language even when it contains a backtick. A one-line fenced span (`` ```just ci``` ``) and an unclosed fence running to the end of the text, on one line or several, are unchanged. **What gets better, what doesn't get worse:** code inside a fenced block now shows exactly as written. The change is one regex in the notification body function, and every existing shared case still passes. ### Validation - Added tests: six shared cases in `test-fixtures/notification-body.json`: backticks inside a block don't close it, a closing fence at the end of the last code line closes the block, a four-backtick block keeps its code, a four-backtick block can hold a three-backtick fence, an unclosed one-line fence runs to the end, and an opening line with a backtick is dropped. All 112 BuzzPushKit XCTest cases and the Swift Testing suite pass. - No visible change outside notification text for fenced code, so there are no new screenshots. Human testing is waived; the shared-case run covers the changed behavior. 🤖 Generated with [Claude Code](https://claude.com/claude-code) --------- Signed-off-by: Tom Brow <tomb@squareup.com> Co-authored-by: Tom Brow <tomb@squareup.com> Co-authored-by: Claude Opus 5.5 <noreply@anthropic.com> |
||
|
John Matthew Tennant
|
432df8aa52 |
fix(media): run thumbnail regeneration tests in CI and cap rebuild pixels (#9198)
## Summary Two gaps in the thumbnail regeneration from [#9174](https://github.com/block/buzz/pull/9174): - **Its MinIO tests never ran in CI.** `api::media::tests::postgres_tests::external_infra_minio_tests` is excluded from the PostgreSQL lane, which skips `external_infra*` modules, and the backend integration job's only media MinIO step selects the admin tests. A sibling step now runs them against the same Postgres and MinIO. - **Rebuilding a thumbnail skipped the 25 MP pixel cap.** Upload validation rejects images over 25 megapixels before they reach the decoder. A thumbnail rebuilt from a stored original goes straight to `generate_image_metadata_sync`, so that cap didn't apply. The check is now a shared `check_image_pixels` that upload validation and thumbnail generation both run before decoding. On a rebuild, an oversized original gets the same 404 as any other regeneration failure. ### Related issue Follow-up to [#9174](https://github.com/block/buzz/pull/9174), from its review. ### Testing - `missing_thumbnail_is_not_regenerated_when_unsafe` now stores a valid 5001x5000 PNG as an image original without thumbnails and requests one through the media route. On `main` the relay rebuilds and serves it; with this change the request is a 404 and no thumbnail is written. - The new CI step runs both `external_infra_minio_tests` cases one at a time, since they share the fixture image's storage keys. 🤖 Generated with [Claude Code](https://claude.com/claude-code) --------- Signed-off-by: John Tennant <jtennant@squareup.com> Co-authored-by: Simone <0828be588d5c9c4d092c5b1cf01761d5aef63d6b104807fd8e8284d517dd1a99@buzz.block.builderlab.xyz> Co-authored-by: Claude Opus 5.5 <noreply@anthropic.com> |
||
|
Tom Brow
|
4a101752fb |
fix(mobile): never show emoji shortcodes in reaction pills (#9411)
## Context A reaction slot should never show an emoji shortcode as text. Today it does in two cases: - An agent's reaction is a kind 7 event with content `:shortcode:` and no NIP-30 `emoji` tag, so the pill printed `:approve:` in tiny text instead of the community emoji. - A custom emoji whose image fails to load fell back to the shortcode text. ## Behavior - A tagless `:shortcode:` reaction resolves against the community custom-emoji palette and renders that image. An `emoji` tag on the event still wins. - A shortcode with no palette entry, or whose image fails to load, shows a neutral placeholder glyph (the muted sparkles icon) instead of text. The shortcode survives only as the semantics label. - This applies to every reaction slot: the timeline pills, the combined reaction tray, the Flutter reaction detail sheet, and the native iOS reactions sheet (which is told which shortcodes have no image, so `NativeMessageGlyph` draws the placeholder). System-message rows reuse the same reaction row. - Unicode emoji are unchanged. The icon is the existing `BuzzIcons.sparkles`. Pareto note: the palette lookup is the shared `reactionEmojiUrl` helper, so there is no new resolver, and the pill only watches the palette when the reaction has no tag. ### Validation - `just mobile-check mobile-test`: format and analyze clean; full suite passes (4773 passed, 74 skipped). - New widget tests (journeys, in `reaction_row_test/shortcode_tests.dart`): a tagless known shortcode renders its image; an unknown shortcode and a failed image render the placeholder and never the text; unicode is unchanged; the native sheet payload marks image-less shortcodes. Reverting the fix makes both new journeys fail. - iOS: added a Swift unit test for the native glyph placeholder (`NativeMessageImageLoaderTests`); not run locally, the app run below exercises the same code. - Automated app run on a cloned iOS simulator with a fixture entry point (mocked media, synthetic palette): confirmed the pills before and after, and opened the reaction sheet from a long-press to confirm the placeholder renders there too. The clone was deleted afterwards. ## Before / after Captures use synthetic shortcodes and a synthetic palette. <img width="300" alt="reaction-pills-before" src="https://raw.githubusercontent.com/block/buzz/75b22a00d92df2db389ef90d35d476b285b60374/pr-9411--reaction-pills-before.png"> <img width="300" alt="reaction-pills-after" src="https://raw.githubusercontent.com/block/buzz/75b22a00d92df2db389ef90d35d476b285b60374/pr-9411--reaction-pills-after.png"> Reaction sheet after: <img width="300" alt="reaction-sheet-after" src="https://raw.githubusercontent.com/block/buzz/75b22a00d92df2db389ef90d35d476b285b60374/pr-9411--reaction-sheet-after.png"> 🤖 Generated with [Claude Code](https://claude.com/claude-code) Signed-off-by: Tom Brow <tomb@squareup.com> Co-authored-by: Tom Brow <tomb@squareup.com> Co-authored-by: Claude Opus 5.5 <noreply@anthropic.com> Co-authored-by: studio <dc2fc481343672df31a689840c09299972e704dac592e0da6f18486646a7ee3e@buzz.block.builderlab.xyz> |
||
|
Michael Fransen
|
2f792c2f6b |
fix(mobile): isolate channel header scroll rebuilds (#9400)
## Summary Improve scrolling performance in the Messages channel list by avoiding unnecessary inventory rebuilds as the header moves. Keep scroll-driven header state in a notifier and retain the inventory while the header animates. Provider and parent updates still rebuild the inventory with current channel data. This complements the lazy-row optimization in #9401. In manual iPhone runs with 500 channels, adding lazy rows on top of header isolation reduced maximum observed Flutter UI work from **65.5 ms to 4.2 ms**. That measurement reflects the added lazy-row change; no standalone performance gain was established for header isolation. This is an independent production-only change. Test fixtures and diagnostic instrumentation are excluded; regression checks were run locally and are not included in this PR. ### Related issue Related: #5911 addresses scrolling behavior inside conversations. This change addresses header-triggered rebuilds in the Messages channel inventory. No matching open PR or issue was identified in the focused duplicate search. ### Testing Exercised Messages on a physical iPhone with 500 channels against an isolated local relay. Header collapse and channel updates worked. This change alone did not remove the large scroll stalls; lazy section rows are a separate change. The device run preceded the refresh onto current main. Local-only regression checks passed 10 tests on this independent branch. They verify stable inventory identity during header movement and visible channel updates. These checks are excluded from the commit. Remaining visible jumps are under investigation; this PR does not claim to resolve them. Generated with Codex Signed-off-by: Michael Fransen <mfransen@squareup.com> Co-authored-by: Karl <9e8471f7b792e46c9c100840959dc71c660786c79c2a3165dbcaf58f52c4266e@buzz.block.builderlab.xyz> |
||
|
Michael Fransen
|
2636e986a0 |
fix(mobile): build channel section rows lazily (#9401)
## Summary Improve scrolling performance in the Messages channel list by building Solo and Team rows only as needed. Sections currently mount all their rows as one scroll item, which causes long UI stalls with large channel lists. In manual iPhone runs with 500 channels, maximum observed Flutter UI work fell from **65.5 ms to 4.2 ms** after adding lazy rows to a build with header isolation (#9400). The tester reported much smoother scrolling. This was an exploratory comparison with different gestures, not a controlled benchmark of this independent branch. Use stable channel keys and retain section controls, sorting, and collapse animations. Clip the sliver extent during collapse so the animation does not mount the entire section. The shared transition supports downward vertical lists. This is an independent production-only change. Test fixtures and diagnostic instrumentation are excluded; regression checks were run locally and are not included in this PR. ### Related issue Related: #5911 addresses scrolling behavior inside conversations. This change addresses eager row mounting in the Messages channel inventory. No matching open PR or issue was identified in the focused duplicate search. ### Testing On a physical iPhone with 500 channels against an isolated local relay, maximum Flutter UI work fell from 65.5 ms to 4.2 ms after adding lazy rows to a build that already isolated header rebuilds. The tester reported much smoother scrolling. Gestures differed between runs, so this is not a controlled benchmark or an isolated measurement of this branch on its own. The device run preceded the refresh onto current main. Local-only regression journeys passed 12 tests on this independent branch. They cover page laziness and updates, variable-height rows, large text, the last row, collapse reversal, reduced motion, and semantics. These checks are excluded from the commit. Smaller visible jumps remain under investigation; this PR does not claim to resolve them. Generated with Codex --------- Signed-off-by: Michael Fransen <mfransen@squareup.com> Signed-off-by: Tom Brow <tomb@squareup.com> Co-authored-by: Karl <9e8471f7b792e46c9c100840959dc71c660786c79c2a3165dbcaf58f52c4266e@buzz.block.builderlab.xyz> Co-authored-by: Tom Brow <tomb@block.xyz> Co-authored-by: Tom Brow <tomb@squareup.com> Co-authored-by: studio <dc2fc481343672df31a689840c09299972e704dac592e0da6f18486646a7ee3e@buzz.block.builderlab.xyz> |
||
|
Blake McAnally
|
745d2a86e0 |
fix(cli): treat a retried sidebar write the relay already stored as success (#9202)
Follow-up to #9191. It addresses the review findings that came in as that PR merged. ## Summary **A retried write was reported as a conflict.** This was found by the Codex security review on #9191 (LOW). - `BuzzClient::submit_event` can resend the same signed event after an ambiguous attempt, for example a timeout after the relay stored it. - The relay answers that resend `accepted: true, message: "duplicate:"`. `publish` turned any `duplicate:` into exit 5 with "a newer update won; run the command again". - If you ran `buzz sidebar sections create` again, you got a second section. On a `duplicate:` reply, `publish` now re-reads the head from the writer (`consistency: strong`). It reports success only when the head is the event it signed. The check is safe because `replace_parameterized_event` returns `was_inserted = false` for both an exact-id duplicate and a stale (dominated) write. Only a stored event can be the head with our id, so a dominated write still exits 5. **Unknown keys are dropped on decode.** This was raised by joahg on #9191. The module docs now state the limitation and why it is safe: - Buzz Desktop (`block/buzz-app`, `validate_sidebar_payload`) refuses to sign a document with unknown keys, so a new field needs a new `meta.v`. - `decode` refuses an unknown `meta.v`. The commands then neither read nor overwrite that head. ## Not changed joahg also noted the lost-update window between the head read and the submit. That window is documented in `crates/buzz-cli/README.md` (from #9191). A kind:30078 replaceable event has no compare-and-set on the relay, so the CLI cannot detect the case. A test would only check the fake relay's replace rules. ## Testing - `cargo test -p buzz-cli`: 665 pass. `cargo clippy -p buzz-cli --all-targets -D warnings` and `cargo fmt --check` are clean. - New test: `a_retry_of_a_stored_write_is_success`. The fake relay stores the event and answers `duplicate:`. The test fails without the fix (`Conflict("a newer sidebar sections update won; run the command again")`). - `a_dominated_write_is_a_conflict` now seeds a newer head under the caller's own key. Before, every conflict test had an empty own head, so a looser check (`Some(_)`) still passed. The test now fails under that change. - An agent review ran. It found that gap in the dominated-write test, which is now fixed. Its remaining notes are optional. ### Manual test steps The retry path needs a lost relay response, so you cannot easily trigger it by hand. These steps check that normal writes did not change: 1. Run `cargo build -p buzz-cli`. Then set `BUZZ_RELAY_URL` and either pair with Buzz Desktop (`buzz auth desktop pair`) or set `BUZZ_PRIVATE_KEY`. 2. Run `buzz sidebar sections list` and save the output. 3. Run `buzz sidebar sections create --name "Retry test"`. Expected: `"accepted": true`, a non-null `event_id`, and a `section_id`. 4. Run `buzz sidebar sections delete --section "Retry test"`. Then run `list` again. Expected: the same output as step 2. 🤖 Generated with [Claude Code](https://claude.com/claude-code) Signed-off-by: Blake McAnally <bmcanally@squareup.com> Co-authored-by: Claude Opus 5.5 <noreply@anthropic.com> |
||
|
Will Pfleger
|
fc8c802253 |
feat(workflow): add owner-only agent mentions for workflow messages (#9227)
Adds owner-only agent mentions, a relay setting,
`BUZZ_WORKFLOW_AGENT_MENTIONS`. Its values are `any`, the default and
today's behaviour, and `owner`. Any other value fails startup. With
`owner`, a workflow message can direct an agent only if the run's cause
and definition allow it. The setting is relay-wide.

**Recording what caused each run.** `workflow_runs` gets `cause_source`
and `cause_pubkey` columns. Migration `0087` adds them with named checks
marked `NOT VALID`, so it does not scan existing rows under its lock;
`0088` validates the checks separately. `create_workflow_run` now takes
a required `RunCause`, so every place that creates a run has to set one:
- **Event trigger:** the cause is the signer of the message, reaction or
diff. For a reaction, that is the reactor, not the author of the message
being reacted to.
- **Cron and interval schedules:** the cause is the timer.
- **Webhook:** the caller is unknown.
- **Manual trigger:** the cause is the invoking pubkey.

Rows written before this change have no cause. A stored source without
the pubkey it requires, or with one it forbids, is read as no cause.

**Deciding eligibility.** A run's messages may direct agents only when
all of these hold:
- the cause is a schedule, or an event or manual trigger whose pubkey is
the workflow owner's;
- every step of the definition that is running is `send_message` or
`delay`. This is an allowlist, so any other action, including one added
later, makes the definition ineligible, even when an `if:` skips that
step;
- the run did not resume after an approval.

Webhook runs and runs with no recorded cause are never eligible. The
executor decides this from `WorkflowConfig::agent_mentions`, and passes
`ActionSink::send_message` the owner's stored step text with a
`may_direct_agents` flag. The sink adds `buzz:workflow-mention` tags
only when the flag is set, and returns `SentMessage { event_id,
agent_mentions_withheld }`, which is true only when it left out a tag
that a member named in both the stored and rendered text would otherwise
have received. Webhook and manual runs start through `execute_run`, so
`execute_from_step` is used only to resume after an approval.

**The gate.** With `owner`, the relay adds `buzz:workflow-mention` only
to messages from eligible runs. Messages from other runs still post with
their plain `p` tags and still notify people. With `any`, mention tags
are added exactly as before.

**Making it visible.** When a `send_message` step leaves the tags out:
- its output in the run trace gets `"agent_mentions": {"withheld": true,
"reasons": [...]}`, listing each reason that applies: `cause` (not
started by the owner or a timer), `steps` (a step other than
`send_message` or `delay`), `resumed` (resumed after an approval). The
key is absent when nothing was withheld. The trace is what the app's run
history shows;
- the relay logs it at info level under the
`buzz_relay::workflow_agent_mentions` target (visible under the default
filter) with the community, workflow, run, step and reasons;
- the counter `buzz_workflow_agent_mentions_withheld_total` increases
once per reason, labelled `reason`.

**Discovery.** The NIP-11 document always carries
`"workflow_agent_mentions": "any" | "owner"`, so a missing field means
an older relay.

`NOSTR.md` now specifies `buzz:workflow-mention` for clients: what the
tag means, the checks an agent makes before acting, that a relay may
leave it out under a policy, and the NIP-11 `workflow_agent_mentions`
field. The relay policy itself is in the new operator guide,
`docs/operator-workflow-agent-mentions.md`: the setting and its values,
what counts as a run's cause for each trigger, which steps are allowed,
the trace key, the log and metric, the NIP-11 field, when to use
`owner`, rollout across pods, and what it doesn't cover. The
`TESTING.md` and `.env.example` entries link to it.

---------

Signed-off-by: Will Pfleger <wpfleger@block.xyz>
Co-authored-by: Duncan <dcfd242e557282d7a1e2cf2e6877522682f1e5c6156dc92ca7d90eaedd3b0f95@buzz.block.builderlab.xyz>
mobile-v1.1.0-rc.2
|
||
|
klopez4212
|
cb69ad9e4f |
Adapt iPhone Duo layouts, rail navigation, and native sheets (#8568)
Duo keeps conversations and Settings details open across closed, book and flat postures. Book mode splits at the fold; flattening restores the sidebar. Native rail controls, full-width navigation backdrops and sheet-local safe areas keep content aligned. Ordinary iPhones remain single-pane in portrait and landscape; tablet and Duo split layouts remain enabled. Includes the recovered preview's matching pane widths, Buzz empty-pane mark, stable Settings chevrons, Bestie pane routing and Duo-only upward New menu attachment. Current main's Activity redesign, Search content fade and unread-navigation button are retained. Menu selection checks sit beside their labels. Shared mobile changes remain in scope: the native iOS status editor, Appearance preview layout, avatar crop preservation, onboarding footer layout, profile/invite sheet geometry and nested conversation navigation. This PR is not exclusively Duo-gated. Nested navigator observers preserve recording cancellation and navigation callbacks; crop resizing preserves the selected image region. iOS 27.1 APIs remain compile-time and runtime gated. Validation on the reconciled source: Flutter analysis, Activity/Home journeys, the full mobile test suite, file-size checks and Swift package tests. The iPhone single-pane fix was also exercised on an iPhone 18 Pro simulator before reconciliation. Fresh hosted CI and physical-device confirmation of the reconciled build are separate and remain pending. --------- Signed-off-by: kenny lopez <klopez4212@gmail.com> Signed-off-by: Tom Brow <tomb@squareup.com> Co-authored-by: Terp <5856f6900e8e0a4e0ea1f4f8d2ee33e4753d2119bc122f94ecafc660b46c0511@buzz.block.builderlab.xyz> Co-authored-by: Claude Opus 5.5 <noreply@anthropic.com> Co-authored-by: Tom Brow <tomb@block.xyz> Co-authored-by: Tom Brow <tomb@squareup.com> |
||
|
klopez4212
|
5f81803cb1 |
End last-human agent Huddles and preserve mobile transcript access (#9375)
## Summary Leaving an agent DM Huddle previously skipped client lifecycle cleanup, allowing Join to remain visible while the relay waited for the agent. Apply the existing last-human rule to DMs: release audio first, then publish the ending and archive when the human count is at most one. Preserve the existing additional-device and same-Huddle rejoin guards. Retain DM membership when other humans remain so hanging up does not revoke transcript access. Offer **View** only when cached backing-room membership confirms transcript access, opening the original Huddle transcript and reply threads without joining audio. Non-members retain disabled Ended. Preserve Open for an active local session even when an ended event arrives. For admitted or just-left Huddles, switching/removing a community retires pending remote finalization and waits for local audio teardown. Generation guards prevent retired count/end results from launching follow-up writes or interfering with a later call. Existing in-flight Huddle-start rollback behavior is unchanged. Client only; remote relay finalization is separate in #9376. Human counts use backing-channel membership; known duplicate owner admissions prevent client cleanup. Concurrent device arrivals are not made atomic by this client-only change, and human-to-human DMs with retained memberships still rely on relay finalization. ### Related issue Split from the combined Huddle repair at the author's request. Searched open Huddle issues/PRs; no exact duplicate found for this mobile behavior. ### Testing Follow-up fixes are in `7f28dc486`; merged current main in `7a592f19d`. Required push checks pass on the merged head. - Mobile formatting, analysis, and full suite passed (4,705 tests, 71 skipped; supplementary suites: 4 and 27). - DM hangup journey covers sole-human ending, preservation of another owner device, and preservation of membership when another human remains. Existing rejoin/lifecycle regressions remain in the full suite. - View journey reads the original transcript and opens a server-only reply-thread summary without joining audio. - Mutation checks: restoring the DM cleanup exemption fails the last-human journey; removing thread summaries fails View navigation. Restored production code passes. - Independent review completed; follow-up review of the three blocking fixes found no remaining blockers. - Follow-up regressions cover live-call Open after an ended event, reactive history membership revocation, stalled count/end requests during community transition, and background teardown of a later call while retired cleanup is unresolved. Phone/human validation remains pending. Start an agent DM Huddle and leave from the last human device: its card should stop offering Join. Tap View to read the transcript and replies. Repeat with another device still in the Huddle and verify it stays open. Not deployed. --------- Signed-off-by: kenny lopez <klopez4212@gmail.com> Co-authored-by: Terp <5856f6900e8e0a4e0ea1f4f8d2ee33e4753d2119bc122f94ecafc660b46c0511@buzz.block.builderlab.xyz> |
||
|
Luke Tornquist
|
aa9b44ef36 |
buzz-db: pin explicit FK-child cleanup and same-workflow fire links (#8317)
> Builds on #8219 (merged); rebased onto `main` at `93ffc37cb` (includes the rustls bump, #8319). ## What This closes the identified debt from #8212. Every remaining `ON DELETE CASCADE` / `SET NULL` foreign key was audited against every supported way its parent row gets removed, with FK actions retired in the per-test schema (`test_support::retire_foreign_key_delete_actions`). One production change was needed. The rest is already explicit and is now covered by tests. **Production change:** `attach_scheduled_workflow_run` (`store/workflow.rs`) now links a scheduled fire only to a run of the **same** workflow (`EXISTS` on `(community_id, workflow_id, id)` in the existing admitted `UPDATE`). Before this, a fire for workflow B could reference a run of A. That FK is already `NO ACTION`, so the link would block A's explicit run delete. The only production caller (`buzz-workflow` cron tick) attaches the run it just created for the same workflow, so live behavior is unchanged. A mismatched attach now returns `false` like any other non-match, and the caller already treats that as best-effort. ## FK audit (all 12 delete actions) | Child FK | Action | Parent removal path → handling | |---|---|---| | `scheduled_workflow_fires → workflows` | CASCADE | Workflow delete removes fires explicitly (#8212) | | `workflow_runs → workflows` | CASCADE | Explicit (#8212) | | `workflow_approvals → workflows` | CASCADE | Explicit (#8212) | | `workflow_approvals → workflow_runs` | CASCADE | Explicit, including cross-workflow approvals (#8212) | | `join_policy_acceptances → relay_members` | CASCADE | Explicit (#8212) | | `channel_members → channels` | CASCADE | Single-channel removal is a soft delete. The community purge deletes members before channels. **Pinned here.** | | `personal_read_frontiers → personal_read_accounts` | CASCADE | No single-account hard delete exists. The purge deletes frontiers before accounts. **Pinned here.** | | `personal_read_frontiers → channels` | CASCADE | Same as above. **Pinned here.** | | `users.agent_owner_pubkey → users` | SET NULL | The only production hard delete of users is the purge deleting all of a community's users in one statement. **Pinned here** (owner + owned agent). No single-user hard delete exists. | | `product_feedback → communities` | SET NULL | Communities are tombstoned, never hard-deleted. The purge already nulls feedback `community_id` explicitly. **Pinned here.** | | `community_deletion_manifest_keys → community_deletion_requests` | CASCADE | Requests are retained. `mark_logically_verified` deletes chunks explicitly, and the chunk guard trigger is unchanged. **The existing lifecycle test now runs with FK actions retired.** | | `community_deletion_executor_heartbeats → community_deletion_requests` | SET NULL | Requests are retained, so this action is never reached. **Pinned here:** the heartbeat stays linked through the purge. | Audit method: searched `crates/**/*.rs` for `DELETE FROM` against each parent table. Every direct `DELETE FROM communities` / `users` hit is in `#[cfg(test)]` fixtures. Production removes rows only through the scoped purge loop in `store/deletion.rs` and the channel soft delete in `store/channel.rs`. **Not added:** per-parent delete APIs. They would duplicate the community purge for parents that are never hard-deleted. I also left out a source-text "no hard delete" policy test, because it would pass without any production fix. If a single-user, channel, read-account, request or community hard delete is ever added, it has to clear `agent_owner_pubkey` (only that column) and delete these children explicitly first. ## Tests - `attach_rejects_run_from_another_workflow`: a claim for B can't be linked to A's run, and the fire stays unlinked. - `purge_removes_fk_children_explicitly_without_fk_actions`: on the retired-FK schema, `channel_members` and `personal_read_frontiers` children are seeded through an admitted transaction, and then the production quiesce → fence → purge runs. Every child must be deleted explicitly, both users must be removed, feedback must survive with `community_id = NULL`, and the retained request's heartbeat (selected by `executor_id`) must stay linked. The quiesce barrier against open admitted writers is already pinned by `begin_quiescing_waits_for_open_admitted_writer_note_update`; this test does not re-claim it. - `manifest_key_chunks_bind_freeze_execution_and_cleanup` now retires FK actions first. Each test was checked to fail when its production behavior is removed: dropping the `EXISTS` guard, dropping `personal_read_frontiers` from the purge order (`23503`), dropping feedback provenance clearing, and dropping the explicit manifest chunk delete. All four failed as expected. ## What got simpler The production change is one predicate. No new concepts or APIs. The FK audit is now settled, so the follow-up migration can drop all 12 actions at once. No new delete code was needed. **Identified debt (pre-existing, outside this diff):** the cron tick in `buzz-workflow/src/lib.rs` logs only `Err` from `attach_scheduled_workflow_run`; an `Ok(false)` (no matching unlinked claim) leaves the fire unlinked without a trace. **Identified debt (unrelated, pre-existing):** `writer_pool_rejects_non_read_committed_database_default` hangs with no active query on clean `177551dda` as well (bounded after ~270 s on both checkouts). ## Verification (Blox, at the exact tree of this commit) | Gate | Result | |---|---| | `cargo fmt --all -- --check` | pass | | `cargo clippy --workspace --all-targets -- -D warnings` | pass | | `cargo nextest run -p buzz-db --lib` | 166/166 | | `scripts/postgres-test-run.sh -p` buzz-admin / audit / deletion / push-gateway / relay / search / workflow | all rc 0 (4, 7, 11, 11, 402, 20, 2) | | `scripts/postgres-test-run.sh -p buzz-db` | 510 pass, 2 fail: the pre-existing hang above, plus one 150 ms `PoolTimedOut` in `routed_fallback_spends_one_acquire_budget_when_aurora_cache_is_cold` (pool setup under full-lane load; it passed on the clean-baseline lane and passes in isolation at this tree, 1/1 in 1.7 s) | The new tests are selected by the `postgres-ci` nextest filter `(test(/postgres_tests::/) or binary(/^postgres_/)) and not test(/(^|::)external_infra[^:]*::/)`. --------- Signed-off-by: Elrond <28d6302a099e5225b02c4155ac4236e4912603df2ab08dbfc2f4fef08ce598c8@buzz.block.builderlab.xyz> Signed-off-by: Luke Tornquist <tornquist@squareup.com> Co-authored-by: Elrond <28d6302a099e5225b02c4155ac4236e4912603df2ab08dbfc2f4fef08ce598c8@buzz.block.builderlab.xyz> Co-authored-by: Claude Opus 5.5 <noreply@anthropic.com> |