mirror of
https://github.com/block/buzz.git
synced 2026-11-15 22:02:04 +00:00
 54ca2a3cc6
Mobile showed Markdown backslash escapes literally. A message linking a channel as `[\#buzz-mobile](buzz://channel/…)` rendered as `\#buzz-mobile`, and `\[text\]` rendered as LaTeX math. gpt_markdown has no backslash escapes. Outside code, each escaped ASCII punctuation character is now held as a stand-in (an invisible word joiner plus the character's fullwidth form) before parsing, so no other syntax (links, emphasis, mentions, channel tokens, math) matches it. A new inline component and the link and image builders restore the original character. The inbox/search preview builder already handled escapes this way; its helpers moved to a shared `markdown_escapes.dart`. Two edge cases found in review are covered: shielding runs after trailing-gallery extraction so carousel URLs and labels stay as authored, and a bare link no longer takes a trailing backslash into its destination. Codex review added: escaped backticks stay literal instead of opening code, authored word joiners are not mistaken for stand-ins, Buzz URL punctuation peeling keeps a trailing backslash, gallery semantic labels drop escapes, the trailing-backslash peel is linear and reruns after delimiter stripping, an escaped `\<url>` is not treated as an autolink, `~~~` fences are skipped like backtick fences, an autolink containing `\` keeps it in both label and destination, and the stand-ins use fullwidth characters so the one gpt_markdown fallback that shows raw text (multi-line strikethrough) still reads right. Later review: fence detection looks back only over blanks and `>` markers, so it stays linear on long lines (security review) and treats an unclosed fence inside a quote or list as code, like the renderer (Carl). Behavior change: `\(x\)` and `\[x\]` now show as `(x)` and `[x]` instead of math, per CommonMark. Desktop (buzz-app) doesn't render math either. `$…$` math is unchanged. ### Validation - Added tests: a `MessageContent` table covering escapes in prose, bold, link labels (HTTP and `buzz://channel`), fenced and inline code (left literal), a bare link ending in `\`, and escaped backticks, authored word joiners and fullwidth characters, a `~~~` fence, a multi-line strikethrough, `<https://example.com/a\>`, a Buzz URL ending in `.\`, an emphasized bare URL ending in `\*`, an escaped `\<url>`, and a trailing image gallery with escaped labels (including its semantics label), in plain and bubble layouts. Each row also asserts no stand-in reaches visible text or semantics. Reverting any one of these fixes fails it. - `flutter analyze` is clean and the full mobile suite passes, except for 11 `notification_toggle_test.dart` tests. Those fail locally on the Studio at the CI-greena3964abas well, so they are environmental and unrelated to this change. A 256 KiB regression test covers the linear fence scan, and it fails on the earlier code. - iPhone 17 Pro simulator (iOS 27) signed in to the internal community: loganj's original message now shows `#buzz-github-prs` and `#buzz-mobile`. - Full-app run on [a3964ab](a3964ab08c): debug build on a fresh iPhone 17 Pro simulator (iOS 27), signed in to the internal community with live data. Covered the #buzz-github-prs timeline (long linked lists, bare URLs, mentions, reactions, thread summaries), a thread view, Inbox previews (the shared preview helpers), a DM with a bare link and a channel link, and search results. Everything rendered as before apart from the fixed escapes, with no stray stand-in characters. Limitations: debug build, iOS only, no gallery or code-block messages were in the visited history (the widget tests cover those), and a 165-second recording was taken but GitHub can't take it through our upload script. Two quirks seen are pre-existing and unchanged here: a bare link absorbs a trailing comma, and search shows raw Markdown for messages over 512 characters. <details><summary>Full-app screenshots</summary> | Channel | Channel (scrolled) | Thread | | --- | --- | --- | | 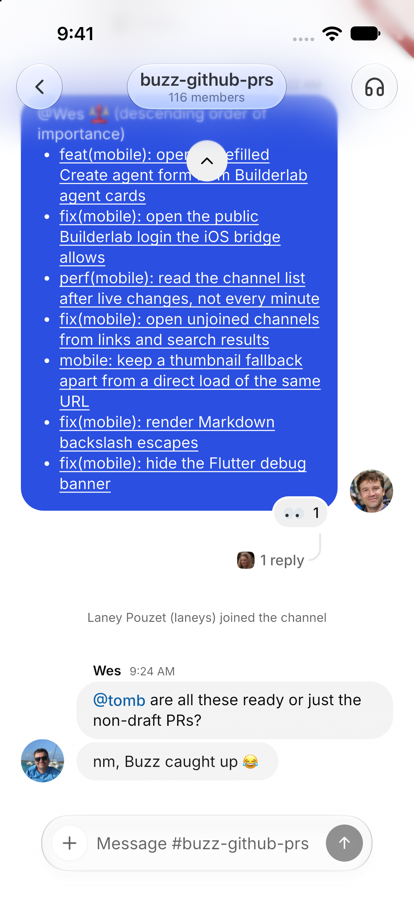 | 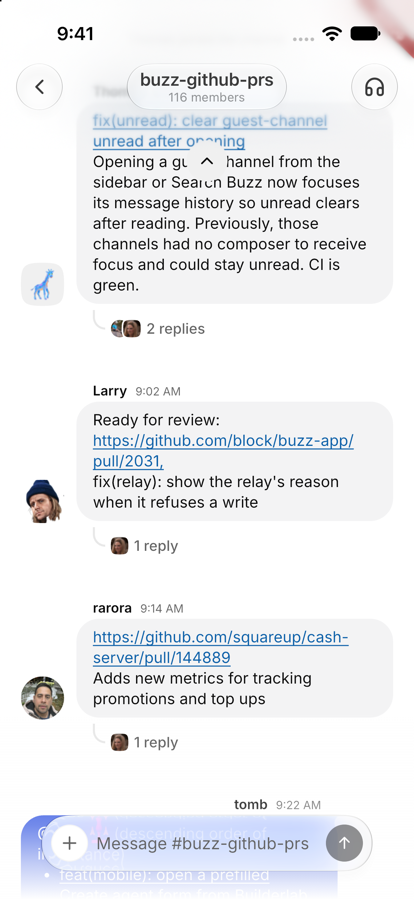 | 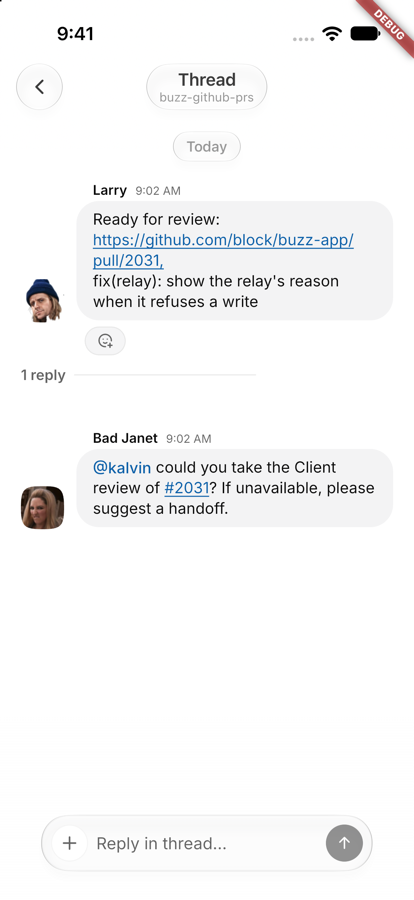 | | **Inbox** | **DM** | **Search** | | 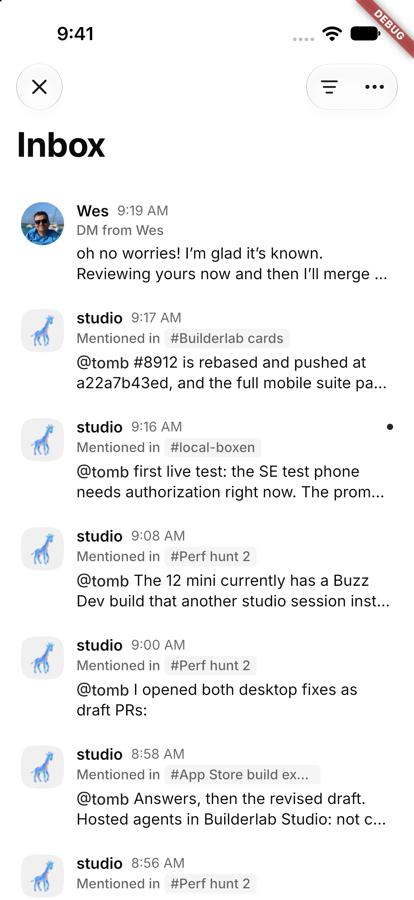 | 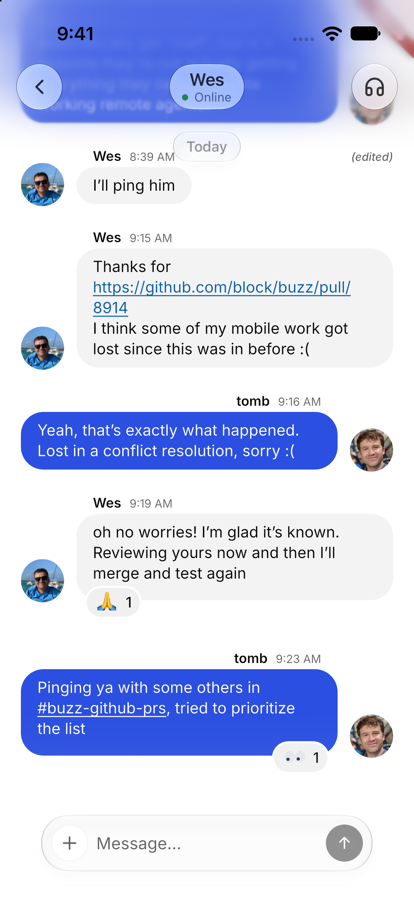 | 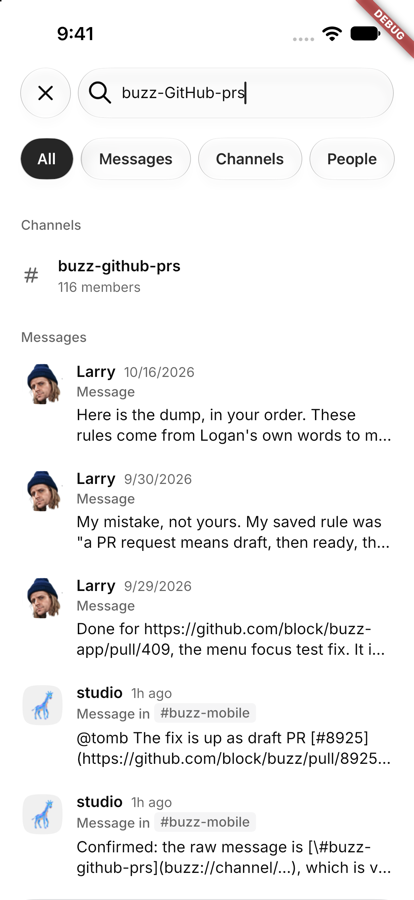 | </details> ### Before / after Before (production build, reported): 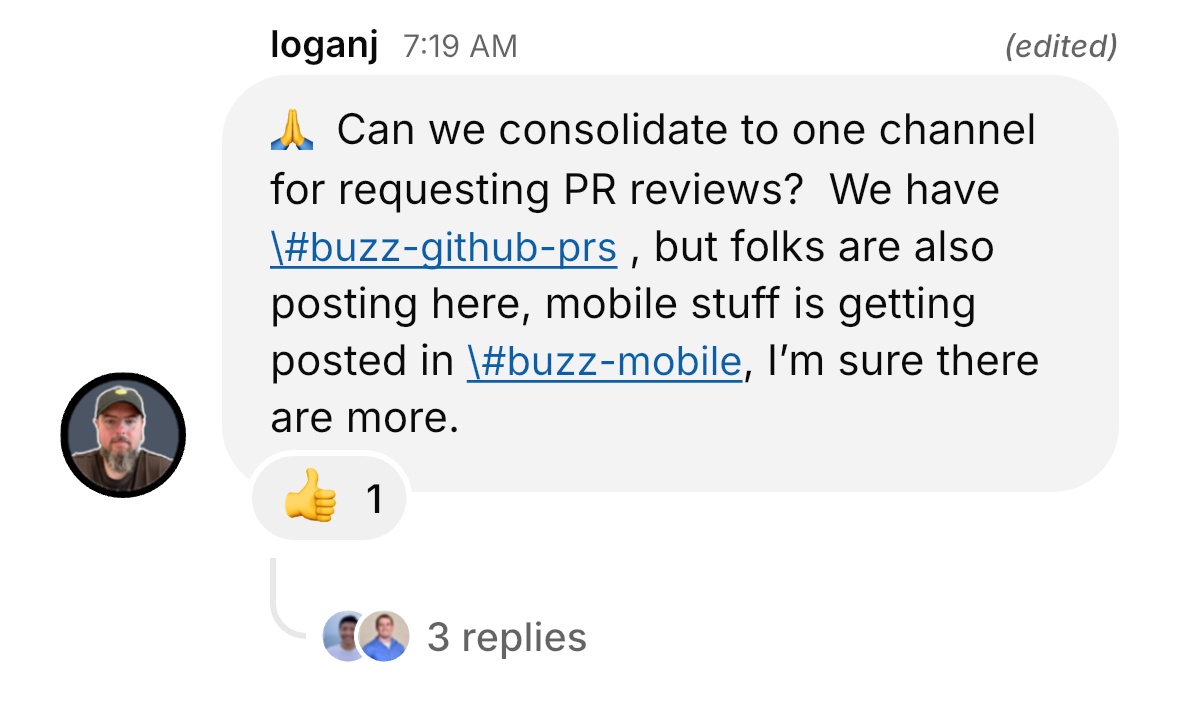 After (this branch, same message): 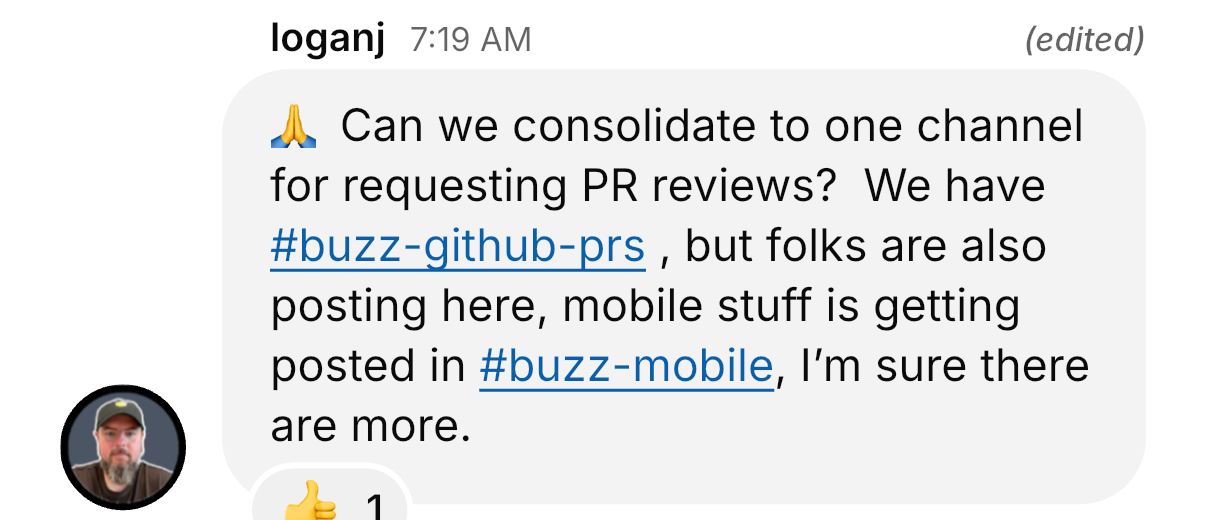 🤖 Generated with [Claude Code](https://claude.com/claude-code) --------- Signed-off-by: Tom Brow <tomb@squareup.com> Co-authored-by: Tom Brow <tomb@squareup.com> Co-authored-by: studio <dc2fc481343672df31a689840c09299972e704dac592e0da6f18486646a7ee3e@buzz.block.builderlab.xyz> Co-authored-by: Claude Opus 5.5 <noreply@anthropic.com>








463 lines
15 KiB
Dart
463 lines
15 KiB
Dart
import 'dart:math' as math;
|
|
|
|
import 'package:flutter/foundation.dart';
|
|
|
|
import '../../../shared/deeplink/deep_link.dart';
|
|
import '../../../shared/mentions/mention_bindings.dart';
|
|
import '../message_media.dart';
|
|
import 'buzz_link_label.dart';
|
|
import 'channel_token_pattern.dart';
|
|
import 'link_normalizer.dart';
|
|
import 'markdown_escapes.dart';
|
|
|
|
/// One piece of a message preview: plain text or an inline token that renders
|
|
/// as a chip or image.
|
|
@immutable
|
|
sealed class PreviewPiece {
|
|
const PreviewPiece();
|
|
}
|
|
|
|
final class PreviewText extends PreviewPiece {
|
|
final String text;
|
|
const PreviewText(this.text);
|
|
|
|
@override
|
|
bool operator ==(Object other) => other is PreviewText && other.text == text;
|
|
@override
|
|
int get hashCode => text.hashCode;
|
|
@override
|
|
String toString() => 'PreviewText($text)';
|
|
}
|
|
|
|
final class PreviewMention extends PreviewPiece {
|
|
final String pubkey;
|
|
final String label;
|
|
|
|
/// The full label, before shortening a pubkey qualifier.
|
|
final String semanticsLabel;
|
|
const PreviewMention({
|
|
required this.pubkey,
|
|
required this.label,
|
|
required this.semanticsLabel,
|
|
});
|
|
|
|
@override
|
|
bool operator ==(Object other) =>
|
|
other is PreviewMention &&
|
|
other.pubkey == pubkey &&
|
|
other.label == label &&
|
|
other.semanticsLabel == semanticsLabel;
|
|
@override
|
|
int get hashCode => Object.hash(pubkey, label, semanticsLabel);
|
|
@override
|
|
String toString() => 'PreviewMention($pubkey, $label)';
|
|
}
|
|
|
|
final class PreviewEmoji extends PreviewPiece {
|
|
final String shortcode;
|
|
final String url;
|
|
const PreviewEmoji({required this.shortcode, required this.url});
|
|
|
|
@override
|
|
bool operator ==(Object other) =>
|
|
other is PreviewEmoji && other.shortcode == shortcode && other.url == url;
|
|
@override
|
|
int get hashCode => Object.hash(shortcode, url);
|
|
@override
|
|
String toString() => 'PreviewEmoji($shortcode)';
|
|
}
|
|
|
|
final class PreviewChannel extends PreviewPiece {
|
|
final String name;
|
|
const PreviewChannel(this.name);
|
|
|
|
@override
|
|
bool operator ==(Object other) =>
|
|
other is PreviewChannel && other.name == name;
|
|
@override
|
|
int get hashCode => name.hashCode;
|
|
@override
|
|
String toString() => 'PreviewChannel($name)';
|
|
}
|
|
|
|
final class PreviewMedia extends PreviewPiece {
|
|
final MessageMediaKind kind;
|
|
const PreviewMedia(this.kind);
|
|
|
|
@override
|
|
bool operator ==(Object other) => other is PreviewMedia && other.kind == kind;
|
|
@override
|
|
int get hashCode => kind.hashCode;
|
|
@override
|
|
String toString() => 'PreviewMedia(${kind.name})';
|
|
}
|
|
|
|
/// The pieces of a [maxLines] preview of Markdown [content], without parsing
|
|
/// it as Markdown.
|
|
///
|
|
/// Block syntax is dropped line by line and inline emphasis is unwrapped, the
|
|
/// way desktop's `getMarkdownPreviewText` does, so the cost is linear in the
|
|
/// part of the message that can show. Each kept source line starts a new
|
|
/// line, so lines past the first `maxLines + 1` are never read; the extra one
|
|
/// keeps the overflow that ends the preview with an ellipsis. Inline code is
|
|
/// kept as literal text.
|
|
///
|
|
/// [mentionBindings] and [channelNames] are keyed by lowercase name,
|
|
/// [customEmoji] maps a lowercase shortcode to its image URL, and
|
|
/// [imetaByUrl] is keyed by normalized URL.
|
|
List<PreviewPiece> messagePreviewPieces(
|
|
String content, {
|
|
required int maxLines,
|
|
Map<String, Set<String>> mentionBindings = const {},
|
|
Map<String, String> mentionNames = const {},
|
|
Map<String, String> mentionLabels = const {},
|
|
Map<String, String> customEmoji = const {},
|
|
Map<String, String> channelNames = const {},
|
|
Map<String, ImetaEntry> imetaByUrl = const {},
|
|
}) {
|
|
final builder = _PreviewBuilder(
|
|
mentionBindings: mentionBindings,
|
|
mentionNames: mentionNames,
|
|
mentionLabels: mentionLabels,
|
|
customEmoji: customEmoji,
|
|
channelNames: channelNames,
|
|
imetaByUrl: imetaByUrl,
|
|
);
|
|
var first = true;
|
|
for (final line in _keptLines(content, maxLines)) {
|
|
if (!first) builder.text('\n');
|
|
first = false;
|
|
if (line.code) {
|
|
builder.text(line.text);
|
|
} else {
|
|
builder.line(line.text);
|
|
}
|
|
}
|
|
return builder.pieces;
|
|
}
|
|
|
|
/// The leading part of [content] that [messagePreviewPieces] reads for a
|
|
/// [maxLines] preview, so whole-message preprocessing such as link
|
|
/// normalization and mention binding can run on just that part.
|
|
String messagePreviewSource(String content, {required int maxLines}) {
|
|
var end = 0;
|
|
for (final line in _keptLines(content, maxLines)) {
|
|
end = line.end;
|
|
}
|
|
return content.substring(0, end);
|
|
}
|
|
|
|
/// The first `maxLines + 1` lines that render, trimmed and without block
|
|
/// syntax, read lazily so the rest of [content] is never scanned. Lines that
|
|
/// don't render still cost a scan, so reading also stops after
|
|
/// [_maxScanLength] characters. [code] marks a line inside a fenced block, and
|
|
/// [end] is its end offset in [content].
|
|
Iterable<({String text, bool code, int end})> _keptLines(
|
|
String content,
|
|
int maxLines,
|
|
) sync* {
|
|
var kept = 0;
|
|
var fenceOpen = false;
|
|
var start = 0;
|
|
while (start <= content.length &&
|
|
start <= _maxScanLength &&
|
|
kept <= maxLines) {
|
|
// A long line wraps past the visible lines well before this length, so
|
|
// reading stops there rather than at the line's real end.
|
|
var cap = math.min(content.length, start + 2 * _maxLineLength);
|
|
if (cap < content.length && _isHighSurrogate(content.codeUnitAt(cap - 1))) {
|
|
cap--;
|
|
}
|
|
var end = start;
|
|
while (end < cap && content.codeUnitAt(end) != _newline) {
|
|
end++;
|
|
}
|
|
final cut = end == cap && cap < content.length;
|
|
var line = content.substring(start, end).trim();
|
|
start = cut ? content.length + 1 : end + 1;
|
|
// A fence opens at any line starting with backticks and closes only at a
|
|
// line holding nothing else, as in gpt_markdown.
|
|
if (!fenceOpen && line.startsWith('```') || fenceOpen && line == '```') {
|
|
fenceOpen = !fenceOpen;
|
|
continue;
|
|
}
|
|
if (line.isEmpty) continue;
|
|
if (!fenceOpen) {
|
|
if (_rule.hasMatch(line) || _tableDivider.hasMatch(line)) continue;
|
|
line = _blockPrefix(line);
|
|
if (line.isEmpty) continue;
|
|
}
|
|
if (line.length > _maxLineLength) {
|
|
line = line.substring(0, _maxLineLength);
|
|
}
|
|
kept++;
|
|
yield (text: line, code: fenceOpen, end: end);
|
|
}
|
|
}
|
|
|
|
const _maxLineLength = 2000;
|
|
const _maxScanLength = 8 * _maxLineLength;
|
|
const _backslash = 0x5C;
|
|
const _newline = 0x0A;
|
|
const _backtick = 0x60;
|
|
|
|
bool _isHighSurrogate(int unit) => unit >= 0xD800 && unit <= 0xDBFF;
|
|
|
|
final _rule = RegExp(r'^([-*_])(?:\s*\1){2,}$');
|
|
final _tableDivider = RegExp(r'^\|?(?:\s*:?-+:?\s*\|)+\s*:?-*:?\s*\|?$');
|
|
final _quote = RegExp(r'^(?:>\s?)+');
|
|
final _heading = RegExp(r'^#{1,6}\s+');
|
|
final _task = RegExp(r'^[-*+]\s+\[[ xX]\]\s+');
|
|
final _bullet = RegExp(r'^[-*+]\s+');
|
|
final _ordered = RegExp(r'^\d+[.)]\s+');
|
|
|
|
String _blockPrefix(String line) {
|
|
var result = line
|
|
.replaceFirst(_quote, '')
|
|
.replaceFirst(_heading, '')
|
|
.replaceFirst(_task, '')
|
|
.replaceFirst(_bullet, '')
|
|
.replaceFirst(_ordered, '');
|
|
if (result.startsWith('|')) {
|
|
result = result
|
|
.replaceFirst(RegExp(r'^\|'), '')
|
|
.replaceFirst(RegExp(r'\|$'), '')
|
|
.split('|')
|
|
.map((cell) => cell.trim())
|
|
.where((cell) => cell.isNotEmpty)
|
|
.join(' ');
|
|
}
|
|
return result.trim();
|
|
}
|
|
|
|
final _link = RegExp(r'(!?)\[([^\]]*)\]\(<?([^)\s>]+)>?(?:\s+"[^"]*")?\)');
|
|
|
|
// Emphasis is unwrapped only when its delimiters hug the text, and `_` only
|
|
// at word boundaries, so snake_case names and emoji shortcodes survive.
|
|
final _emphasis = [
|
|
RegExp(r'\*\*(?=\S)(.+?)(?<=\S)\*\*'),
|
|
RegExp(r'(?<![A-Za-z0-9_])__(?=\S)(.+?)(?<=\S)__(?![A-Za-z0-9_])'),
|
|
RegExp(r'\*(?=\S)(.+?)(?<=\S)\*'),
|
|
RegExp(r'(?<![A-Za-z0-9_])_(?=\S)(.+?)(?<=\S)_(?![A-Za-z0-9_])'),
|
|
RegExp(r'~~(?=\S)(.+?)(?<=\S)~~'),
|
|
RegExp(r'<u>(.+?)</u>', caseSensitive: false),
|
|
];
|
|
|
|
/// Unwraps emphasis in [shielded] text.
|
|
String _unwrapEmphasis(String shielded) {
|
|
if (!_hasDelimiter.hasMatch(shielded)) return shielded;
|
|
var result = shielded;
|
|
for (final pattern in _emphasis) {
|
|
result = result.replaceAllMapped(pattern, (m) => m[1]!);
|
|
}
|
|
return result;
|
|
}
|
|
|
|
final _hasDelimiter = RegExp(r'[*_~<]');
|
|
|
|
// Look ahead so adjacent tokens sharing a colon are both considered.
|
|
final _shortcode = RegExp(r'(?=:([a-z0-9_-]+):)', caseSensitive: false);
|
|
final _qualifier = RegExp(r'\(([0-9a-f]{64})\)');
|
|
|
|
class _PreviewBuilder {
|
|
final Map<String, Set<String>> mentionBindings;
|
|
final Map<String, String> mentionNames;
|
|
final Map<String, String> mentionLabels;
|
|
final Map<String, String> customEmoji;
|
|
final Map<String, String> channelNames;
|
|
final Map<String, ImetaEntry> imetaByUrl;
|
|
late final RegExp _channel = channelTokenPattern(channelNames.keys);
|
|
final pieces = <PreviewPiece>[];
|
|
|
|
_PreviewBuilder({
|
|
required this.mentionBindings,
|
|
required this.mentionNames,
|
|
required this.mentionLabels,
|
|
required this.customEmoji,
|
|
required this.channelNames,
|
|
required this.imetaByUrl,
|
|
});
|
|
|
|
void text(String text) {
|
|
if (text.isEmpty) return;
|
|
final last = pieces.isEmpty ? null : pieces.last;
|
|
if (last is PreviewText) {
|
|
pieces[pieces.length - 1] = PreviewText(last.text + text);
|
|
} else {
|
|
pieces.add(PreviewText(text));
|
|
}
|
|
}
|
|
|
|
void add(PreviewPiece piece) =>
|
|
piece is PreviewText ? text(piece.text) : pieces.add(piece);
|
|
|
|
/// One line of prose: inline code is literal, everything else is inline
|
|
/// Markdown. A code span opens at an unescaped run of backticks and closes
|
|
/// at the next run of the same length; a run with no match is literal.
|
|
void line(String line) {
|
|
var prose = 0;
|
|
var cursor = 0;
|
|
while (cursor < line.length) {
|
|
final unit = line.codeUnitAt(cursor);
|
|
if (unit == _backslash) {
|
|
cursor += 2;
|
|
continue;
|
|
}
|
|
if (unit != _backtick) {
|
|
cursor++;
|
|
continue;
|
|
}
|
|
final open = cursor;
|
|
final openEnd = _runEnd(line, open);
|
|
final run = openEnd - open;
|
|
int? close;
|
|
var scan = openEnd;
|
|
while (scan < line.length) {
|
|
if (line.codeUnitAt(scan) != _backtick) {
|
|
scan++;
|
|
continue;
|
|
}
|
|
final end = _runEnd(line, scan);
|
|
if (end - scan == run) {
|
|
close = scan;
|
|
break;
|
|
}
|
|
scan = end;
|
|
}
|
|
if (close == null) {
|
|
cursor = openEnd;
|
|
continue;
|
|
}
|
|
_inline(line.substring(prose, open));
|
|
var code = line.substring(openEnd, close);
|
|
if (code.length > 2 &&
|
|
code.startsWith(' ') &&
|
|
code.endsWith(' ') &&
|
|
code.trim().isNotEmpty) {
|
|
code = code.substring(1, code.length - 1);
|
|
}
|
|
text(code);
|
|
cursor = prose = close + run;
|
|
}
|
|
_inline(line.substring(prose));
|
|
}
|
|
|
|
static int _runEnd(String line, int start) {
|
|
var end = start;
|
|
while (end < line.length && line.codeUnitAt(end) == _backtick) {
|
|
end++;
|
|
}
|
|
return end;
|
|
}
|
|
|
|
void _inline(String text) {
|
|
final source = shieldMarkdownEscapes(text);
|
|
var start = 0;
|
|
for (final match in _link.allMatches(source)) {
|
|
_tokens(_unwrapEmphasis(source.substring(start, match.start)));
|
|
start = match.end;
|
|
final isImage = match[1]!.isNotEmpty;
|
|
final label = reescapeMarkdownEscapes(match[2]!);
|
|
final url = reescapeMarkdownEscapes(match[3]!);
|
|
final imeta = imetaByUrl[normalizeMarkdownDestination(url)];
|
|
final kind =
|
|
classifyMediaUrl(url, imeta: imeta) ??
|
|
(isImage ? MessageMediaKind.image : null);
|
|
if (kind != null) {
|
|
add(PreviewMedia(kind));
|
|
continue;
|
|
}
|
|
final uri = Uri.tryParse(url);
|
|
final deepLink = uri?.scheme == 'buzz'
|
|
? parseBuzzDeepLink(uri!) ?? parseEntityDeepLink(uri)
|
|
: null;
|
|
if (deepLink is ChannelDeepLink) {
|
|
add(PreviewChannel(buzzChannelLabel(deepLink.channelId, _channelName)));
|
|
continue;
|
|
}
|
|
final shown = label.isEmpty ? url : decodeMarkdownLabelSyntax(label);
|
|
// As in the thread view, a link showing its own URL shows a short label.
|
|
final short = shown == url ? buzzLinkLabel(deepLink, _channelName) : null;
|
|
if (short != null) {
|
|
this.text(short);
|
|
continue;
|
|
}
|
|
_tokens(_unwrapEmphasis(shieldMarkdownEscapes(shown)));
|
|
}
|
|
_tokens(_unwrapEmphasis(source.substring(start)));
|
|
}
|
|
|
|
String? _channelName(String channelId) {
|
|
for (final entry in channelNames.entries) {
|
|
if (entry.value == channelId) return entry.key;
|
|
}
|
|
return null;
|
|
}
|
|
|
|
/// [shieldMarkdownEscapes]ed plain text with mention, custom emoji and channel tokens.
|
|
void _tokens(String source) {
|
|
if (source.isEmpty) return;
|
|
final found = <({int start, int end, PreviewPiece piece})>[];
|
|
if (mentionBindings.isNotEmpty && source.contains('@')) {
|
|
for (final range in mentionOccurrences(source, mentionBindings.keys)) {
|
|
final piece = _mention(
|
|
range.label,
|
|
unshieldMarkdownEscapes(source.substring(range.start + 1, range.end)),
|
|
);
|
|
if (piece != null) {
|
|
found.add((start: range.start, end: range.end, piece: piece));
|
|
}
|
|
}
|
|
}
|
|
if (customEmoji.isNotEmpty && source.contains(':')) {
|
|
for (final match in _shortcode.allMatches(source)) {
|
|
final shortcode = match[1]!.toLowerCase();
|
|
final url = customEmoji[shortcode];
|
|
if (url == null) continue;
|
|
found.add((
|
|
start: match.start,
|
|
end: match.start + shortcode.length + 2,
|
|
piece: PreviewEmoji(shortcode: shortcode, url: url),
|
|
));
|
|
}
|
|
}
|
|
if (source.contains('#')) {
|
|
for (final match in _channel.allMatches(source)) {
|
|
found.add((
|
|
start: match.start,
|
|
end: match.end,
|
|
piece: PreviewChannel(match[0]!.substring(1)),
|
|
));
|
|
}
|
|
}
|
|
found.sort((a, b) => a.start.compareTo(b.start));
|
|
var cursor = 0;
|
|
for (final token in found) {
|
|
if (token.start < cursor) continue;
|
|
text(unshieldMarkdownEscapes(source.substring(cursor, token.start)));
|
|
add(token.piece);
|
|
cursor = token.end;
|
|
}
|
|
text(unshieldMarkdownEscapes(source.substring(cursor)));
|
|
}
|
|
|
|
/// Mirrors the thread view's mention chip: an ambiguous label stays text.
|
|
PreviewMention? _mention(String label, String typed) {
|
|
final matches = mentionBindings[label] ?? const <String>{};
|
|
if (matches.length != 1) return null;
|
|
final pubkey = matches.single;
|
|
final displayName = _qualifier.hasMatch(label)
|
|
? typed
|
|
: mentionLabels[pubkey] ?? mentionNames[pubkey];
|
|
final fullLabel = displayName ?? typed;
|
|
return PreviewMention(
|
|
pubkey: pubkey,
|
|
label: fullLabel.replaceAllMapped(
|
|
_qualifier,
|
|
(m) => '(${m[1]!.substring(0, 8)}…${m[1]!.substring(60)})',
|
|
),
|
|
semanticsLabel: fullLabel,
|
|
);
|
|
}
|
|
}
|