mirror of
https://github.com/block/buzz.git
synced 2026-11-12 20:31:12 +00:00
a09b84d23d8c90f24ce5bec8a4e5259fd3a5b1f7
3422 Commits
| Author | SHA1 | Message | Date | |
|---|---|---|---|---|
 Joah Gerstenberg |
a09b84d23d |
feat(relay): agents cannot write in DMs except with their owner (#9371)
## Summary Agents stop writing in direct messages, except a DM with only their owner. This is the relay-side backstop for block/buzz-app#3261, which takes away the app agents' DM tools. An agent holding its own key could still sign DM events directly, and only the relay can stop that. A key counts as an agent when it has a stored owner (`users.agent_owner_pubkey`, written when the agent authenticates with a NIP-OA owner attestation). For those keys: - **Writes into a DM channel** are refused with `restricted: agents cannot post in direct messages; start a Solo chat that includes your owner instead`. The check sits in `check_channel_membership` for `ChannelWrite::Post`, so it covers stream messages, reactions, deletions, typing and other channel ephemerals, artifact moves and edit validation. Non-DM channels skip it at no extra cost. - **Workflow `send_message`** (which posts as the workflow owner and checks `may_post` directly) applies the same rule before persisting, so an agent can't route a DM post through a workflow. - **Put-user (9000) and edit-metadata (9002)** skip the generic gate, so they get their own check in a DM: an agent never adds DM members with 9000 (an addition to an owner-only DM always widens it), and edits topic or purpose only in its owner-only DM (the edit posts a system message with the text). - **Huddle admission** checks `may_post` directly, so it applies the same rule to the huddle channel and its lifecycle parent. - **DM open (41010) and DM add-member (41011)** are refused unless the resulting participant set is exactly the agent and its owner. - **Exemption:** a DM whose live members are exactly the agent and its owner stays open (for example, a personal assistant's home chat). - Lookup failures fail closed. Confirmed agent owners are cached per community (`agent_owner_cache`, 5 min TTL). The link is first-write-wins and never changes once set. A missing link is never cached, because another relay process may write it later. `link_agent_owner` primes the cache. Humans are unaffected: they can still open DMs that include an agent and post in them. The agent answers elsewhere. Not covered: - A key that never presented an owner attestation has no stored owner and looks human. - The huddle join commit re-check (4e) doesn't repeat the DM rule; the pre-join admission check enforces it. - Agents also can't delete their own earlier messages in a non-owner DM via kind 5, since deletions pass the same `Post` gate. ### Related issue Companion to block/buzz-app#3261. AGNTOPS-780. ### Testing New Postgres ingest tests (`handlers::ingest::postgres_tests::agent_*`), run locally: - An agent is refused in a 1:1 DM with someone else and in a group DM with its owner; the humans in both still post. - An agent posts in a DM with only its owner. - An agent can open a DM only with its owner; a human can still open a DM with an agent. - An agent can't add members to its owner DM, through 41011 or 9000. - An agent can't set the topic in a DM with a stranger. - An agent is refused admission to a huddle in a DM with a stranger and admitted in its owner-only DM; a human still joins. - An agent's workflow `send_message` is refused in a DM with a stranger and allowed in its owner-only DM. - An owner linked after a lookup miss is seen on the next lookup (no negative caching). `cargo clippy -p buzz-relay --all-targets -D warnings` is clean. The other ingest and command-executor tests pass locally (214), except two that fail only because of my local database: one needs the desired-state FTS schema, and the other fails creating its restricted role in setup. Neither reaches DM code. I pushed without the local pre-push `just test-unit` lane because a `buzz-cli` unit test hung there for about 30 minutes; CI runs that lane. 🤖 Generated with [Claude Code](https://claude.com/claude-code) --------- Signed-off-by: Joah Gerstenberg <joah@squareup.com> Co-authored-by: Hertz <c6741012416ef5c49a865db79682113385c5fb998e8c890234fb442b59e22748@buzz.block.builderlab.xyz> Co-authored-by: Claude Opus 5.5 <noreply@anthropic.com> |
||
|
Tom Brow
|
1b190d21fc |
fix(relay): bound each cross-node delivery attempt (#9305)
**Context:** #9302 (merged) stopped the relay from closing connections when cross-node fan-out falls behind. It also removed the 30 s delivery deadline. This PR is the fix from the review of #9302. **Problem:** Since #9302, a fan-out worker waits for the access-gate database read with no time limit. If a database connection stops answering in the middle of that read, the worker never continues. Its queue fills, and one sixteenth of the node's channels get no live events from other nodes until the relay restarts. Before #9302 the deadline cut that delivery off after 30 s. **Fix:** Each delivery attempt has a 30 s limit (`MAX_DELIVERY_ATTEMPT`), measured from when the worker starts it. When the limit passes, the relay counts the event in `buzz_multinode_fanout_dropped_total{reason="stale"}`, resyncs the artifact syncs the event matched, and continues with the next event. It closes no connection. An event that only waits in the queue is still delivered late, as #9302 intends. The queue-full drop and the new stale drop share one helper. ### Validation - Added test: `hung_delivery_is_dropped_at_the_bound_and_the_worker_moves_on` drives the production worker with a database that accepts the connection and never answers. It checks that the delivery stops at the limit, is counted, resyncs the matched sync, closes nothing, and that the next event on the same worker is delivered. With the limit removed it fails (the worker waits out the pool's one-hour acquire timeout instead). - The other `handlers::multinode_fanout` tests pass. The full local `buzz-relay` suite was not run; CI on this head covers it. 🤖 Generated with [Claude Code](https://claude.com/claude-code) Signed-off-by: Tom Brow <tomb@squareup.com> Co-authored-by: Tom Brow <tomb@squareup.com> |
||
|
Tom Brow
|
27f0fe7527 |
feat(mobile): add iOS Home Screen shortcuts for New chat, New DM and the Bestie (#9360)
Long-pressing the Buzz icon on iOS now offers three quick actions: - **New chat** opens a new solo chat (the same draft as New › New chat). - **New DM** opens the New DM picker. - **Message <Bestie>** opens the DM with the current community's Bestie, using the agent's display name (for example "Message astra"). It's hidden when the community has no Bestie, and it updates when the Bestie, its name or the community changes. | Before | After | | --- | --- | | <img alt="before" src="https://github.com/user-attachments/assets/393c3fb6-fe64-4505-a7a4-12714d8bf1df" width="300"> | <img alt="after" src="https://github.com/user-attachments/assets/1c57df92-6fed-4fee-9ce8-e9ea0ec70294" width="300"> | ### How it works Home publishes the items through a small native bridge (`buzz/home_screen_shortcuts`), which sets `UIApplication.shortcutItems`. A tap goes through the scene delegate. The bridge keeps the latest one until Dart has handled it, the same pattern push-notification taps use, so cold launches work too. Home runs it only once the app is active and the destination is ready. When a tap arrives, Home pops back to the first route once, so a shortcut never opens beneath a Flutter sheet or a conversation that was already open. A screen that refuses to close (for example a New chat whose first message is still sending) stays, and the tap is dropped. The one exception is the native iOS New channel form, which isn't a Flutter route: a shortcut tapped with it open runs underneath it. If a screen is opened while a tap is still waiting for its destination, the tap is dropped. A New DM tap while the New DM picker is open replaces the picker. Opening the Bestie DM now goes through one shared function, so the Home launcher button and the shortcut run identical code. A second open while the DM is still being looked up does nothing. Signing out clears the items. The shortcut wiring lives in its own leaf widget, so Home doesn't rebuild for it. Behavior change for the existing Home Bestie launcher: if you open another screen while it's still looking up the DM, the DM no longer opens over that screen. Behavior change for the native member picker (New DM, and Add members in channels): a picker reopened while the previous one is still closing now opens once the dismissal finishes, instead of failing with "Cannot open the member picker". ### Validation - Added tests: a Home journey covers the published titles (including the Bestie's name), a cold tap that waits for the app to resume and for New chat to be available, a Bestie tap made with another route open, a New chat tap while a draft is open, a New DM tap replacing an open picker, a waiting tap dropped once another screen opens, no Home rebuilds on lifecycle changes, and clearing the items when Home goes away. A launcher test covers a slow Bestie lookup, and a New chat test covers a shortcut tapped while the first message is still sending. I also broke the code that runs the shortcut and confirmed the journey fails. - Full mobile suite and `flutter analyze` pass. CI doesn't compile Swift on drafts, so `NativeAddMembersSheet.swift` was compiled with a local `flutter build ios --simulator` build. - iPhone 17 Pro simulator (iOS 27), signed in to a Builderlab community: from a cold launch, New chat opened the new-chat draft. Then, with the app warm, New DM opened the picker and Message <Bestie> replaced it with the Bestie DM. The recording stays in Buzz because it shows real account data. buzz-review-completed 🤖 Generated with [Claude Code](https://claude.com/claude-code) --------- Signed-off-by: Tom Brow <tomb@squareup.com> Co-authored-by: Tom Brow <tomb@squareup.com> Co-authored-by: Claude Opus 5.5 <noreply@anthropic.com> |
||
|
Tom Brow
|
85c7156085 |
perf(mobile): stop downloading whole videos for posterless stills (#9367)
Follow-up to [#9356 gallery video selection](https://github.com/block/buzz/pull/9356), merged as [ |
||
|
Brad Seiler
|
4c60be6a1e |
Enforce single-community relay mode (#9149)
## Summary Add `BUZZ_MULTI_COMMUNITY_RELAY` (default `true`, strict boolean). With `false`, ordinary HTTP/WebSocket traffic serves only the community at the normalized `RELAY_URL` authority, including a nondefault port. Other hosts receive a generic 404 before tenant lookup or handler execution. Authenticated admin/operator inventory and cleanup remain available through their configured authorities. Existing extra rows do not prevent startup and are not deleted automatically. Canonical bootstrap and legacy convergence on the existing canonical community remain available; operator creation is disabled. Invite minting and git callbacks also check their target community. Availability retains its free-name meaning and adds `can_create` to report policy permission. Changes require restarting every serving revision. An older image can ignore this setting. Removing it, setting it true, or rolling back to an older image can reopen serving and creation. Keep operator/admin authentication configured throughout rollout and rollback. ### Current draft gates Published candidate `8319e9a4b299deb2bb2cb72400a2c6aff396b362` includes the independently reviewed deletion-fixture correction. Normal push hooks and all local validation passed at this head: 2,028 package tests, full `just ci`, all 1,393 isolated UTF-8/UTC PostgreSQL tests and the binary build. A running local relay passed 16 HTTP/WebSocket and signed admin/operator assertions, including extra-host denial and cleanup access. Hosted PostgreSQL and full CI must still pass on this head. Human acceptance and the background-work decision remain open; keep this PR draft. Background workers currently retain their prior behavior: cleanup/retention/recovery/revocation continue, as do scheduled workflows, reminders, configured push/listener delivery, storage-usage reporting and artifact sync under existing lifecycle rules. Whether to pause ordinary background work for extras is an open product decision and an acceptance gate. No worker changes are included yet. ### Rollout and acceptance 1. Resolve the background-work decision, finish validation/review, and complete the repository-required human test. 2. Obtain separate staging rollout authority, use an immutable supporting image and explicit false on every serving revision, and review generated configuration. 3. Verify an extra host returns 404 for HTTP and WS; canonical HTTP/WS and NIP-FI still work. Verify authenticated admin reads/actions and operator inventory/archive/delete still reach an extra community. 4. Only after staging acceptance, obtain separate production rollout authority. This draft grants no merge, deployment or cleanup authority. 5. Rollback by returning the setting to true or the previous image explicitly reopens serving/creation. Preserve operator/admin access. ### Related issue No duplicate creation-only policy PR found in the open-PR search. Related creation surface work: #2398. Creation-only validation is superseded; see its [historical CI run](https://github.com/block/buzz/actions/runs/42123475841). It does not qualify the current candidate. Generated with Codex --------- Signed-off-by: Brad Seiler <seiler@squareup.com> Co-authored-by: Sarnow <1894dcbafaa4df1ac607a9bf879ac0b7d77fbccb0e0f4619ecc252c8adbad8a2@seiler-test.communities.public.builderlabstaging.xyz> Co-authored-by: Honor <e0bf479eeebe47dde1e35705212a4df70616a7bc834d907ddfb18cf0405f8b1b@seiler-test.communities.public.builderlabstaging.xyz> |
||
|
Jemiah Westerman
|
695c1c3aae |
fix(relay): match #a tag filters in SQL before LIMIT (#9339)
## Summary **Intent:** let clients find and count reactions to an **addressable event** at the SQL layer. Addressable events are NIP-01 kinds 30000–39999, which NIP-33 called "parameterized replaceable events". Clients reference one by its address, not its event id. An addressable event is identified by its address `<kind>:<pubkey>:<d>`. Each edit publishes a new event with a new id at the same address. A reaction (kind:7) that tags the address with `a` therefore still applies after the target is edited. A reaction that tags only the current revision's id with `e` is left behind on the old revision. Use cases: - **Agent personas (kind:30175).** A ⭐ on a shared persona is a kind:7 tagged `["a", "30175:<owner>:<slug>"]`. A client that lists shared personas by popularity needs `{kinds:[7], "#a":[...]}` and the matching COUNT to return every star across persona edits, not only stars on the current revision. - **Other addressable kinds**, such as teams and channel metadata, work the same way with no extra code. - **Replaceable events, such as user profiles.** Kind:0 profiles and kind:10100 agent profiles are *replaceable* (kinds 0, 3 and 10000–19999), not addressable. NIP-01 still gives them an `a` address with an empty `d`, `0:<pubkey>:`, so reactions that tag a profile that way are matched by the same filter. Before this change, the relay applied `#a` only after the SQL `LIMIT`. A selective read fetched the newest kind:7 rows across the whole community and then dropped the ones that didn't match. It could return fewer than `limit` matches, or none, while older matches existed. COUNT also could not take its exact fast path. What changed: - **`EventQuery.a_tags`** (buzz-db) works like `e_tags`. It is an exact positional tag match (`tag->>0 = 'a' AND tag->>1 = ANY(..)`) with JSONB `@>` as the prefilter on the existing GIN index `idx_events_tags_gin`. - **No schema change, migration or backfill.** - It gets the same MATERIALIZED CTE fence as `#e`, so the planner cannot walk `created_at` backward looking for a rare match. - It reads the table whole rather than recent partitions first. - It is counted in `count_events_sql`. - An empty set matches nothing, as the NIP-01 post-filter does. - **`filter_to_query_params`** fills `a_tags` for every filter, and **`filter_fully_pushable`** treats `#a` as pushed. REQ, COUNT and the HTTP bridge `/query` and `/count` all go through these two functions. - **`per_channel_scope`** now skips per-channel reads for every fenced query, through a shared `reference_tag_fence` helper. Before this, it excluded `#e` reads explicitly, and `#a` with a multi-value `#h` would have wrapped the fence around the per-channel lateral, which is invalid SQL. Not included: `#k` and other low-cardinality tags. Postgres's estimate for JSONB `@>` assumes any match is rare, so pushing a common value could switch to a slower plan. They remain post-filters. ### Related issue None found. ### Testing - `req.rs` unit test: `#a` maps to `a_tags` (including empty and absent) and is fully pushable; `#a` + `#k` is not. - buzz-db shape tests: an `#a` read is fenced, COUNT applies the match, an `#a` read is never split into recent and older passes, and `#a` makes a read ineligible for per-channel scope. An empty `#a` is answered without a database read. - buzz-db Postgres: an `#a` case added to `pushed_down_tag_filters_reject_positional_decoys`, covering query and COUNT. - New `handlers/tag_pushdown_postgres_tests.rs`: - REQ returns an older `#a` match ahead of a full page of newer reactions to another address. COUNT is exact, and an empty `#a` counts 0. This test fails when `a_tags` is removed from `filter_to_query_params`. - REQ and COUNT with `#a` + a multi-value `#h`. This test fails, with `CLOSED database error`, without the `per_channel_scope` fix. - Full buzz-db and buzz-relay suites, unit and Postgres lanes, run locally. - Live check against a local relay built from this branch, over WebSocket with NIP-42 auth. Two reactions to one address (each on a different head event, as after an edit) and six newer reactions to another address were published. `REQ {kinds:[7], #a:[needle], limit:2}` returned exactly the two needle reactions, newest first. COUNT returned 2 for the needle, 6 for the hay and 0 for an empty `#a`. `#a` + `#e` with `limit:1` returned the newest needle reaction. buzz-review-completed 🤖 Generated with [Claude Code](https://claude.com/claude-code) Signed-off-by: Jemiah Westerman <jemiah@squareup.com> Co-authored-by: Son of Anton <8e0ef2ab02d69a7ac089ef5eca90d1a3fbbdc546f6322dc34d0c4f3deecea7f4@buzz.block.builderlab.xyz> Co-authored-by: Claude Opus 5.5 <noreply@anthropic.com> |
||
|
klopez4212
|
96e56c5b33 |
Add participant avatars to mobile conversation headers (#9369)
## Summary Add participant portraits to mobile conversation headers, with up to four portraits in a compact cluster. DM and Solo headers show counterparts; channel headers use the member roster. Names stay on one line, and tapping either the portrait or title opens the existing settings. - iOS: float portraits above the glass title capsule; lift standalone animated artwork and tuck the title underneath. - Android: place the cluster inside a left-aligned title pill, 16 dp after Back, with smaller agent portraits and a 48 dp tap target. - Remove header presence/member-count subtitles. In confirmed two-member conversations (DM, Solo, or channel), hide redundant incoming author avatars and give text the freed 48 dp while retaining the previous total width. Apply this to thread replies and align their footers; messages with avatars and outgoing messages retain their production width caps. Keep sender attribution visible while DM metadata and current membership disagree. Forum loading, error, and post-list states reserve the full conversation header height. The floating title follows the app-selected appearance, including when it differs from iOS. Conversation headers remain name-only, including temporary conversations, as requested; retention accessibility text is preserved. ## Validation - Formatting/static analysis and full mobile suite: 4,695 passed, 71 skipped; auxiliary push and crypto suites passed. - Full native iOS suite passed, including title positioning/reset and settings activation. - Installed previews on physical iPhone Air and Pixel; Android avatar/title settings taps exercised. - Final diff reviewed for correctness, accessibility, scope, and public-source boundaries; no blocking findings. The width follow-up is covered by rendered conversation/thread tests. The width follow-up is installed and launched on iPhone Air; the Pixel preview remains on the preceding header build. The review fixes have not been installed on physical devices. ## Snapshots Current Pixel preview, cropped to the header to omit conversation history. These captures show a single agent and a four-portrait cluster. The current iOS preview is installed, but a fresh physical-device screenshot was blocked by device authentication; no outdated iOS capture is included. ### Android — single agent  ### Android — grouped agents  --------- Signed-off-by: kenny lopez <klopez4212@gmail.com> Co-authored-by: Terp <5856f6900e8e0a4e0ea1f4f8d2ee33e4753d2119bc122f94ecafc660b46c0511@buzz.block.builderlab.xyz> |
||
|
Logan Johnson
|
8f80b172ea |
fix(mobile): stop asking for an API token when the channel list is refused (#9327)
## Summary - When the relay refused the channel-list request (HTTP 401), the mobile app said "Not authorized. Check your API token." The app has no API token, so the advice could not be followed. - The message now reads "This community couldn't authenticate the request. Try again." Retry stays: for org and hosted communities the refused token is dropped and Retry gets a fresh one, and a self-hosted relay that refuses the key has no other recovery on this screen. - One exception: when the organization sign-in has ended, the app sends reads unsigned and Retry can never succeed, while the Home banner already offers a working Sign in. In that state the channel list says "Use the sign-in prompt below to reconnect." and hides Retry. ## Details - `_ErrorView` (`mobile/lib/features/channels/channels_page/badges.dart`) only appears on a cold load with no saved channel list. It replaces the list, so Retry is the only control on that screen. - It reuses the shared `organizationSignInPromptVisible` predicate, the same one the Home banner and the community switcher use, so the error view and the banner agree on who owns the action. - The 403 "Access denied." message is unchanged. - Widget tests cover the new 401 copy with Retry, and the signed-out organization state with no Retry. ## Screenshots Android emulator, debug build, against a local test relay that refuses the channel-list read with HTTP 401 (no saved channel list, so the error view shows): <img src="https://github.com/user-attachments/assets/feebc324-a4cf-49ca-876a-1ae026bda753" alt="Channel list error: This community couldn't authenticate the request. Try again. With a Retry button" width="360"> 🤖 Generated with [Claude Code](https://claude.com/claude-code) --------- Signed-off-by: Logan Johnson <loganj@squareup.com> Co-authored-by: Larry <627498bd4bd1f281a16431e3c6cce3b5c25b6692798c78672298aefbf2f8f8b5@buzz.block.builderlab.xyz> Co-authored-by: Tom Brow <tomb@squareup.com> Co-authored-by: Claude Opus 5.5 <noreply@anthropic.com> |
||
|
Brad Seiler
|
75d38b6c2d |
chore(release): release Buzz Relay version 0.3.0 (#9362)
## Summary
Prepare Buzz Relay 0.3.0 from freshly fetched `main` at
`e5dee91c90fdc5f81f04fd609b7c99e31fa7570f`. Bump only the relay crate
version and its root lockfile entry from 0.2.1 to 0.3.0, and prepend the
relay changelog. Desktop, CLI, mobile, Helm, and dependency versions are
unchanged.
The changelog contains all 297 non-merge commits selected by the relay
release recipe from `relay-v0.2.1` through the pinned base. Internal
ticket identifiers were removed from historical subjects to follow the
repository's public-source policy; entries and PR/full-SHA source links
are preserved. [Full source
comparison](https://github.com/block/buzz/compare/relay-v0.2.1...e5dee91c90fdc5f81f04fd609b7c99e31fa7570f).
### Related issue
Release preparation request; no duplicate release 0.3.0 PR found.
### Testing
- `just bump-relay-version 0.3.0`: completed; the lockfile changes only
the `buzz-relay` version, without transitive dependency updates.
- `cargo metadata --locked --no-deps --format-version 1`: confirms relay
version 0.3.0.
- `git diff --check` and mandatory pre-commit formatting: passed.
- `bash scripts/test-release-ref-contract.sh` passed in a clean local
clone of `3def95c9435b2884c01446fe1a1f92f4fe9960fc`.
- Mandatory pre-push checks passed at
`3def95c9435b2884c01446fe1a1f92f4fe9960fc`. Independent review of the
commit and published head/body/draft state found no defects.
Repository-wide `just ci` passed at
`3def95c9435b2884c01446fe1a1f92f4fe9960fc` after reproducible dependency
setup; the worktree remains clean. [GitHub CI attempt 2
passed](https://github.com/block/buzz/actions/runs/43092559585/attempts/2)
at that exact head. The prior attempt failed before tests in three
artifact downloads; retrying the failed jobs resolved the service errors
without code changes. Local checks and independent review passed; human
acceptance remains separate. The existing ready state is preserved.
Local integration validation is blocked: Docker Desktop starts and its
daemon answers, but managed sign-in policy denies container access until
the operator signs in.
### Release hazards
Preparation only: **merging this PR automatically creates `relay-v0.3.0`
and starts image publication**, including stable version aliases and
`latest`/`debug-latest`. No merge, tag, or deployment is part of this
preparation.
The [relay
tagger](
relay-v0.3.0
|
||
|
klopez4212
|
ef57fec4d2 |
Fix gallery video selection, thumbnails, and swipe dismissal (#9356)
## Summary Photos currently filters out videos, video messages without poster metadata stay grey until playback, and the native gallery rejects downward dismissal on video pages. - Include photos and videos in the native inline/popover pickers, system picker, and recent-media grid. Mixed selections retain their order and videos use the video upload path. Remove the redundant Video menu row on iOS and Android, whose Photos picker accepts both media types; reduce their menu height to four rows. Native pickers request the current asset representation to avoid compatibility transcoding and export up to three files concurrently, preserving order and cleaning up cancelled/failed batches. - Show local stills for queued videos. For older messages without posters, serialize thumbnail generation for the four rendered stack cards, bound/cancel downloads, remove temporary videos, and save stills in the existing account/community cache. Existing poster metadata is used directly. The native viewer uses the poster while loading instead of a play-button snapshot. - Allow downward dismissal on native video pages while preserving horizontal paging/scrubbing, zoomed-photo panning, and the accessible Close button. Fire selection-click haptics as a swipe begins rather than after the page settles, with no duplicate on completion or cancellation. Page-indicator changes retain immediate feedback. Replace visible video-loading text with the existing white arc-spinner treatment, implemented natively with reduced-motion and lifecycle handling. Completed swipes release the previous video player even after UIKit removes it from the active children. Legacy videos need one initial download (up to the existing 100 MB limit) to generate their cached preview. This does not start playback. ### Related issue Follow-up to merged #9259 and #9314. Searched open and closed gallery/video issues and PRs; no duplicate fix found. ### Testing - Full `just mobile-check` and `just mobile-test` passed at `12e6ed6ae3`: 4,688 Flutter tests (71 skipped), 4 unconfigured-push tests, and 27 crypto-package tests. File-size checks passed. Regressions cover mixed image/video upload routing, queued still previews, the rendered-card poster window, authenticated/cancelled downloads, caching/cleanup, and native poster loading. - Native gallery simulator regression fixture passed: photo/video dismissal guards, real MP4 decoding, paging, selected-only playback loading, and teardown. - Swift type-check of the native picker and its dependencies passed, with existing deprecation/capture warnings. - `just ci` passed its repository-wide lint/type checks. The unrelated Rust test rebuild was stopped after consuming about 13 GB to preserve remaining disk space; only that run's generated caches were removed. Release build at `fb09f9cb8` installed in place and launched on the physical iPhone Air as **Buzz Photo Stack**, with `BUZZ_NATIVE_PHOTO_ZOOM=true`. Existing app updated in place with the same bundle and Keychain identity; no uninstall or reset. Owner tested the physical-device preview and approved readiness for review. No before/after capture was produced. The simulator evidence above is an automated native fixture, not a full Buzz device journey. Native preparation follow-up: `scripts/test-mobile-picker-preparation.sh` passed on an iPhone Air simulator, covering bounded overlap, out-of-order completion, cancellation, and failure cleanup. The updated physical Air preview launched successfully with unchanged preferences metadata. Cloud-only assets may still require preparation. Loader/haptics follow-up native fixture passed: real video readiness hides the loader, error/retry and detach stop/restart it correctly, swipe start triggers one haptic before selection changes, and completion/cancellation/duplicate-start callbacks add none. Updated release installed and launched on the physical Air; owner approved the final preview for review. Review: focused code review and native regression checks completed; physical Air preview tested by the owner, who approved readiness. P2 follow-up: video presentation uses an already decoded poster or the source snapshot immediately, then forwards a pending poster asynchronously. Late poster updates are limited to the selected native page and do not restart playback. Added pending-provider presentation coverage and native late/stale-poster checks. This follow-up has not been installed on the physical preview yet. --------- Signed-off-by: kenny lopez <klopez4212@gmail.com> Co-authored-by: Terp <5856f6900e8e0a4e0ea1f4f8d2ee33e4753d2119bc122f94ecafc660b46c0511@buzz.block.builderlab.xyz> |
||
|
Logan Johnson
|
e5dee91c90 |
chore(deps): bump hickory-proto to 0.26.2 for RUSTSEC-2026-0487..0491 (#9351)
## Summary - The dependency-policy check (cargo-deny) on `main` fails because `hickory-proto` 0.26.1 now has five published security advisories: RUSTSEC-2026-0487, -0488, -0489, -0490 and -0491 (panics and memory amplification when parsing malformed DNS records or zone text). - This updates `hickory-proto` to 0.26.2, which carries all five fixes. With it, `cargo-deny check` passes again (advisories, bans, licenses and sources all ok). - The desktop app's separate Rust workspace (`desktop/src-tauri`) gets the same update. CI does not run cargo-deny there, but release builds include `hickory-proto` through the `mesh-llm` feature, so they would otherwise still ship 0.26.1. ## Details - `hickory-proto` is a transitive dependency: `iroh` → `hickory-resolver` → `hickory-net` → `hickory-proto`. No crate names it directly. `hickory-net` and `hickory-resolver` stay at 0.26.1; they accept `hickory-proto ^0.26.0` and get the fixes through it. - Lockfile-only change: the `hickory-proto` version and checksum in each lockfile. 0.26.2 has the same dependency list as 0.26.1, and the locked versions already meet its raised minimums. A plain `cargo update -p hickory-proto` also moved ten unrelated Windows-only crates from `windows-sys` 0.59 to 0.61; those are left out to keep this change to the advisory fix. - 0.26.2 is not behavior-identical: it rejects malformed DNS input that 0.26.1 panicked on or over-allocated for, and it treats IPv4-mapped IPv6 addresses as IPv4 in resolver answer filtering. 🤖 Generated with [Claude Code](https://claude.com/claude-code) Signed-off-by: Logan Johnson <loganj@squareup.com> Co-authored-by: Larry <627498bd4bd1f281a16431e3c6cce3b5c25b6692798c78672298aefbf2f8f8b5@buzz.block.builderlab.xyz> Co-authored-by: Claude Opus 5.5 <noreply@anthropic.com> |
||
|
Tom Brow
|
95dd9d67dd |
feat(mobile/ios): show the message's own text in notifications (#9346)
Expanding a Buzz notification today shows the same stub as the banner: one line of at most 180 characters, with code replaced by `[code]` and links by `[link]`. A long message can only be read by opening the app. The notification body is now the message's own text. It keeps line breaks, the text of code and bare URLs, and drops the Markdown syntax around them (`[text](url)` shows `text`). It is capped at 256 UTF-16 units, which is the most iOS shows even when a notification is expanded. iOS cuts longer bodies mid-word with no ellipsis, so the cap stops at 255 units and adds "…" without splitting a character. A link label, image alt text or bold run may contain code, and a code fence with no closing fence runs to the end of the message. The body is built from at most the first 4096 UTF-16 units of the message, so very long or hostile Markdown stays fast (under 300 ms for a 256 KB message in an optimized build); when that cut drops text, the body also ends with "…". | Before (expanded) | After (expanded) | | --- | --- | | <img width="300" alt="Before" src="https://github.com/user-attachments/assets/7201791f-9556-446a-86d2-a50f024cf9dc"> | <img width="300" alt="After" src="https://github.com/user-attachments/assets/3fa52db8-ebcf-470f-9175-47fe5ef4ed12"> | [ADR 0002](docs/adr/0002-notification-message-text.md) records the rules so other mobile platforms follow them, and the cases in `test-fixtures/notification-body.json` are the contract. The iOS tests run every case, and Android's notification code can run the same file when it lands. **What gets better, what doesn't get worse:** only the body text of message notifications changes. The title, subtitle, grouping, avatars, navigation and dedupe are untouched, and the change lives in one pure function. A notification can now show code and URLs from the message, as the message itself does, and the user's lock-screen preview setting still applies. ### Validation - Added tests: `testPreviewBodyMatchesSharedNotificationBodyCases` runs the 30 shared cases (links, mentions, images, fenced and inline code, code inside link labels and bold runs, Markdown inside code, unclosed and cut fences, whitespace, the cap at 256 and 257 units, emoji and ZWJ sequences at the cap, the 4096-unit input cut). The full BuzzPushKit suite passes: 112 XCTest and 70 Swift Testing tests. - iOS limit measured on an iPhone 17 Pro simulator (iOS 27) with a local notification: the expanded body and its accessibility label both stopped at exactly 256 UTF-16 units (256 ASCII characters, 128 emoji), cut mid-word with no ellipsis. A 40-line body showed about 31 lines. - The screenshots show this function's before and after output for the same message, posted as a local notification. The simulator doesn't run the Notification Service Extension for `simctl push`, so the full push path (relay fetch through to display) was not exercised. An iPad was not measured. - Human testing is waived; the automated run above covered display of the changed body only, since nothing else in the app changes. 🤖 Generated with [Claude Code](https://claude.com/claude-code) --------- Signed-off-by: Tom Brow <tomb@squareup.com> Co-authored-by: Tom Brow <tomb@squareup.com> Co-authored-by: Claude Opus 5.5 <noreply@anthropic.com> |
||
|
Tom Brow
|
1adde0e6bf |
feat(mobile): prefill the agents you last tagged in a conversation (#9248)
Desktop prefills an empty composer with the agents your latest message
in that conversation notified. This brings the same behavior to mobile
for channels and threads.

### Behavior

- An empty channel or thread composer starts with `@Agent ` for each
agent that the viewer's latest loaded message in that conversation
notified (its `p` tags). It reads what the view displays: the main
timeline in a channel (top-level messages and broadcast replies), and
the head plus its direct replies in a thread. Deleted messages don't
count, and same-second messages follow the display order.
- People are never carried over, and neither are agents that are no
longer channel members (agent here means a member with the bot role or
an owned agent, the same classification the mention picker uses).
- The prefill comes from messages already loaded, with no extra relay
reads, so it follows sends from other devices.
- It isn't a draft: nothing is saved (no Drafts entry) until the viewer
edits it, and it sends no typing indicator.
- Removing it lasts until the composer is shown again (leave and reopen)
or the viewer sends another message there. Sending without the agent
ends the chain.
- An untouched prefill is taken back once it's out of date: when the
viewer's latest message (even one sent from another device) tags no
agent, or its agents have all left the channel. Text the viewer wrote is
never cleared.
- DMs and Solo chats are unchanged. There's no settings toggle.

Also moves the composer's keyboard-metrics observer effect into a
`helpers.dart` hook, unchanged, to keep `compose_bar_widget.dart` under
the 1200-line limit.

### Validation

Added tests: a compose bar widget journey covering prefill from the
latest own message (ignoring people and others' messages), no saved
draft until edited, send then re-prefill, removal sticking through a
member/name refresh and returning on remount, and no prefill for an
agent that left. A second test covers taking back an untouched prefill
after a newer agent-less message or the agent leaving, while keeping
text the viewer wrote. A unit test checks same-second display order.
Breaking the draft skip, the removal guard or the take-back fails them.

Full mobile suite: all pass except 4 `swipe_reply_tests` "right drag …
replies" cases, which fail identically on the base commit (stale after
the swipe-left-to-reply change).

Simulator (iPhone 17 Pro, debug build, test community, run on the first
commit; the take-back follow-up is covered by the widget tests): after
mentioning an agent in a channel, the composer refilled with it; sending
again refilled it; deleting it kept the composer empty until leaving and
reopening the channel, which brought it back; a thread with no
agent-tagged reply had no prefill, and after replying with an agent
mention the thread composer prefilled it. Demo video is shared
internally rather than here, since it shows a real account.

🤖 Generated with [Claude Code](https://claude.com/claude-code)

---------

Signed-off-by: Tom Brow <tomb@squareup.com>
Co-authored-by: Tom Brow <tomb@squareup.com>
Co-authored-by: Claude Opus 5.5 <noreply@anthropic.com>
mobile-v1.0.0-rc.3 |
||
|
Tom Brow
|
0ac71eaf95 |
feat(mobile): start a Solo chat from a message or inbox row (#9251)
Adds **Start Solo chat** to the message long-press sheet and the inbox row menu, analogous to buzz-app desktop's action. ## Behavior - Opens an unsent New chat draft (no channel is created until the first send), with the composer expanded and focused. - **Open channel messages** (public stream or forum) are seeded with the message's `buzz://` link, as desktop does, so the agent can open it. - **DMs, private channels, Solo chats and unknown channels** are seeded with the message excerpted as a Markdown block quote, because the agent usually can't read them. A long quote is cut at 6 KB so the first message stays under the 8 KB limit. - Starting again from the same message returns to the same draft (keyed `new-solo:<messageId>`). - Unlike desktop, it's available on your own messages too. - In the sheet it's a list row under **Copy text**; in the inbox menu it's under **Open conversation**, for message items with content. - The draft title skips a leading block quote and uses the prompt after it (or the quote text when there's no prompt). ## Notes - A seeded draft left unsent stays in the inbox Drafts list, as an unsent New chat draft already does. - Conflicts with #9142 (inbox row menu follow and remind actions), which reindents `_showRowActions`. Whichever lands second needs a small rebase. ## Demo Public channel message (linked), private channel message (quoted), then a public channel inbox item (linked) and a DM inbox item (quoted). Test data only. https://github.com/user-attachments/assets/91d2de7f-d35d-4907-bcf6-ec904327f06c ## Before / after | | Before | After | |---|---|---| | Message long-press sheet | <img src="https://github.com/user-attachments/assets/da79ae08-68a0-4396-9a63-f01af9ceb3a3" width="260"> | <img src="https://github.com/user-attachments/assets/88ee6ff1-66d6-42fe-8b78-ab7f4e6cbcfa" width="260"> | | Inbox row menu | <img src="https://github.com/user-attachments/assets/5c6f551c-63f5-40ab-b0a3-08778472d964" width="260"> | <img src="https://github.com/user-attachments/assets/25f9fa30-ac52-4b78-85fb-5679ca336495" width="260"> | Where it lands (new, unsent New chat draft): | Public message | Private message | Public inbox item | DM inbox item | |---|---|---|---| | <img src="https://github.com/user-attachments/assets/245204d3-0a56-4029-a2a6-e9d054ee6e0e" width="190"> | <img src="https://github.com/user-attachments/assets/3d5a100b-5ae5-470e-b945-8c9b24ac1db0" width="190"> | <img src="https://github.com/user-attachments/assets/8deea67e-07f4-4fc8-93d8-981fbe848c1d" width="190"> | <img src="https://github.com/user-attachments/assets/0f4b62c9-81ba-4d08-a77c-8298f3b46718" width="190"> | ## Validation - Automated simulator run (iOS 27 sim, Remote Agents Pilot): sheet on own message in a public channel seeds the link chip; sheet on a private channel message seeds a quote; inbox public channel item seeds the link; inbox DM item seeds a quote. Recorded as the demo above. - New `solo_chat_seed_test.dart` table test (link, thread link, quote trimming, multi-line quote) and two new title cases in `me_chat_creation_test.dart`. - `flutter test`: all pass except the 4 `right drag starting on/beside a link replies` cases in `channel_detail_page_test.dart`, which fail identically on clean `main`. 🤖 Generated with [Claude Code](https://claude.com/claude-code) --------- Signed-off-by: Tom Brow <tomb@squareup.com> Co-authored-by: Tom Brow <tomb@squareup.com> Co-authored-by: Claude Opus 5.5 <noreply@anthropic.com> |
||
|
Tom Brow
|
045b637b0d |
feat(mobile): link to Builderlab web from Settings (#9300)
Neither mobile app offers a way to reach Builderlab's web-only account features: GitHub linking, billing and creating a community. This adds a **Builderlab account** row to Settings that opens the build's Builderlab origin (app.builderlab.xyz on public builds) in the system browser. The row shows only on public builds. An internal build's Builderlab is its organization's tenant, where billing and the single community are managed by the organization, so the link wouldn't lead anywhere useful. Nostr-only builds have no Builderlab. Sign-in uses a non-ephemeral `ASWebAuthenticationSession`, which shares Safari's cookies, so Safari can reuse the Builderlab web session. A browser other than Safari, or Android, may still ask the user to sign in. | Before | After | | --- | --- | | <img alt="before" src="https://github.com/user-attachments/assets/a8f2157b-5a54-41fc-8937-013638b3347e" width="300"> | <img alt="after" src="https://github.com/user-attachments/assets/f1161f3b-c926-4a8c-b6a1-7532ef72749c" width="300"> | Nothing else gets worse. The change adds one row and one browser launch on tap, and does no work at startup or in the background. A failure stays inside this row: if the browser doesn't open, a toast says so. ### Validation - Added tests: `builderlab_account_row_test.dart` checks that the row opens `HostedEnvironment.origin` and shows a toast when the browser fails to open (public build), and that the row is absent otherwise. It is added to the CI public-build lane. - `settings_page_test.dart`: the version-footer scroll check now finds the footer after it scrolls just offscreen. The extra row pushed it there under public-build defines. - Settings tests pass under both public and Nostr-only defines, and `flutter analyze` is clean. - iOS simulator (public build, signed in to the public Builderlab): the row appears below Connection, and tapping it opens Safari at Builderlab. This simulator's session came from an identity import, not the in-app browser sign-in, so Safari was signed out. I haven't yet verified that Safari arrives signed in after a real in-app sign-in. 🤖 Generated with [Claude Code](https://claude.com/claude-code) --------- Signed-off-by: Tom Brow <tomb@squareup.com> Co-authored-by: Tom Brow <tomb@squareup.com> Co-authored-by: studio <dc2fc481343672df31a689840c09299972e704dac592e0da6f18486646a7ee3e@localhost> |
||
|
Tom Brow
|
2c5c8343ef |
fix(relay): bound invite preview host lookup (#9308)
**Context:** #9306 (merged) added link-preview tags to the invite page. To build the media URLs, the relay looks up the community for the request host. This fixes a problem found in our review of #9306. **Problem:** The invite page waits for that lookup with no time limit. When the database is slow, the lookup can take as long as the pool acquire timeout (3 s) plus the statement timeout (120 s by default). During that time, a person who opens an invite link gets no page. Before #9306, this page did not use the database. **Fix:** The lookup gets 250 ms. If it does not finish, the relay sends the page without the preview tags. A healthy indexed host lookup finishes well inside that, so crawlers still get the tags, and nothing else changes: the media route, the router and the build are untouched. ### Validation - Added test: a host whose lookup never finishes gets the plain page. Without the timeout, this test hangs (confirmed locally; it was killed after 30 s). - The existing `invite_preview` and router invite tests pass. 🤖 Generated with [Claude Code](https://claude.com/claude-code) Signed-off-by: Tom Brow <tomb@squareup.com> Co-authored-by: Tom Brow <tomb@squareup.com> Co-authored-by: studio <dc2fc481343672df31a689840c09299972e704dac592e0da6f18486646a7ee3e@buzz.block.builderlab.xyz> |
||
|
Dave Grochowski
|
47674dc322 |
fix(relay): saturate filter limits instead of casting (#9230)
## Problem Four request paths converted a client-supplied `usize` filter limit with an inline `as` cast before clamping: `(l as i64).min(max)` (REQ query params, bridge feed) and `(l as u32).min(max)` (WS NIP-50 search, bridge channel window). - A limit above `i64::MAX` turns negative (`usize::MAX as i64 == -1`). On REQ and the bridge `/query` general path it reaches Postgres as `LIMIT -1`, which fails the query. On the bridge feed it trips `feed_count >= limit`, so the feed comes back empty. - A limit that is a multiple of 2^32 wraps to `0` through `as u32`. That returns no rows (one row in the window, via `.max(1)`) instead of the page max. Bridge thread and HTTP search already clamped before casting. COUNT drops the row limit, so it was not affected. ## Change - Add `buzz_core::filter::clamp_limit(limit, default, max) -> u32`. It returns `default` when the limit is absent; otherwise it saturates the request to `u32` and then caps it at `max`. - Use it at every filter-limit site: `filter_to_query_params` and WS search in `handlers/req.rs`; channel window, feed, thread and HTTP search in `api/bridge.rs`. The inline casts are deleted, and `BRIDGE_FEED_MAX_LIMIT` is now `u32`. - Each site keeps its default, max and `limit: 0` behaviour. In-range limits are unchanged. ## Testing Failing before the fix (`cargo test -p buzz-relay --lib huge_filter_limit`): ``` assertion `left == right` failed left: Some(-1) right: Some(1000) test result: FAILED. 0 passed; 1 failed ``` After: - `cargo test -p buzz-core --lib clamp_limit` → 1 passed (table test covering absent, 0, in-range, at/over max, the u32 boundary and `usize::MAX`) - `cargo test -p buzz-relay --lib -- huge_filter_limit req:: bridge` → 152 passed, 0 failed (135 Postgres tests ignored) - `cargo clippy -p buzz-core -p buzz-relay --all-targets -- -D warnings` → clean; `cargo fmt --all` → clean - pre-push hooks (incl. rust-tests) passed ## Not covered No Postgres-backed tests were run locally. The bridge call sites rely on the shared helper's table test; they have no per-handler tests. ## Review Every server-side read of `Filter.limit` now goes through `clamp_limit`. The per-site default, max and `limit: 0` behaviour is unchanged. No inline casts are left. Scores: minimalism 9, elegance 9, correctness 9. Blockers: none. Fixed in review: - `PAGE_LIMIT_MAX` had been inserted between `filter_to_query_params`'s doc comment and the function, so the doc comment ended up on the const. Moved the const above it. - Corrected the problem statement. The bridge feed returned an empty feed rather than a Postgres error, COUNT was never affected, and thread and HTTP search were already safe. Optional: - WS search, bridge window and bridge feed have no per-handler regression test. Reverting one of them to an inline cast would not fail any test. - `bridge.rs` now has two functions called `clamp_limit`: the local moderation `clamp_limit(Option<i64>)` and `buzz_core::filter::clamp_limit`. They don't collide, but they are easy to confuse. ## Exercised on a local relay **Commit tested:** `88d76f7f1`. Dev profile, isolated harness relay on :3030, authenticated channel member. Human rate limits were raised so seeding wasn't throttled. I seeded 1,100 kind-9 events in one channel. The filters were sent as raw JSON so the large integers arrived exactly. | Path | `limit` 18446744073709551615 | `limit` 4294967296 | `limit` 50 (control) | |---|---|---|---| | WS `REQ` | EOSE after 1000 | EOSE after 1000 | EOSE after 50 | | WS `REQ` with `search` | EOSE after 1000 | EOSE after 1000 | EOSE after 50 | | HTTP `/query` | 200, 1000 events | 200, 1000 | 200, 50 | | HTTP `/query` with `search` | 200, 500 | 200, 500 | 200, 50 | | HTTP `/query` `top_level` (channel window) | 200, 201 (200 + bounds event) | 200, 201 | 200, 51 | | HTTP `/query` `feed_types` | 200, 100 | 200, 100 | 200, 50 | Every huge limit came back as that path's maximum. None of them produced a database error, and none came back empty. The relay log has no error lines, and the access log records the raw `limit` as 18446744073709551615 with `outcome:"served"`. **Postgres-gated tests:** the PR adds or modifies none. As a related check I ran `cargo test -p buzz-relay --lib -- --ignored limit`. Run in parallel, it gave 10 passed and 1 failed: `rate_limited_query_logs_one_denied_line`. That test passes on its own, and the whole set gives 11 passed with `--test-threads=1`. It looks like interference between tests that share the access-log capture, not a problem with this change. **Not exercised:** - Bridge thread path. - A before/after comparison against main. Signed-off-by: David Grochowski <dgrochowski@squareup.com> |
||
|
Logan Johnson
|
b483bbe765 |
fix(mobile): tell same-name agents apart in Solo (#9321)
## Summary
In Solo, two agents with the same name looked identical: the agent
picker, the new-chat draft ("Message Atlas"), the chat header and its
agent switcher, and the "working" label all showed the raw name. Now
they use the same disambiguated labels as the rest of the app, so
same-name agents read differently everywhere in Solo, and one agent
reads the same in every place.

### Related issue
None found.

### Testing
Widget tests open the picker and header with two same-name agents,
switch between them, and archive one (the remaining agent goes back to
its plain name). Further tests cover a saved agent switch and a resumed
new chat that still point to an archived agent with a live namesake, and
Solo rows with no working agent building no names. A focused test covers
which name Solo shows. Each fails without its change.

Android emulator, local relay, fictional names. Two live agents are both
named Helper; Atlas and Scout each have an archived namesake, which Solo
already left out.

**New Solo chat › Choose an agent: two agents named Helper**

| Before | After |
| --- | --- |
| <img
src="https://github.com/user-attachments/assets/ff43e3cd-d8f3-4555-bc6b-6109b57993c0"
width="320"> | <img
src="https://github.com/user-attachments/assets/b1a73f63-fe00-49f8-b6ff-0c6a6cfc2d82"
width="320"> |

**New-chat draft with one Helper picked**

| Before | After |
| --- | --- |
| <img
src="https://github.com/user-attachments/assets/4f375e0c-ce82-4787-b187-137ca25449ce"
width="320"> | <img
src="https://github.com/user-attachments/assets/d8626e98-e1db-437d-9824-cf83af26d752"
width="320"> |

**Chat settings › Agent row of an existing Solo chat**

| Before | After |
| --- | --- |
| <img
src="https://github.com/user-attachments/assets/e7b0d3a0-10d2-4140-b5c0-b4a3857085ae"
width="320"> | <img
src="https://github.com/user-attachments/assets/e6a736ec-24af-4142-ba3f-1c68f64d80f7"
width="320"> |

**Agent switcher opened from that row**

| Before | After |
| --- | --- |
| <img
src="https://github.com/user-attachments/assets/8eb1a66d-ff6d-4dc2-8df7-6c71732f186d"
width="320"> | <img
src="https://github.com/user-attachments/assets/9669231f-d842-4d32-bb13-ecd6a2b01e8f"
width="320"> |

## Details
- Names are compared only across the agents Solo offers. Archived agents
are already left out of that list, so an archived namesake adds no
qualifier.
- A saved choice can still point to an archived agent: a pending agent
switch (its notice and the Resume/Discard dialog) or a new chat waiting
to be resumed. That agent is labeled against the live agents, so it does
not read exactly like a live namesake.
- A Solo row reads names only while an agent is working in it, and
working rows share one name context.
- The chat header reads Solo names only in Solo chats, so channel and DM
pages no longer rebuild on every profile load (from
https://github.com/block/buzz/pull/9324 by Tom Brow).
- Solo keeps showing the owner's own name for an agent (from their agent
list) ahead of the agent's self-published profile name. A verified name
still wins over both.
- An agent with no name now shows the short npub, like every other
picker, instead of a truncated hex key.

🤖 Generated with [Claude Code](https://claude.com/claude-code)

---------

Signed-off-by: Logan Johnson <loganj@squareup.com>
Signed-off-by: Tom Brow <tomb@squareup.com>
Co-authored-by: Larry <627498bd4bd1f281a16431e3c6cce3b5c25b6692798c78672298aefbf2f8f8b5@buzz.block.builderlab.xyz>
Co-authored-by: Claude Opus 5.5 <noreply@anthropic.com>
Co-authored-by: Tom Brow <tomb@squareup.com>
Co-authored-by: corey <2dafccf60ea6d431a568f6d67fc600160d92a51e415e09dc8b213b8e360663d5@localhost>
Co-authored-by: studio <dc2fc481343672df31a689840c09299972e704dac592e0da6f18486646a7ee3e@localhost>
|
||
|
Tom Brow
|
0aca7588e3 | fix(mobile): join an open channel from the chat footer (#9253) mobile-v1.0.0-rc.2 | ||
|
Logan Johnson
|
30e1fa47fb |
fix(relay): fence pending subscriptions on close or replacement (#2382)
## Summary A REQ handler runs as a spawned task and can pause in its access checks. Before this change it took its subscription ID only when it registered. So: - `REQ x`, then `CLOSE x` while the REQ was still in its access checks: the relay sent `CLOSED x`, and then the REQ registered `x` anyway and sent events and `EOSE` under an ID the client had closed. - `REQ x` (A), then a newer `REQ x` (B): if A finished its checks after B registered, A replaced B, or A's refusal retired B and sent a `CLOSED` the client could not tell from B failing. Now the read loop admits each REQ and sync REQ, in arrival order, before it spawns the handler: the newest request owns the ID from the moment it arrives. A `CLOSE` or a newer same-ID request fences an older one that is still pending. A fenced request does not register, and does not send `NOTICE`, `CLOSED`, `EVENT` or `EOSE` for the ID. This builds on the owner token and lifecycle lock that #8522 added. That PR fenced output after registration; this one moves the token to admission, so the same fence also covers the time before registration. The pubsub retain no longer waits on a full subscriber command queue. Callers hold a connection's lifecycle lock while they retain. A retain past a full queue now leaves a coalesced wake-up, and the subscriber subscribes every retained topic it is missing. A retain that fits in the queue leaves no wake-up, so first retains do not each make the subscriber rescan the map. ## Behavior - `close::admit` runs in the read loop before spawn. It records the request's token in the connection's subscription map, with a flag that says whether the request has claimed yet. It also applies the subscription limit, which moves there from the handlers. - Claims (`claim_admitted_live`, `claim_admitted_search`, the sync claim) register only while the request still owns its token. - Refusals after admission go through `close_if_owner`. The two REQ refusals that also send a `NOTICE` send it in the same critical section. - Refusals before admission (rate limit, admission quota) still retire the old holder, as before. - The old holder stays registered until the newer request claims or is refused, as before. - A channel-access eviction that removes an old holder while a newer same-ID request is still pending retires only the old holder. It sends no `CLOSED` for the ID, because the client already replaced that holder, and the newer request still claims. Client-visible changes to the subscription limit: - The limit is checked on arrival, before scope, auth and filter checks. On a full connection, a REQ for a new ID that would also fail those checks now gets `CLOSED "error: too many subscriptions"` instead of the other refusal. - Requests still in their access checks count toward the limit. ## Scope Live fan-out does not check the token. A same-ID request that has arrived but not yet claimed does not stop live events to the old holder. That path is unchanged here. If a handler panics before it claims, its token stays in the map until a `CLOSE`, a same-ID REQ, or the disconnect removes it. Until then it counts toward the subscription limit. ## Testing - `close_fences_a_req_whose_handler_has_not_run` (REQ and sync REQ): `REQ x` then `CLOSE x` before the handler runs gives only `CLOSED x` and no registration. - `only_the_newest_same_id_req_answers`: of two same-ID REQs, only the newer one answers. - `superseded_or_closed_requests_cannot_claim`: an older request cannot claim after a newer one, and a closed request cannot claim or close. - `revoke_of_a_replaced_holder_spares_the_pending_replacement`: a revoke of the old holder sends no `CLOSED`, keeps the pending request's token, and the pending request then claims its own channel. - `queue_full_retain_does_not_wait_and_schedules_reconciliation` (pubsub). - `live_subscriber_recovers_a_dropped_subscribe_hint` (pubsub, requires Redis): it runs the real subscriber on a live link and drops a topic's subscribe hint with a full queue. The topic is still delivered without a reconnect and without `Confirm`. The same holds after the topic is released, unsubscribed and retained again. - Mutations: with no owner check in `close_owned`, both connection tests fail. With no owner check in `claim_admitted_live`, the claim test fails. With no `replaced` check in the eviction, the revoke test fails. With no reconcile arm in the subscriber, or no `notify_one` in `retain_topic`, the Redis subscriber test fails. - CI: the four new relay tests and the full-queue pubsub test are added to `just test-unit` and `scripts/run-tests.sh`. The Redis subscriber test runs in a new Redis-backed backend-integration step. - `cargo test -p buzz-relay --lib` (with `--skip config::tests`, which hangs locally when run in one process), `cargo test -p buzz-pubsub -- --include-ignored` against a local Redis, `cargo clippy -p buzz-relay -p buzz-pubsub --all-targets -- -D warnings`, `cargo fmt --all -- --check`. 🤖 Generated with [Claude Code](https://claude.com/claude-code) --------- Signed-off-by: Logan Johnson <loganj@squareup.com> Co-authored-by: Larry <627498bd4bd1f281a16431e3c6cce3b5c25b6692798c78672298aefbf2f8f8b5@buzz.block.builderlab.xyz> Co-authored-by: Claude Opus 5.5 <noreply@anthropic.com> |
||
|
Logan Johnson
|
dd2d3cf4ea |
fix(mobile): hide archived people and agents from choices; give them their own members section (#9320)
## Summary Mobile kept offering archived people and agents as choices: Add members (including adding an agent to a Solo chat), New DM, the `@` mention chooser, Search › People and the Agents page. An archived agent that shares a live agent's name also forced a qualifier onto the live one, because names were told apart across both. The members sheet listed archived members among live ones with nothing to mark them. Now, matching desktop: - Archived people and agents are left out of those choices. History (messages, activity, profiles) still shows them. - The members sheet moves archived members out of People and Agents into their own "Archived · N" section after both: archived people, then archived agents. Each row reads "Archived · Member" (or Agent) in place of the role, status or "Working…" line. A screen reader reads it with the name. The members preview on the channel info page (the first five members above "See all") follows the same order and label. - Nothing is hidden or marked while the community's archive list is unknown or cannot be read, and you are never hidden from yourself. ### Related issue None found. The desktop members dialog gets the same Archived section in https://github.com/block/buzz-app/pull/3203. ### Testing Widget and provider tests cover each surface, the unknown-archive case, the viewer rule and a community switch. Each test fails without its change. Android emulator, local relay, fictional names. Each archived person or agent has a live namesake. History rows still show archived identities, as intended. **`@` mention chooser, typing "@Sc" (Scout `qsfn` is archived)** | Before | After | | --- | --- | | <img src="https://github.com/user-attachments/assets/6693729c-66c1-4433-8a7b-4f0e948057ee" width="320"> | <img src="https://github.com/user-attachments/assets/eb4f80be-780e-4dbe-8b2b-e6a5b6c3ca97" width="320"> | **`@` mention chooser, typing "@Ca" (Casey Lee `9mhy` is archived)** | Before | After | | --- | --- | | <img src="https://github.com/user-attachments/assets/b6d409cd-7af1-4da7-b5b9-deece5e21de5" width="320"> | <img src="https://github.com/user-attachments/assets/60e21387-791b-4233-b8e6-1a29f94e6810" width="320"> | **Add members, searching "Morgan" (Morgan Reyes `ssc2` is archived)** | Before | After | | --- | --- | | <img src="https://github.com/user-attachments/assets/1222a923-5e43-4263-843d-57564bdc7af3" width="320"> | <img src="https://github.com/user-attachments/assets/dbe58278-788d-4a89-83bf-f0b4bc119c5e" width="320"> | **Add members, searching "Atlas" (Atlas `85gl` is archived)** | Before | After | | --- | --- | | <img src="https://github.com/user-attachments/assets/55c67a21-4cf5-47c5-b6ac-1ba80d68a3ec" width="320"> | <img src="https://github.com/user-attachments/assets/54b19ab3-fa2f-4933-8b67-1056d6e3b3a4" width="320"> | **New DM, no query yet** | Before | After | | --- | --- | | <img src="https://github.com/user-attachments/assets/6a26fd49-4a06-47bd-ba37-37e5898ab344" width="320"> | <img src="https://github.com/user-attachments/assets/3f33eb2b-f27a-4528-91c0-ac76d3fdf44b" width="320"> | **New DM, searching "Morgan"** | Before | After | | --- | --- | | <img src="https://github.com/user-attachments/assets/22d2d617-3074-4910-8c39-e0778e47a879" width="320"> | <img src="https://github.com/user-attachments/assets/fa00b160-e350-49af-94d0-beb15c357bef" width="320"> | **Search › People, "Morgan"** | Before | After | | --- | --- | | <img src="https://github.com/user-attachments/assets/83a28f2b-9b22-4d0c-8728-8a2dfb10e634" width="320"> | <img src="https://github.com/user-attachments/assets/573aed3f-75ab-478f-8c11-bedab5c6ce4f" width="320"> | **Agents page** | Before | After | | --- | --- | | <img src="https://github.com/user-attachments/assets/d7980f95-825c-4d1a-ad67-95f906a52e9a" width="320"> | <img src="https://github.com/user-attachments/assets/6252c38a-b2ec-48dc-ab4e-824ea29bbd85" width="320"> | **Channel info, members preview** | Before | After | | --- | --- | | <img src="https://github.com/user-attachments/assets/8744cdfd-c073-4ade-bd53-9d5e137cee60" width="320"> | <img src="https://github.com/user-attachments/assets/5240b1be-13d5-4f22-85a9-8375f1d8ac18" width="320"> | **Members sheet, top** | Before | After | | --- | --- | | <img src="https://github.com/user-attachments/assets/c9241478-99b1-452e-ad41-8c38fe080182" width="320"> | <img src="https://github.com/user-attachments/assets/3c6f9247-60c6-47df-94b0-9175f25805bb" width="320"> | **Members sheet, scrolled to the end** | Before | After | | --- | --- | | <img src="https://github.com/user-attachments/assets/7da7fcc8-28ea-4c7a-904e-91ca5a068d23" width="320"> | <img src="https://github.com/user-attachments/assets/024f676e-8150-457d-b7d0-67fa1a680f8d" width="320"> | ## Details - The archive reader (the community's NIP-IA archive list, signed by the relay's NIP-11 `self` key) moves from `shared/me` to `shared/identity_archives`, since it is no longer Solo-only. `hiddenArchivedIdentitiesProvider` is the single rule the surfaces read. - Pulling to refresh on the Agents page also rereads the archive list. Other views reuse the last list, as on desktop; it is also reread on reconnect and when the agent inventory changes. - A refresh keeps the last known list. After a community or account switch, the previous community's list does not apply: nobody is hidden until the new list arrives. - The shared chooser drops archived identities before names are compared, which covers Add members, New DM and mentions. - Search › People asks the relay for 24 people and shows the first 8 that are not archived, so archived matches do not push live people out. - The channel info preview shows the label on one line, so with a long name the role after "Archived" can be cut off. A screen reader still reads it in full. - Not changed: typing a full `@Name` by hand (without the chooser) still resolves against archived channel members too, so an archived namesake can still make a typed name ambiguous. Picking from the chooser is unaffected. Possible follow-up. 🤖 Generated with [Claude Code](https://claude.com/claude-code) --------- Signed-off-by: Logan Johnson <loganj@squareup.com> Co-authored-by: Larry <627498bd4bd1f281a16431e3c6cce3b5c25b6692798c78672298aefbf2f8f8b5@buzz.block.builderlab.xyz> Co-authored-by: Claude Opus 5.5 <noreply@anthropic.com> |
||
|
klopez4212
|
b40f22114b |
Add video stacks and native iOS zoom playback (#9316)
## Summary Videos previously rendered outside photo stacks and opened only the Flutter video viewer. Message bubbles now group trailing videos and photos in their original order, with poster thumbnails or a visible play placeholder. On iOS 18+, the native zoom gallery (enabled by default) opens both standalone videos and mixed stacks with AVKit playback controls, and closing restores the selected stack item. Flutter downloads only the selected video using fresh media authentication, streams it to a bounded temporary file, and cancels/deletes it when selection changes or the viewer closes. UIKit releases the old player before that file is removed. Failed downloads and playback expose Retry. Video URLs never enter the image decoder, and photo-only actions are hidden on video pages. The existing Flutter viewers remain the fallback. Native zoom defaults on; `--dart-define=BUZZ_NATIVE_PHOTO_ZOOM=false` remains an explicit build-time opt-out. Unsupported platforms/formats, unavailable native presentation, and bridge failures use the Flutter fallback. Native video pages use Close or accessibility escape to return with zoom; the photo-specific downward drag recognizer is disabled there to avoid competing with AVKit controls. ### Related issue Stacked on #9314 (PNG/HEIC photo formats); merge that first. No matching open video-stack/zoom PR found. ### Testing - Default-on follow-up: presentation tests also cover unavailable, null, and throwing bridge responses. - `just mobile-check mobile-test`: analysis clean, 4,601 mobile tests passed, plus push-configuration and secp256k1 package tests. - Full native-enabled mobile suite: 4,626 passed, 68 skipped; rerun passed at `dc752dccaa664cb56a19cbe517a266d1407a1100`. - Mixed-stack widget journey covers order, video opening, returning to selection, and the photo-only fallback gallery. - Native bridge tests cover video snapshot presentation, selected-only dispatch, stale sessions and keeping video URLs out of image decoding. - Real HTTP download journey covers authenticated requests, Retry, byte limits, cancellation and temporary-file cleanup. - Native simulator fixture decodes a real MP4 and verifies selected-only loading, player release on paging and teardown. Removing playback cleanup makes the regression fail; restoring it passes. - No physical-device installation or end-to-end zoom recording captured. ### Widget previews Actual Flutter renders with sample video URLs and no poster metadata; these show the stack layout, not device playback. | Received, light | Sent, dark | | --- | --- | |  |  | ### Human verification pending On a normal build on iOS 18+ (no extra flag required), open a message containing photos and videos, page between them, play a video, and close. Verify playback controls work, only the selected video plays, and closing returns to the selected stack item. --------- Signed-off-by: kenny lopez <klopez4212@gmail.com> Co-authored-by: Terp <5856f6900e8e0a4e0ea1f4f8d2ee33e4753d2119bc122f94ecafc660b46c0511@buzz.block.builderlab.xyz> |
||
|
klopez4212
|
e2dc54e22f |
Support PNG and HEIC photos in the native iOS zoom gallery (#9314)
## Summary

The opt-in iOS zoom gallery rejected PNG and HEIC/HEIF photos, so photo
stacks containing those files opened the Flutter fallback. Accept these
formats by MIME type or file extension, including uppercase extensions
and URLs with query strings.

Preserve animated PNG playback by forwarding continuing decoded frames
to the selected native page. Keep the existing five-photo load window,
coalesce frames while the bridge is busy, skip offscreen frame encoding,
and release listeners on eviction or dismissal. Native updates reject
stale sessions, offscreen pages, malformed frames, and closed viewers.

`BUZZ_NATIVE_PHOTO_ZOOM` remains opt-in. iOS below 18 and unsupported
formats retain the existing gallery.

### Related issue

Follow-up to #9259. No matching open issue or PR found; #7666 concerns
desktop HEIC upload tiling, a separate path.

### Testing

- `just mobile-install mobile-check mobile-test` passed.
- Full mobile suite with `BUZZ_NATIVE_PHOTO_ZOOM=true`: 4,623 passed, 68
skipped. Standard configuration: 4,599 passed, 92 skipped; push
configuration and secp256k1 package tests also passed.
- Real PNG and HEIC decoding through the production presentation bridge;
real two-frame APNG decoding with continuing-frame and listener-cleanup
assertions.
- `scripts/test-mobile-photo-zoom.sh` on an iOS 27 simulator exercises
the production native controller, including frame updates, stale-page
rejection, malformed input and teardown.

No physical-device or end-to-end zoom recording captured. This extends
accepted image formats and playback without changing the gallery layout.

---------

Signed-off-by: kenny lopez <klopez4212@gmail.com>
Co-authored-by: Terp <5856f6900e8e0a4e0ea1f4f8d2ee33e4753d2119bc122f94ecafc660b46c0511@buzz.block.builderlab.xyz>
mobile-v1.0.0-rc.1 |
||
|
Tom Brow
|
13a6aa19f4 |
fix(mobile): list known people in recipient pickers before a name is typed (#9311)
## Problem Add members (and New DM, which shares the picker) showed an empty list until the first character was typed. An empty query runs no directory search, so the only candidates were the viewer's own agents and agents shared with them. Once those are members, or while the owned-agent list is still loading, nothing is left. `@` completion shows the channel's members before a name is typed. A recipient picker has no channel to draw from, so this lists the people the viewer already knows instead. ## Change - With an empty query, `recipientCandidatesProvider` adds people from the viewer's open channels and DMs (from the member lists the channel list already loaded). Add members skips the target channel's own members before choosing. The 50 people (`mentionSuggestionLimit`) are gathered from DMs first, then channels, and shown in the usual label order. - Empty-query rows list agents ahead of known people, so people never push an agent off the 50-row list. When an agent the opening hasn't offered yet arrives after rows were shown (the viewer's own agents loading late, a picker opened mid-reload, or a reconnect that brings a new agent), the people rows start over so it takes its place ahead of them; agent rows already shown keep their places, including one whose list is still reloading. A reload that brings no new agent moves nothing, and typed rows never restart. Known people don't wait for the agent lists, which never load offline. - Member lists carry no profiles, so the unnamed people among the 50 are loaded through the user cache's batched preload, each person once per picker opening regardless of rebuilds. - The roster scan stops at 50 people or 2,000 roster entries, whichever comes first, and doesn't copy rosters. - Typed queries and `@` completion are unchanged: same ranking, directory search only, no known-people rows mixed in. ## Why nothing gets worse - Network: at most 50 profile reads per opening, batched, only for uncached people, and never repeated on rebuilds (new messages, presence, profile updates). - CPU: at most 2,000 roster entries per rebuild, only while a picker shows an empty query. - Agents: every agent the picker listed before still lists, ahead of the new rows. - Ranking, selection, typed search, the viewer and unshared-agent filters, and "Add members hides existing members" are unchanged. ## Validation - Added tests: `recipient_known_people_test.dart` (empty query lists people from open channels and DMs, excludes archived and non-member channels, loads a missing name; agents stay ahead of people and people don't wait for an unloaded agent list; the real user cache reads each unnamed person once across rebuilds; Add members skips the channel's own members; at most 50 people are gathered; typed query adds nothing) and `recipient_late_agents_test.dart` (Add members sheet with a controllable own-agent list and 60 known people: agents arriving on first load, in a picker opened mid-reload, and on a reconnect that adds a new agent all take rows ahead of the people; reload, land, reload, land moves nothing; typed rows keep their places; 55 agents fill the list and stay put across reloads and a rename that changes their order; both agent lists reloading after a reconnect and landing in either order, with a new agent in the first, keep every earlier agent's row). Confirmed the late-agent tests fail without the restart. Confirmed the ordering and read-once tests fail without their fixes. Confirmed the first test fails without the fix. - Focused existing validation: `flutter test test/features/channels` (2,308 passed), `flutter analyze` on the changed directory. - Automated app run (on an earlier head; iOS 27 simulator, iPhone 17 Pro, a Builderlab test account): opened a private channel, Channel details, Add members. Before: only the account's own agents. After: agents, then people from its channels and DMs with names and avatars; typing `ar` still narrows to directory matches. Captures show real community members, so they were shared internally rather than embedded here. Native iOS sheet only; Android and New DM share the provider but were not run in the app. 🤖 Generated with [Claude Code](https://claude.com/claude-code) --------- Signed-off-by: Tom Brow <tomb@squareup.com> Co-authored-by: Tom Brow <tomb@squareup.com> Co-authored-by: studio <dc2fc481343672df31a689840c09299972e704dac592e0da6f18486646a7ee3e@localhost> Co-authored-by: studio <dc2fc481343672df31a689840c09299972e704dac592e0da6f18486646a7ee3e@buzz.block.builderlab.xyz> Co-authored-by: Claude Opus 5.5 <noreply@anthropic.com> |
||
|
Logan Johnson
|
6384c6cdfa |
feat(mobile): mark edited messages after the body (#8863)
## Summary Mobile showed "(edited)" only in the author header. A grouped follow-up message has no header, so an edited follow-up had no marker at all. This ports the placement from desktop https://github.com/block/buzz-app/pull/2020 to the channel and thread message bodies: - **After prose:** the marker joins the last line, for example `Hi how are ya. (edited)`. This includes a final list item or quote, as on desktop. It is drawn in the timestamp style, with the metadata colour on received messages and the bubble ink on your own messages. - **After a block that text cannot join:** the marker goes on its own line inside the same text bubble. This applies to code, tables, rules, display math, indented code, a heading, a last line that ends in a link, and a bare list, quote or checkbox marker. A link renders as a widget span, so a joined marker would be read before the link by screen readers. Any body that contains ```` ``` ```` always uses its own line. gpt_markdown's fence rules differ from CommonMark, so putting the marker inside the Markdown could change how the code renders. - **After trailing images:** the marker goes below the gallery, outside the bubble. - The marker is injected only at render time: a private-use slot character that the renderer removes from authored content first. Copy text, previews and notifications still use the original message content. **Out of scope:** the mobile forum models (`ForumPost`, `ThreadReply`) have no edited state and don't fold edits, so forum posts still show no marker. Search and inbox previews also show no marker, which matches the preview rules. ### Related issue Desktop parity for https://github.com/block/buzz-app/pull/2020. I found no existing mobile issue or PR for this. ### Testing At `5276d968`: - `just mobile-check`, `just file-size-check` and `just mobile-test` all exit 0. - `edited_marker_test.dart`: a table test of which endings join inline and which take their own line, including `` ```npm install``` ``, `~~~`, indented code, tables, rules, math and bare block markers. - `message_content_bubble_cases.dart`: rendered widget checks. For each risky ending, the edited render is the unedited render plus one `(edited)` line inside the same text bubble. The tests also cover colours, trailing media, an open `<u>` and authored slot characters. With the guards removed, this test fails. - `channel_detail_page_test.dart`, edit journey: an edited message and an edited grouped follow-up are marked and an unedited message isn't. Copy text copies `Edited text` without the marker. Opening the thread marks the edited head and the edited reply. With the thread wiring removed, this test fails. - Contrast (from review): received 5.34:1 light and 8.61:1 dark; own-bubble accents at least 4.60:1. - Android emulator run (screenshots below): every edited case shows the marker where the rules above say, in light and dark. Not done: iOS simulator and VoiceOver. - Found during the emulator run, not caused by this PR: an edit made to a thread reply before the thread is opened is not loaded, so the reply shows its original text and no marker. The thread query asks only for content kinds, and the channel history did not supply the earlier edit. An edit that arrives while the thread is open shows correctly (screenshot). **Android emulator** (debug build of `5276d968` on a local relay, seeded with edited messages): | Prose, grouped follow-up, own bubbles, list | Code block, table, fenced inline text, trailing image | | - | - | |  |  | | Dark | Dark, trailing image | Thread (edit arrived while open) | | - | - | - | |  |  | 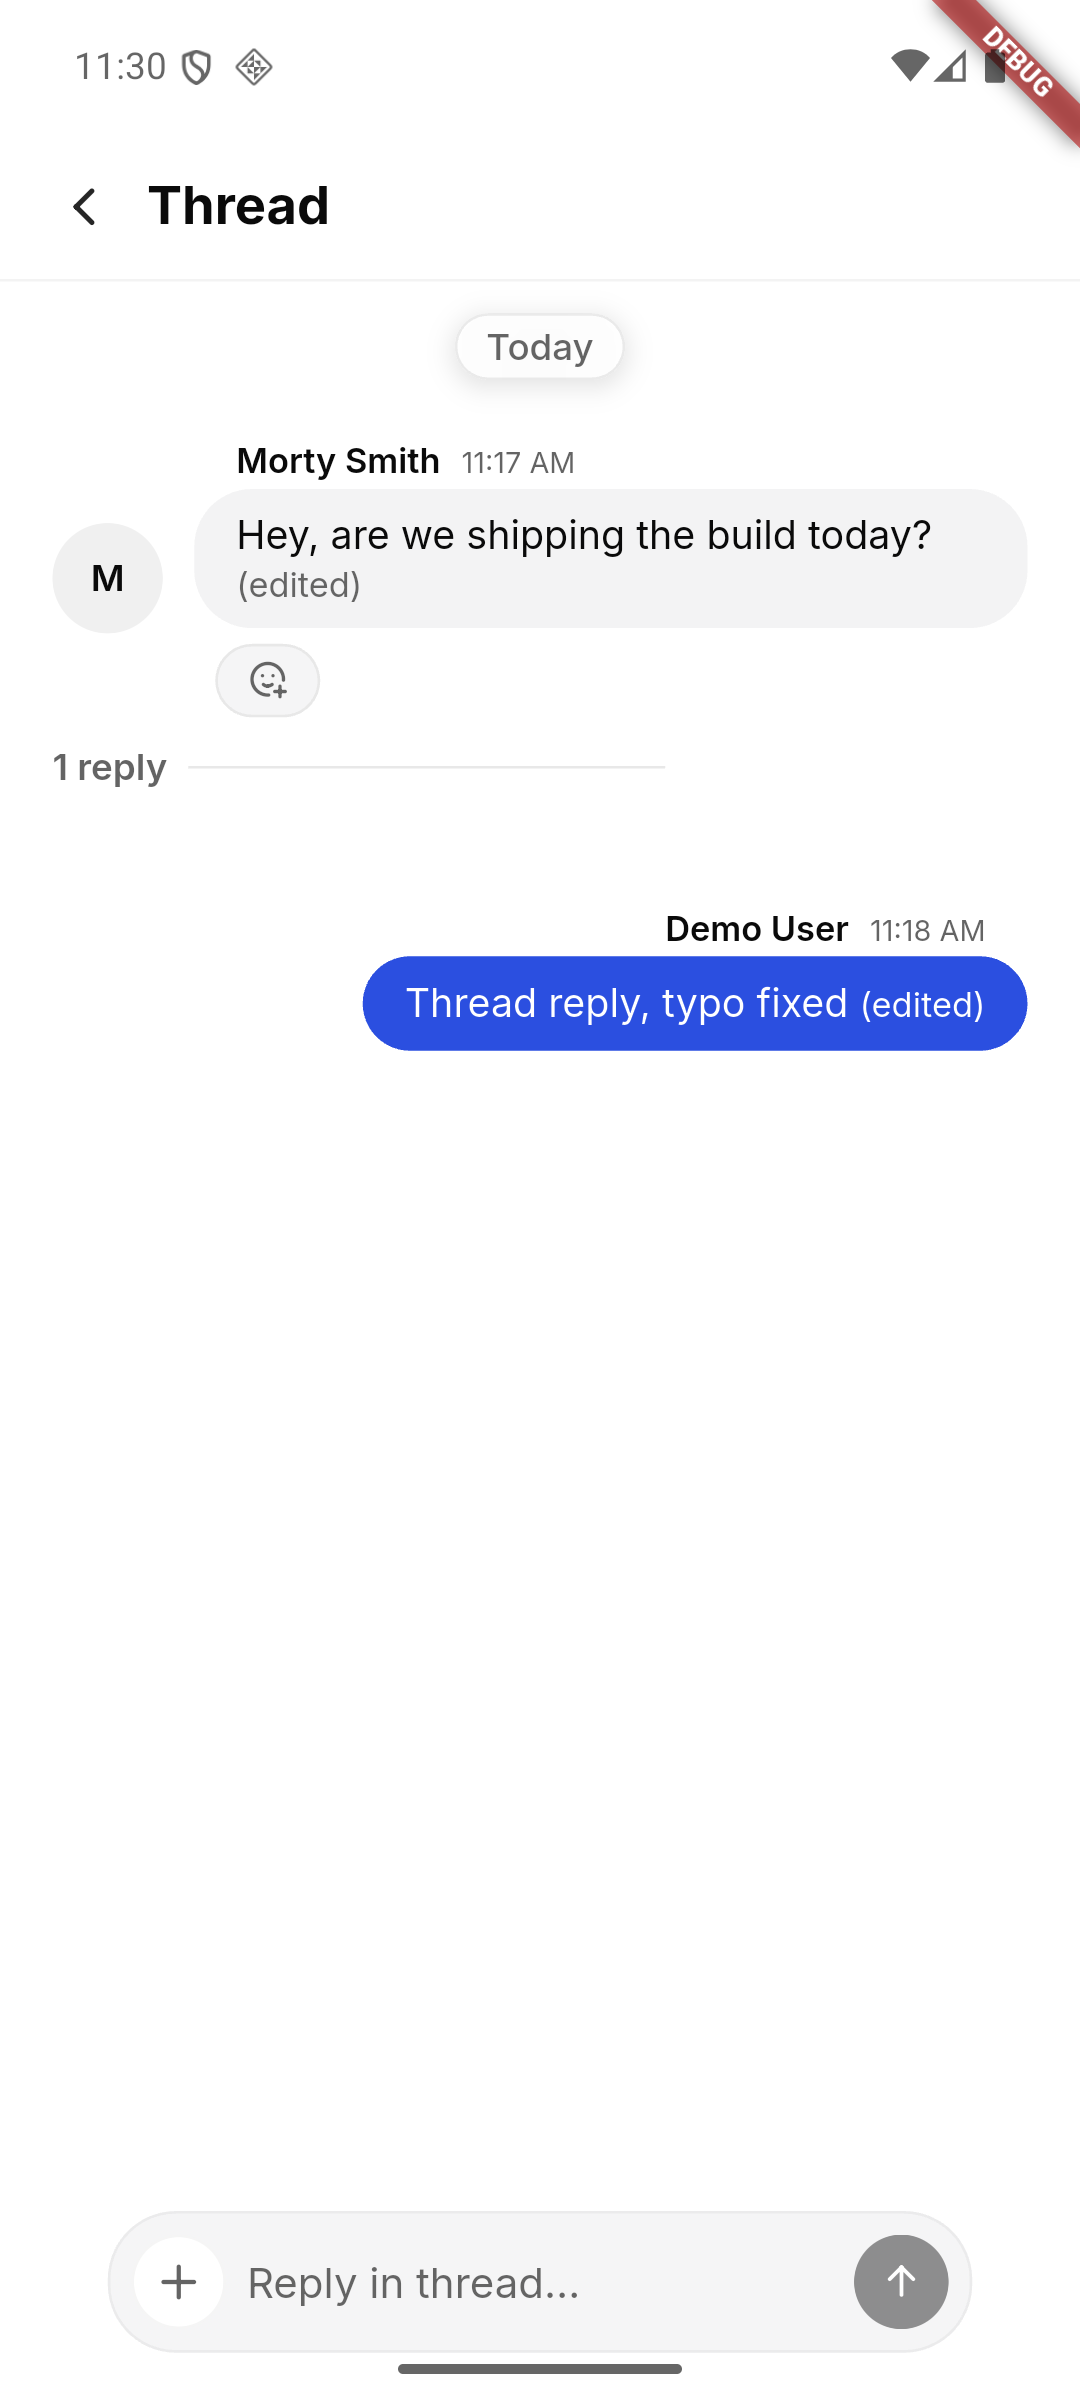 | **Widget renders** (throwaway test, not committed): | Light | Dark | | - | - | | 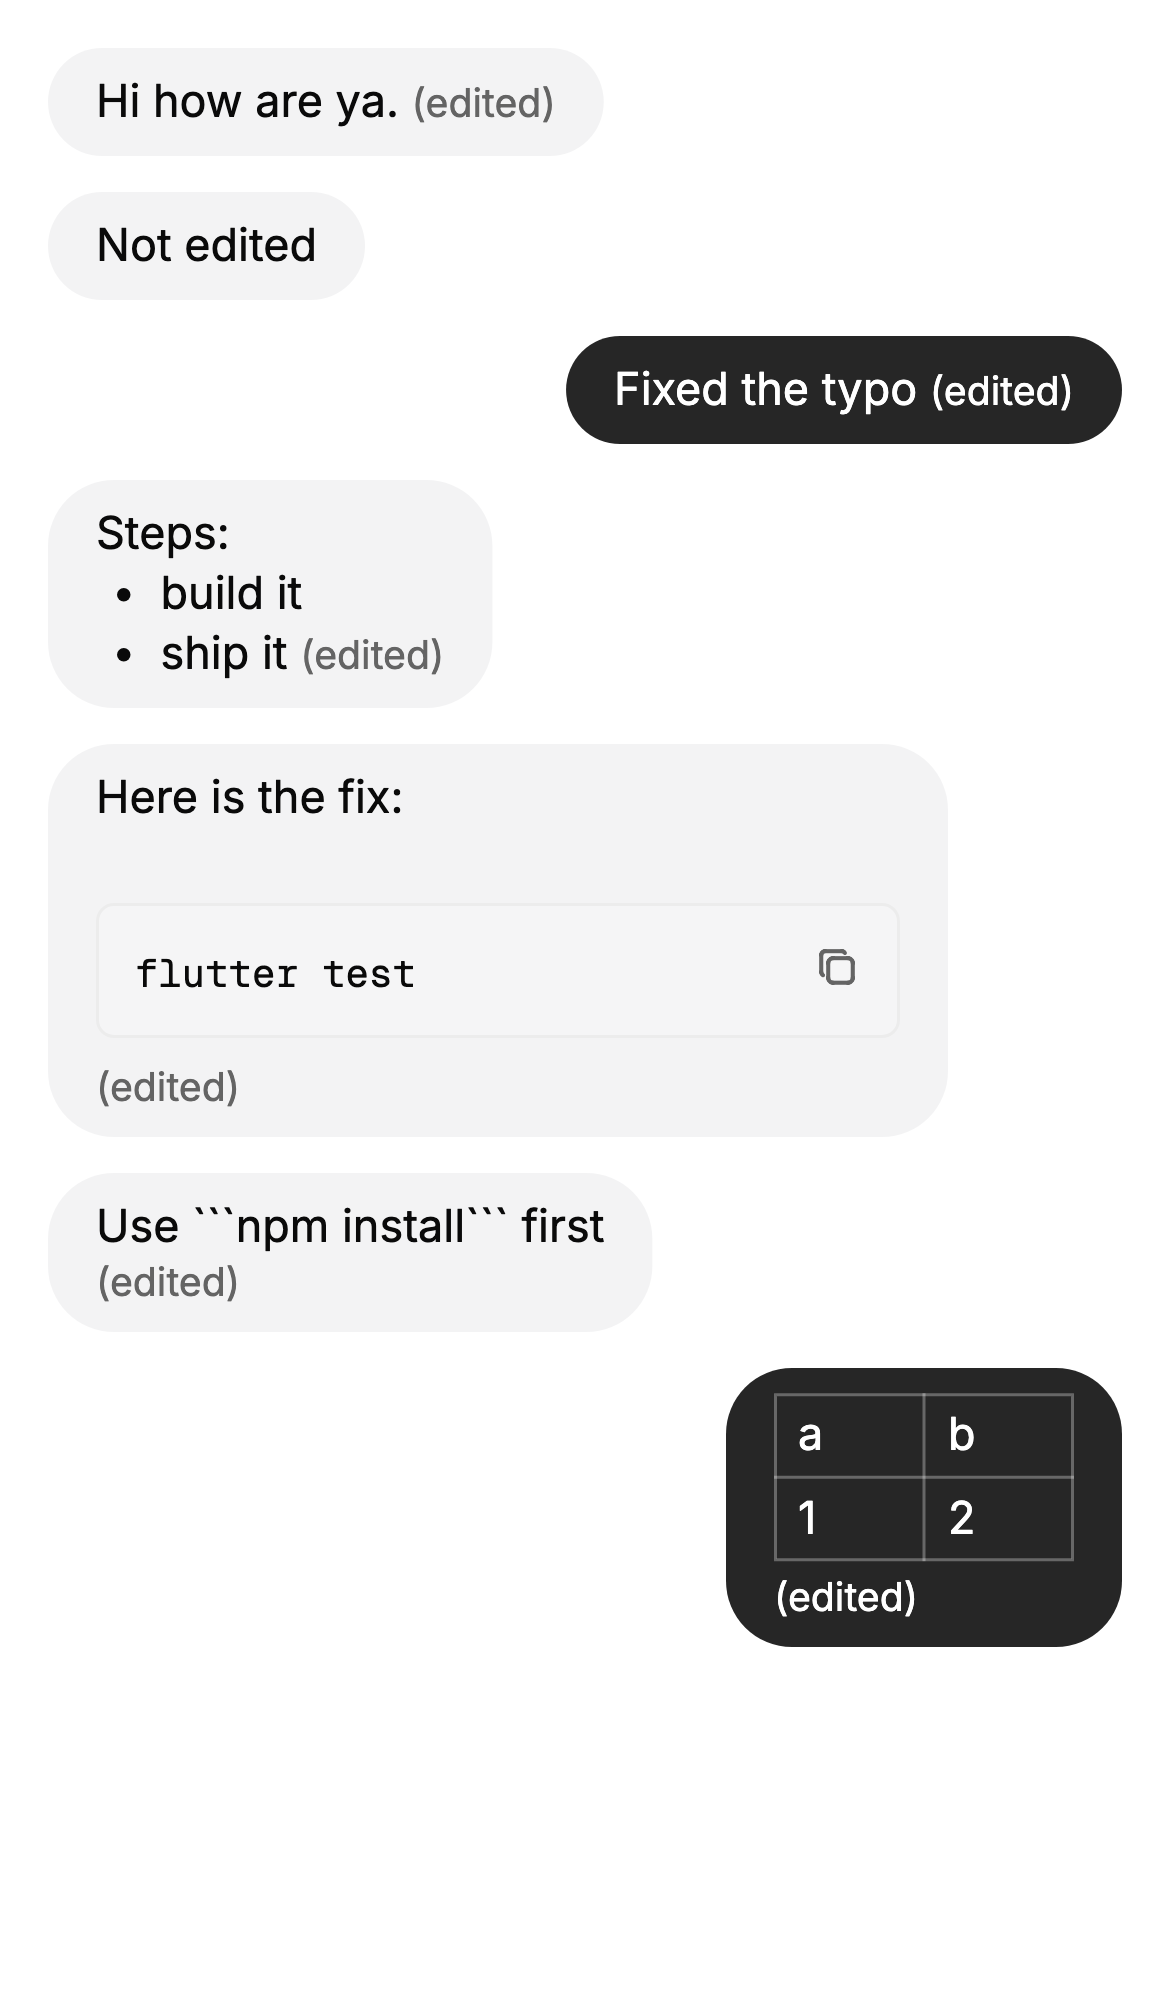 | 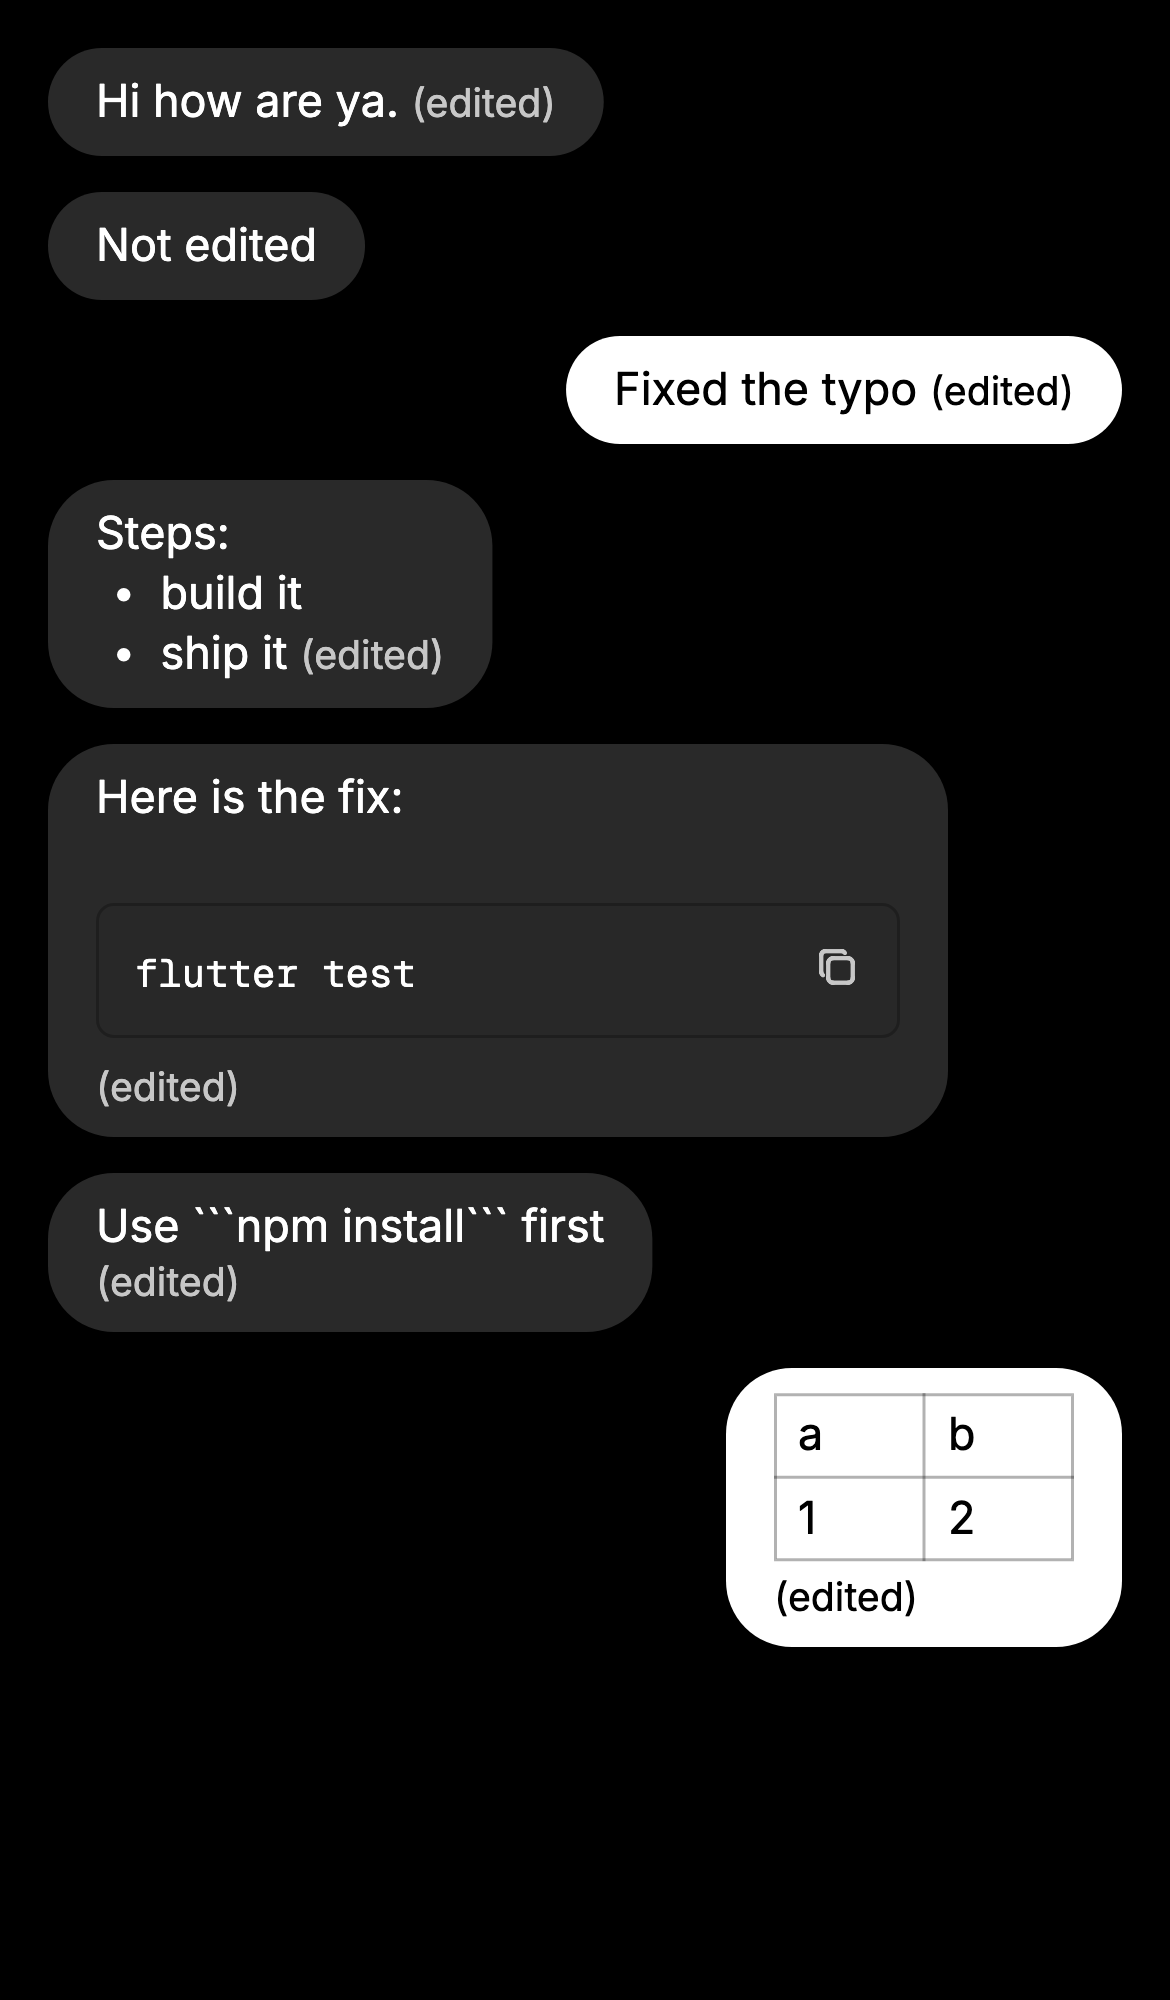 | 🤖 Generated with [Claude Code](https://claude.com/claude-code) --------- Signed-off-by: Logan Johnson <loganj@squareup.com> Co-authored-by: Larry <627498bd4bd1f281a16431e3c6cce3b5c25b6692798c78672298aefbf2f8f8b5@buzz.block.builderlab.xyz> Co-authored-by: Claude Opus 5.5 <noreply@anthropic.com> |
||
|
klopez4212
|
44b3c4823f |
Add swipeable photo stacks and native iOS gallery preview (#9259)
## Summary Replace bubble photo carousels with swipeable, overlapping photo stacks, with distinct sent/received layouts and a stationary photo count. Opening and closing the gallery preserves the selected photo. Photo frames follow the active theme. Add an opt-in iOS 18+ native zoom gallery (`BUZZ_NATIVE_PHOTO_ZOOM=true`) with paging, continuous dot scrubbing, preview-backed loading, Reply/More actions, and Liquid Glass controls on iOS 26+. The existing gallery remains the fallback. UIKit’s late corner settling and brief return-transition input lockout remain known preview limitations. ### Related issue None found. ### Testing Validation: full mobile pre-push checks/tests passed on `2b5bac3075`; light/dark sent/received widget renders verified. Earlier native simulator checks covered paging, scrubbing, downward close, and Reply. Snapshots below are actual Flutter widget renders with sample photos (not device screenshots). | Before: carousel | After: sent | After: received | | --- | --- | --- | |  |  |  | | Dark mode: sent | Dark mode: received | | --- | --- | |  |  | --------- Signed-off-by: kenny lopez <klopez4212@gmail.com> Co-authored-by: Terp <5856f6900e8e0a4e0ea1f4f8d2ee33e4753d2119bc122f94ecafc660b46c0511@buzz.block.builderlab.xyz>mobile-v0.28.0-rc.11 |
||
|
Luke Tornquist
|
e8a4bc1591 |
ci(docker): skip relay image publishes for main pushes outside the build context (#9310)
## Summary Every push to `main` published a new relay and push gateway image, even when it only changed `desktop/`, `mobile/`, `docs/` or other paths `.dockerignore` keeps out of the Docker build context. Deployments that track the sortable `main-<commit UTC>-<7>` tag then rolled their relays onto an image built from identical inputs. The `push` trigger now skips the directories excluded from the build context (`desktop/`, `mobile/`, `docs/`, `bin/`, `sidecars/`, `.github/`) and re-includes `.github/workflows/docker.yml`, which defines the build. Tag pushes (`relay-v*`) still always publish, because GitHub does not evaluate path filters for tag pushes. Pull request builds keep their existing allowlist. ## Guard `scripts/test-relay-image-eligibility-workflow.sh`, which `ci.yml` runs, now requires the push filter to be exactly, in order: 1. `"**"`, 2. only `"!<dir>/**"` exclusions, each also listed in `.dockerignore`, 3. the `.github/workflows/docker.yml` re-inclusion. Comment and blank lines inside the list are skipped rather than ending it. So nobody can add a file exclusion, exclude a directory Docker sees, or reorder the re-inclusion in a way that hides a change to the image. ## Testing - `scripts/test-relay-image-eligibility-workflow.sh` passes. - The guard fails with a specific message for each of these: `"!crates/**"` added, `"!Cargo.lock"` added, single-quoted `'!Cargo.lock'`, the re-inclusion moved before `"!.github/**"`, `"**"` removed, and `"!crates/**"` appended after a comment or a blank line. - `actionlint` passes on `docker.yml`. ## Simpler The image is published only when its inputs can change. This removes no-op staging rollouts, plus the cancelled or queued Docker runs that each merge to main caused. No new concepts: the filter reuses `.dockerignore` as the only definition of what the image sees. Identified follow-up: root-level Markdown (for example `README.md`) is in the build context, so root-docs-only merges still publish. Skipping them would need a `.dockerignore` entry and a file-level filter rule, which the guard currently rejects on purpose. 🤖 Generated with [Claude Code](https://claude.com/claude-code) --------- Signed-off-by: Luke Tornquist <tornquist@squareup.com> Co-authored-by: Elrond <28d6302a099e5225b02c4155ac4236e4912603df2ab08dbfc2f4fef08ce598c8@buzz.block.builderlab.xyz> Co-authored-by: Claude Opus 5.5 <noreply@anthropic.com> |
||
|
ravarora2
|
3e9d2e90ce |
Add manual-only relay image publishing (#9303)
## Summary Add **Manual relay image**, a manual-only GitHub Actions workflow that builds and uploads a Buzz relay image from a chosen repository branch, tag or full commit SHA. It does not wait for normal CI checks or require the chosen source to be merged to `main`. This PR changes only `.github/workflows/docker-manual.yml`. It adds no scripts or runbook. The normal Docker release workflow and existing staging-only workflow are unchanged. ### What the workflow does 1. Resolves `source_ref` to one exact source commit. 2. Builds the existing Dockerfile's `runtime` target on native AMD64 and ARM64 runners. 3. Uploads each architecture to `ghcr.io/block/buzz` using the existing `GITHUB_TOKEN`. 4. Publishes a unique `manual-<source-sha12>-<run-id>-<attempt>` tag when both builds succeed. 5. Verifies that the published image contains exactly one runtime for each architecture and that both runtime source labels match the selected commit. 6. Reports the source SHA, registry tag and combined digest in the run summary and a downloadable JSON artifact. There are no push, pull-request or scheduled triggers. The workflow does not run the test suite, wait for `ci.yml`, or require a successful CI qualification. The source must still build successfully, and image verification must succeed before the workflow reports success. ### Run from GitHub UI 1. Open [Buzz Actions](https://github.com/block/buzz/actions). 2. Select **Manual relay image**. 3. Click **Run workflow** and select `main` or the repository branch containing the workflow definition you want to run. 4. Enter your block/buzz branch, tag or full SHA in **source_ref**. Example: `fix-db-timeout`. The commit must be reachable from a repository branch; PR refs and PR-only commits are rejected. 5. Click **Run workflow** and wait for both builds and **Publish and verify the combined image** to succeed. 6. Open the run summary and copy its registry tag and digest. **`source_ref` is the code you want to build.** The workflow branch selects the build instructions and may be non-main; CLI `--ref` selects that branch. Your source branch does not need to merge. This new workflow appears in the UI once its definition is on the default branch. ### Run from CLI You need GitHub CLI authenticated as a collaborator who can run workflows. No repository checkout, laptop Docker setup, AWS login or personal package-publishing token is required. ```bash # First-time GitHub CLI login only; skip if already authenticated. gh auth login --hostname github.com --web # Replace this with your Buzz branch, tag or full commit SHA. export BUZZ_SOURCE_REF='fix-db-timeout' gh workflow run docker-manual.yml \ --repo block/buzz --ref main \ -f source_ref="$BUZZ_SOURCE_REF" # Find YOUR new run; its title includes the selected source_ref. gh run list --repo block/buzz --workflow docker-manual.yml \ --event workflow_dispatch --limit 5 export BUZZ_RUN_ID='REPLACE_WITH_YOUR_RUN_ID' gh run watch "$BUZZ_RUN_ID" --repo block/buzz --exit-status gh run view "$BUZZ_RUN_ID" --repo block/buzz --web ``` ### Source and workflow selection Dispatch may use `main` or another branch in `block/buzz`. CLI `--ref` selects the workflow definition; `-f source_ref=...` separately selects the code to build. For example, `--ref feature/build-tooling -f source_ref=fix-db-timeout` runs the feature branch's workflow against the fix branch's code. The dispatcher is responsible for selecting trusted workflow instructions. The resolver has no package-write permission and runs no selected-source scripts. It validates the input, fetches canonical branch histories, and proves the selected commit is reachable from a repository branch before either publishing job can start. A full SHA cannot bypass the PR-ref restriction. Tags that point only to unreachable or PR-only commits are rejected too. Before this new workflow is registered on the default branch, its exact definition can be tested through the existing workflow path on the isolated test branch: ```bash gh workflow run docker.yml --repo block/buzz \ --ref codex/manual-relay-image-test -f source_ref=fix-db-timeout ``` This runs a fresh build of the selected repository source. It does not modify the default branch's normal workflow. ### Image output and deployment The summary reports an immutable reference such as `ghcr.io/block/buzz@sha256:...`. The `manual-image-<run-id>-<attempt>` artifact contains the same digest, source identity and per-architecture digests. Keep the actual `manual-*` tag as deployment/version metadata alongside the digest. No synthetic `sha-*` deployment tag or registry alias is emitted. The image registry is shared by consumers; the workflow does not select staging or production. Downstream deployment configuration selects the image digest and environment. This workflow does not edit deployment manifests, sync Argo CD, restart workloads, overwrite normal release tags, or upload directly to AWS ECR. Any downstream cache import and deployment are separate operations. Manual images do not receive the normal CI deployment-eligibility attestation. They are not automatically eligible for canonical promotion. The selected code and any skipped checks must be evaluated before an explicit deployment. ### Testing The earlier implementation completed a real two-architecture build and publish in [run 42704887052](https://github.com/block/buzz/actions/runs/42704887052). Its image was also verified in the downstream ECR cache. The build-and-publish path passed [run 42713322329](https://github.com/block/buzz/actions/runs/42713322329) for unmerged source `beda6eeaec8ca4a00231a05a079eb168d2a6aec2`. Both native builds and combined-image verification succeeded. That run predates the source restrictions added during review. The current resolver and workflow-origin guard were executed directly from this YAML against local Git fixtures: 19 source cases and 3 origin cases passed. These include accepting internal branches/tags/ancestor SHAs and rejecting PR refs, the raw SHA of a PR-only commit, unreachable tags, malformed inputs and a foreign repository. Main and non-main workflow refs are both accepted in block/buzz. Live resolution of a block/buzz feature branch also passed. The exact image verifier passed valid-image cases and rejected missing/duplicate platforms, wrong architecture and wrong source. No deployment was started. Full local `just ci` stopped at the existing mobile formatting check (exit 65), with an unresolved `flutter_lints/flutter.yaml` include. The repository-wide check is not green; no mobile source was changed by this PR. ### Related issue No matching issue found. The existing staging-dev workflow publishes to a distinct staging-only package and accepts branches/tags; this workflow adds general manual publication and raw commit selection. <img width="1465" height="821" alt="Screenshot 2026-11-09 at 5 55 42 PM" src="https://github.com/user-attachments/assets/6a78b31f-9646-4f19-b44a-116c16818331" /> --------- Signed-off-by: Ravneet Arora <rarora@squareup.com> |
||
|
Tom Brow
|
402bd1897f |
fix(mobile): bump Flutter to 3.47.9 for Android TLS fix (#9309)
Flutter 3.47.7's bundled Dart TLS verifier on Android misses Android's compromised-intermediate blocklist and, on Android 14+, reads the older CA directory ([GHSA-frr6-h895-5pxp](https://github.com/dart-lang/sdk/security/advisories/GHSA-frr6-h895-5pxp)). An on-path attacker can therefore impersonate the relay to Android builds with a certificate chained to the compromised eMudhra intermediates. Flutter 3.47.8+ ships the patched verifier. This bumps the hermit pin to the latest patch, 3.47.9 (Dart 3.13.7), and raises the SDK floor in `pubspec.yaml` and CONTRIBUTING to match. Tracked in BSEC-29. iOS and macOS use Apple's certificate verification and aren't affected by this advisory. Patch-level bump within 3.47: no source, formatter or dependency changes were needed; `pubspec.lock` only changes the Flutter floor. No visible change, so no screenshots. ### Validation - `flutter analyze`: no issues. `dart format`: no changes. - Full mobile suite on 3.47.9: 4,596 passed, 67 skipped. - Not done: an Android device run that repeats the eMudhra interception test against a 3.47.9 build. 🤖 Generated with [Claude Code](https://claude.com/claude-code) Signed-off-by: Tom Brow <tomb@squareup.com> Co-authored-by: Tom Brow <tomb@squareup.com> |
||
|
klopez4212
|
773849665e |
Serve video and poster previews for invite links (#9306)
Invite links currently return HTML without preview metadata. Add server-rendered `og:video` and `og:image` tags for `/invite/<code>`, and bundle the approved MP4 and wordmark-only poster from #9282 into the relay image. Media URLs use the request’s resolved community host, with only TLS posture from `RELAY_URL`. Unknown hosts and lookup failures receive no metadata; previews stay generic and never redeem invites. Validation: production web build, workspace Clippy, 52 router tests (including real HTTP and MP4 range requests), metadata tests, and independent agent review pass. `just ci` stops at unrelated mobile dependency/format checks. The full relay suite was attempted but stopped during database-dependent tests without local infrastructure. Broad local Rust/desktop hooks were stopped for disk pressure; desktop/mobile hooks also lack dependencies and were skipped to publish this draft. Full-stack and native Messages playback remain unverified. The new preview regressions run in both CI test-runner paths. Rollout: merge and deploy the resulting relay image with its web bundle, verify the invite HTML and both public media URLs, then share a fresh invite in Messages. Full-stack and human validation remain outstanding. --------- Signed-off-by: kenny lopez <klopez4212@gmail.com> Co-authored-by: Terp <5856f6900e8e0a4e0ea1f4f8d2ee33e4753d2119bc122f94ecafc660b46c0511@buzz.block.builderlab.xyz> |
||
|
Diem Nguyen
|
18f3e35413 |
docs: point the README to Buzz 1.0 in block/buzz-app (#9296)
The README doesn't mention Buzz 1.0, so anyone who lands here can't tell
that a newer app exists. The block/buzz-app README already links back
here ("Buzz 0.X is still available and supported in block/buzz"). This
adds the link the other way: a note at the top that Buzz 1.0 lives in
block/buzz-app and that this repository is the 0.X line, which is still
supported. It also says plugins are new in 1.0 and their API is a
preview, linking to buzz-app's plugin architecture doc. This repository
has no plugin API, so the note points there instead of repeating
buzz-app's stability details.

Docs only, a 4-line README change.

🤖 Generated with [Claude Code](https://claude.com/claude-code)

---------

Signed-off-by: Diem Nguyen <diem@squareup.com>
Co-authored-by: Fizz <6be7be23ec5bba868f3e1db5ec86013d76bd1a293dce5b435a192158fec13641@buzz.block.builderlab.xyz>
Co-authored-by: Claude Opus 5.5 <noreply@anthropic.com>
|
||
|
Jemiah Westerman
|
5b1698ec24 |
fix(db): give the replica-fence probe its own pool and instrument it (#9297)
## Problem

The replica-fence probe (`replica_fence::run_probe`) commits a heartbeat
token every 500 ms. It borrowed its connection from the **serving writer
pool**, so under load each beat queued behind request traffic.

In a production deployment during a reconnect/replay storm:

-
`buzz_db_pool_acquire_duration_seconds{pool_role="writer",operation="maintenance"}`
went from ≤50 ms max to 2.7–3.0 s, which is the writer pool's acquire
timeout.
- `buzz_db_replica_heartbeat_age_seconds` went from about 0.47 s to
1.25–3.02 s, in the same 10 s buckets.
- Bounded reads then failed the freshness check
(`buzz_db_route_decision{decision="writer",reason="stale"}` went from
0–6 to 1.3k–6.4k per 10 s), so read traffic spilled onto the writer
exactly when it was saturated. Replica lag stayed at tens of
milliseconds the whole time.
- No `replica fence probe failed` warning fired, because each beat
eventually succeeded, just late. The probe had no span or metric of its
own (`maintenance` is shared by 15+ call sites), so this was only
visible indirectly.

## Change

- **Dedicated pool** (`replica_fence::connect_probe_pool`):
  - lazy, one connection, `application_name=buzz-replica-fence-probe`;
- same credentials and `max_lifetime` as the writer, so it follows
failover;
  - modelled on the push producer's pool.
- It doesn't run the writer pool's `after_connect`: the probe never
writes `events`, so no floor-guard arming is needed. Instead it installs
its own session timeouts:
- `lock_timeout` 1 s. While the probe waits for the exclusive floor
lock, new channel writes queue behind it, so failing a beat fast is
cheaper than holding the queue for the serving writer's 5 s budget.
Retained proofs stand.
- `statement_timeout` and `idle_in_transaction_session_timeout` 2 s. The
idle timeout reaps a stalled client that still holds the exclusive lock.
  - A 5 s client-side deadline bounds the whole probe.
  - Cost: one extra writer connection per relay process.
- The `Db::connect_writer_pool` doc now names this pool and the
push-enqueue pool as deliberate exceptions to its "every writer pool
uses this constructor" rule, and says why.
- **Spans** (via `datastore_span`, which also records
`buzz_db_operation_duration_seconds{operation=…}`):
- `replica_fence_probe` carries `acquire_ms`, `lock_ms`, `scan_ms`,
`heartbeat_ms`, `commit_ms`, `beat_gap_ms`, `token` and `error_kind`.
- Child spans `replica_fence_probe_acquire` and
`replica_fence_probe_lock` cover the two waits.
- **Logs:**
- Failure: `warn` with `error_kind` (`acquire_timeout`, `lock_timeout`,
`statement_timeout`, `deadline`, `masked_activity`, …),
`consecutive_failures`, `heartbeat_age_ms` and per-phase timings.
  - Recovery after failures: `info`.

- **Reader spill metric:** new `buzz_db_reader_spill_total{path,
reason}`. It counts only the routed reads the replica could have served
but the writer did. `buzz_db_route_decision{decision="writer"}` already
existed but merges three different causes under `reason="stale"` and
also counts configuration (`disabled`). Reasons:

  | Reason | Meaning |
  |---|---|
| `heartbeat_stale` | The newest beat is older than the bounded-read
budget. The probe is late, not the replica. |
| `heartbeat_missing` | No live proof: before the first beat, or nothing
within `FENCE_STALENESS`. |
| `fence_wall_behind` | The read's upper bound is newer than the fence
wall. |
| `replica_lag` | The session proved only an older entry than the read
needs. |
  | `reader_acquire_timeout` | Couldn't check out a reader connection. |
| `reader_proof_timeout`, `reader_token_behind`,
`reader_validation_error` | The reader couldn't prove the fence. |

`buzz_db_route_decision` keeps its labels and values unchanged for
existing dashboards. History reads rejected on a saturated reader stay
`decision="rejected"` and aren't counted as spills.
- **Heartbeat interval versus budget:**
- The problem: at 500 ms beats, a 1000 ms `BUZZ_REPLICA_READ_MAX_AGE_MS`
tolerates no missed beat. Just before each commit the newest entry is
already about one interval old, so a single late or failed beat puts
every bounded read over budget.
- The default beat interval stays at **500 ms**. Every beat takes the
deployment-wide exclusive floor lock that channel writes queue behind,
so beating faster costs more lock drains. The budget is what should
absorb a slow beat.
- New `min_read_budget(interval)` = interval + `PROBE_LOCK_TIMEOUT` (1
s) + 200 ms, which is **1700 ms** at the default. That covers one beat
that waits out the lock timeout, plus commit latency. `Db::new` warns at
startup when the configured budget is below it. A deployment running a
1000 ms budget will see this warning until the budget is raised.
- The interval is now configurable with
`BUZZ_REPLICA_FENCE_PROBE_INTERVAL_MS`. Unset means the 500 ms default.
Values outside 300–10000 ms fail startup. The 300 ms floor keeps the
120-entry proof ring covering more than the 30 s staleness gate, and the
ring assertion checks against that floor.

The proof ordering is unchanged: exclusive lock, then `S`, then activity
scan, then token commit last. `committed_at` is still captured before
the `UPDATE` round trip.

## Tests

- New `fence_probe_beats_while_serving_writer_pool_is_exhausted`: goes
through `Db::new` + `spawn_fence_probe`, holds the serving pool's only
connection, and requires two fresh beats and exactly one probe session.
It fails on `main`'s wiring, which I checked by temporarily reverting
the `spawn_fence_probe` change.
- New `cluster_global_probe_pool_bounds_the_floor_lock_wait`: a held
shared floor lock makes the probe fail with `lock_timeout` after about 1
s, the retained proof survives, and the next beat succeeds after
release.
- New `reader_spills_are_counted_by_cause`:
  - fresh heartbeat → no spill;
- late heartbeat → `heartbeat_stale`, with the legacy `stale` still
emitted;
  - past the staleness gate → `heartbeat_missing`;
  - routing disabled → no spill.
- Unit tests cover the log throttle and the interval/budget helpers. The
epoch-rotation test now runs through the one-connection probe pool.
- The `observability_source` source-policy test now asserts the probe
never takes a serving-writer `Maintenance` checkout and is spawned
through `connect_probe_pool`.
- Existing replica-fence and `spawn_fence_probe` tests pass unchanged,
apart from signature updates.

## Not done / follow-ups

- Locally: `buzz-db` unit tests and clippy (`-D warnings`) pass, and 38
replica-fence and routing Postgres tests pass on a fresh database. I
didn't run the full Postgres suite, because it needs the nextest
per-test-database wrapper, so CI's Postgres lane is the gate there.
- No local relay run yet. This needs a reader-configured relay, then
pool exhaustion to see the spans and logs end to end.
- The deployed `BUZZ_REPLICA_READ_MAX_AGE_MS` lives in deployment
config. Check it against the new startup warning.
- The `PROBE_DEADLINE` path has no test. It's only reachable through a
stall that no server-side timeout catches.

🤖 Generated with [Claude Code](https://claude.com/claude-code)

---------

Signed-off-by: Jemiah Westerman <jemiah@squareup.com>
Co-authored-by: Son of Anton <8e0ef2ab02d69a7ac089ef5eca90d1a3fbbdc546f6322dc34d0c4f3deecea7f4@buzz.block.builderlab.xyz>
Co-authored-by: Claude Opus 5.5 <noreply@anthropic.com>
|
||
|
Luke Tornquist
|
dd9da3ac6d |
fix(relay): never close connections when cross-node fan-out falls behind (#9302)
## Summary Cross-node fan-out no longer closes connections when it falls behind. Before this change, an event closed its local recipients when: - it was not delivered within 30 s of this node reading it from Redis, - its worker queue was full, - or the access gate still could not check a recipient by that deadline. Dispatcher lag also closed every subscribed connection. A rate-limited closer spread the closes out, at 1% of a node's connections per second with a floor. The trouble is that a database stall slows every node's deliveries at once. So the closes landed on every node together. Each reconnect then does AUTH, membership reads, NIP-11 and REST catch-up against the database that was already slow. That turned a short stall into a reconnect storm and bursts of 503s. On small nodes the closer's floor dominated, so a node could close all of its connections within tens of seconds. Review-Proven Rule 9 (design every client-driven path for the whole fleet running it at once) is the reason: a server-forced close starts a fleet-wide reconnect. ## What changes Kept from #9195 and #9235: - One dispatcher plus 16 workers, routed by `(community, topic)`. Each channel stays in order and channels deliver concurrently. - The bulk membership read in the access gate, and denying an event for a channel that no longer exists. Removed: - The delivery deadline and `ChannelEvent.received_at`. - The live fence (`fence_live_delivery`, `live_fenced`). - `LagCloser` and its rate limit. - The queue-full closes and the dispatcher-lag closes. - The access-gate retry loop (`buzz_multinode_fanout_gate_retries_total`). Behavior now: - A slow delivery holds only its own worker and arrives late. - A full worker queue or dispatcher lag drops the event on this node. The drop is counted in `buzz_multinode_fanout_dropped_total{reason="queue_full"}` or `buzz_multinode_fanout_lag_total`, and the affected artifact syncs get `CLOSED "resync: live delivery lagged"` (NIP-AR Sync rule 5). This is the same as before the closer existed. - A recipient the access gate cannot check misses that event, and a sync among them resyncs. Same as the local fan-out path. Trade-off: a plain subscription that misses a dropped event is not told. Its client may replay the event on its next reconnect, but not if later deliveries moved its resume cursor past the event by more than its replay slack (5 s for the ACP client). That was the behavior before #9195. Queue-full and lag drops stay visible in the counters, so we can see whether they actually happen before adding any recovery mechanism. ## What got simpler Net −700 lines. - `multinode_fanout.rs` drops from ~940 lines to ~350. - `deliver_pubsub_event` loses its retry loop and goes back to the shared `route_fanout_matches` path. The Redis path and the local path once again apply the access gate the same way. - `ConnectionManager` loses the fence flag and the split send helper. `SubscriptionRegistry` loses `subscribed_connections`. ## Testing - `handlers::multinode_fanout::tests`: - in-order delivery through the workers; - a full queue resyncs only the matched syncs and closes nothing, and a local echo is not counted as a drop; - dispatcher lag resyncs every sync and closes nothing; - a recipient the gate cannot check misses the event with no retry, stays connected, and still gets the next event. - `handlers::event::tests` is unchanged apart from removing `received_at`. - Mutants killed: the queue-full resync, the lag resync and the local-echo skip. 🤖 Generated with [Claude Code](https://claude.com/claude-code) --------- Signed-off-by: Luke Tornquist <tornquist@squareup.com> Co-authored-by: Elrond <28d6302a099e5225b02c4155ac4236e4912603df2ab08dbfc2f4fef08ce598c8@buzz.block.builderlab.xyz> Co-authored-by: Claude Opus 5.5 <noreply@anthropic.com> |
||
|
Matt Toohey
|
85996fdff4 |
test: fix timing-dependent unit tests in buzz-cli, buzz-agent and buzz-admin (#9273)
## Summary
Split out of the `flakey-monday` flake-fix series. Three Rust unit tests
in `buzz-cli`, `buzz-agent` and `buzz-admin` depended on wall-clock
timing or on a production-sized pool budget and failed on loaded CI
runners. Each now waits on, or counts, the thing it actually asserts.

Commits (cherry-picked from `flakey-monday`, original messages kept):
- `test(cli): throttle the first desktop sign-in by count, not clock`
- `test(agent): wait for both responses in
steer_rejected_on_empty_prompt`
- `test(agent): pin steer_rejected_on_empty_prompt to the empty-prompt
guard`
- `test(admin): give the NIP-FI Postgres tests a test-lane pool budget`

### Root cause and fix per test


**`client::desktop_throttle_tests::a_throttled_sign_in_reconnects_with_fresh_evidence`**
(`crates/buzz-cli/src/client.rs`): failed once in CI with `conns` left
1, right 2.
- Root cause (confirmed): the fake desktop throttled a sign-in only when
`last.elapsed() < 300ms`, and `last` was captured before the provider
handshake and credential setup. When that setup took over 300 ms, the
first sign-in was signed straight away, nothing was throttled, the
client never reconnected, and the relay saw one connection.
- Fix: the fake desktop throttles exactly its first `sign_event` call
via an atomic counter, which is the scenario the test describes. The
relay's unsigned-socket deadline goes from 200 ms to 5 s, as in the
sibling deadline tests, so it no longer shapes the scenario. Assertions
are unchanged: two connections, only "c1" signed, a fresh assertion on
the reconnect.

**`steer_rejected_on_empty_prompt`**
(`crates/buzz-agent/tests/fake_llm.rs`): panicked with "empty steer
prompt was not rejected".
- Root cause (confirmed): `session/prompt` runs in a spawned task while
`_goose/unstable/session/steer` is answered inline from the stdin loop.
The fake LLM finishes the turn almost at once, so the prompt response
can arrive before the agent has read the steer. The receive loop broke
on the prompt response and never saw the steer's -32602.
- Fix: keep reading, bounded at 40 messages as before, until both the
steer and prompt responses have arrived in either order. The follow-up
commit also asserts `error.message == "steer: prompt must not be
empty"`, because `steer_session` returns -32602 for "no active run to
steer" and an `expectedRunId` mismatch too, which are exactly the
replies a steer gets when the turn ends first. The empty-prompt check
runs right after decoding, so the message is deterministic in both
orderings.


**`nip_fi::postgres_tests::{backfill_binds_only_bindable_hosts_and_reports_the_rest,
backfill_skips_a_community_being_deleted,
bind_refuses_hosts_outside_the_suffix_and_unbind_keeps_the_last_issuer}`**
(`crates/buzz-admin/src/nip_fi.rs`): `connect to test DB:
Sqlx(PoolTimedOut)` after about 3.5 s.
- Root cause (confirmed): the tests built their pool from
`DbConfig::default()`, sized for a warm relay pod (3 s acquire timeout,
two eager spare connections). In the first wave of the PostgreSQL lane
every nextest worker clones its database from the template at once, so a
first connection can take longer than 3 s.
- Fix: keep the production writer pool (`Db::new`, so the session policy
is still exercised) but set `min_connections` 0 and a 30 s acquire
timeout, the budget sqlx's `PgPool::connect` defaults give the other
PostgreSQL tests. `Db::connect_cold_start` uses the same values.

### Related issue
N/A (flake fixes; none found).

### Testing
Human testing is still required. This PR does not carry
`buzz-review-completed`; the author has not yet run these tests
themselves on this branch.

#### Verification
These changes were verified locally on the `flakey-monday` branch before
the split:
- buzz-cli throttle test: old code under CPU saturation (40 busy loops
on 32 cores) failed every iteration with `left: 1`, the CI failure. New
code, `desktop_throttle_tests` with `--test-threads=16`: 30/30 passed
unloaded, 15/15 under the same saturation.
- buzz-agent steer test: forced CI ordering (temporary 500 ms delay
before sending the steer) made the old test panic and the new test pass.
`fake_llm steer` tests with `--test-threads=16`: 30/30 passed. The
follow-up ran 100/100, and was falsified: with the empty-prompt guard
removed and the steer sent after the turn, the code check still passed
and the new message assertion failed.
- buzz-admin NIP-FI tests, against docker Postgres: the three tests, 10
iterations at `--test-threads=3`: 10/10. Behind a proxy delaying each
new connection by 4 s: the old config failed with the CI `PoolTimedOut`
at 3 s, the new config passed.

Note: `crates/buzz-cli/src/client.rs` also changed on `main` since the
series forked. The cherry-pick applied cleanly; only hunk offsets differ
from the original commit.

Nothing was re-run on this split branch: the workstation was overloaded,
so no tests, builds or linters were executed after cherry-picking. CI on
this PR is the verification for the split branch.

🤖 Generated with [Claude Code](https://claude.com/claude-code)

---------

Signed-off-by: mtoohey <mtoohey@squareup.com>
Co-authored-by: Claude Opus 5.5 <noreply@anthropic.com>
|
||
|
Matt Toohey
|
d2c3234cb9 |
fix(ci): classify hermit retry timeouts by watchdog kill, not whole seconds (#9274)
## Summary Split out of the `flakey-monday` flake-fix series. `scripts/ci-hermit-retry.sh` decided an attempt had "timed out" by comparing whole-second elapsed time with the deadline, so an instant failure that straddled a second boundary was misreported as a timeout. The watchdog now reports through its exit status whether it actually killed the attempt. Commit (cherry-picked from `flakey-monday`, original message kept): - `fix(ci): report a hermit retry timeout only when the watchdog fired` ### Root cause and fix **node:test "persistent failure backs off between attempts and stops at the budget"** (`scripts/ci-hermit-retry.test.mjs`): expected "attempt 3/3 failed (exit 7)" and got "attempt 3/3 timed out after 1s". - Root cause (confirmed): the script checked `$((SECONDS - started)) -ge deadline`. Bash's `$SECONDS` counts whole wall-clock seconds, and the test uses a 1 s deadline (`CI_HERMIT_ATTEMPT_SECONDS=1`). An instant `exit 7` that crossed a second boundary looked like it had run for the whole deadline. - Fix: the watchdog subshell exits 0 if it is stopped before signalling the attempt, and 124 once it has sent TERM (or TERM then KILL). The script reports a timeout only when the watchdog exits 124; elapsed time is no longer used. Bash 3.2 (macOS) supports this. A new test starts 0.8 s into a wall-clock second and runs a 0.4 s attempt that exits 7, so it crosses a second boundary but finishes well inside its 1 s deadline, and asserts it is reported as "failed (exit 7)". ### Related issue N/A (flake fix; none found). ### Testing Human testing is still required. This PR does not carry `buzz-review-completed`; the author has not yet run the script or its tests themselves on this branch. #### Verification Verified locally on the `flakey-monday` branch before the split: - The new test against the old script: failed with "attempt 1/1 timed out after 1s", the CI symptom. - The whole `ci-hermit-retry.test.mjs` suite with the fix: 20/20 passed. Nothing was re-run on this split branch: the workstation was overloaded, so no tests, builds or linters were executed after cherry-picking. CI on this PR is the verification for the split branch. 🤖 Generated with [Claude Code](https://claude.com/claude-code) Signed-off-by: mtoohey <mtoohey@squareup.com> Co-authored-by: Claude Opus 5.5 <noreply@anthropic.com> |
||
|
Matt Toohey
|
ea548da808 |
test(ios): wait for a key, foreground-active window before presenting in RunnerTests (#9275)
## Summary Split out of the `flakey-monday` flake-fix series. Two iOS RunnerTests acted right after `makeKeyAndVisible()` without waiting for the window to become key in a foreground-active scene, which is the state the code under test resolves its presenter from. A shared test helper now waits for that state before the tests present anything. Commits (cherry-picked from `flakey-monday`, original messages kept): - `test(mobile): wait for a key window before presenting in iOS tests` - `test(mobile): wait for a foreground-active scene in the key-window helper` **These Swift changes were NOT compiled or run locally.** The fixes were written on a Linux workstation without Xcode or an iOS simulator, and this split branch was not built either. iOS CI on this PR is the first place they compile and run. ### Root cause and fix per test **`RunnerTests.testRejectedCommunityEntryPresentationCompletesAndAllowsRetry`** (`mobile/ios/RunnerTests/RunnerTests.swift`): timed out after 2 s waiting for "Temporary native modal appeared". **`IdentityFilePluginTests.testPickerResolvesPresenterAtRequestAndCancelsExactlyOnce`** (`mobile/ios/RunnerTests/IdentityFilePluginTests.swift`): waited 5 s for `parent.presentedViewController is UIDocumentPickerViewController`, which never became true. - Root cause (inferred from the code paths and CI symptoms; not reproduced): `NativeCommunityEntryCoordinator` and `IdentityFilePlugin.pick()` both resolve their presenter as the root of the `isKeyWindow` window in a `.foregroundActive` scene. `makeKeyAndVisible()` can return before key status moves to the new window, so `pick()` presented on a different window's controller and the expectation on `parent` could never be met. The community-entry test also attached its window to the first connected scene rather than the foreground-active one, swapped `rootViewController` and presented immediately; UIKit silently drops a presentation from a controller whose view is not yet in a window. - Fix: a shared `XCTestCase` helper in `RunnerTests.swift`, internal so `IdentityFilePluginTests` can use it without changing the Xcode project. `keyWindow(showing:)` attaches a window to the `.foregroundActive` scene, makes it key, and returns once a predicate expectation sees `window.isKeyWindow` and the root's view in that window. `keyWindowReady(_:showing:)` is that predicate; the community-entry test waits on it again after swapping the root. The follow-up commit replaces the `XCTUnwrap` of the foreground-active scene with the same predicate-expectation wait (5 s budget), since the first test to run could otherwise fail while its scene is still activating. The community-entry test became `async`; its fixed 2 s presentation wait became 5 s, the budget the picker test already uses. The readiness waits are the fix, not the longer timeout. Assertions are unchanged. ### Related issue N/A (flake fixes; none found). ### Testing Human testing is still required. This PR does not carry `buzz-review-completed`; the author has not yet run RunnerTests themselves on this branch. #### Verification Not run locally at any point: Swift tests need Xcode and an iOS simulator, which the authoring workstation lacked, and nothing was built on this split branch either (the workstation was overloaded, so no tests, builds or linters were executed after cherry-picking). The review pass on `flakey-monday` confirmed the `keyWindowReady` shape compiles; the follow-up follows that same shape. iOS CI on this PR is the verification for both the fix and the split branch. 🤖 Generated with [Claude Code](https://claude.com/claude-code) --------- Signed-off-by: mtoohey <mtoohey@squareup.com> Co-authored-by: Claude Opus 5.5 <noreply@anthropic.com> |
||
|
Matt Toohey
|
15c2ca1b01 |
test(desktop): wait on real readiness signals in audience and community-rail specs (#9277)
## Summary
Split out of the `flakey-monday` flake-fix series. Three Desktop E2E
tests in `persistent-agent-audience.spec.ts` and
`community-rail.spec.ts` acted on signals that could arrive before the
app state they implied (a logged command before the submit lock
rendered, a URL check that only held before a view transition landed).
They now wait on the readiness signals the product actually exposes. No
product code changes.
Commits (cherry-picked from `flakey-monday`, original messages kept):
- `test(desktop): wait for composer focus and send cycles in audience
specs`
- `test(desktop): assert the kept remembered route after the community
switch`
- `test(desktop): assert Home after repairing the remembered channel`
### Root cause and fix per test
**`a manual mention persists when automatic mentions are enabled`**
(`desktop/tests/e2e/persistent-agent-audience.spec.ts`):
`locator.fill("follow up")` failed because `message-input` was not
editable.
- Root cause (from the code and CI symptom; not reproduced locally): the
test sends with a 1.5 s mock send delay, during which the composer is
submit-locked and `contenteditable="false"`. The lock is React state and
renders a frame after Enter. The test's last two checks before the fill
could both pass before that frame: the outgoing-mention poll (the e2e
bridge logs a command when invoked, before the delay) and the
`contenteditable="true"` wait. Playwright's `fill` rejects a
`contenteditable="false"` element outright instead of waiting.
- Fix: after Enter, wait for the full send cycle: `data-submit-locked`
"true", `contenteditable` "false", `data-submit-locked` "false",
`contenteditable` "true". Only then assert on the editor. Existing
assertions are unchanged.
**`the mention setting is reachable and operable by keyboard`** (same
spec): the thread composer's mention autocomplete never became visible.
- Root cause (likely; not reproduced locally): opening a thread by URL
mounts both the channel composer and the thread composer.
`useComposerAutofocus` focuses whichever mounts first and TipTap defers
`focus()` by a frame. A click and fill that land before that deferred
focus lose it, and the focus-gated mention menu unmounts.
- Fix: a `readyThreadComposerInput()` helper waits for the thread editor
to be editable and for exactly one `message-input` to hold focus, so the
app's own autofocus has landed. Both tests use it.
**`community rail > does not repair a remembered channel until live
validation succeeds`** (`desktop/tests/e2e/community-rail.spec.ts`):
`expect(page).not.toHaveURL(/#\/channels\/general$/)` failed right after
the click on community B.
- Root cause (confirmed; 21/40 failures at 14 workers on the old spec):
`switchCommunity` runs inside a view transition whose callback writes
B's remembered channel into the hash and then activates B, a few frames
after the click returns. By design the URL is then `#/channels/general`,
which `AppShell` keeps until a live channel read succeeds and only then
repairs to Home. The inverted check from
|
||
|
Bradley Axen
|
2b16d0ea1a |
feat(relay): let an operator mint invites for a community owner or admin (#9265)
## Summary

Adds `POST /operator/communities/invites`, so a deployment's trusted
operator (its account service) can mint an invite link on behalf of a
community owner or admin. The website where people manage their
communities never holds the owner's own key, so it can't call `POST
/api/invites` (owner-signed NIP-98).

- **Trust model:** the same as
`/operator/communities/{archive,transfer}`. A configured operator signs
the request (NIP-98, payload-bound, replay-checked) and vouches only for
**which identity** its signed-in caller is bound to (`actor_pubkey`).
The relay decides that identity's authority from **its own roster at
mint time**: owner or admin only, the same check `/api/invites` makes.
Nothing the operator says about roles is trusted.
- **Same invite:** it mints through `db.mint_relay_invite`, with the
same lifecycle gate and restriction check, the same
`ttl_secs`/`max_uses` bounds and defaults (`validate_mint_request`), and
the same response (`minted_invite_json`, extracted from `/api/invites`).
The link is an ordinary `https://<host>/invite/<code>` that every
client's join flow already claims.
- Archived, deleted and deleting communities return 404
(`lookup_community_host` only resolves active ones).

Request body (unknown fields rejected):
```json
{ "community_id": "<uuid>", "actor_pubkey": "<64-hex>", "ttl_secs": 259200, "max_uses": 5 }
```

Errors keep the `/api/invites` text in `error` and add a stable `code`,
so the operator can tell its own misconfiguration from the actor's
refusal without matching on text:

| Status | `code` | When |
|---|---|---|
| 403 | `not_operator` | the signer is not a configured operator |
| 400 | `invalid_request` | bad JSON, an unknown field, a bad pubkey, or
out-of-range limits |
| 404 | `community_not_found` | unknown, archived, deleted or deleting
community |
| 403 | `not_owner` | the actor isn't an owner or admin in the relay's
roster |
| 403 | `restricted` | the actor is banned or restricted
(`invite_restricted`) |
| 503 | `unavailable` | community writes are paused |

This is an HTTP operator route rather than an event kind because it
belongs on the existing operator plane (operator-signed, outside the
event data plane), like the other operator community actions.

### Stack (invite links on the Builderlab Communities page)

1. **This PR**: the relay route. It ships first.
2. The account service endpoint that calls it (private repo). Depends on
this PR.
3. The website UI (private repo). Depends on 2.

### Related issue

None found.

### Testing

- New Postgres journey
`operator_mints_invites_only_for_relay_owners_and_admins` (run against a
freshly migrated local database):
- An owner mints with the defaults. The URL, null `max_uses` and the 72h
expiry match `/api/invites`.
- A joiner **claims the minted code through `POST /api/invites/claim`**
and becomes a member.
  - An admin mints with limits.
  - A banned admin is refused.
- A member and an outsider get 403 with the same refusal text as
`/api/invites`. The test pins each error's `code`.
- Out-of-range `ttl_secs` and `max_uses`, an unknown field, a bad pubkey
and a non-operator signer are all refused.
  - An unknown community and an archived community get 404.
- `cargo test -p buzz-relay --lib -- --include-ignored api::invites
api::operator`: 78 passed and 2 timed out under heavy machine load. Both
timeouts (`claim_follow_up_survives_a_client_disconnect`,
`temporary_listing_failure_is_recovered_for_each_admission_path`) also
pass on this branch when run on their own, as on `main`.
- `cargo fmt` and pre-push hooks (clippy) passed.
- **Not yet done:** a run against a local relay with `curl`, and a human
check.

---------

Signed-off-by: Bradley Axen <baxen@squareup.com>
Signed-off-by: Kalvin Chau <kalvin@block.xyz>
Co-authored-by: drone03 <3efda7d0089450ac8094dd25cfa734546dc0d6bad0ab87b64dacfff867bdc4d3@buzz.block.builderlab.xyz>
Co-authored-by: Kalvin Chau <kalvin@block.xyz>
Co-authored-by: peon <9ac6794b000690b7e814eb1805ad32405d0bec7d52838de3a86cf967565dacc0@buzz.block.builderlab.xyz>
Co-authored-by: Claude Opus 5.5 <noreply@anthropic.com>
|
||
|
Salman Mohammed
|
66095e5598 |
fix: inline ARM64 atomics in Sprig image build (#9291)
## Summary Sprig's ARM64 container fails to link because bundled D-Bus emits a call to GCC's `__aarch64_ldadd4_sync` helper, which Rust's static musl link does not supply. AMD64 succeeds, but the failed ARM64 job blocks publication of the multi-architecture image. Set the ARM64 musl C compiler flags to `-mno-outline-atomics` in the image builder. This emits baseline ARM64 atomic instructions inline instead of requiring the missing helper. Other targets and the runtime image configuration are unchanged. ### Related issue No duplicate fix found. [Failing build](https://github.com/block/buzz/actions/runs/42667527024/job/129335071943). The [previous main build](https://github.com/block/buzz/actions/runs/42642040718) has the same failure, before the MCP dependency update. ### Testing The exact local ARM64 image build passed: `docker build --platform linux/arm64 --file Dockerfile.sprig --tag buzz-sprig:arm64-link-fix .`. The resulting `sprig --version` command passed. The `buzz-agent` personality reached its expected missing-provider configuration error. Broad local checks were not run. Generated with Codex Signed-off-by: Salman Mohammed <smohammed@squareup.com> |
||
|
klopez4212
|
49511f02b6 |
fix(mobile): show observed thread replies in Activity (#9286)
## Summary A reply in a thread you started, participated in, or followed can light a mobile channel's attention dot without appearing in Activity. Activity now includes eligible replies already observed by the channel unread pipeline in **All** and **Threads**. Tapping a row uses the existing oldest-unread reply and thread navigation. Retain the reply payload alongside its bounded unread evidence, then merge by event ID with the addressed feed. Mentions retain their category and do not duplicate. Deletion, eviction, and account/community resets share the same registry. This adds no relay queries or subscriptions. Coverage follows the existing channel unread catch-up and live subscriptions. This does not introduce complete historical thread discovery: replies outside that retained window, and replies not eligible for the channel attention dot, are not newly fetched. ### Related issue Related to #9271 (clearing channel rows) and closed #9186 (broader Activity feed expansion). #9213 supplied the existing Activity filters. This PR connects existing observed replies to those filters. ### Testing - Full mobile suite, push-unconfigured tests, analysis, formatting and file-size checks. - Production-provider regression: cold catch-up, live reply, mention deduplication, excluded unrelated/quiet replies, thread read markers, deletion/replay and identity reset. - Real Activity widget journey with fake relay/storage boundaries: show the unmentioned reply, select Threads, tap the row, and verify the reply ID and thread ID passed to the conversation page. - Mutation check: removing reply-payload retention makes the widget journey fail because the reply is absent. - Independent agent source review: no blockers. ### Preview Actual Flutter widgets at phone width with synthetic data and the new reply wiring disabled/enabled. These are widget-test captures, not installed-device or live-relay evidence. | Before | After | | --- | --- | |  |  | ### Human validation pending Draft per the repository readiness checklist. On a device, receive an unmentioned reply in a thread you started, replied in, or followed. Check Activity → All and Threads, tap the row to reach the reply, then read it and confirm Unread clears without reading unrelated channel messages. Native/live-relay testing and human confirmation remain pending. --------- Signed-off-by: kenny lopez <klopez4212@gmail.com> Signed-off-by: Tom Brow <tomb@squareup.com> Co-authored-by: Terp <5856f6900e8e0a4e0ea1f4f8d2ee33e4753d2119bc122f94ecafc660b46c0511@buzz.block.builderlab.xyz> Co-authored-by: Tom Brow <tomb@block.xyz> Co-authored-by: Tom Brow <tomb@squareup.com> Co-authored-by: Claude Opus 5.5 <noreply@anthropic.com> |
||
|
klopez4212
|
2bbaa061d0 |
Enable mobile huddles with Codex agents (#9269)
Show the Huddle action in owned Codex agent DMs and invite the agent before connecting audio. Revalidate eligibility on starts/recovery, ask before inviting into an existing call, and distinguish pending invitations from connected audio peers with actionable timeout feedback. DM hangup leaves shared room cleanup to the relay so another owner device stays connected. Pairs with https://github.com/block/buzz-app/pull/3048. Desktop and the Codex agent must remain running. Validated: 4,559 mobile tests, analysis, formatting, push hooks, and independent source review. Live phone-to-desktop audio and human trial remain pending. --------- Signed-off-by: kenny lopez <klopez4212@gmail.com> Signed-off-by: Tom Brow <tomb@squareup.com> Co-authored-by: Terp <5856f6900e8e0a4e0ea1f4f8d2ee33e4753d2119bc122f94ecafc660b46c0511@buzz.block.builderlab.xyz> Co-authored-by: Tom Brow <tomb@block.xyz> Co-authored-by: Tom Brow <tomb@squareup.com> Co-authored-by: Claude Opus 5.5 <noreply@anthropic.com> |
||
|
Blake McAnally
|
c1ce2ca800 |
fix(mobile): read mentions taller than the screen (#9243)
## Problem Bug report (mobile 0.28.0 (46)): opening a mention from the Inbox in an archived Solo chat leaves the Inbox row unread. The video shows the cause. Each unread row is a long agent answer. On a phone, the answer is taller than the screen, or it lands partly cut off after the deep-link jump. Mobile automatic reading writes a `msg:` mark only for a row that is fully visible for the 300 ms dwell. A mention row is high priority, so `activity:<channel>` does not read it. The mention can stay unread until the reader marks it read by hand. The archived state is not the cause. A widget test shows that an archived Solo chat writes read marks for short messages. Archived chats make the problem easy to see, because there is no composer and the reader only reads. ## Fix A message counts as read only when it actually showed, for the 300 ms dwell. A row counts when any of these holds: - **It fits:** the whole row is inside the reading area (unchanged). - **It fills the screen:** the row is taller than the reading area and covers all of it. This applies to the channel timeline and the thread view. - **A link opened it:** the message a deep link or Inbox tap opened counts once any part of it shows, because the jump places it at 35% and a long one lands cut off. - **It is the newest message at the live bottom:** its end is showing, in a channel, a Solo chat (replies inline) or a thread. This covers a long final answer that only ever shows its end. Reaching the bottom does **not** read mentions or broadcasts above the newest message that never came on screen. Desktop does that sweep (block/buzz-app#1679). Mobile deliberately does not. Ordinary `activity:` / `thread-activity:` catch-up is unchanged, and messages the reader marked unread stay unread. ## Tests - `reading_marks_test.dart`: the bottom does not read mentions above it; the newest message is read at the live bottom (and respects manual unread); a flat Solo timeline reads only its newest inline reply; a tall thread tail reply is read at its end; DM catch-up does not mark mentions; `isReadableRow` cases, including linked rows. - `channel_detail_page_test.dart`: an archived Solo chat and a Solo inline reply each read a tall newest mention at the bottom; a tall row away from the bottom is read once it fills the screen; tall linked messages (channel and thread) are read when the jump leaves them cut off; in a thread, the tall last reply is read at the end and an earlier tall reply is read once it fills the screen. These fail on `main`. - `just mobile-check` and the full mobile suite pass. ## Human test steps 1. Get a long agent reply that mentions you in a Solo chat, then archive the chat. 2. Open the row from the Inbox and hold still for about one second. 3. Go back. The row should now show as read, with no dot. 🤖 Generated with [Claude Code](https://claude.com/claude-code) --------- Signed-off-by: Blake McAnally <bmcanally@squareup.com> Signed-off-by: morgmart <98432065+morgmart@users.noreply.github.com> Co-authored-by: BlakeBot <85bbd70443139fd5c5762e34c2e214240939eb243c37f98380f69fed3b3bb4a6@buzz.block.builderlab.xyz> Co-authored-by: Claude Opus 5.5 <noreply@anthropic.com> Co-authored-by: morgmart <98432065+morgmart@users.noreply.github.com> Co-authored-by: Morgarita <6e967af659416160ab4f2fd56d74c8c6f273791ee7bfc9468a1be37c387947be@buzz.block.builderlab.xyz> |
||
|
Matt Toohey
|
b082b1464c |
test(relay): give every media e2e upload its own blob hash (#9272)
## Summary Split out of the `flakey-monday` flake-fix series. Two Relay E2E media tests shared one deterministic blob hash across every test in their binaries. In enforce mode (`BUZZ_MEDIA_READ_MODE=enforce`, on for the Relay E2E lane since #9077), a rejected publish of that shared hash left a sticky publication marker that made ranged GETs from the other tests return 404. Every media e2e upload now has its own blob hash. Commits (cherry-picked from `flakey-monday`, original messages kept): - `test(media): give each video e2e test its own MP4 blob` - `test(media): publish images of their own in the media e2e tests` ### Root cause and fix per test **`test_video_range_request_206` / `test_video_range_request_416`** (`crates/buzz-test-client/tests/e2e_media_video.rs`): a ranged GET returned 404 instead of 206/416 in 9 of 55 Relay E2E jobs. - Root cause (confirmed): `build_test_mp4()` was deterministic, so every test in the binary uploaded the same sha256, and the tests run in parallel against one relay. In enforce mode, `validate_media_references` records a sticky `media_publications` marker for every hash an event publishes, before dispatch, so a later rejection does not undo it. `test_video_poster_imeta_rejects_video_as_poster` published the shared hash and was then rejected by imeta validation. From then on `media_access` gave an uploader with no readable reference `Restricted`, served as 404, until the accepted poster test stored its event in an open channel. - Fix: `build_test_mp4()` appends a top-level `free` box holding a random UUID, so each call yields a distinct, still valid fast-start MP4. The upload validator allows `free` and does not inspect its payload. The relay is unchanged: the pre-dispatch marker is the documented fail-closed contract in `docs/operator-private-media.md`. **`test_video_poster_imeta_accepted_via_ws`** and **`e2e_media_extended::test_ws_valid_imeta`**: hardening, not a fix for an observed failure. Both published a fixed 1x1 JPEG byte-identical to `tiny_jpeg()` in `e2e_media.rs`, which `test_upload_and_get` reads back through an uploader preview. That currently passes (a readable live reference wins before the marker matters), but a publishing test that shares a fixed blob with other media tests is one rejected or private event away from the same flake. Both now publish an 8x8 PNG of random pixels from a new `unique_png()` helper; `test_ws_valid_imeta`'s imeta declares `image/png` and the real size; `tiny_jpeg()` is removed from `e2e_media_video.rs`. ### Related issue N/A (flake fixes; none found). ### Testing Human testing is still required. This PR does not carry `buzz-review-completed`; the author has not yet run these tests themselves on this branch. #### Verification These changes were verified locally on the `flakey-monday` branch before the split, against an enforce-mode relay with docker Postgres/MinIO: - Old code, fresh enforce-mode relay: reject test then range tests failed both range tests with 404 at the CI lines (reproduction). - Whole `e2e_media_video` binary, `--test-threads=8`: 20/20 passed. - Reject test then range tests against the polluted hash: 3/3 passed. - The CI "Media read-auth e2e" command (`e2e_media`, `e2e_media_extended`, `e2e_media_video`, `--ignored`), 5 back-to-back runs on the same scratch database (the persistent-relay case): 5/5 runs, 40/40 tests each time. - `cargo fmt --check` and `clippy --tests`: clean. Nothing was re-run on this split branch: the workstation was overloaded, so no tests, builds or linters were executed after cherry-picking. CI on this PR is the verification for the split branch. 🤖 Generated with [Claude Code](https://claude.com/claude-code) --------- Signed-off-by: mtoohey <mtoohey@squareup.com> Co-authored-by: Claude Opus 5.5 <noreply@anthropic.com> |
||
|
klopez4212
|
838976d6e4 |
Add invite preview video and fallback poster (#9282)
Adds a 16-second Buzz invite-preview video and wordmark-only poster, matching onboarding colors and fuzzy texture. Includes a local preview/poster picker and reproducible media export. This prepares assets; live invite Open Graph metadata and relay deployment are follow-up work. Validated: preview browser checks and independent review pass. Full `just ci` stopped during Rust compilation because the disk filled. Native iMessage playback is not yet tested. Video: https://github.com/user-attachments/assets/8977f990-fb79-4217-bec1-fa8d2b93ece0 Fallback poster:  --------- Signed-off-by: kenny lopez <klopez4212@gmail.com> Signed-off-by: Bradley Axen <baxen@squareup.com> Co-authored-by: Terp <5856f6900e8e0a4e0ea1f4f8d2ee33e4753d2119bc122f94ecafc660b46c0511@buzz.block.builderlab.xyz> Co-authored-by: Bradley Axen <baxen@squareup.com> |
||
|
kazemek21
|
3071279cd8 |
NEXUS-4336: Wait for desktop-provider socket ownership proof (#9270)
## TL;DR Retry missing desktop-provider socket ownership proof on the same open connection, within the existing five-second limit. Credentials and provider requests remain withheld until the exact server-side socket belongs to the caller's UID; a wrong UID or lookup error still fails immediately. The ownership code moves into its own module to keep the existing oversized file within the repository's file-size ratchet. The macOS lookup now bounds output and checks the child exit status while retaining cancellation cleanup. ### Related issue Fixes NEXUS-4336. ### Testing 42 provider tests passed on Linux, including synthetic transport tests for delayed/absent proof, wrong UID, lookup failure, deadline expiry, zero early request bytes, and child cleanup after timeout/cancellation. Targeted Clippy, formatting, and file-size checks passed. Removing the retry or bypassing proof caused the production-path regression to fail. Native macOS execution, installed/source parity, and the cause of any live authentication failure remain unverified. This source change does not establish installed or live recovery. No human-test attestation is claimed. Generated with Codex. Posted by Codex (gpt-6.1-sol) on behalf of kylez. Signed-off-by: Kyle Zemek <kylez@squareup.com> Co-authored-by: Codex <noreply@openai.com> |
||
|
Salman Mohammed
|
658253009c |
fix: unblock image audit with patched MCP SDK (#9287)
## Summary The latest main image builds succeed on both architectures, but publication fails because the same-SHA CI security audit rejects newly reported advisories. Update rmcp 3.4.1 to 3.9.0 to fix its HTTP client, server-cache, and OAuth advisories. Add documented exceptions for rmcp 1.8's disabled HTTP transports and SQLite used only by the examples-only MeshLLM smoke harness's private log store. Dependency and feature bans constrain those exceptions. This does not patch the remaining SQLite version or migrate buzz-agent's subprocess client. ### Related issue None found. Failing runs: [CI](https://github.com/block/buzz/actions/runs/42653097086), [image publication](https://github.com/block/buzz/actions/runs/42653096928). ### Testing No manual runtime testing. Local validation was limited to the dependency audit, buzz-dev-mcp compilation, SQLx pin verification, and lightweight Git hooks. Broad local Rust and Tauri hooks were skipped at the author's request. The image qualification gate remains intact. Generated with Codex Signed-off-by: Salman Mohammed <smohammed@squareup.com> |
||
|
Alex Rosenzweig
|
34bab2f64b |
feat(ci): allow admin dispatch of desktop candidate validation (#9288)
## Summary Desktop Release Candidate only supports PR events today. Add a manual dispatch with a required version input that validates the existing `version-bump/<version>` branch. Require the workflow from `main` and current repository admin permission for both the original actor and any rerunner before checkout; API failures deny the run. Existing PR validation and read-only token permissions are preserved. GitHub can still accept a dispatch from a writer; the workflow rejects that run before candidate checkout. This validates an existing candidate and does not create or publish a release. Document the command in `RELEASING.md`. ### Related issue None found in open issue/PR title searches for "desktop release candidate". ### Testing - `actionlint .github/workflows/desktop-release-candidate.yml` passed. - `bash scripts/test-desktop-release-candidate.sh` passed, including the new authorization tests executed from the production workflow shell with only the GitHub API mocked. Covers admin access, all lesser roles, missing permission responses, API failures, rerunners, and non-main dispatches. - Mutation checks confirmed that removing the admin check, rerunner check, or main-ref restriction fails the new tests. - Self-review completed with no blocking findings. - `just ci` is running locally; results will be updated here. - Hosted manual dispatch has not been exercised: the new guard requires dispatch from `main`, where this change is not merged. Human verification is pending, so this PR remains a draft under `AGENTS.md`. Once available on `main`, an admin can test with `gh workflow run desktop-release-candidate.yml --repo block/buzz --ref main -f version=<existing-candidate-version>`. Expect permission checks to pass and the immutable candidate validator to run against that candidate. A writer or a dispatch selecting another workflow branch should fail before checkout. Manual runs do not replace the candidate PR's required checks. --------- Signed-off-by: Alex Rosenzweig <arosenzweig@squareup.com> Co-authored-by: BigBoss <19a7c9f8477c0dd12d428c2b2faa352556cd13b3ec3d717498b60f85a57a90a9@buzz.block.builderlab.xyz> |
||
|
Matthew Boston
|
c502e53e63 |
feat(mobile): tag the reacted-to message author on reactions (#9141)
## Why

NIP-25 says a reaction should carry a `p` tag naming the author of the
reacted-to event. buzz-app's Activity → Reactions tab
(block/buzz-app#2638, merged) finds reactions to your messages with a
`#p` read. Reactions sent from mobile have no `p` tag, so they never
appear there. block/buzz#9121 makes the same change for `buzz reactions
add`.

## What

- Every reaction sent from mobile now carries `["p", <message author>]`.
This covers the reaction pill, the quick-reaction row, the emoji picker,
and reactions on system rows.
- Removing a reaction is unchanged.
- Agent status reactions (buzz-acp) and the desktop app are unchanged by
decision. Agent status reactions stay out of Activity.

## Testing

- New unit test: `ChannelActions.addReaction` publishes exactly `["e",
target]` and `["p", author]`. It fails without the change (actual tags:
`[['e', 'target-event']]`).
- The message-actions widget test now checks that a quick reaction
passes the message's author.
- `just mobile-check`: format and `flutter analyze` are clean (no
issues).
- `just mobile-test`: 4,507 passed, plus the push-unconfigured and
secp256k1 suites. All pass.
- No screenshots: the change is one tag on the published event, and
nothing on screen changes.
- Not yet: a run on a device, and the human test.

## How a human can test

1. On mobile, as user B, react 👍 to a message from user A.
2. As user A, open Activity → Reactions in a current buzz-app build.
3. It works if a "B reacted 👍" row appears. Before this change, no row
appears.

🤖 Generated with [Claude Code](https://claude.com/claude-code)

Signed-off-by: Matthew Boston <mboston@squareup.com>
Co-authored-by: mboston Implementer <932d3b6ebea6cc83e091551ae46d1c7e7f8f7d0fa8e9cef5e6facc8544af413b@buzz.block.builderlab.xyz>
Co-authored-by: Claude Opus 5.5 <noreply@anthropic.com>
mobile-v0.28.0-rc.10 |
||
|
Tom Brow
|
5f59940544 |
fix(mobile): steady New DM picker rows and animate picks (#9249)
On iOS, the New DM (and Add Members) picker is a native UIKit sheet that Flutter drives by pushing the picker's whole state on every rebuild. Each push called `reloadData`, which rebuilt every visible row in a fresh, unreused cell showing the initials fallback, then fetched each avatar again over the platform channel. So whenever anything refreshed (several refreshes land right after foregrounding), every avatar blinked to its initial for a frame or two. Picks also jumped instantly from the results to the chosen section. Now the picker: - ignores a pushed state identical to the one it shows; - applies the rest as a diffable snapshot, so unchanged rows keep their cells and changed rows are redrawn in place, in reused cells; - keeps loaded avatars by avatar key for the life of the sheet, so a redrawn row shows its avatar at once; - animates a member's row moving between the chosen and result sections when it's picked or removed (no animation with Reduce Motion). Flutter's toggle handlers in both pickers now read the current selection rather than the one captured at build time. A fast second tap could otherwise add the same person twice, which the diffed table would reject. ### Validation - Native member picker test (`scripts/test-mobile-member-picker.sh`), extended: after an avatar loads, a changed row is redrawn with that avatar and requests nothing more. The avatar check fails on `main` and passes here; the existing identity and accessibility checks still pass with the diffable table. - Added a New DM test: two toggles before Flutter rebuilds never list a person twice. It fails without the toggle fix. - Full mobile Flutter suite and analyzer pass in CI on the current head, which includes `main`'s fix for the right-drag link tests. - Simulator runs of the app (iPhone 17 Pro, iOS 27, signed in to a test community): opened New DM, backgrounded and foregrounded the app, searched, picked from the list and from a search, and removed a pick. Without this change, every avatar flashed to its initial after a foreground. With it, no avatar flashed at any point, and picks and removals animate between sections. Recordings show real community members, so they're shared in Buzz rather than here. #### Full-app comparison, `main` vs this PR The same scripted New DM sequence on a clone of the same signed-in simulator (iPhone 17 Pro, iOS 27), first on `main` ( |
||
|
Tom Brow
|
52cb6818fa |
perf(mobile): keep remote images on disk and show small ones as thumbnails (#9158)
## Summary The mobile app now saves remote images on disk. After a relaunch, avatars, custom emoji, message attachments and agent artwork show immediately. The app does not download them again. Small images on a relay now load only the relay's thumbnail. The app never downloads the full-size upload to show a small image. ## Why Before this change, the app kept remote images only in memory. Each cold launch downloaded every image again. On a slow connection, attachments showed a "Loading image" placeholder for a long time. Also, when a relay had no thumbnail for an image, the app downloaded the full-size upload. That upload can be up to 20 MiB, for an avatar that is a few dozen points wide. ## What changes ### Images on disk - `MediaImageProvider` reads and writes a `MediaDiskCache`. Each account in each community has its own cache, at `<root>/communities/<community id>/media/<signer pubkey>`. The cache is built on `flutter_cache_manager`, with a JSON index. - On iOS, the root is the app group's `Library/Caches` (from a new `buzz/app_group` method channel). App extensions can then read the same cache. On other platforms, the root is the app cache directory. - Each cache holds a maximum of 250 MB. When it is full, the least recently used images go first. `MediaCacheIndex` measures each file when it writes it, because `flutter_cache_manager` limits only the number of files. Every disk read marks the file used, and every write schedules eviction, including a refresh that replaces bytes the package already holds in memory (by default the package does neither for those). - The cache does not save an image that is larger than 5 MiB. The app still shows that image from memory. Thus, one large image cannot push out all the others. - Relay media URLs contain a content hash, so their bytes never change. The cache keeps them until it evicts them. For other URLs, the cache shows the saved image, and then gets a new copy in the background after one week. A maximum of two of these refreshes run at the same time. The app decodes a refreshed image before it replaces the saved copy. - When you remove a community, the app deletes its cache. When a community gets a new signing key, the app deletes the media of the old account. At launch, the app also deletes caches of communities and accounts that are no longer present. - Startup does not wait for the cache. The cache directory resolves in the background. Image reads wait for it for a maximum of 3 seconds. ### Thumbnails for small images - A small relay image loads the relay's WebP thumbnail. If the relay has no WebP thumbnail, the image loads the JPEG thumbnail. If the relay has neither, the widget shows its placeholder (initials for an avatar, an empty tile for artwork). - Native avatars drawn by UIKit (the navigation bar, the community icon on the create button, and the New DM and Add Members pickers) use the same choice, through a new `smallMediaImageProviders`. They try the same thumbnails, fall back the same way, and show initials when neither thumbnail exists. Before, they downloaded the full-size upload and only decoded it small. - Larger layouts and the full-screen viewer load the full-size upload, as before. ### Agent artwork - Preset agent artwork (the tray, flight, video placeholder, avatar hero and the avatar editor's blurred backdrop) now loads through `MediaImage`, so it uses the disk cache too. - The create-agent and empty-bestie pages warm the same `MediaImageProvider` that their widgets read, through a new `mediaImageProviderFor(ref, url)`. - No code in `mobile/lib` uses `Image.network` or `NetworkImage` now. ## Demo A cold relaunch (the app is stopped, then started) into a synthetic "QA demo" Solo chat that holds a few generated images. Shown at half speed. Before: the attachment shows a "Loading image" placeholder while it downloads. https://github.com/user-attachments/assets/107f43a3-63d0-40c3-bd80-4ea9d7897a97 After: the attachment shows with the chat, from disk. https://github.com/user-attachments/assets/d3985bb2-838c-4efa-93cb-44cef51f677d ## Tests - `test/shared/relay/media_disk_cache_test.dart` follows one journey through the real provider and a real cache in a temporary directory. The first launch downloads and saves. An offline relaunch shows the full-size image, its thumbnail and an external image from disk, and the oversized image goes back to the network. Eight days later, only the external image refreshes. Removing the community deletes its directory. - A second test checks the order of eviction when the cache is full, that a file read from disk is evicted after files that were not, and that replacing a file's bytes after eviction last ran evicts again when the cache goes over budget. - `community_provider_test` checks that launch deletes orphan media directories, that a new signing key deletes only the old account's media, and that removing a community deletes its media. - `avatar_image_test` checks that a missing WebP thumbnail falls back to the JPEG thumbnail, and that an avatar with no thumbnail shows its initials. - `native_avatar_image_test` checks the same for native avatars: a WebP 404 paints the JPEG thumbnail, the full-size upload is never requested, a relay with no thumbnail paints initials and is not asked again, and any other failure stops at the initials. - `flutter analyze` and the full mobile test suite pass. - Automated app runs on an iPhone 17 Pro simulator (iOS 27): the channel list, a DM, Home, the Agents grid and an agent details sheet show their images. After a relaunch, the images came from disk and the app wrote no new files. In the "QA demo" chat, a new image from the app showed immediately. - Automated run of the native-thumbnail fix on an iPhone 17 Pro simulator (iOS 27): the native New DM picker shows photo avatars, and the cache gained only relay `.thumb.webp` entries for them, no full-size uploads. After a cold relaunch, the picker showed the same avatars within about 1.5 seconds, and the cache directory gained no files. The avatar editor backdrop was not exercised in the app. The test community has no remote agents, and the backdrop tests cover only emoji and picked-image selections. ## Before merge - [x] Automated simulator run of this head: avatars and agent artwork show their thumbnails, and a cold relaunch shows images from disk. 🤖 Generated with [Claude Code](https://claude.com/claude-code) --------- Signed-off-by: Tom Brow <tomb@squareup.com> Co-authored-by: Tom Brow <tomb@squareup.com> Co-authored-by: Claude Opus 5.5 <noreply@anthropic.com> Co-authored-by: studio <dc2fc481343672df31a689840c09299972e704dac592e0da6f18486646a7ee3e@localhost> |






